-
-
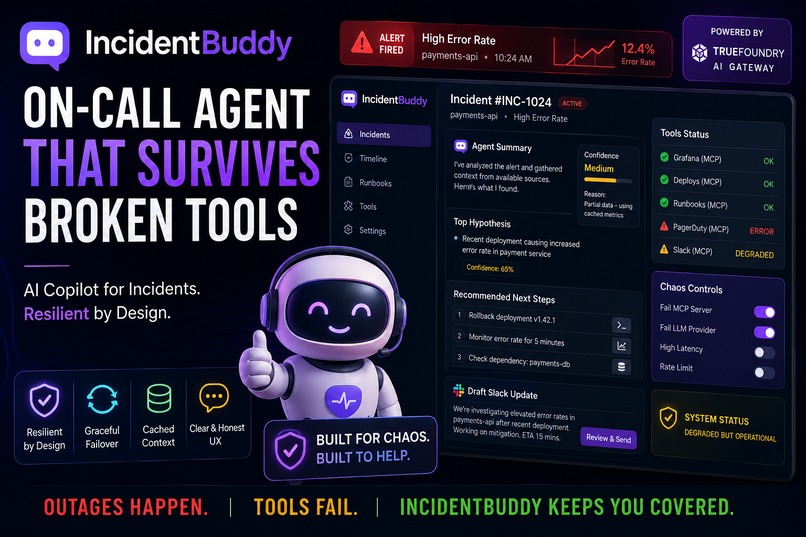
Thumbnail
-
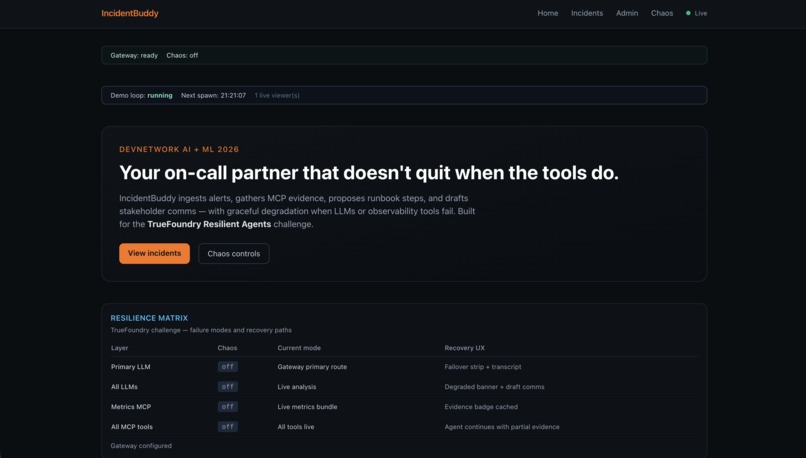
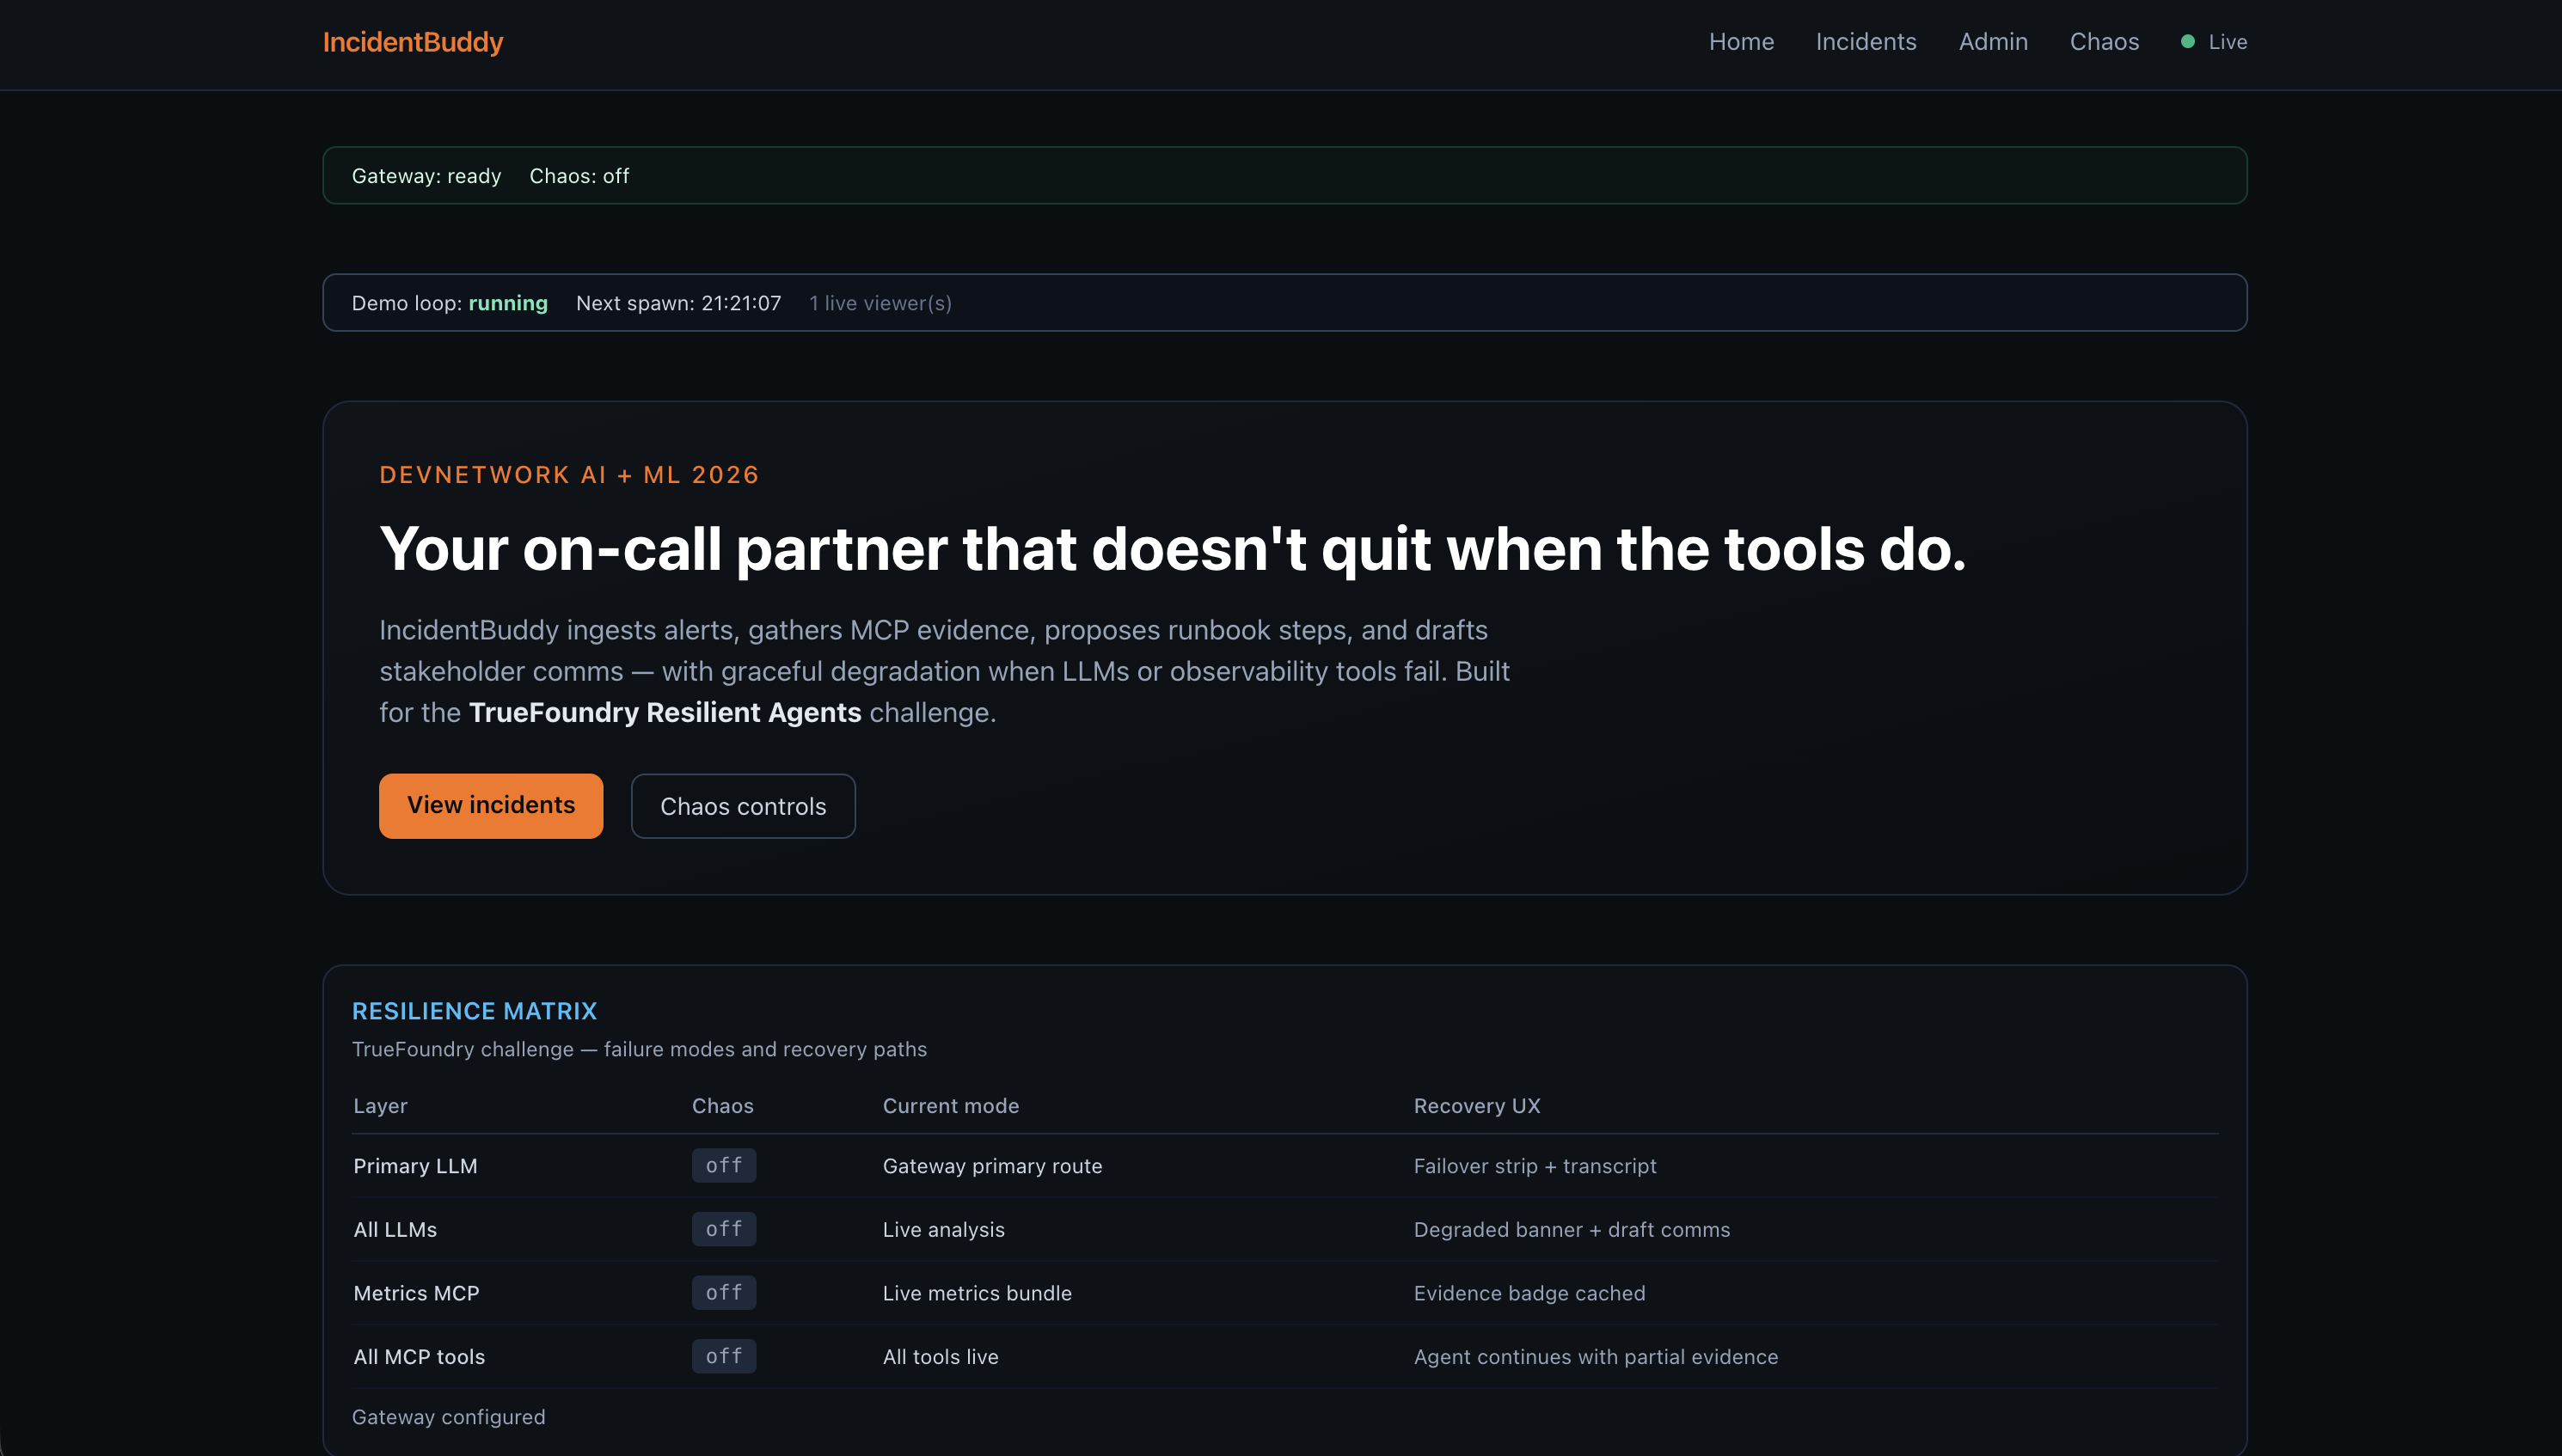
Home Page
-
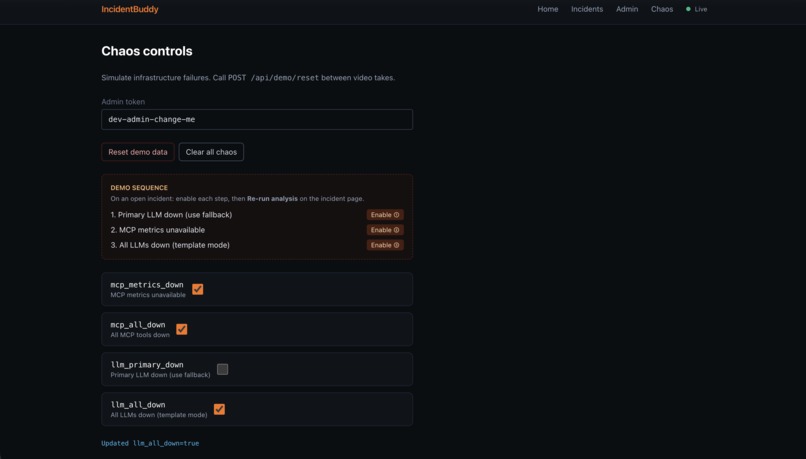
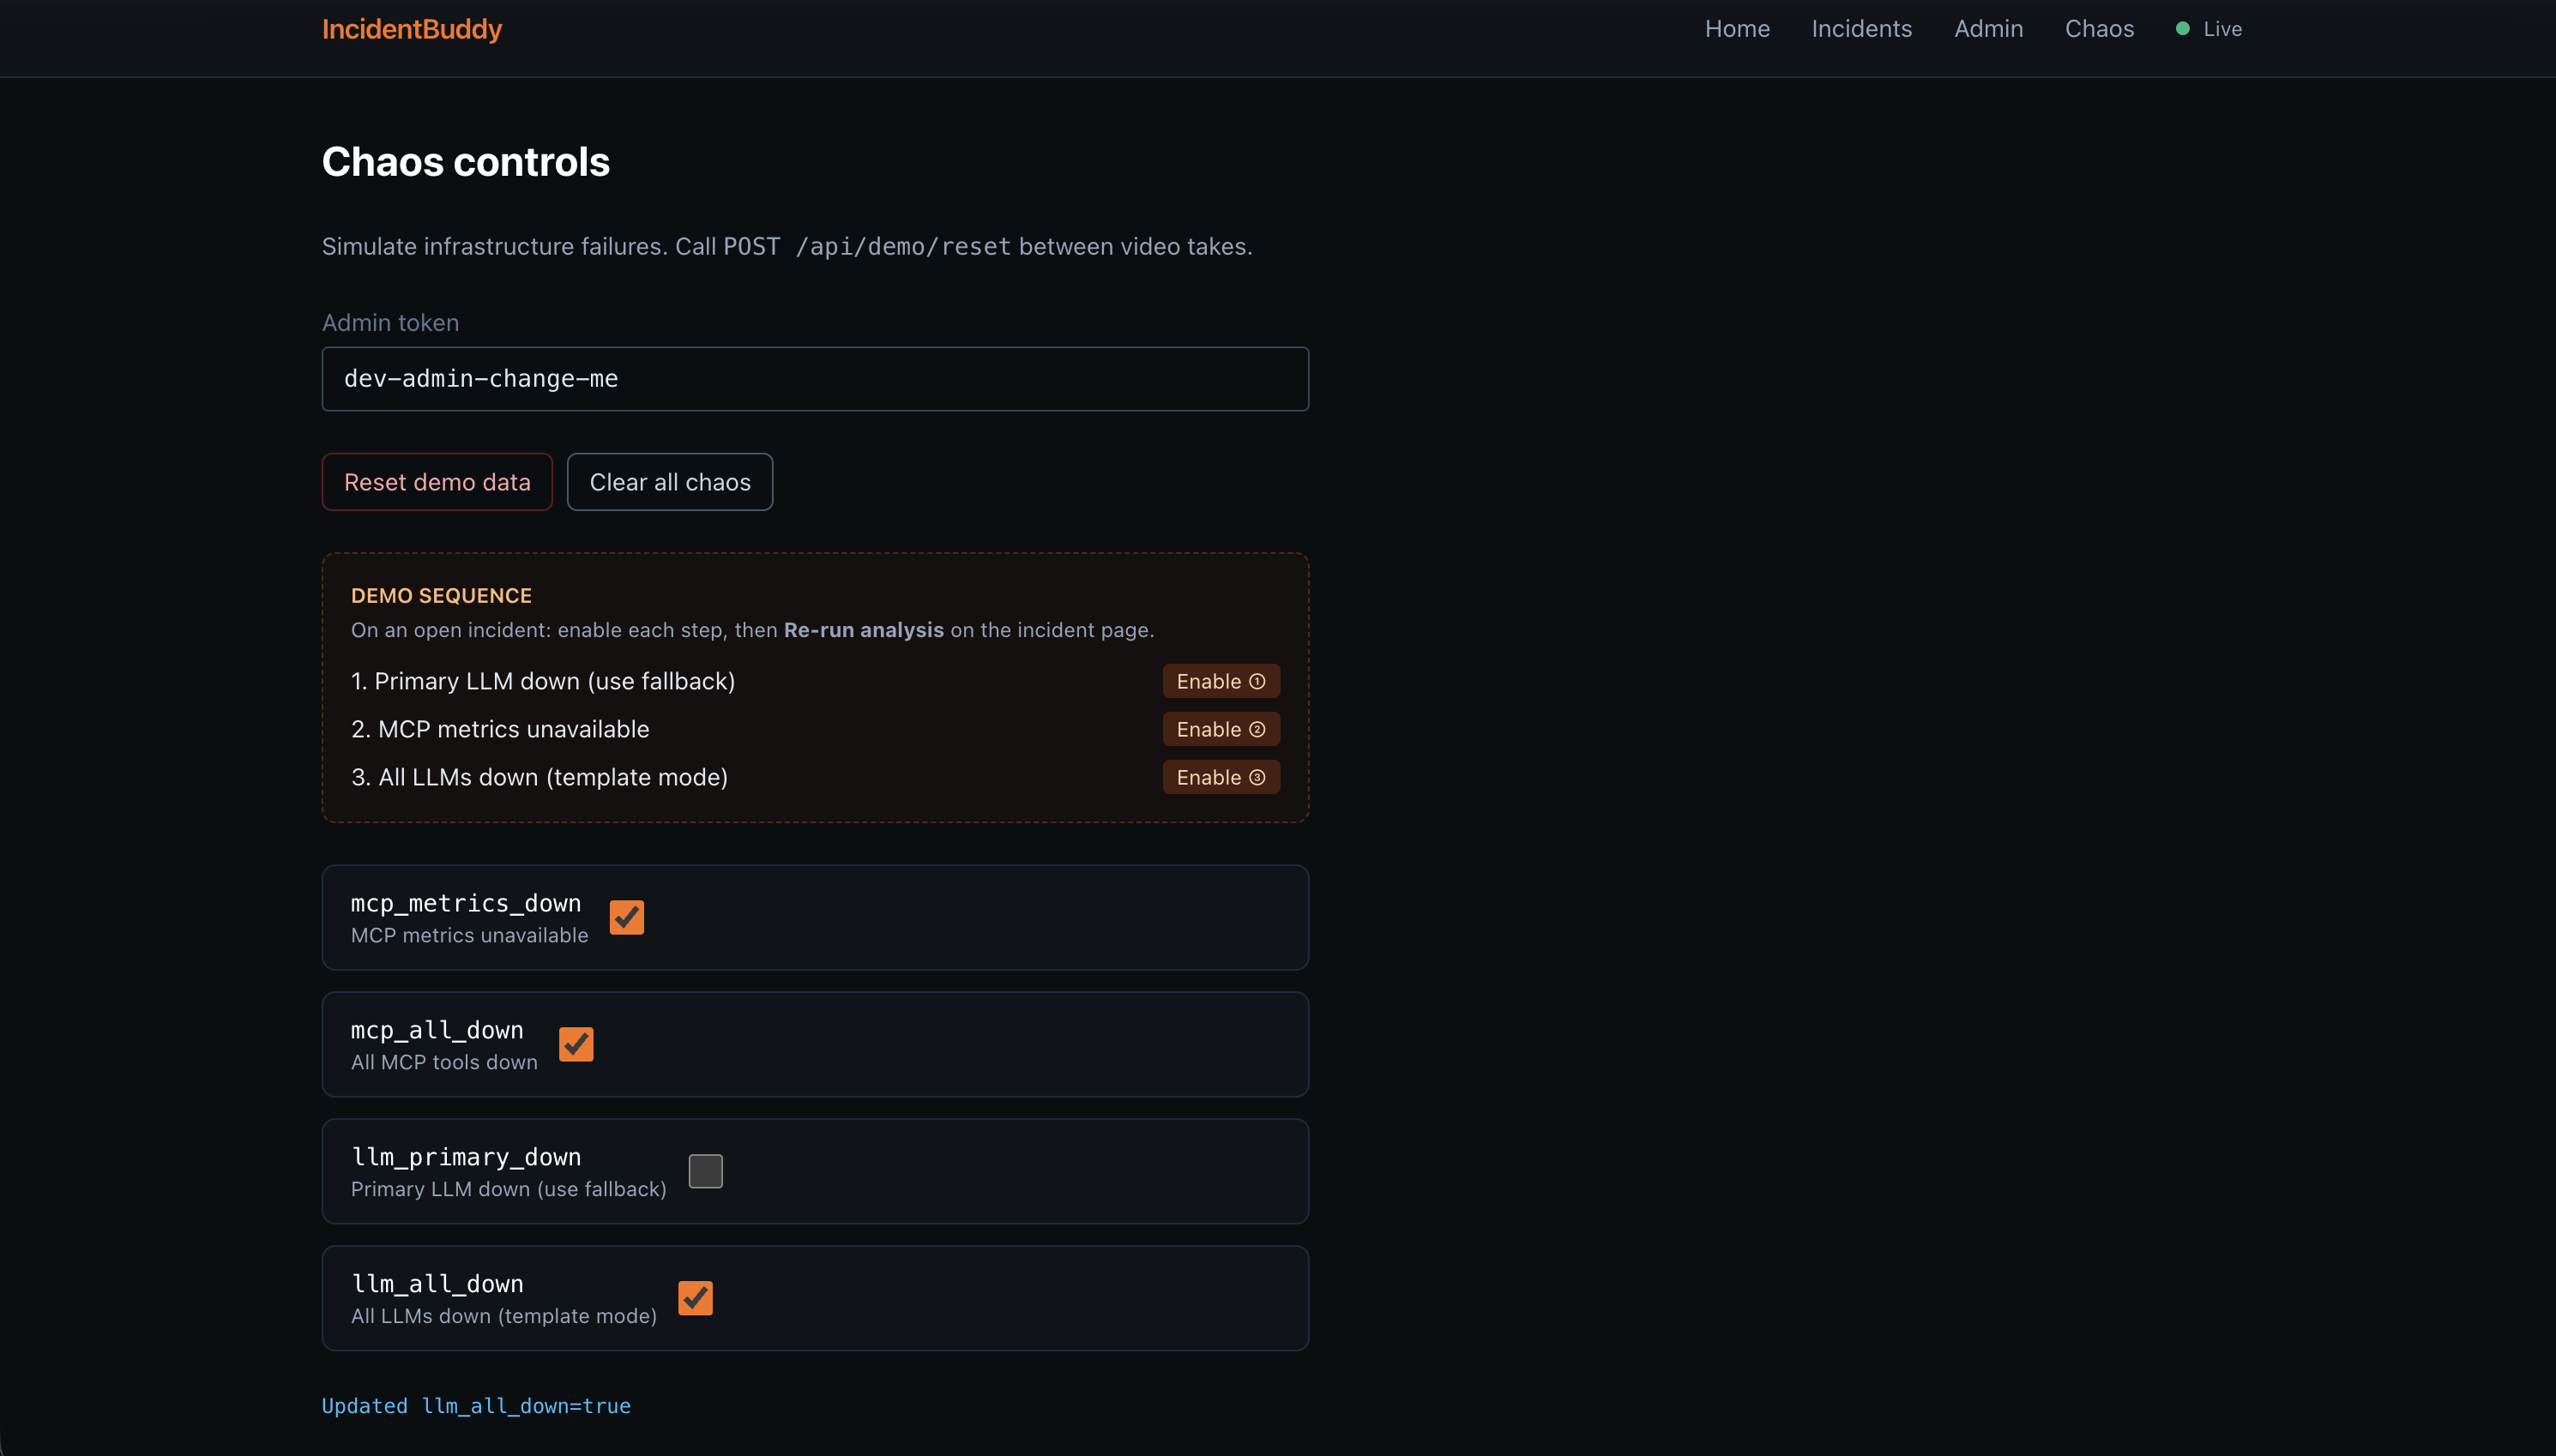
Chaos Panel
-
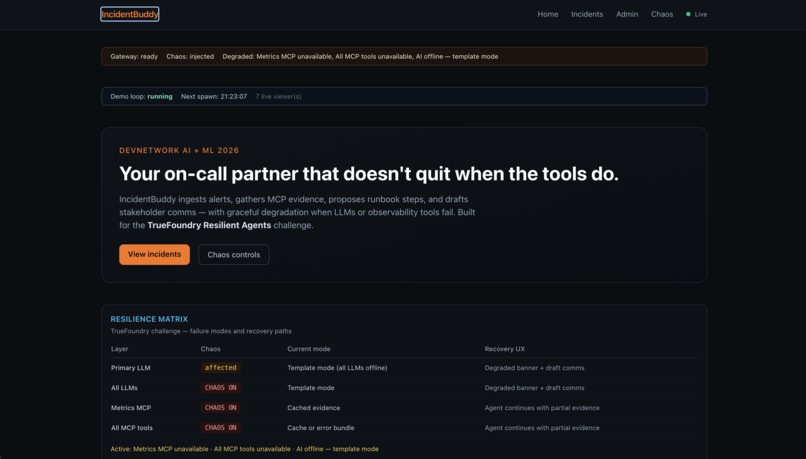
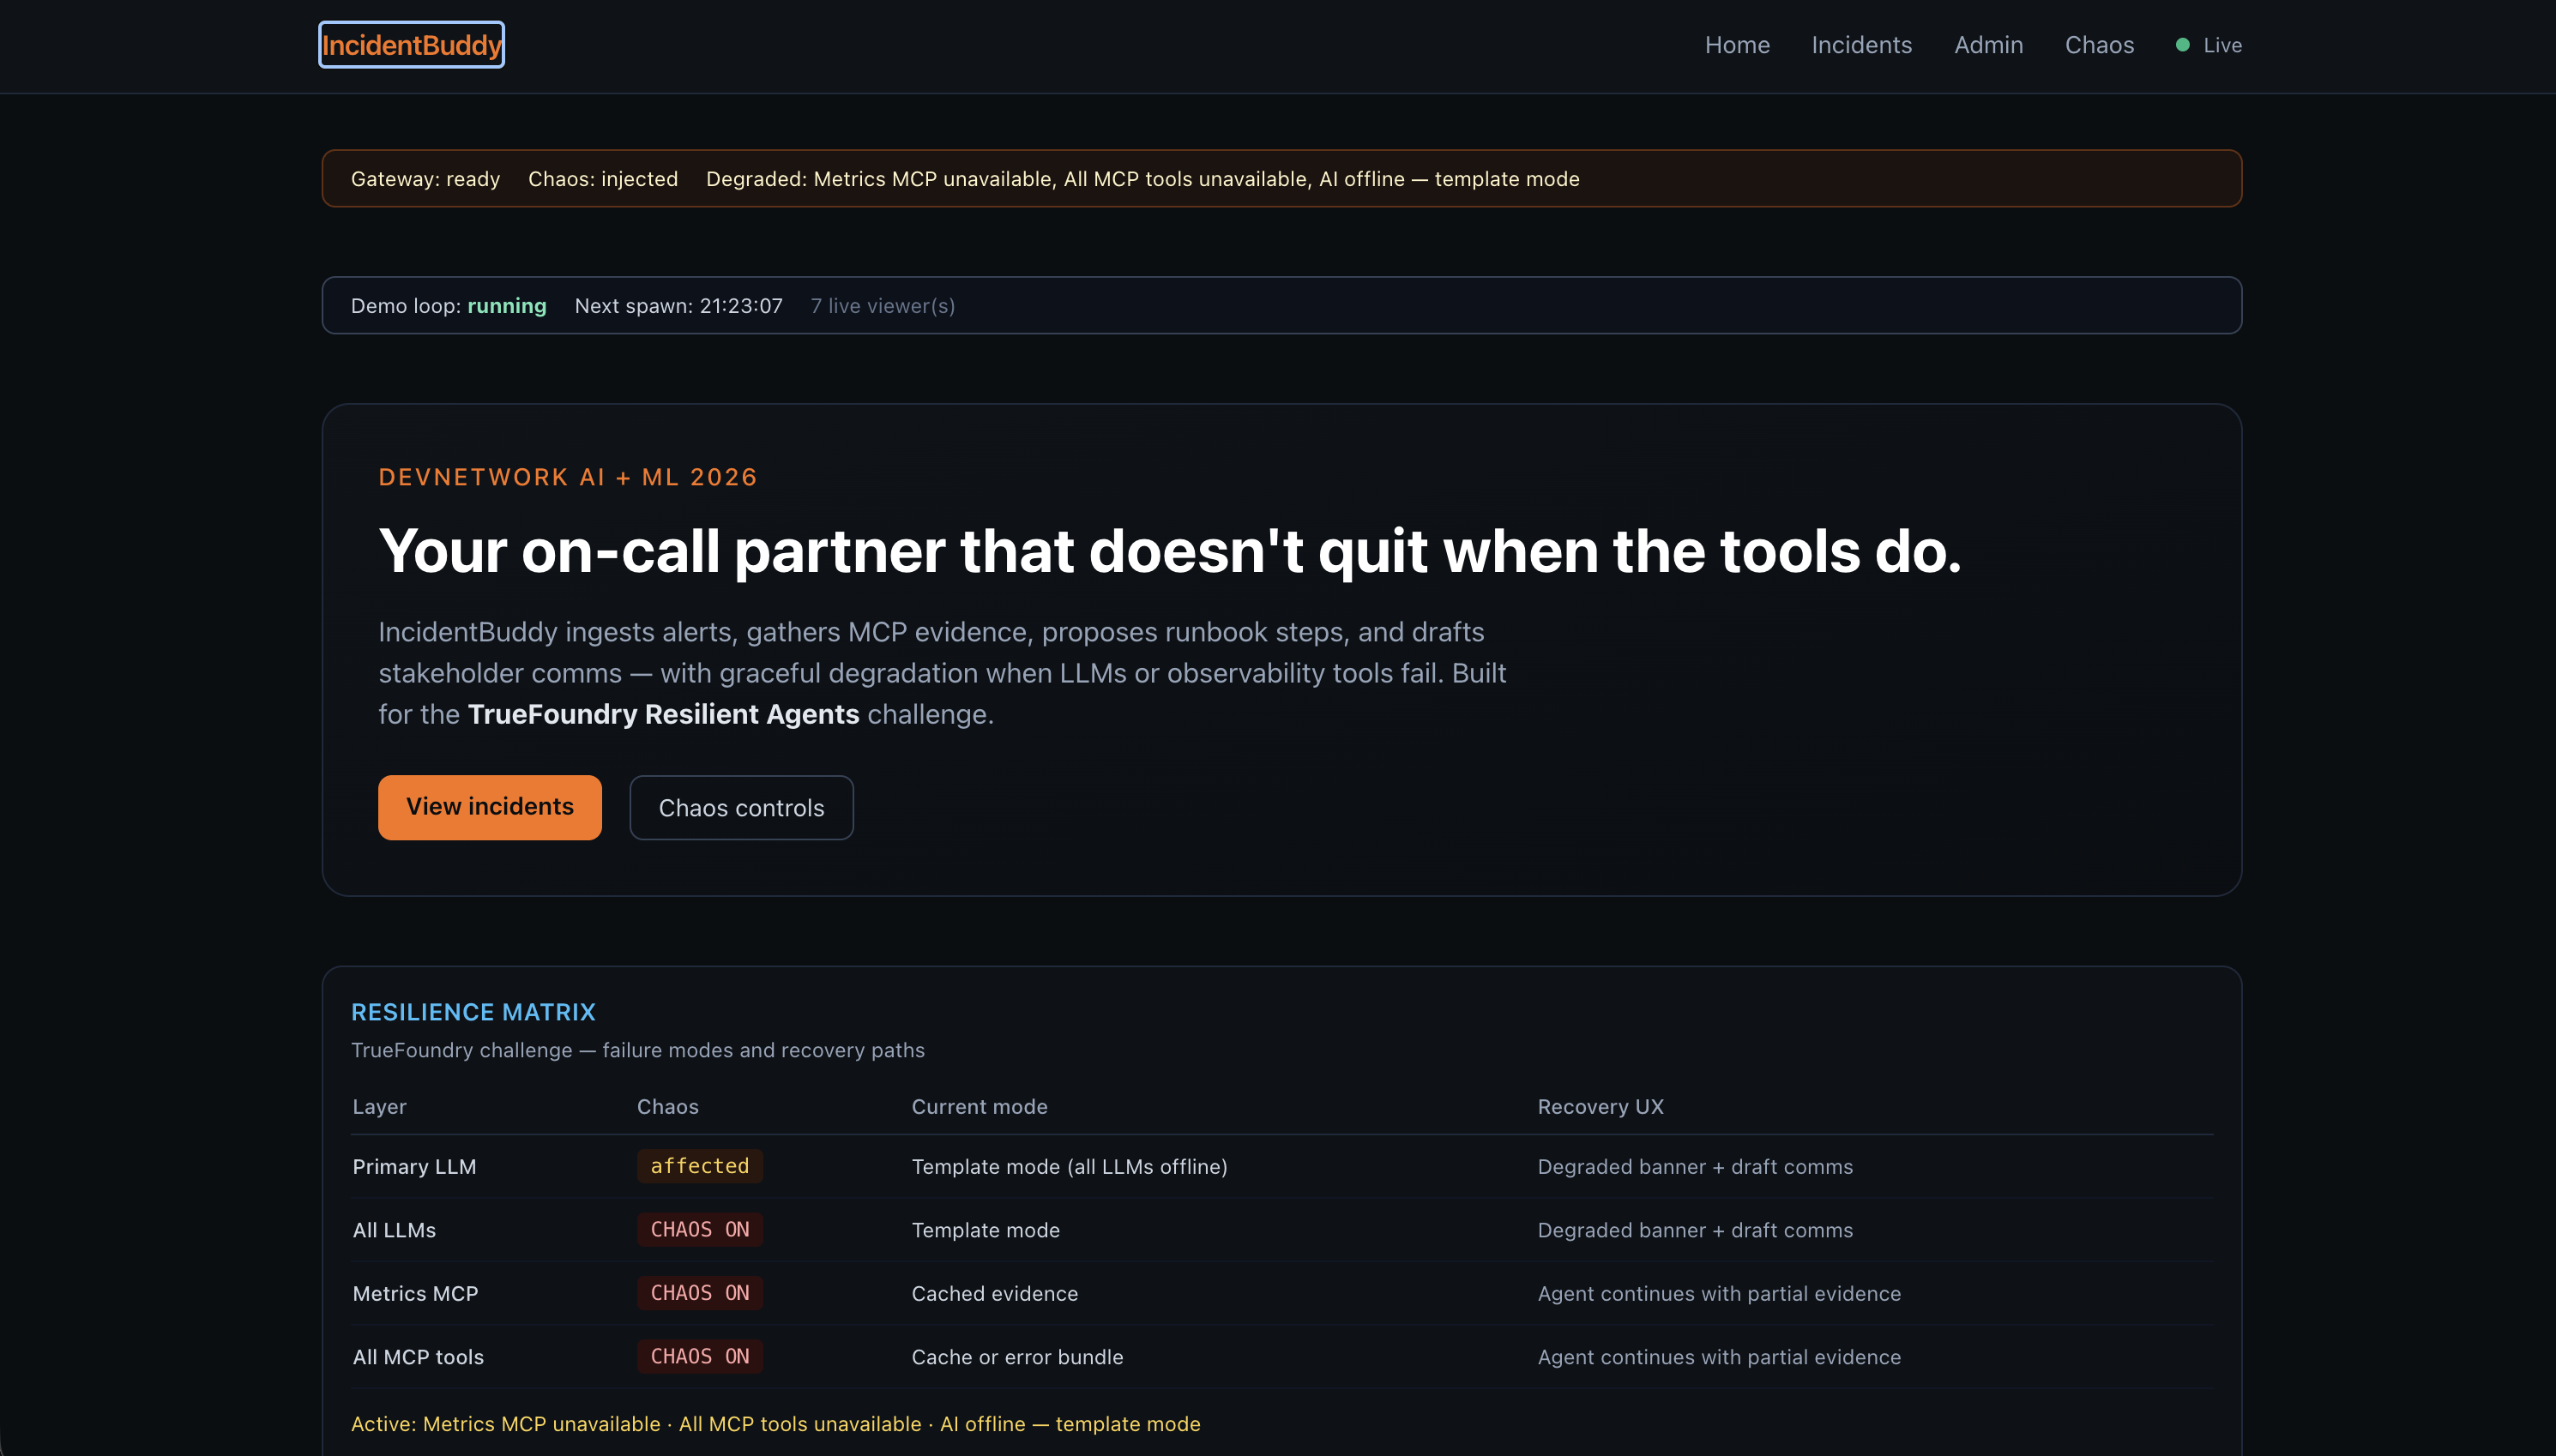
Chaos Resilience Matrix
-
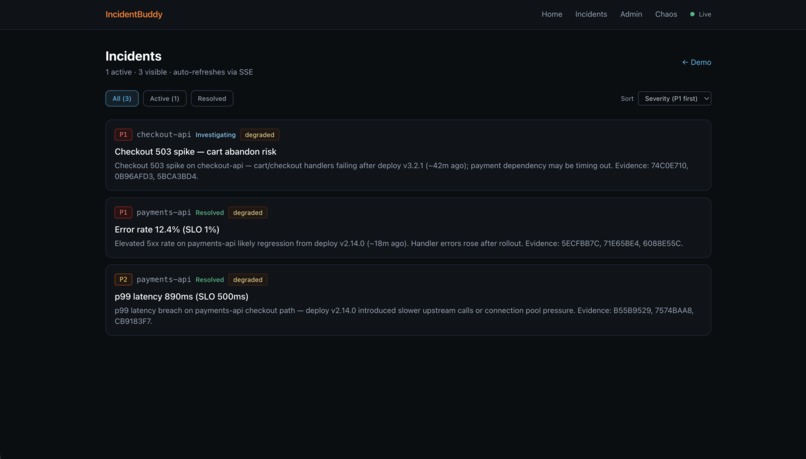
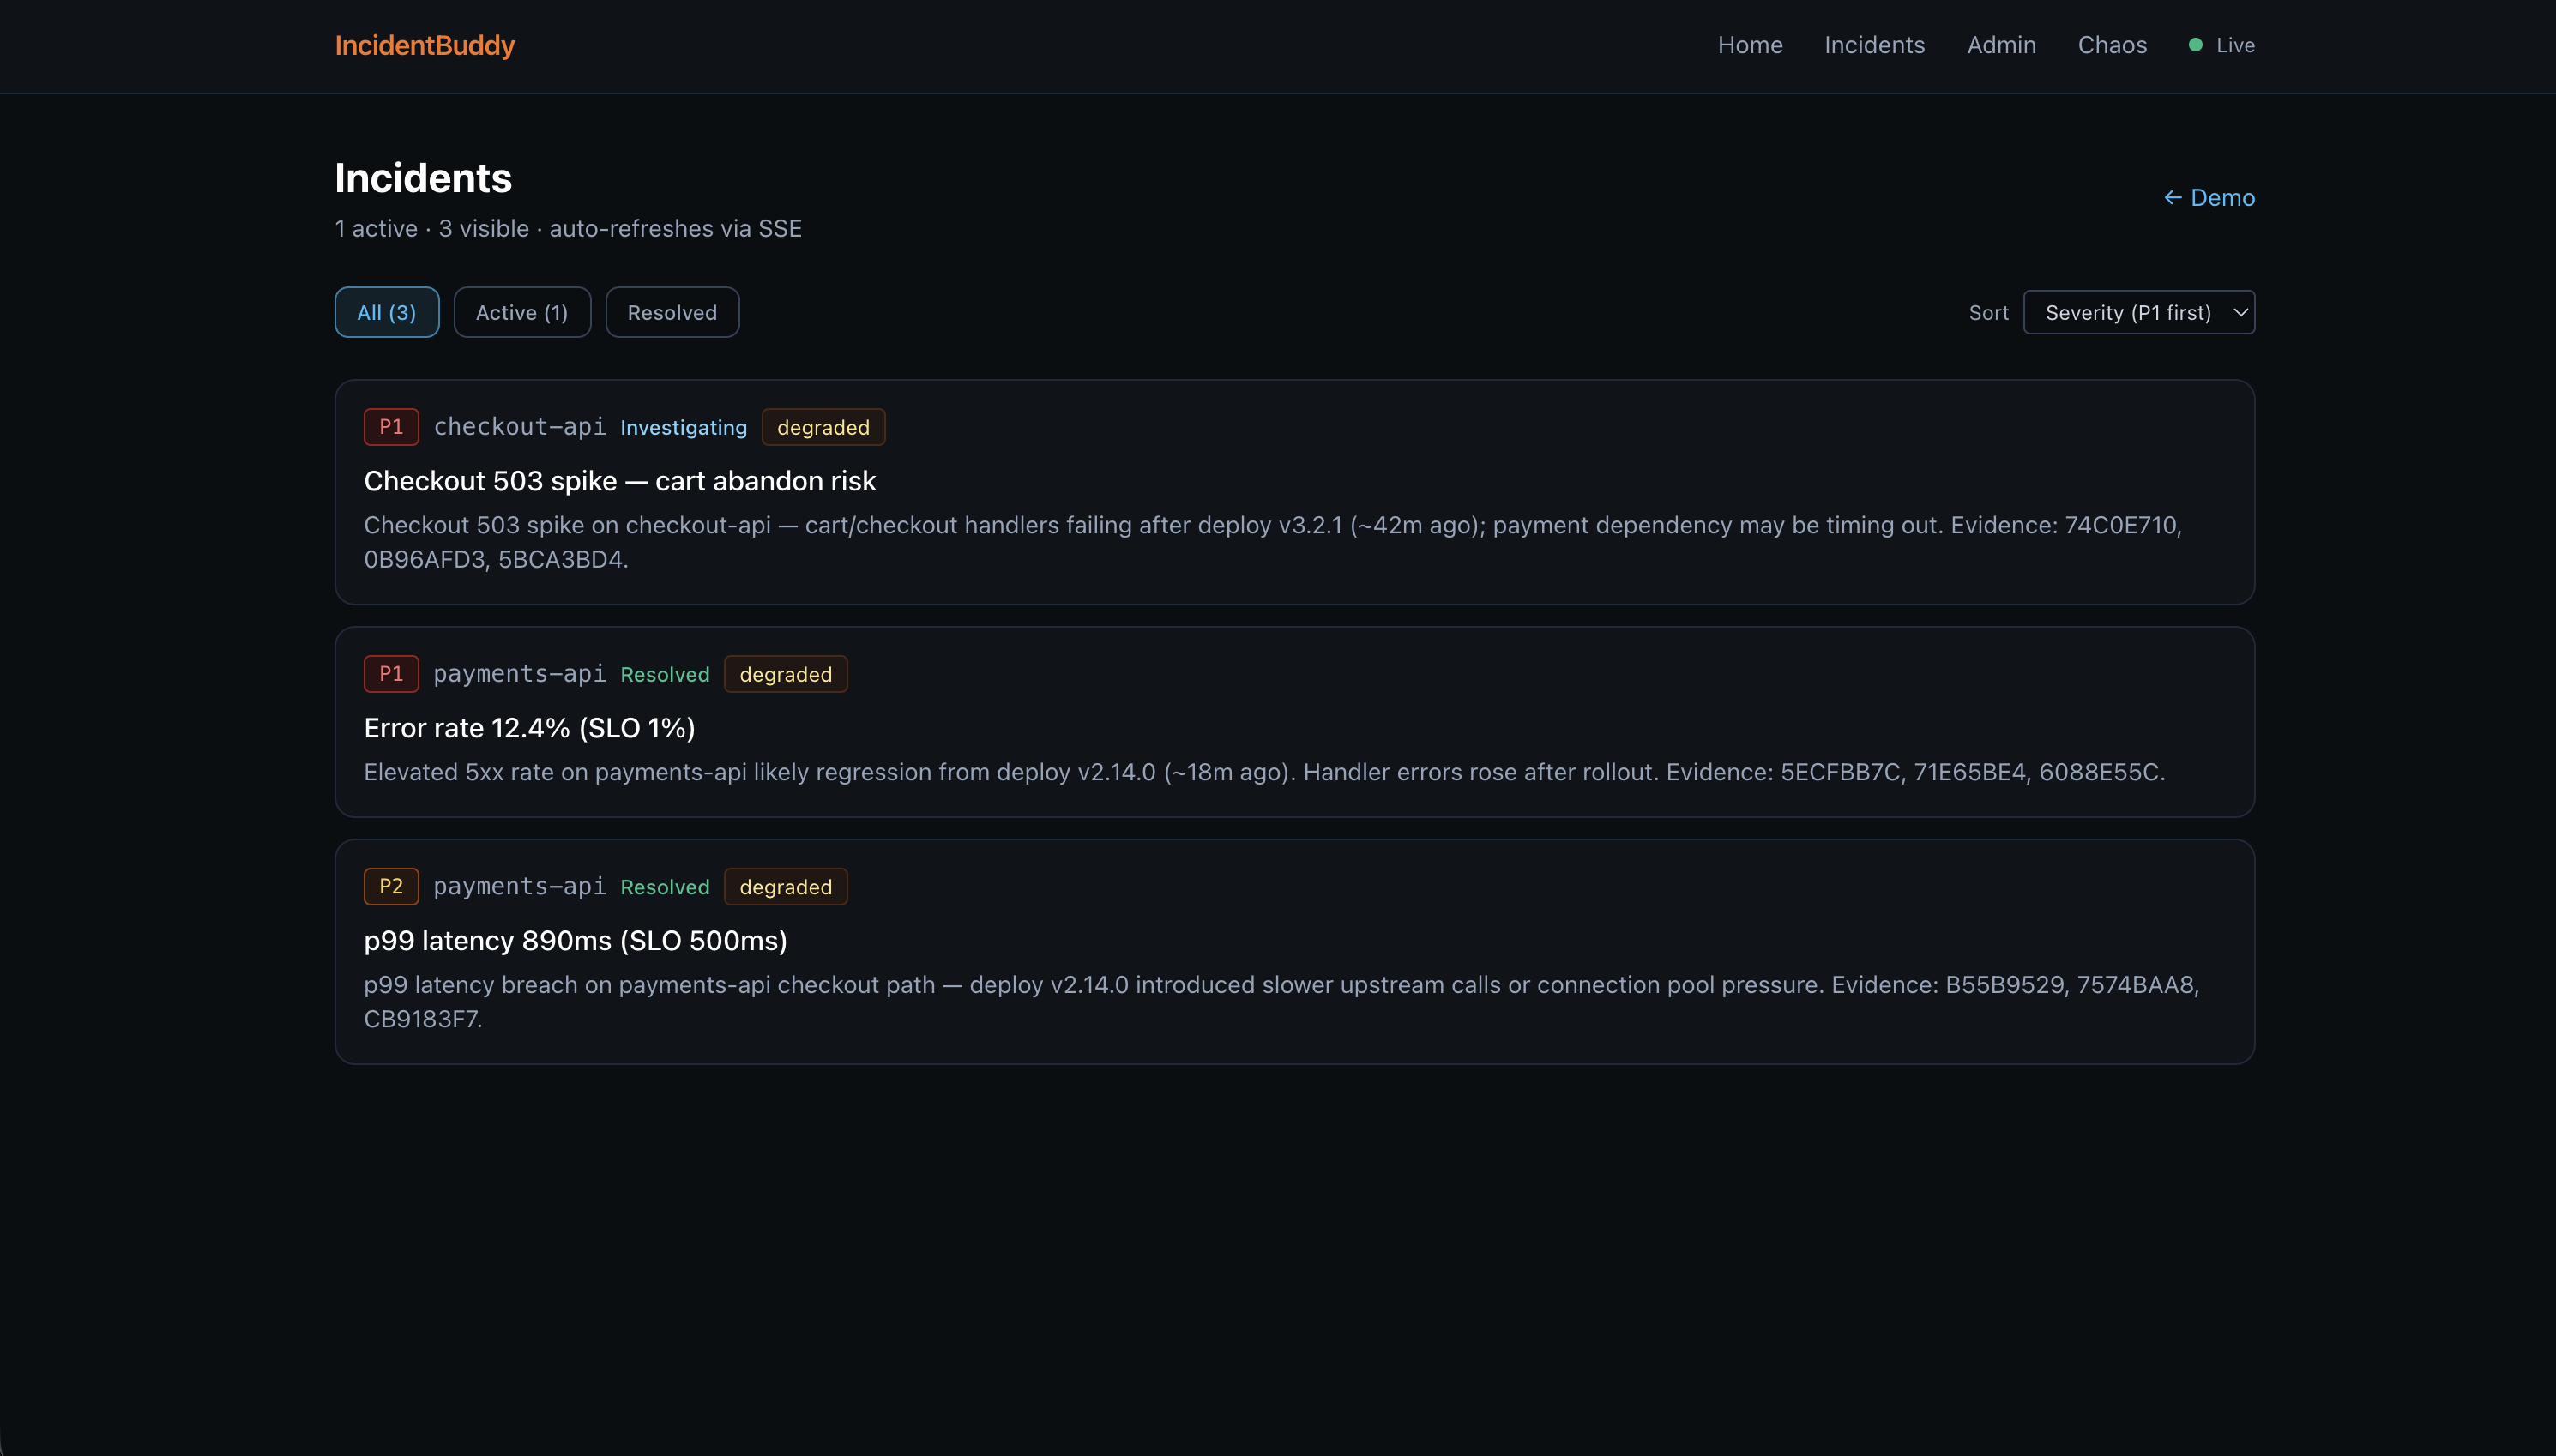
Incidents
-
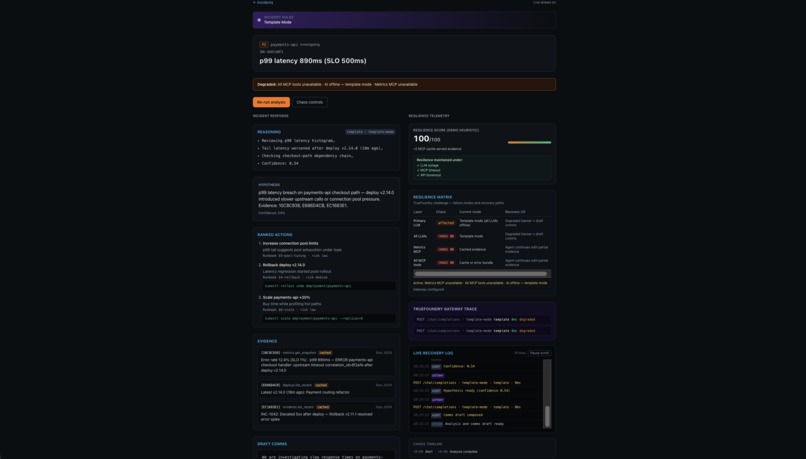
Latency Incident
-
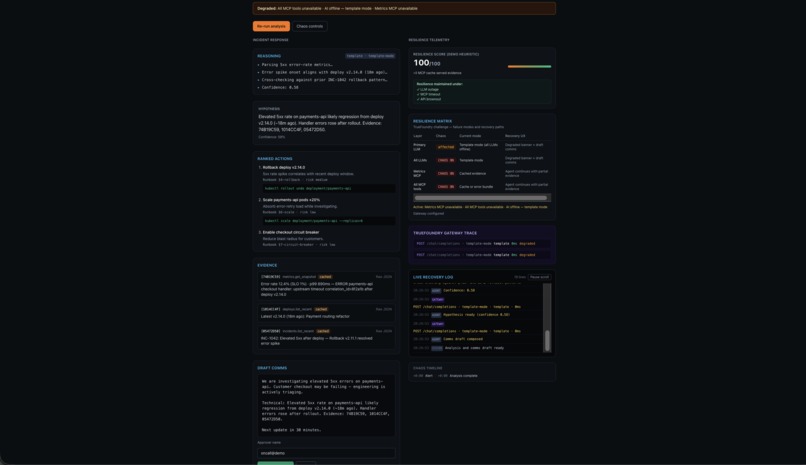
Error rate Incident
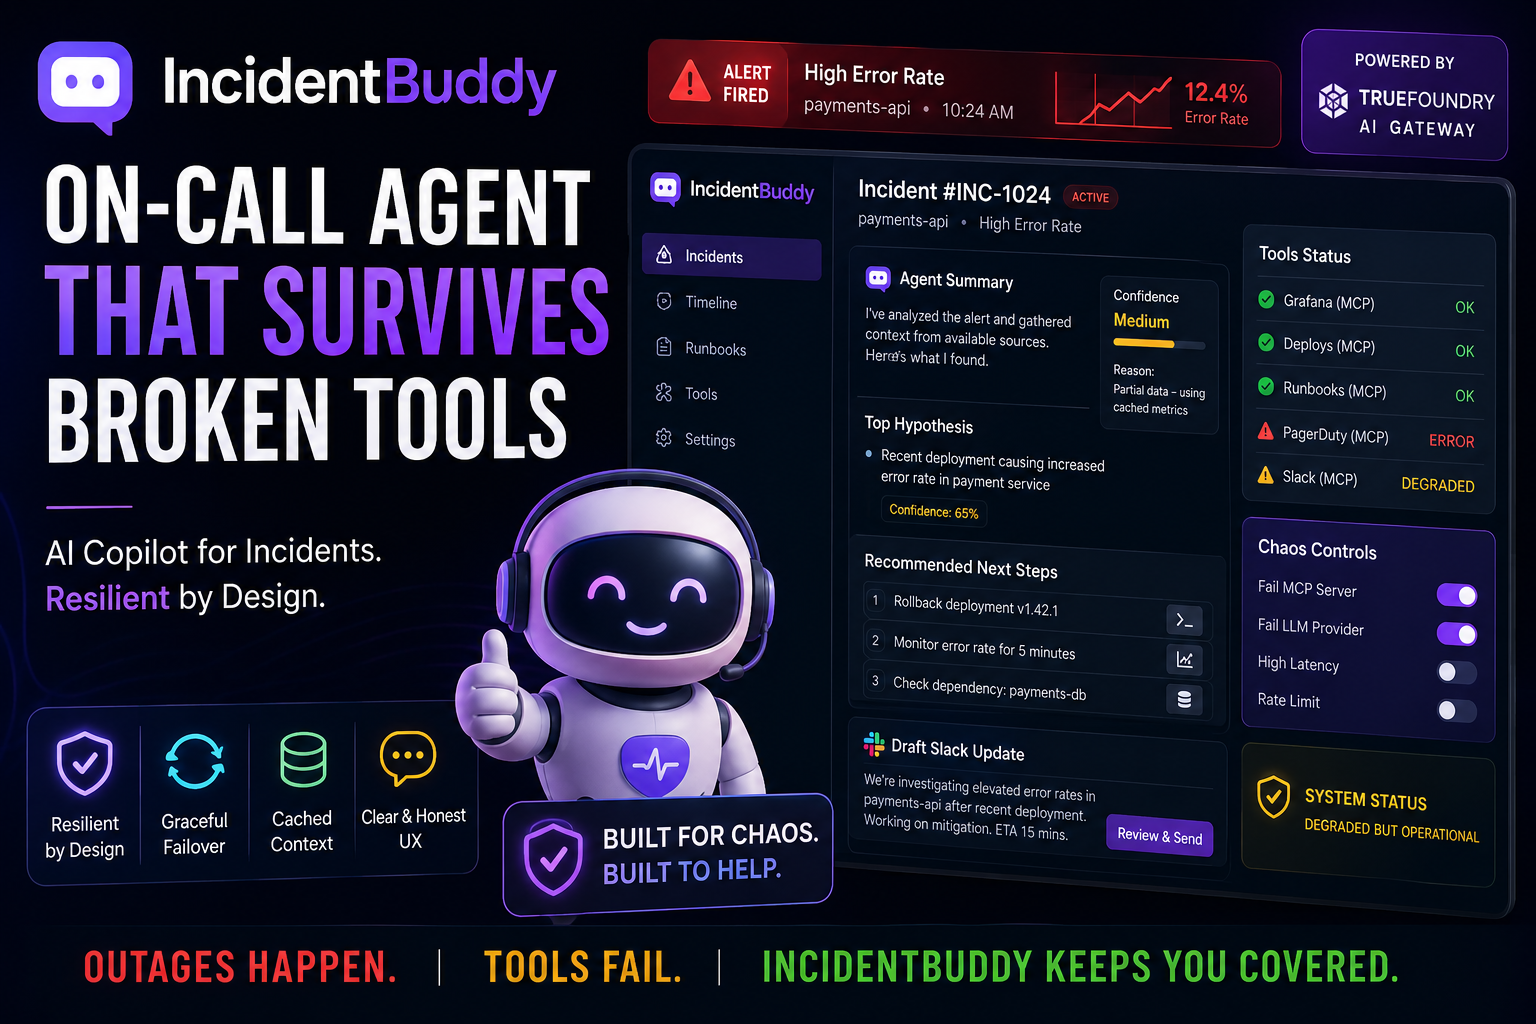
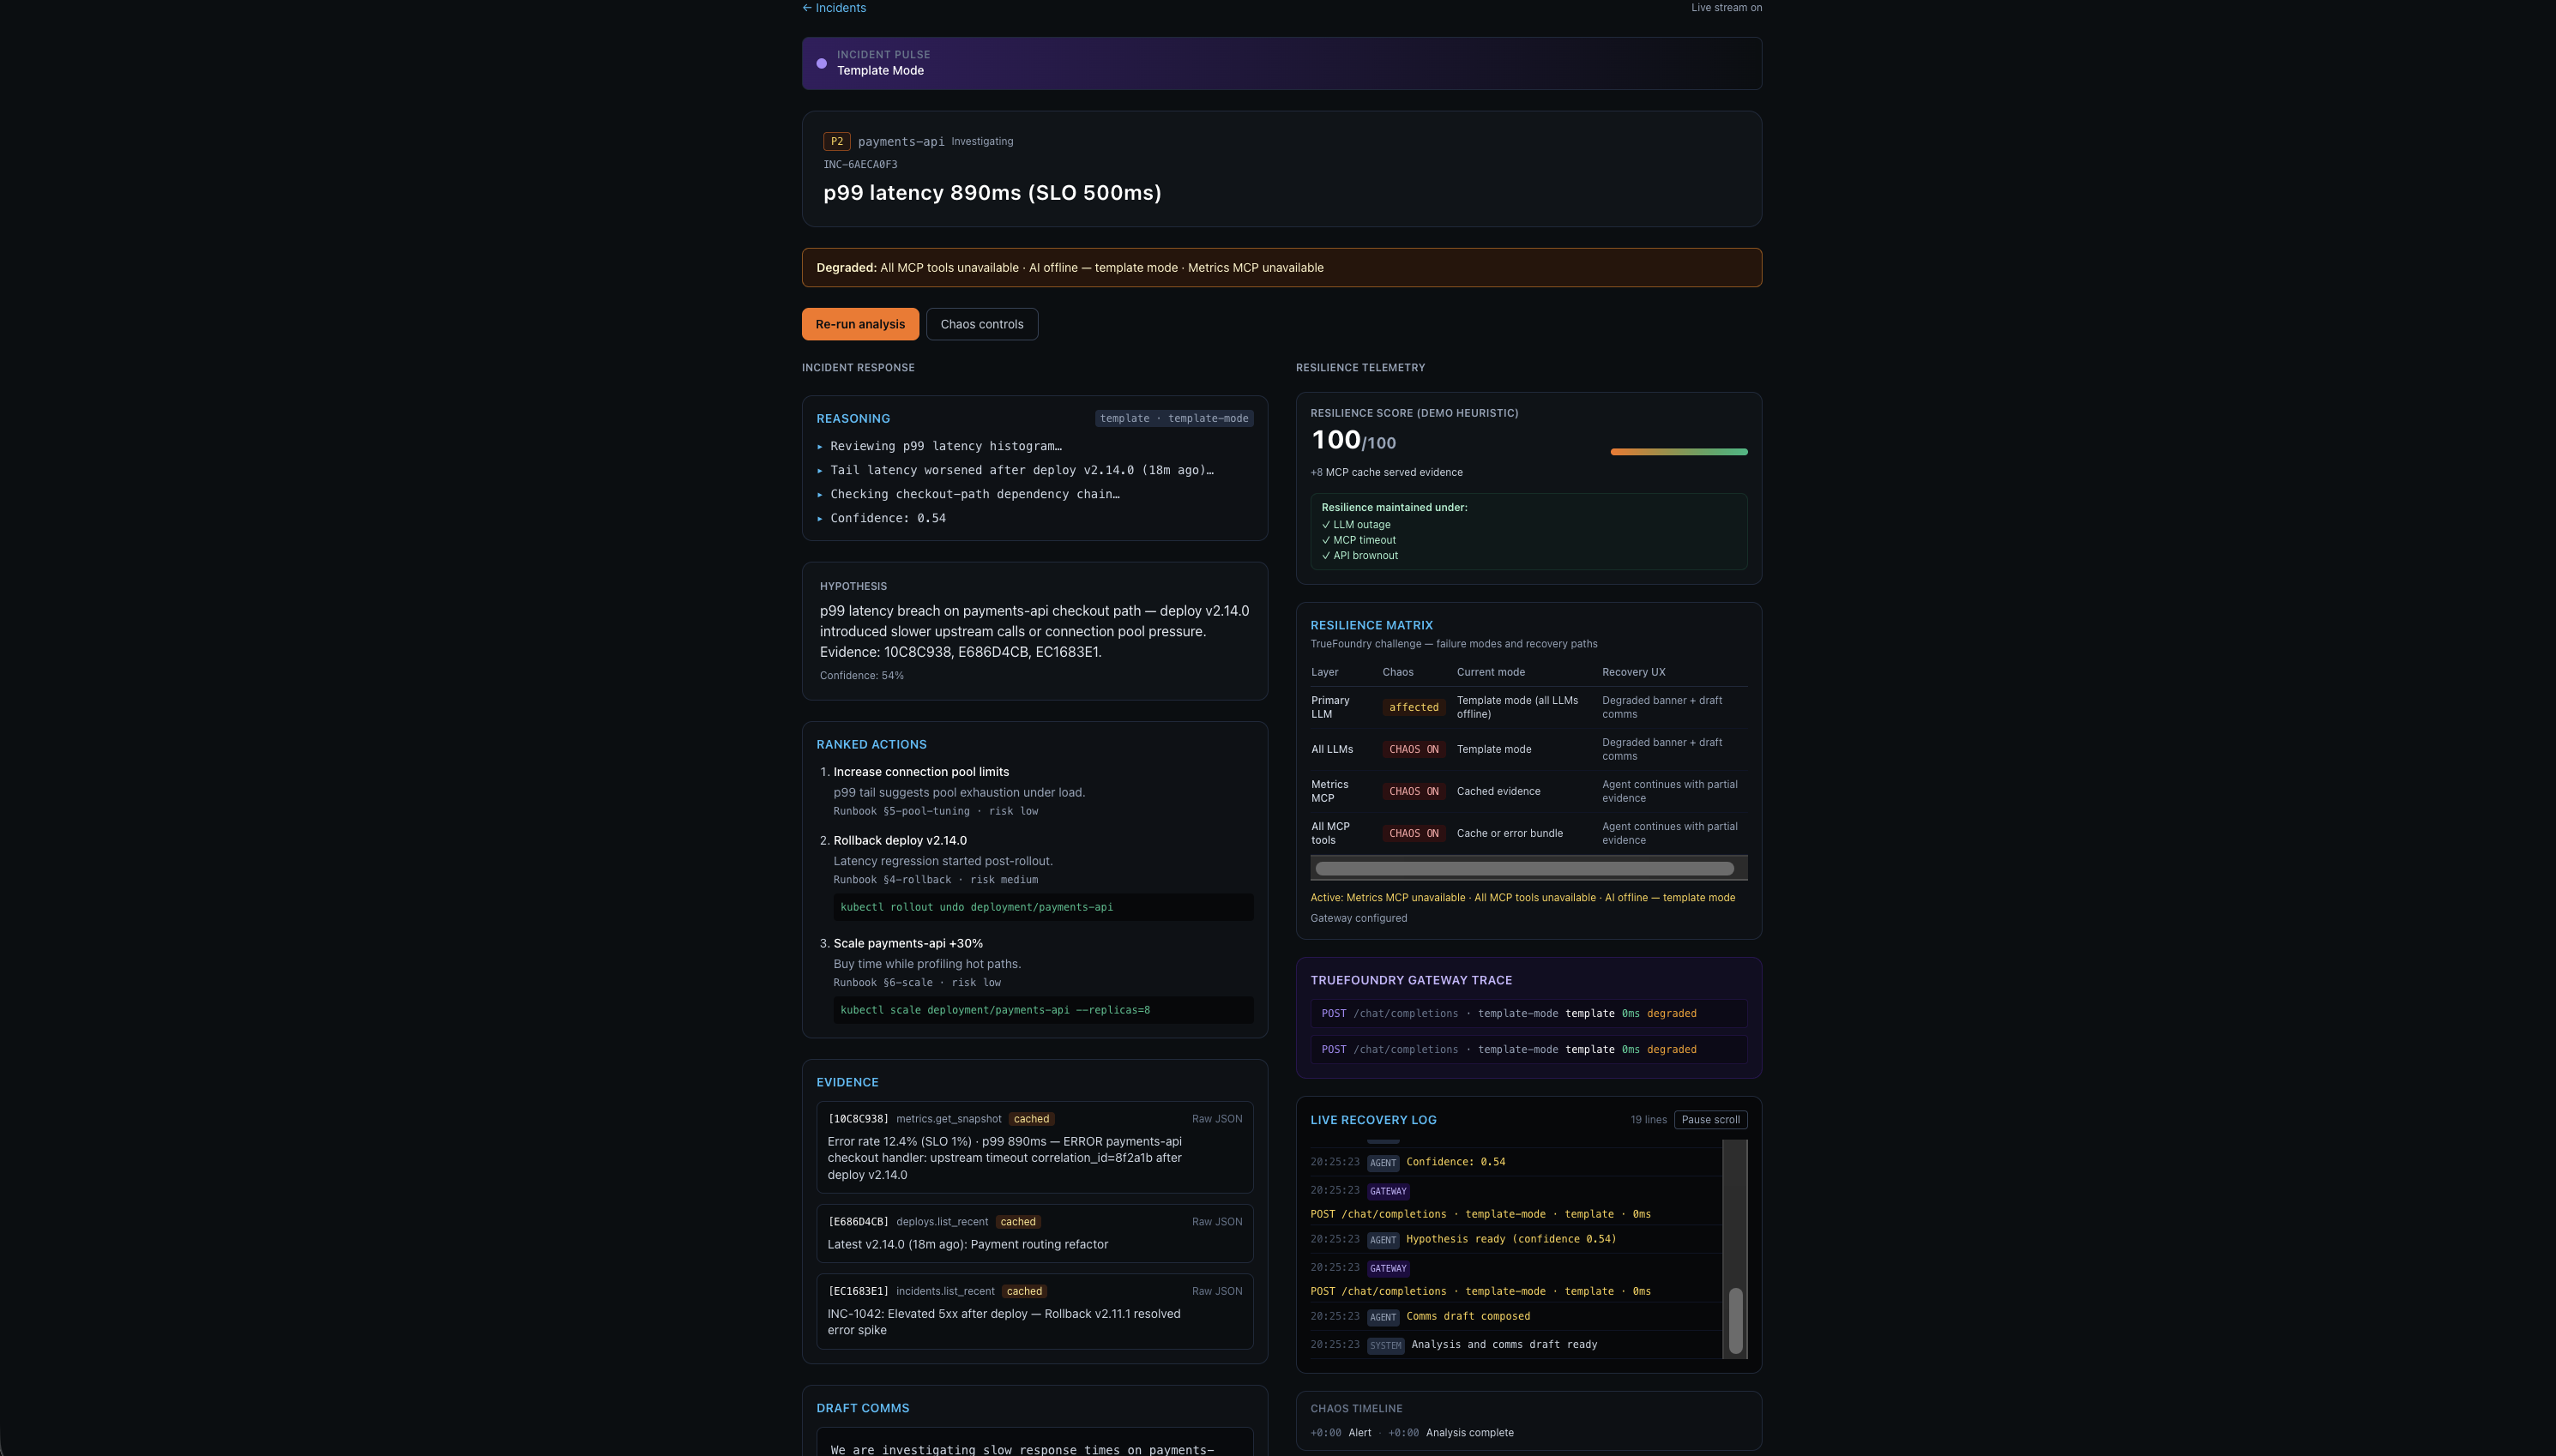
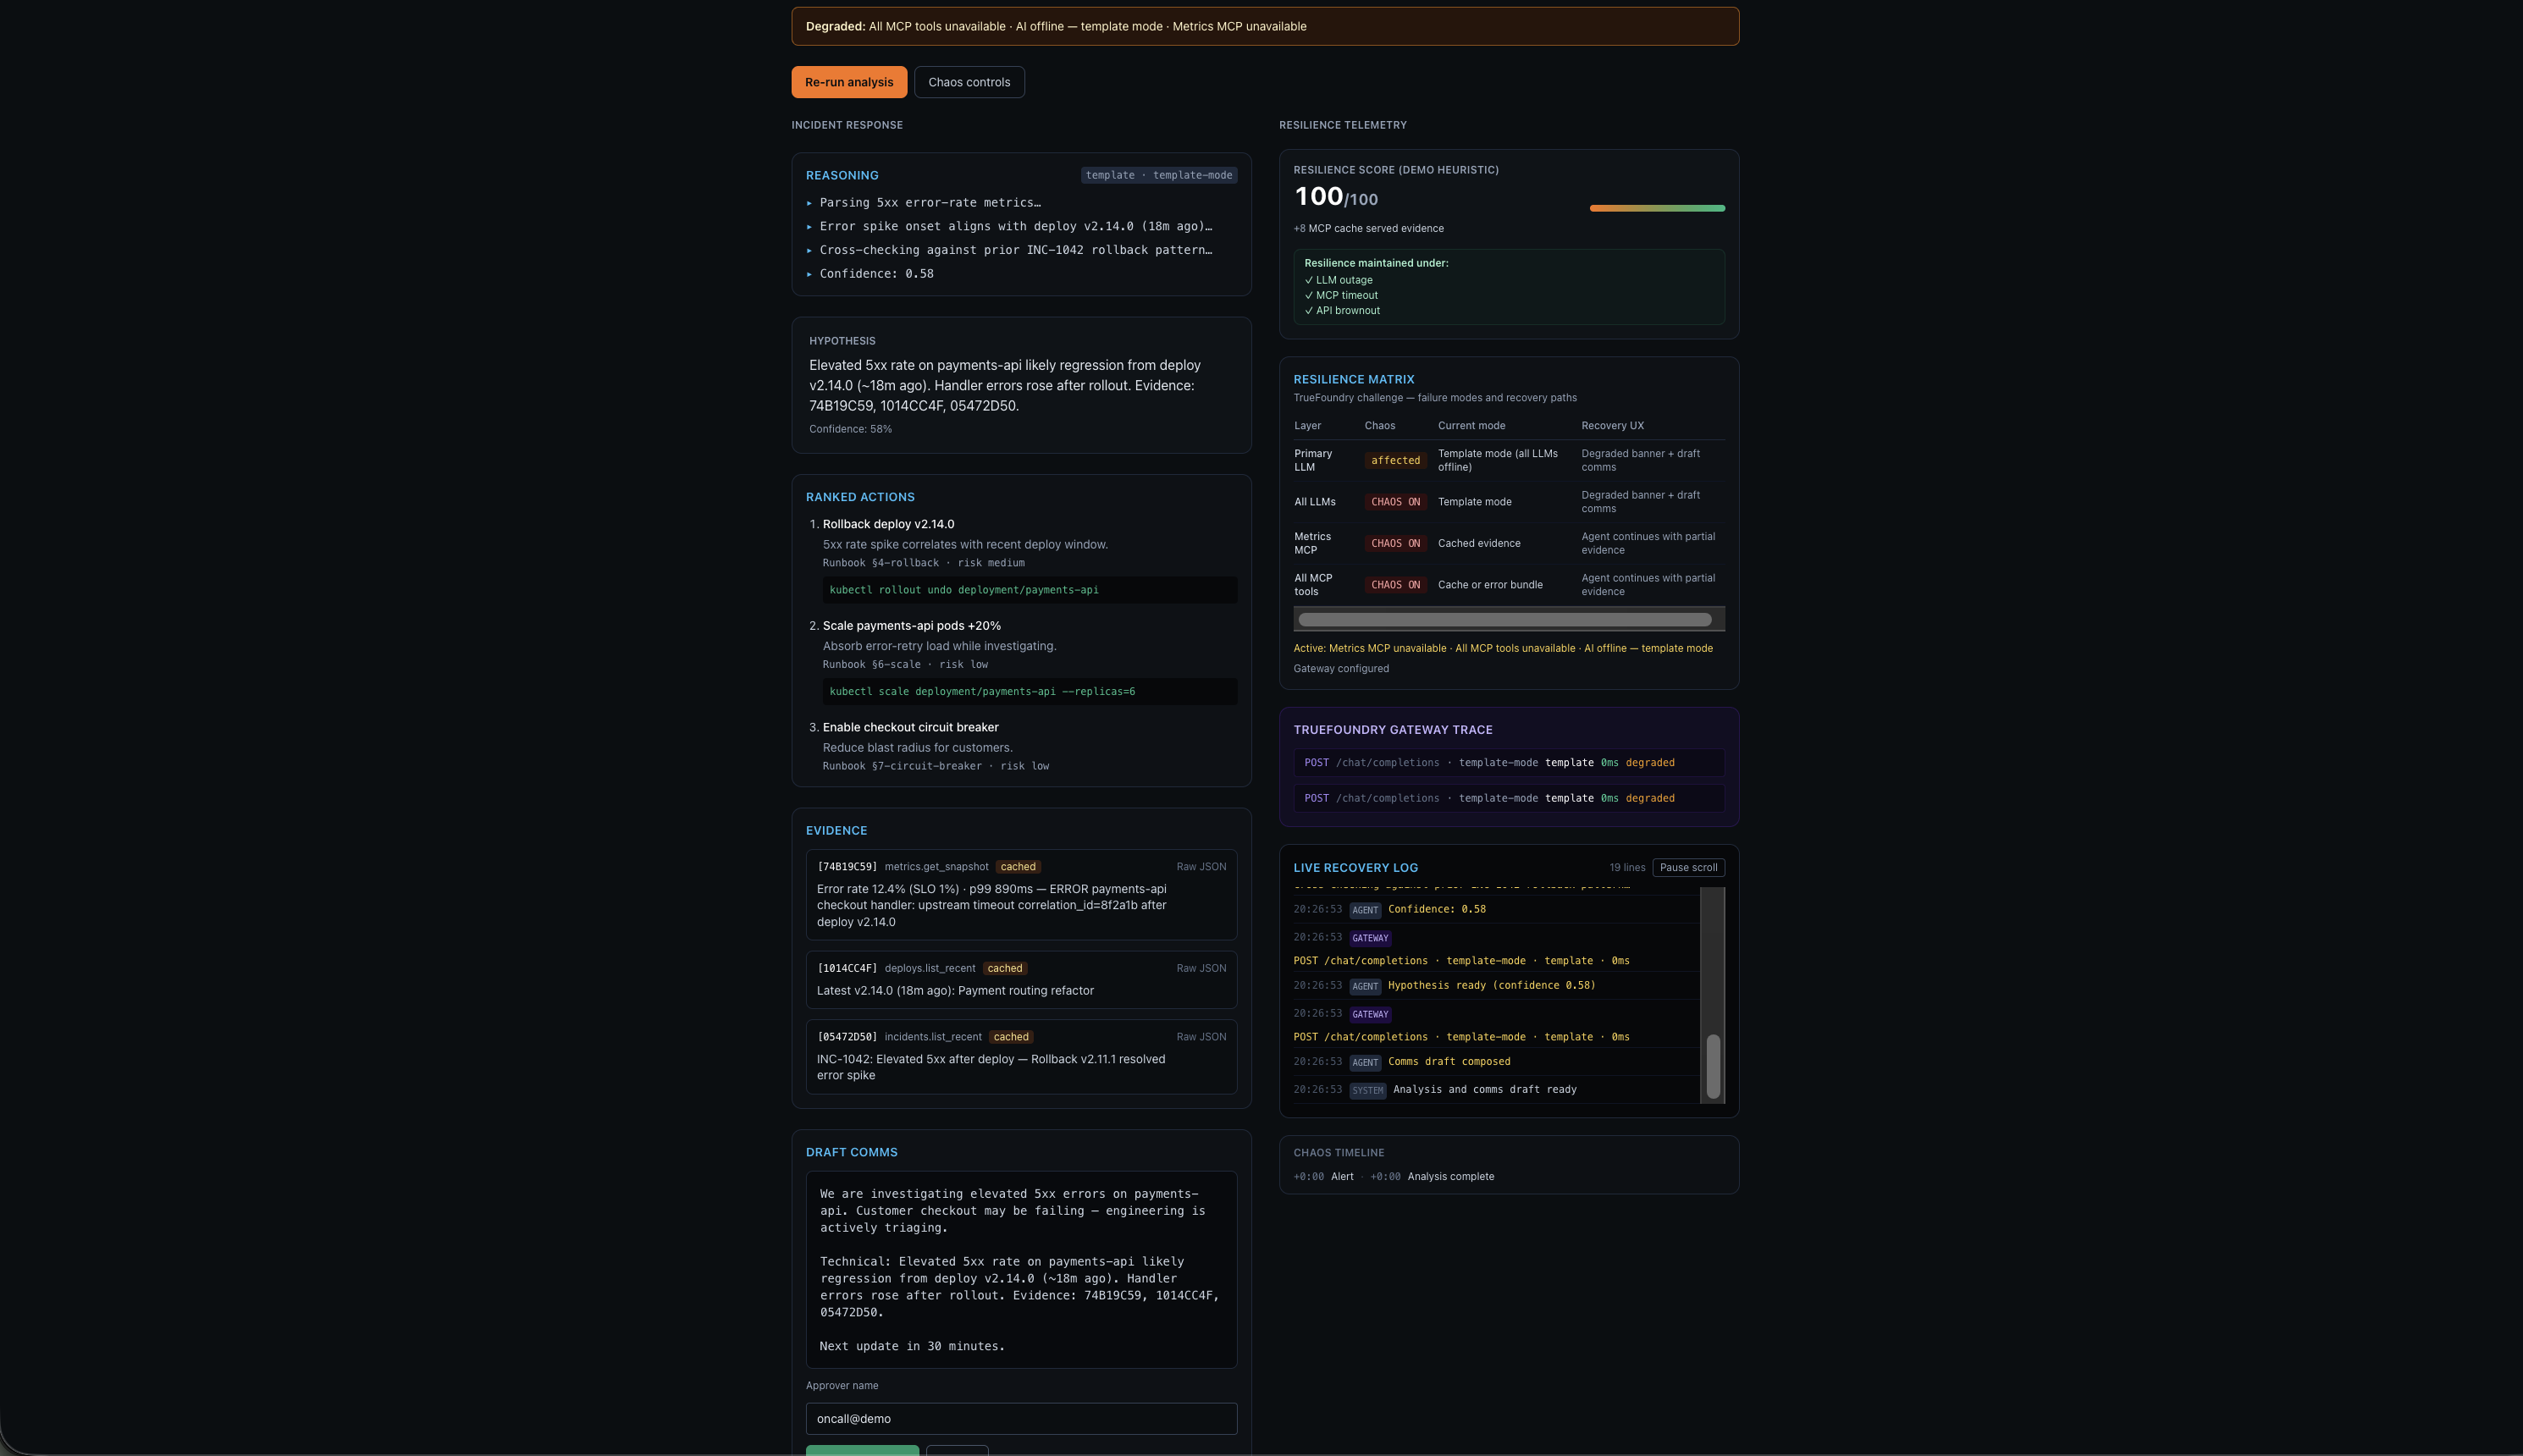
Inspiration
On-call engineers are paged for symptoms, then spend 15–45 minutes stitching together Grafana, deploy logs, PagerDuty, and Slack—while leadership asks for a two-sentence update. The failure mode that actually hurts isn’t the happy path; it’s when the LLM rate-limits or MCP metrics time out in the middle of an incident. We built IncidentBuddy for the TrueFoundry Resilient Agents track because a copilot must degrade visibly and keep moving, not return a silent 500 or an empty panel.
What it does
IncidentBuddy is an on-call incident copilot that:
- Ingests alerts via webhook and demo scenarios (payments-api error rate, checkout latency, auth token failures)
- Gathers MCP-style evidence — metrics, deploys, prior incidents — with live vs cached badges on every bundle
- Runs a multi-phase agent: triage → gather → analyze → ranked runbook actions → draft stakeholder comms
- Human-in-the-loop comms: approve or reject the Slack draft before anything is “posted”
- Resilience-first UX: incident pulse bar, resilience score, failure-mode matrix, gateway trace, failover animation, typewriter reasoning stream, and SSE-backed live recovery log
- 24/7 demo loop: background scheduler keeps the inbox alive for judges; falls back to fixtures when no one is watching to save LLM quota
When you inject chaos from the admin panel, the system fails gracefully:
| Failure | Behavior |
|---|---|
| Primary LLM down | OpenAI-compatible gateway fallback route; visible in transcript |
| All LLMs down | Template mode — scenario-aware analysis still completes |
| MCP timeout | Cached evidence bundles; UI shows degraded badges |
How we built it
| Layer | Choices |
|---|---|
| API | Python 3.12, FastAPI, SQLite, APScheduler (in-process loop) |
| UI | Next.js 14 App Router, Tailwind, SSR incident pages, same-origin /api proxy, SSE live events |
| LLM | TrueFoundry OpenAI-compatible gateway — Nemotron primary, OpenAI fallback, template degradation |
| Resilience | DB-backed chaos flags, mutual-exclusive MCP/LLM tiers, resilience score heuristic, redaction for LLM prompts |
| Deploy | Docker Compose locally; GCP Cloud Run (API + UI) + Secret Manager + Terraform; GitHub Actions CI |
| Demo | One-click TrueFoundry judge replay, five scenario presets, pause/resume loop for clean video |
Browser → Cloud Run (Next.js) → /api proxy → Cloud Run (FastAPI) → SQLite
                                              ├── MCP mock adapters
                                              ├── Agent orchestrator
                                             └── LLM gateway (TrueFoundry / OpenAI)
Challenges we ran into
- Chaos vs “current mode” in the matrix looked contradictory until we split “what you toggled” from “what the gateway is doing now”
redact_for_llmcrashed on list-shaped evidence — fixed JSON serialization before analyze- Admin token 401s from React state lag — fixed with synchronous
sessionStorageseeding before API calls - Demo reset 500 from a missing
loop_stateimport — fixed + regression test - Cloud Run frontend image required a stable
public/directory in Docker; CI needed committed ESLint config and pytest headers forDEMO_TOKEN - Template comms could overwrite richer scenario drafts — guarded empty template bodies from the gateway
Accomplishments that we're proud of
- End-to-end resilience story in under two minutes: chaos on → re-run → failover visible → chaos off → reset
- TrueFoundry judge demo — single button runs simulate + LLM failure + MCP stress + recovery narrative
- Five scenario presets with severity-scaled confidence and service-specific hypotheses
- 17+ automated backend tests (chaos exclusivity, redaction, API auth, demo reset)
- Production path on GCP with Secret Manager, Cloud Build, and GitHub Actions
What we learned
- Judges need visible degradation (transcript routes, matrix, failover strip)—not just logs
- A quota-aware loop (live LLM only when someone is on the dashboard) makes a 24/7 URL affordable
- HITL comms is a cheap trust win for hackathon demos and maps to real incident comms workflows
What's next for IncidentBuddy
- Real MCP servers (Datadog, PagerDuty, GitHub) instead of fixtures
- Slack write path beyond mock approve/post
- Durable DB (Cloud SQL / Turso) instead of ephemeral SQLite on Cloud Run
- Post-incident export of gateway traces and transcripts
- Command suggestions only (no auto-exec) for production safety

Log in or sign up for Devpost to join the conversation.