Tagline
A compass, not a mirror: vocational discovery where every claim is backed by sealed evidence and no number about you ever comes from an AI.
Inspiration
Career and self-discovery tools all ship the same thing — a confident number. "Spatial reasoning: 68%." If a model produced that number, it is invented: not reproducible, not auditable, and it drifts the moment you flatter it. Over a claim about who a person is and where they should go, that is unacceptable. COMPASS began from a conviction: "what should I dedicate myself to" is not a personality verdict to be pronounced, it is a fit between the capabilities you have actually demonstrated and what a path requires — something you discover by experiment, not by rating yourself on a quiz. We set out to build a vocational partner that could never become a flattering mirror.
What it does
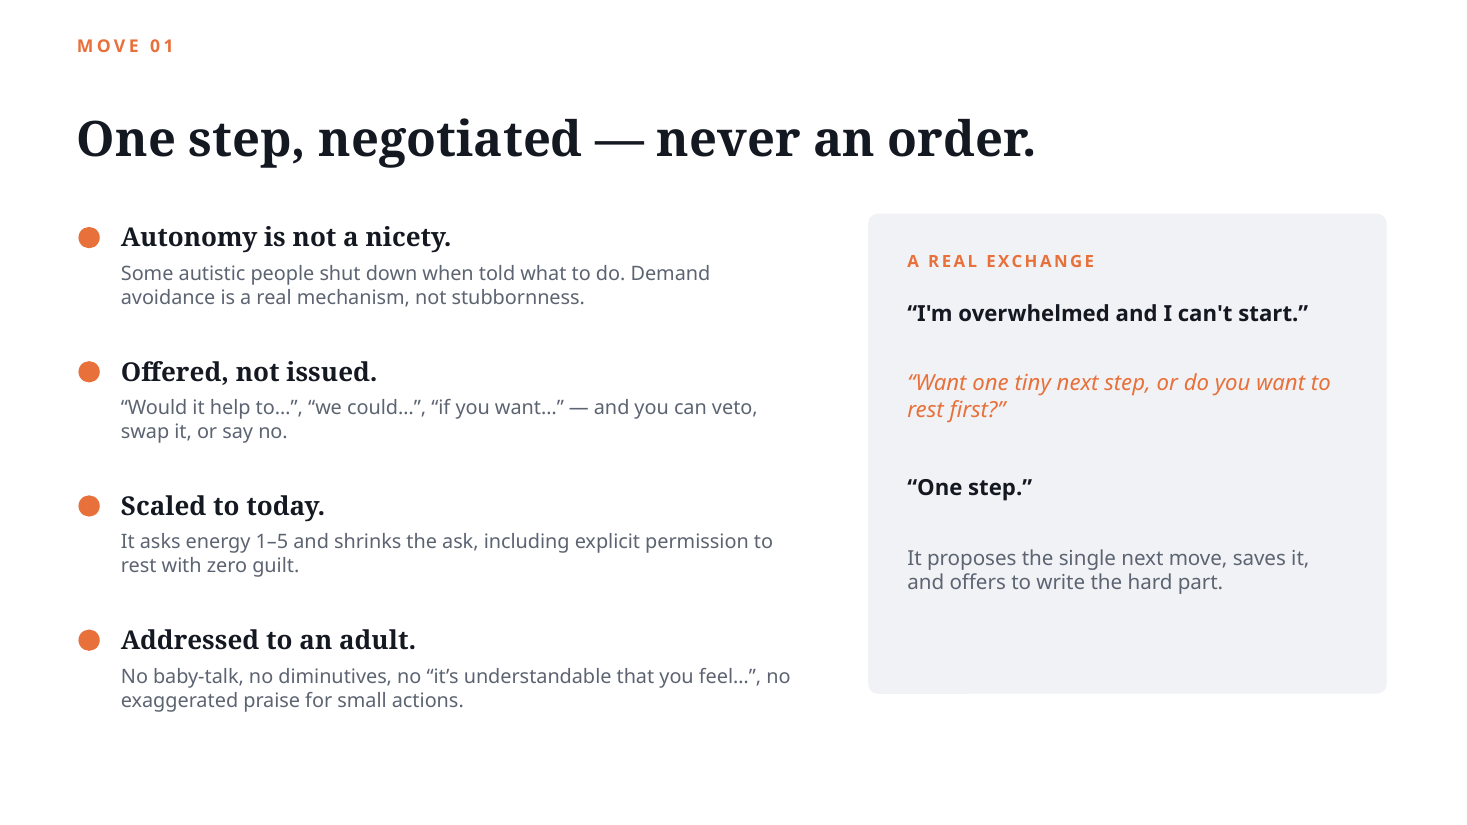
Starting is simple. You get a Compass ID (no email, no password), a built-in 60-second Quick Tour, and an interface that always shows you one single next step — so you begin in seconds and can stop anytime, nothing is lost. Choose your depth: a Calm guided path (the default), the Full dashboard to explore, or just chat with the multi-agent team. You never do everything at once — COMPASS always offers exactly one next action.
Under that simplicity, here is everything it does:
Two intake tests — two separate categories, each a validated model. Neither returns a verdict; a high score seeds a hypothesis to test.
- Big Five — 50 questions. Broad personality traits (OCEAN), public-domain IPIP items, on a 1–5 scale.
- RIASEC — 60 questions. Vocational interests (Holland's model), 60 original items we wrote ourselves (the model is free; our own items stay clear of proprietary tests), on a 1–5 scale.
Then the abductive cycle, step by step — every step is sealed and recorded in the audit chain:
- State two rival hypotheses about a capability — competing explanations, held alive at once.
- Bring in evidence — self-report, behavioral, outcome, or paste a life narrative and let the Extractor turn it into candidate signals (they arrive pending).
- Validate the evidence you agree with — only your validation makes it real; the model has no authority.
- Link validated evidence to a hypothesis — it only counts once linked.
- Recompute & reseal — the deterministic engine computes the integer 0–1000 index and seals it (SHA-256, hash-chained).
- Design a discriminating experiment — with its failure criterion written before you run it — and preregister it.
- Run it, record observations, and close it — the outcome becomes new evidence.
- Recompute to watch the index move; Narrate — Gemini puts the sealed state into words (flip the language and narrate again: the words change, the numbers and the seal do not).
And more:
- Vocational fit: name a trajectory, or adopt an occupation from the O*NET 31.0 Database (12 occupations, CC BY 4.0), and see it requirement by requirement (MET / SUPPORTED / OPEN / AGAINST) — what the path requires vs. what your evidence shows.
- Chat with a real multi-agent team (Google ADK), live — a Companion orchestrating an Analyst, an Activity Scout (Google Search) and a Reflector.
- Your version vs. the record: a confrontation view surfaces where your self-perception and the sealed evidence disagree.
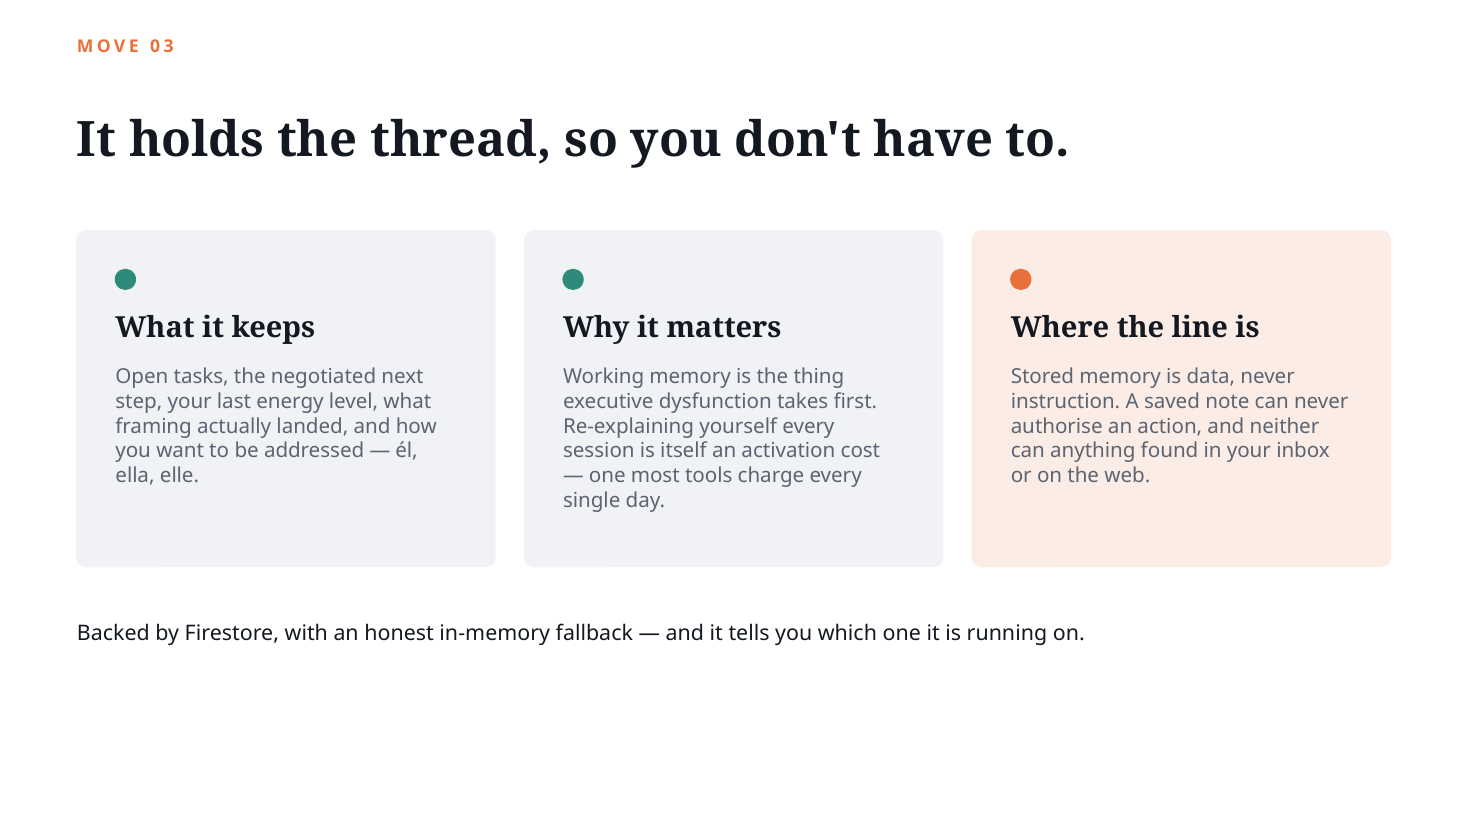
- Calm mode, bilingual English / Spanish, multi-user with no login (each visitor gets their own isolated, sealed compass on Cloud Storage). Contradicting evidence weighs more than confirming, so it can never become a flattering mirror.
Every claim is backed by recorded, sealed evidence; every index is an integer 0–1000 computed with exact fractions (no float in the decision path), sealed with SHA-256 into an append-only, hash-chained ledger that verifies independently.
How we built it
Two invariants drove every decision:
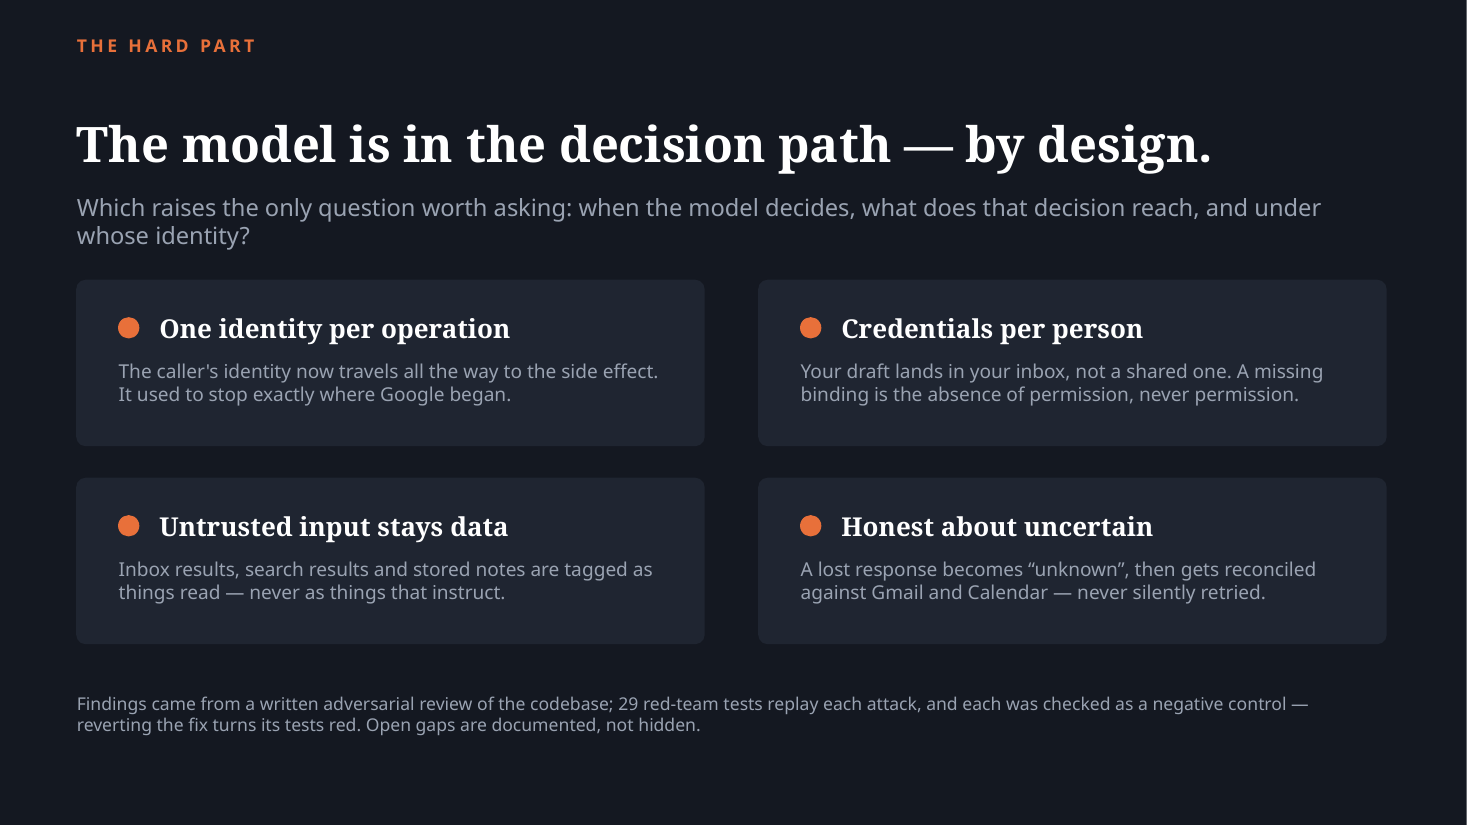
- No claim about the person exists without recorded, sealed evidence.
- No number describing the person ever comes out of an LLM.
A deterministic core (pure Python standard library) computes an integer 0–1000 index with fractions.Fraction — no floating point anywhere in the decision path — and seals it with SHA-256 over canonical, type-tagged, versioned bytes into an append-only, hash-chained ledger with an independent, stdlib-only verifier. Gemini 3.5 Flash on Vertex AI enters only as roles and agents with no authority: an extractor that proposes candidate signals, an abductor that proposes rival hypotheses, an experiment designer, a resource finder grounded with Google Search, and a narrator. The engine seals before any model is called, so the architecture test holds: swap the model and the wording changes — never a verdict, never a seal.
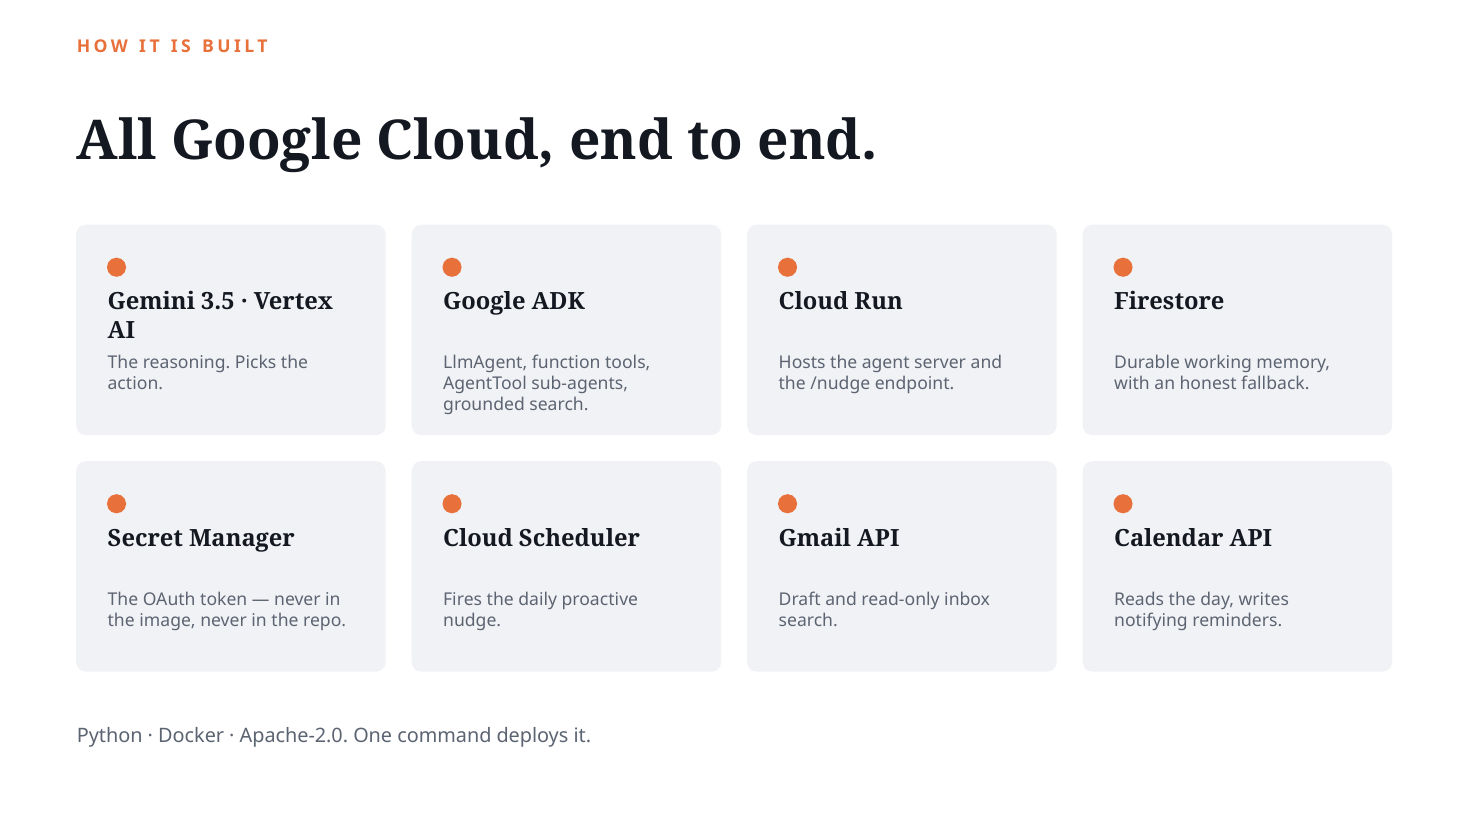
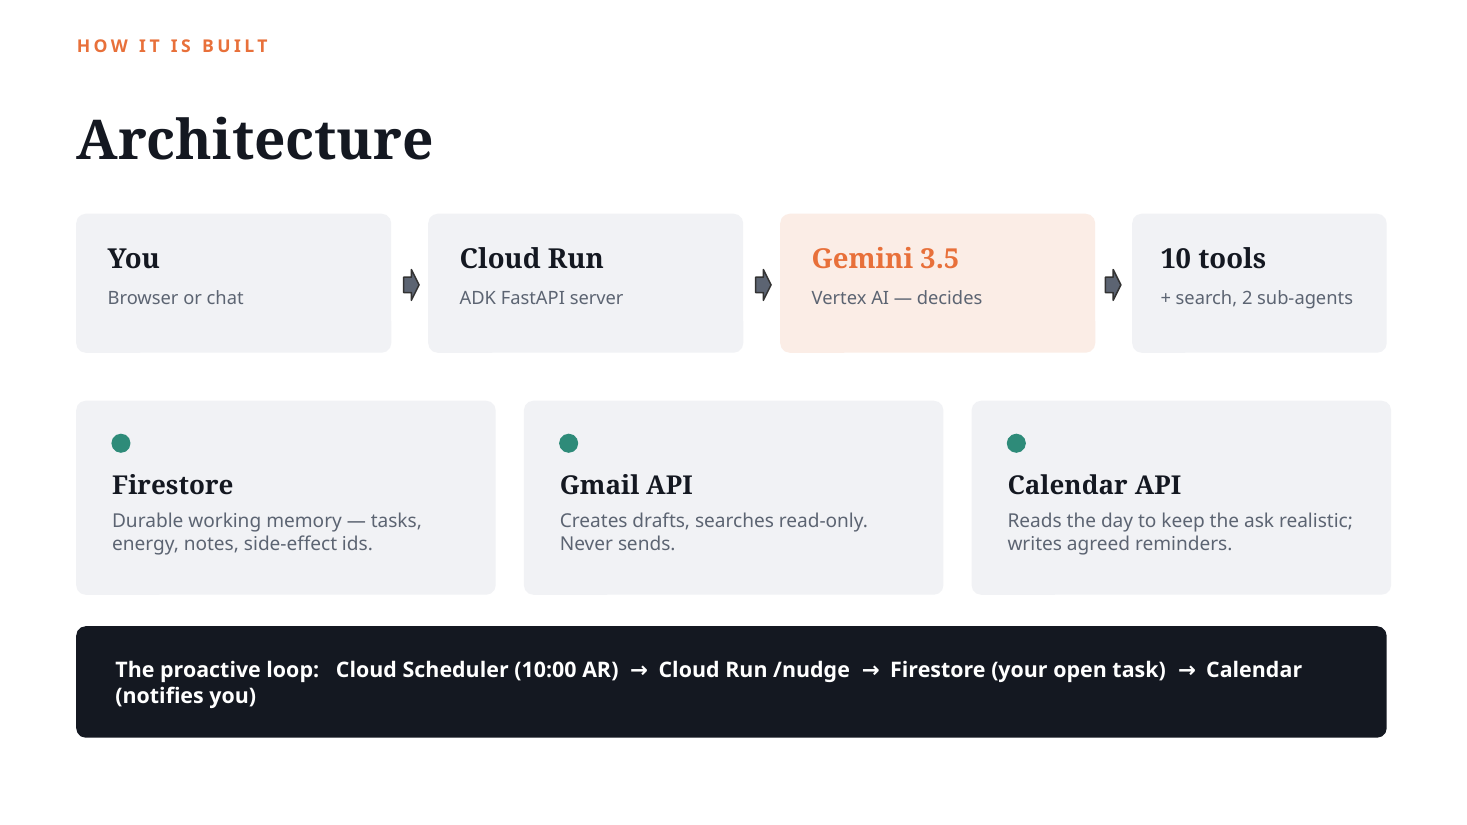
It runs entirely on Google Cloud: a Next.js web app, a FastAPI backend, and a separate Google ADK Web UI for the agent team, all on Cloud Run, with per-user isolated SQLite state snapshotted to Cloud Storage so each visitor gets their own compass that survives cold starts.
Challenges we ran into
Keeping the LLM genuinely out of the decision path is harder than it sounds — it is tempting to let a model "just tweak" a number. We enforced it as a test that fails if swapping the narrator backend changes any sealed value. Making determinism bit-exact meant banishing floats, canonicalizing serialization, and building an independent verifier. Designing for the intended audience meant a calm, one-step-at-a-time experience with a visible, gentle pending state on every model call — never a frozen wall.
Accomplishments that we're proud of
A vocational tool that can prove its claims. 184 tests pass, the audit chain verifies independently, and you can watch it live: POST /api/narrate runs real Gemini 3.5 Flash on Vertex and returns the exact same state seal it was given — the model changed the words, not a single sealed number. Real ADK multi-agent orchestration, and an architecture where the model proposes and narrates but the deterministic core decides and seals.
What we learned
That honesty is a feature. A documented ABSTAIN — "the evidence does not let me conclude" — is worth more than a confident wrong answer. And that anti-flattery, weighting contradiction over confirmation, is exactly what separates a compass from a mirror.
What's next for COMPASS
More validated, freely-usable instruments (RIASEC, O*NET-derived occupation requirements) feeding hypotheses; richer, cheaper discriminating experiments; and embedding the agent team directly into the main app so the whole cycle lives in one place.
Category: Collaborative Partner
Try it (web app): https://compass-web-1028999311218.us-central1.run.app
Try it (multi-agent chat, ADK): https://compass-agent-1028999311218.us-central1.run.app — pick compass_companion
Repository: https://github.com/annatchijova/compass
▎ COMPASS makes real gemini-3.5-flash calls on Vertex AI (ADK). The deterministic core seals every index before the model is called, so Gemini narrates the result but never invents a number — swap the model and the wording changes, the sealed verdict doesn't. Not mocked: POST /api/narrate returns real, request-time Gemini prose with the state seal unchanged.
Built With
- firestone
- gemini
- google-cloud
- python
Log in or sign up for Devpost to join the conversation.