-
-
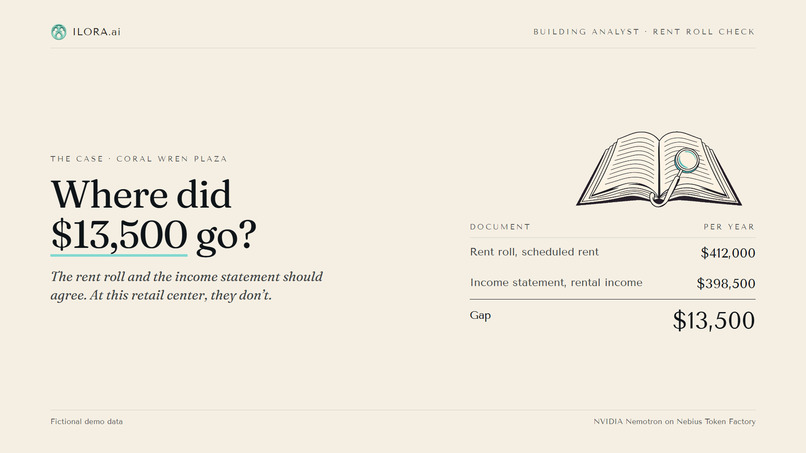
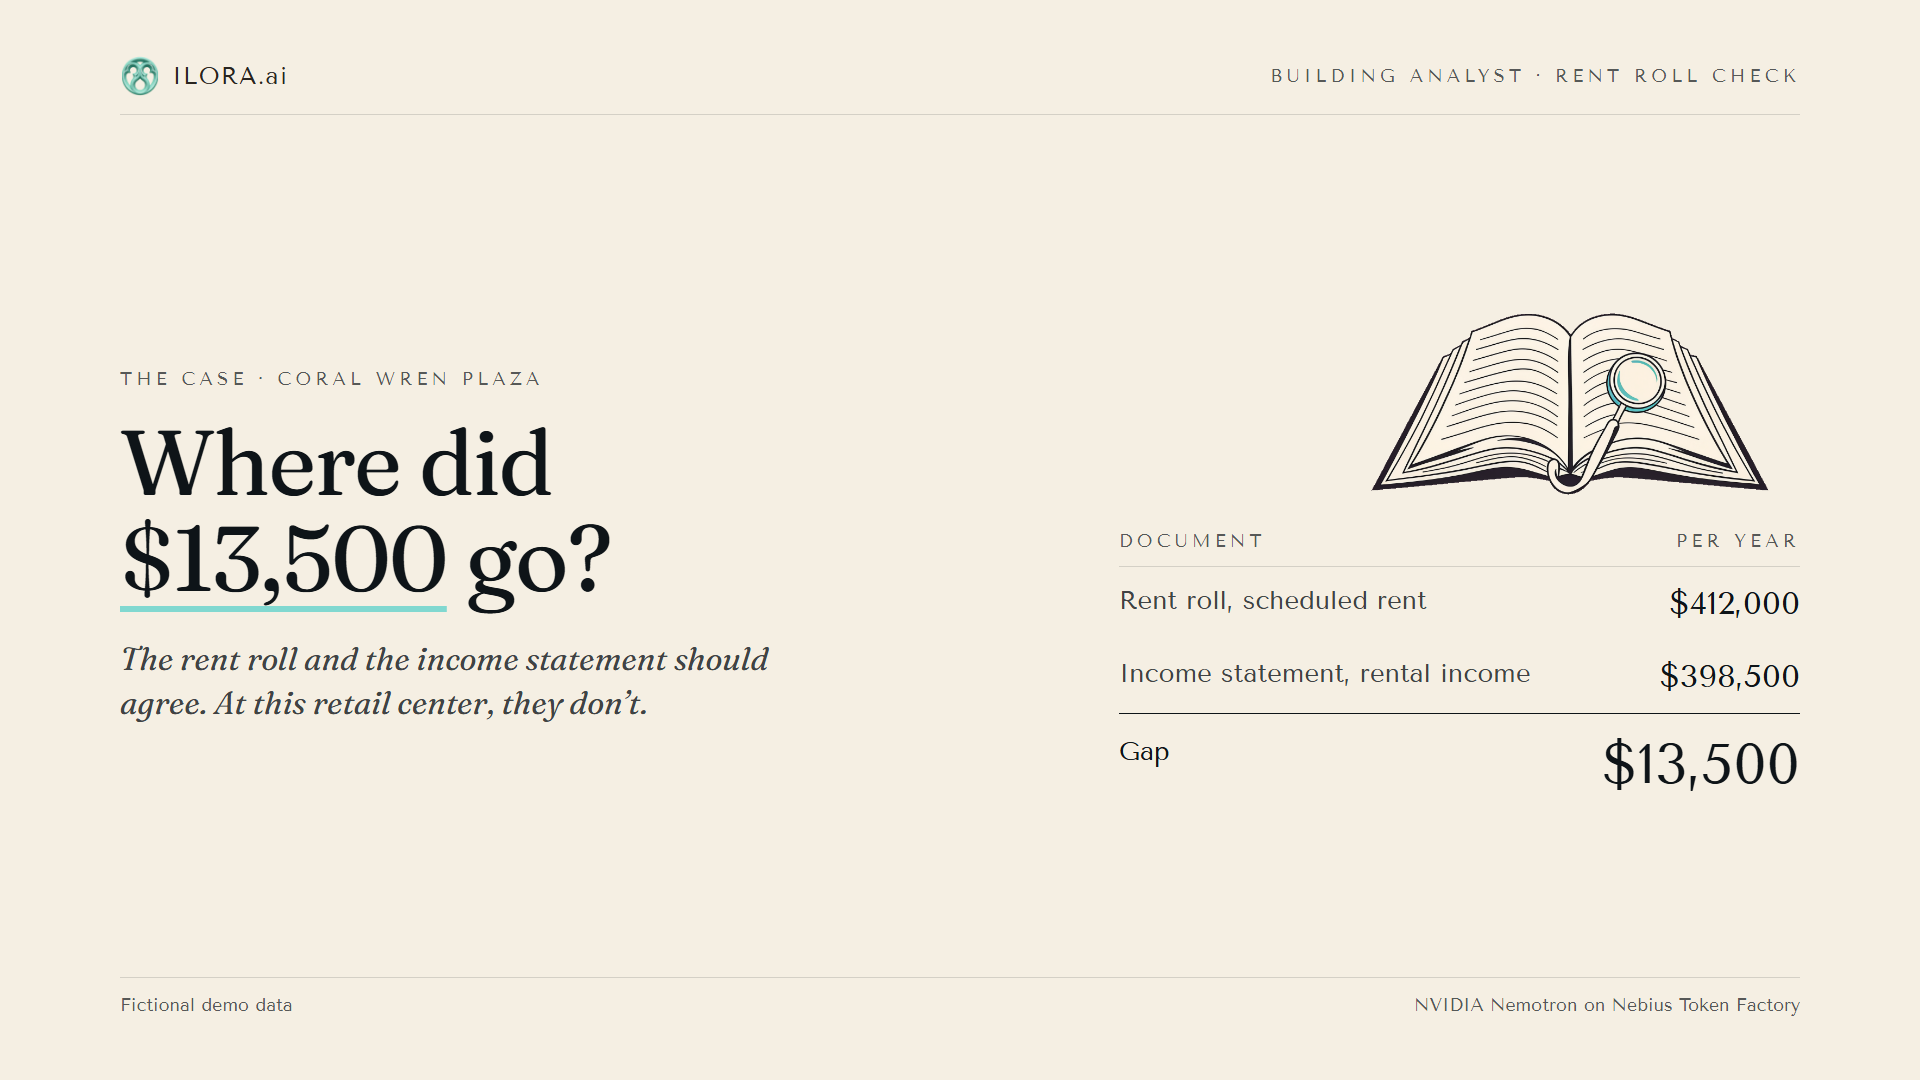
The case: Coral Wren Plaza's rent roll and income statement are $13,500 apart.
-
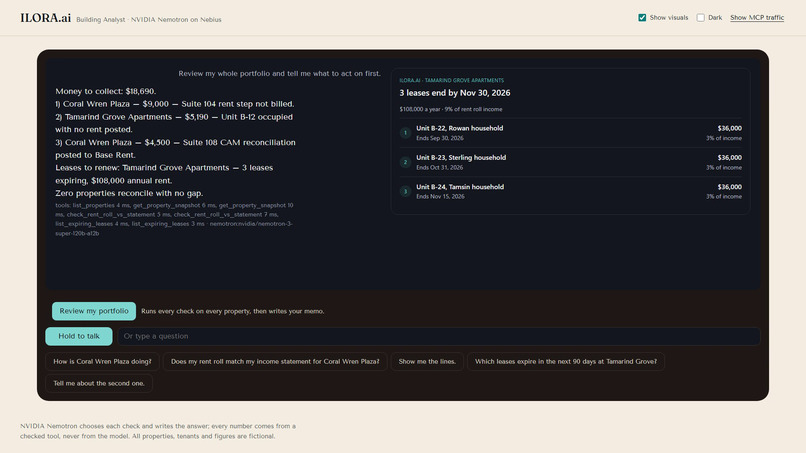
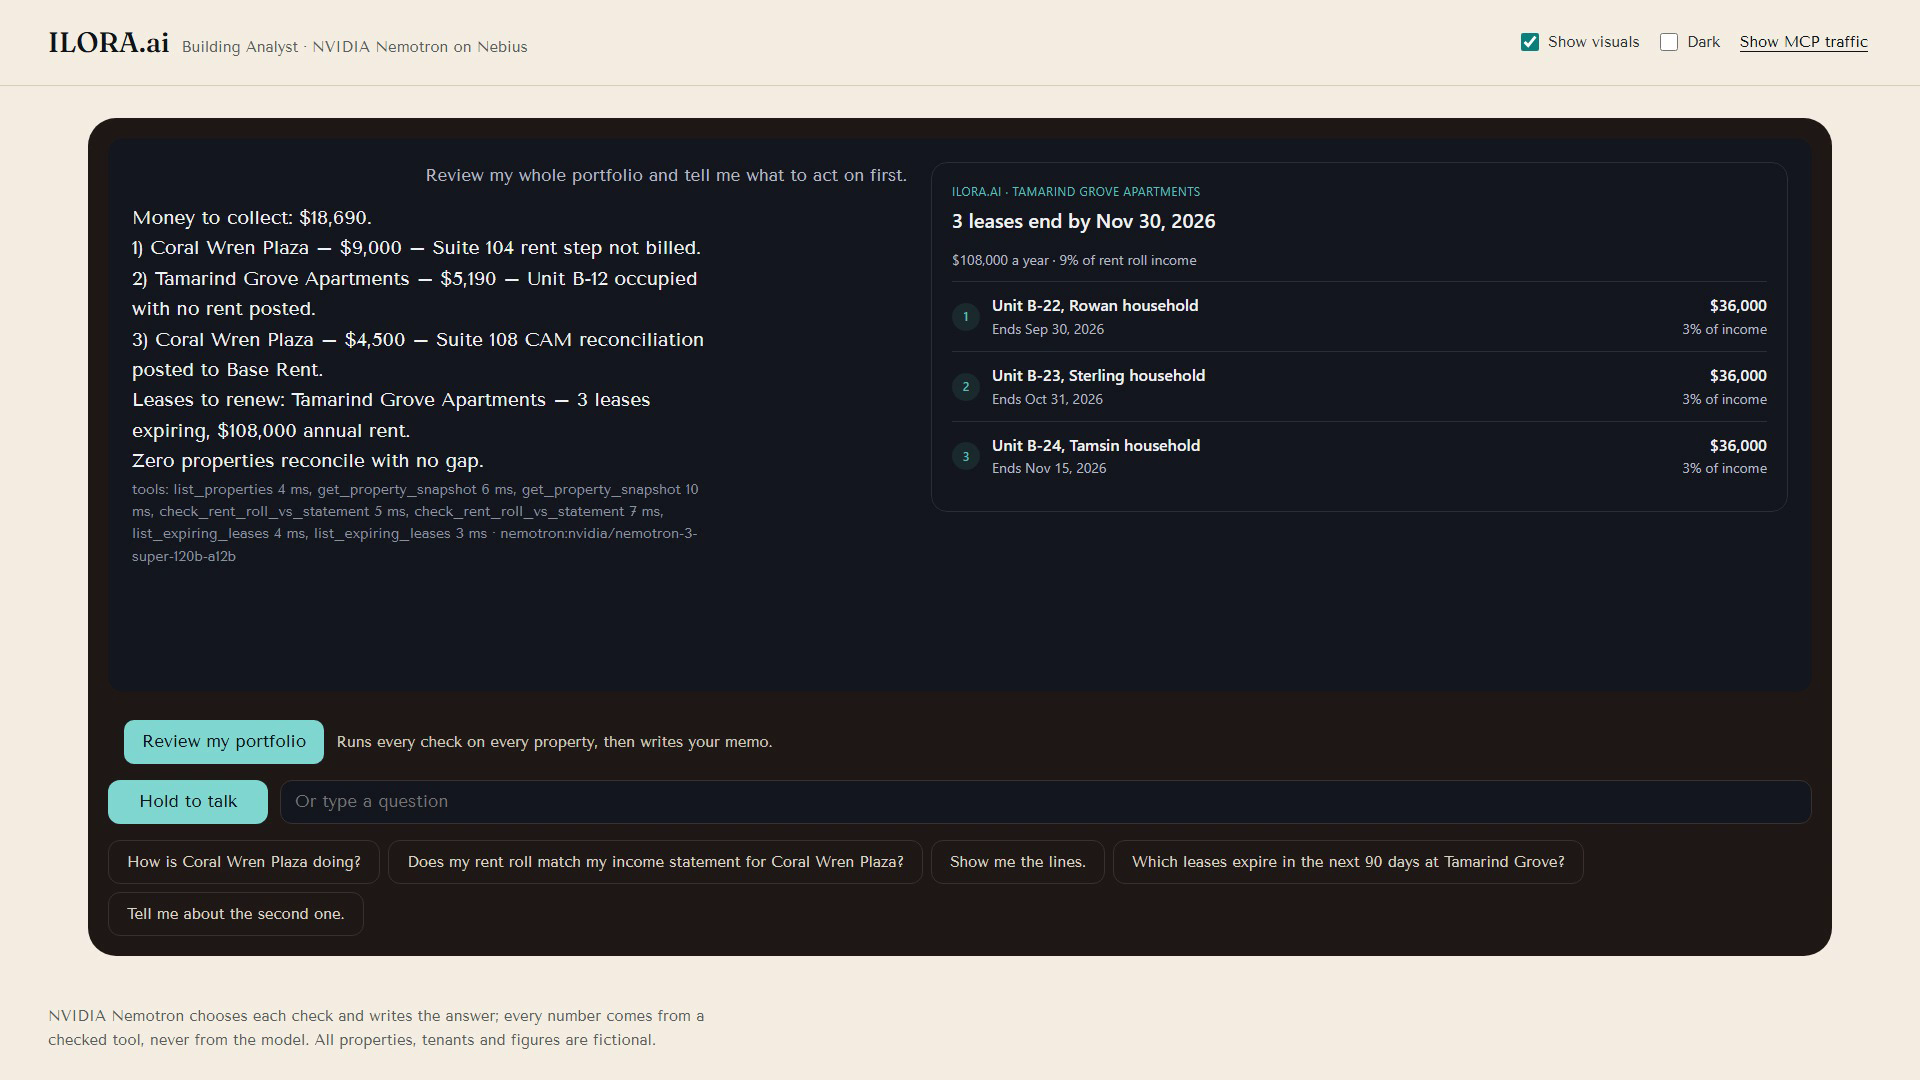
Review my portfolio: Nemotron 3 Super runs seven checks and writes the memo, $18,690 to collect.
-
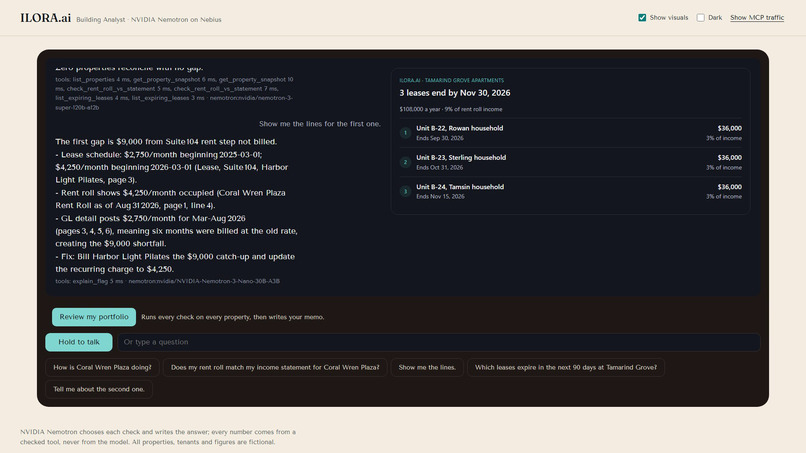
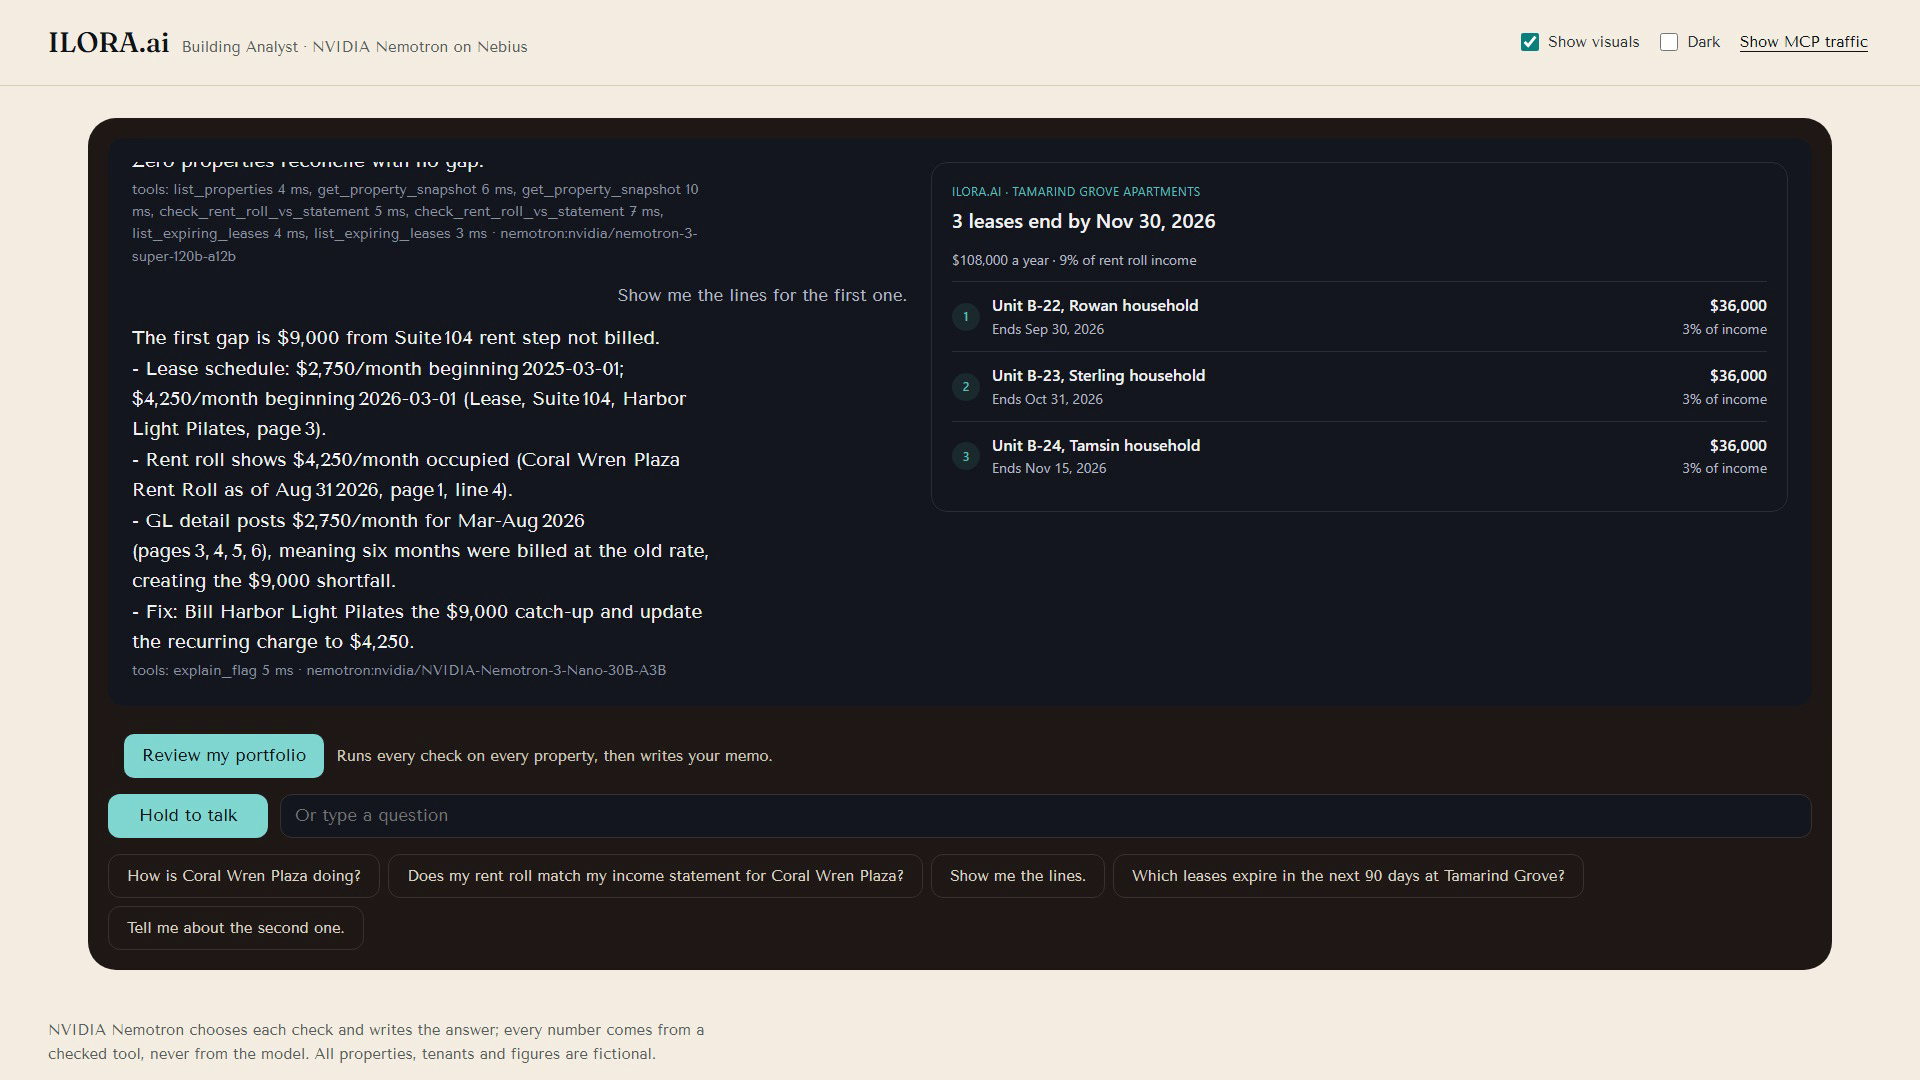
Show me the lines: the lease, rent roll and ledger lines behind the $9,000 gap, with the fix.
-
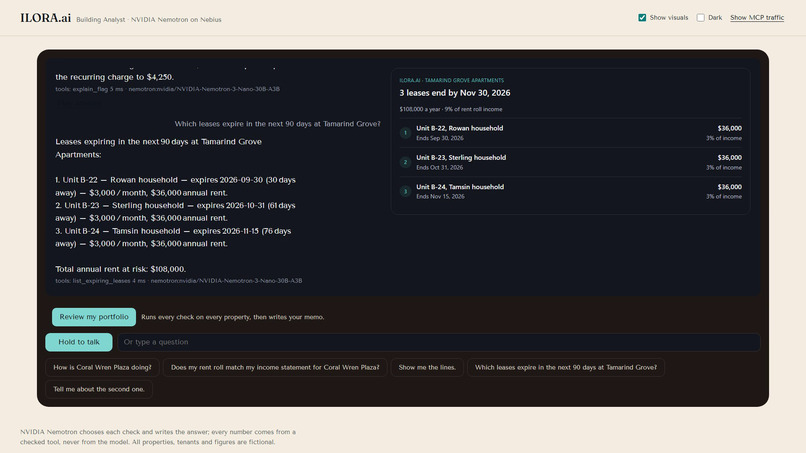
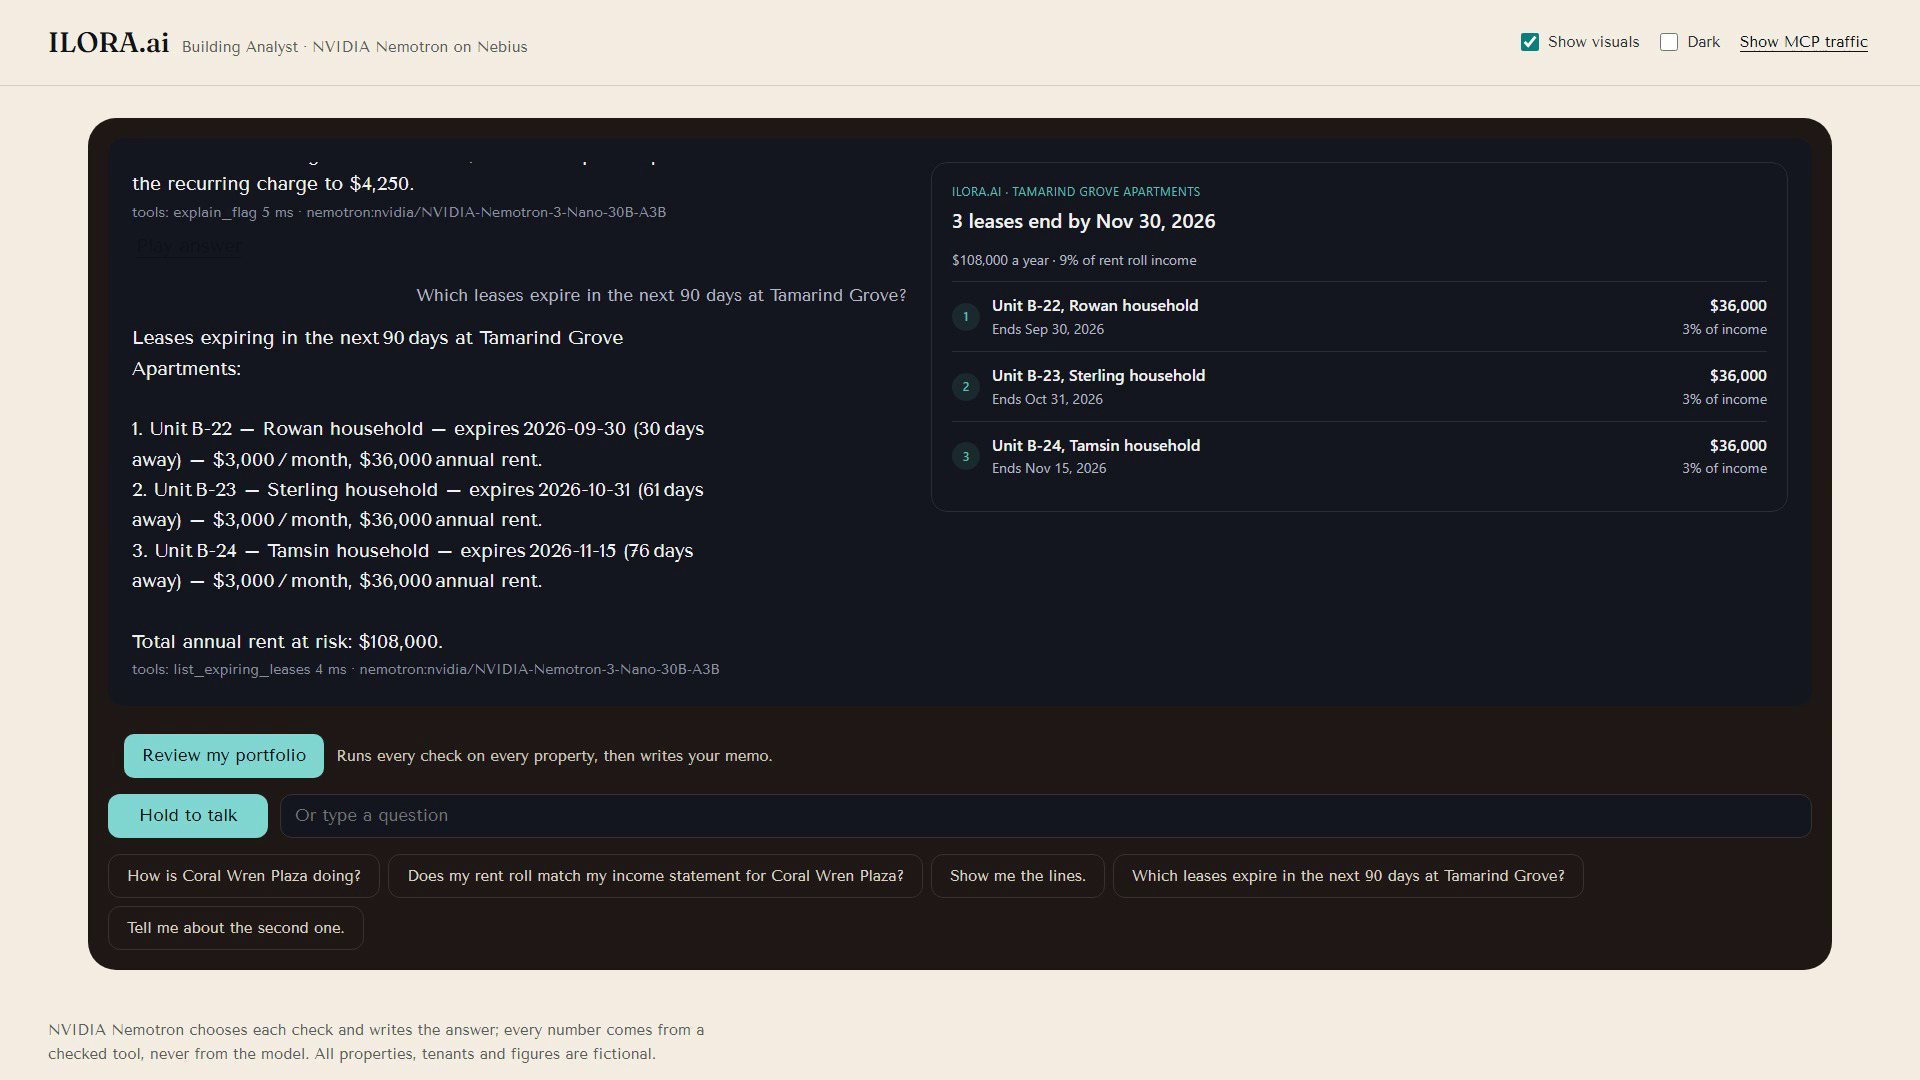
Leases to renew: three leases at Tamarind Grove end within 90 days, $108,000 a year.
-
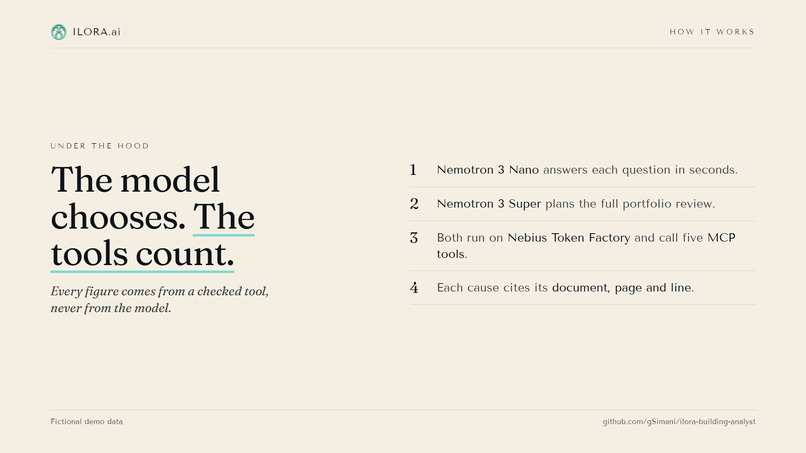
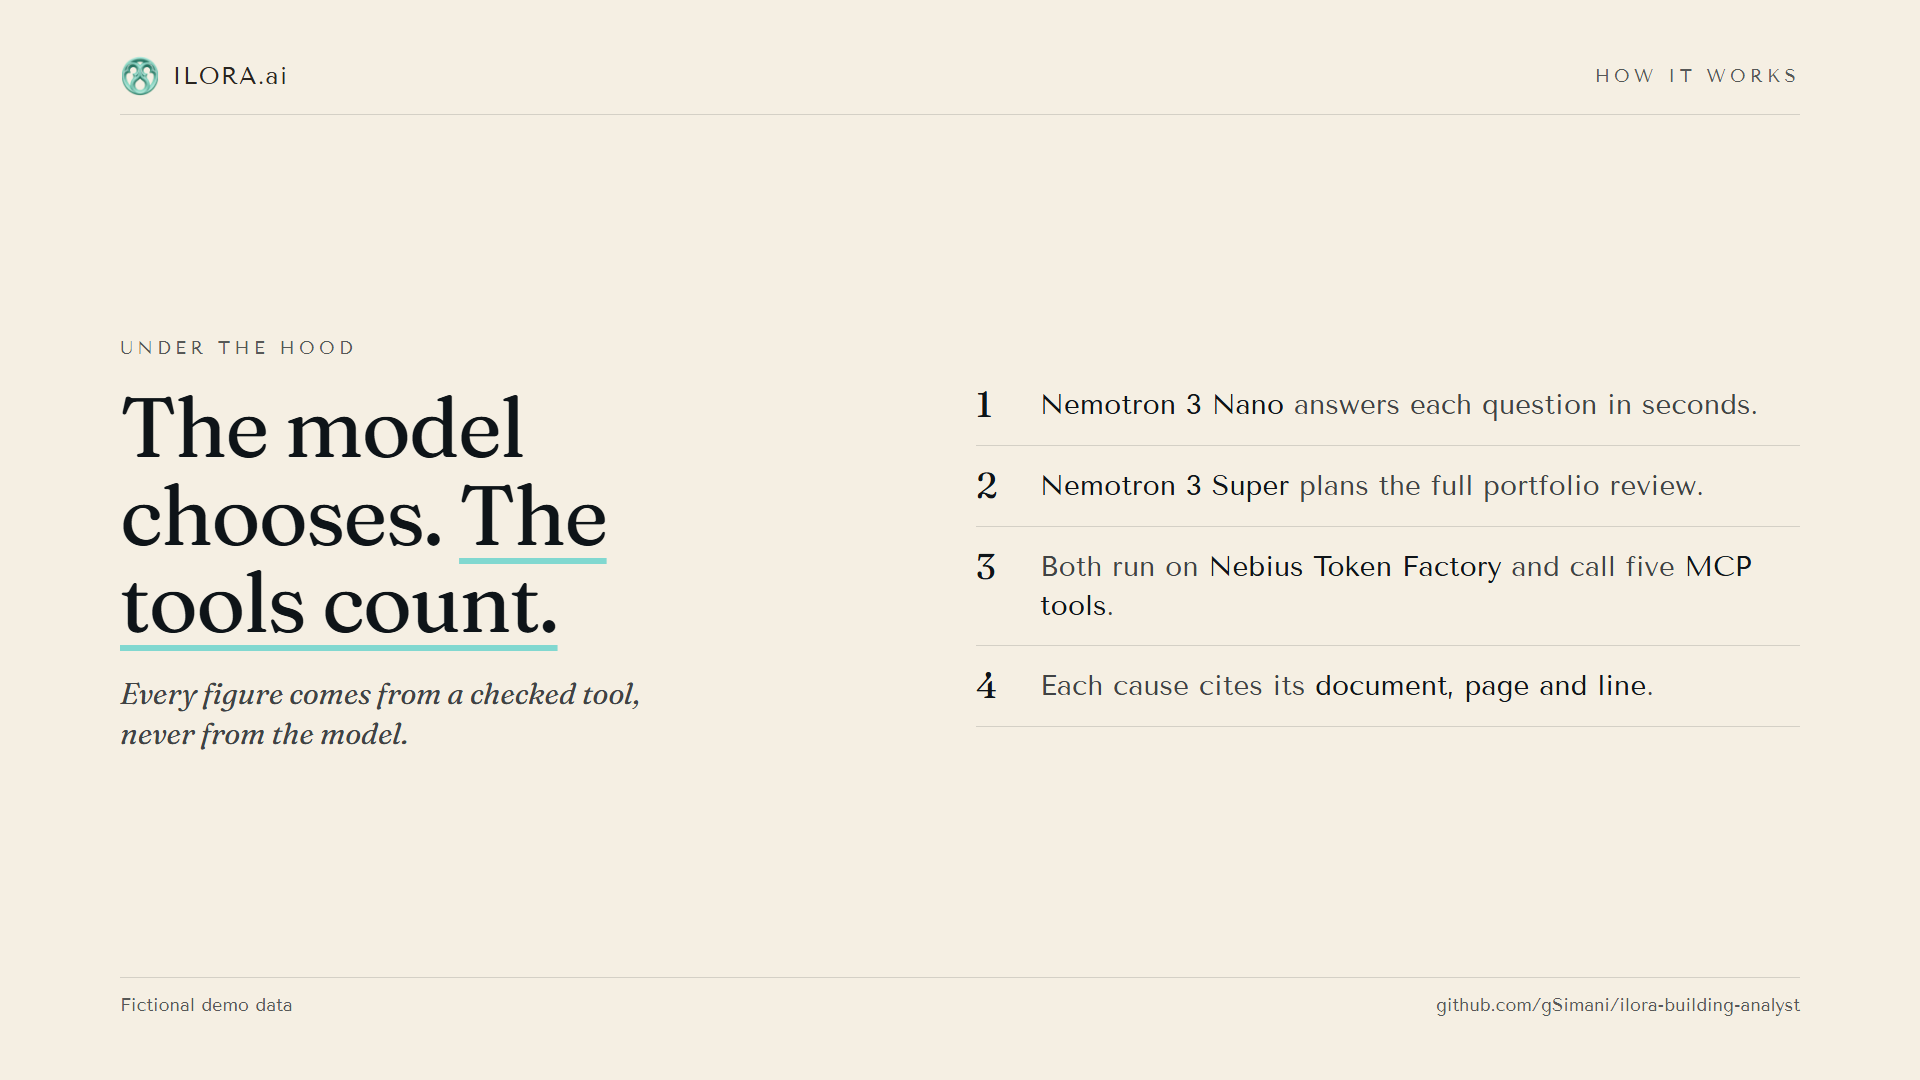
How it works: Nemotron chooses the checks on Nebius Token Factory; every number comes from a tool.
-
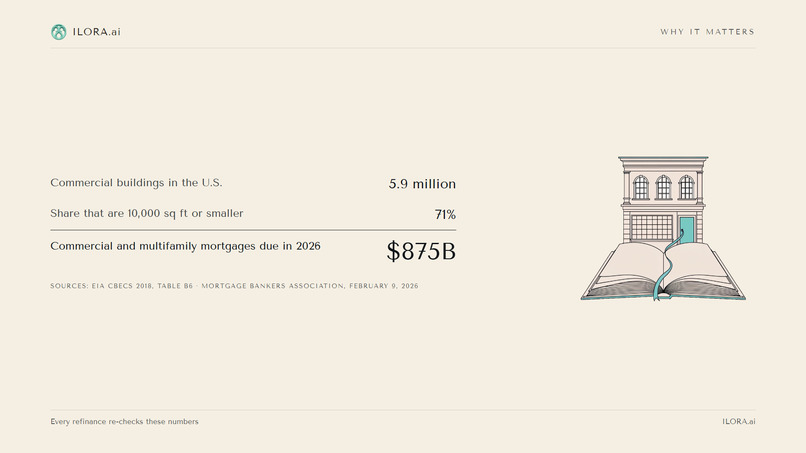
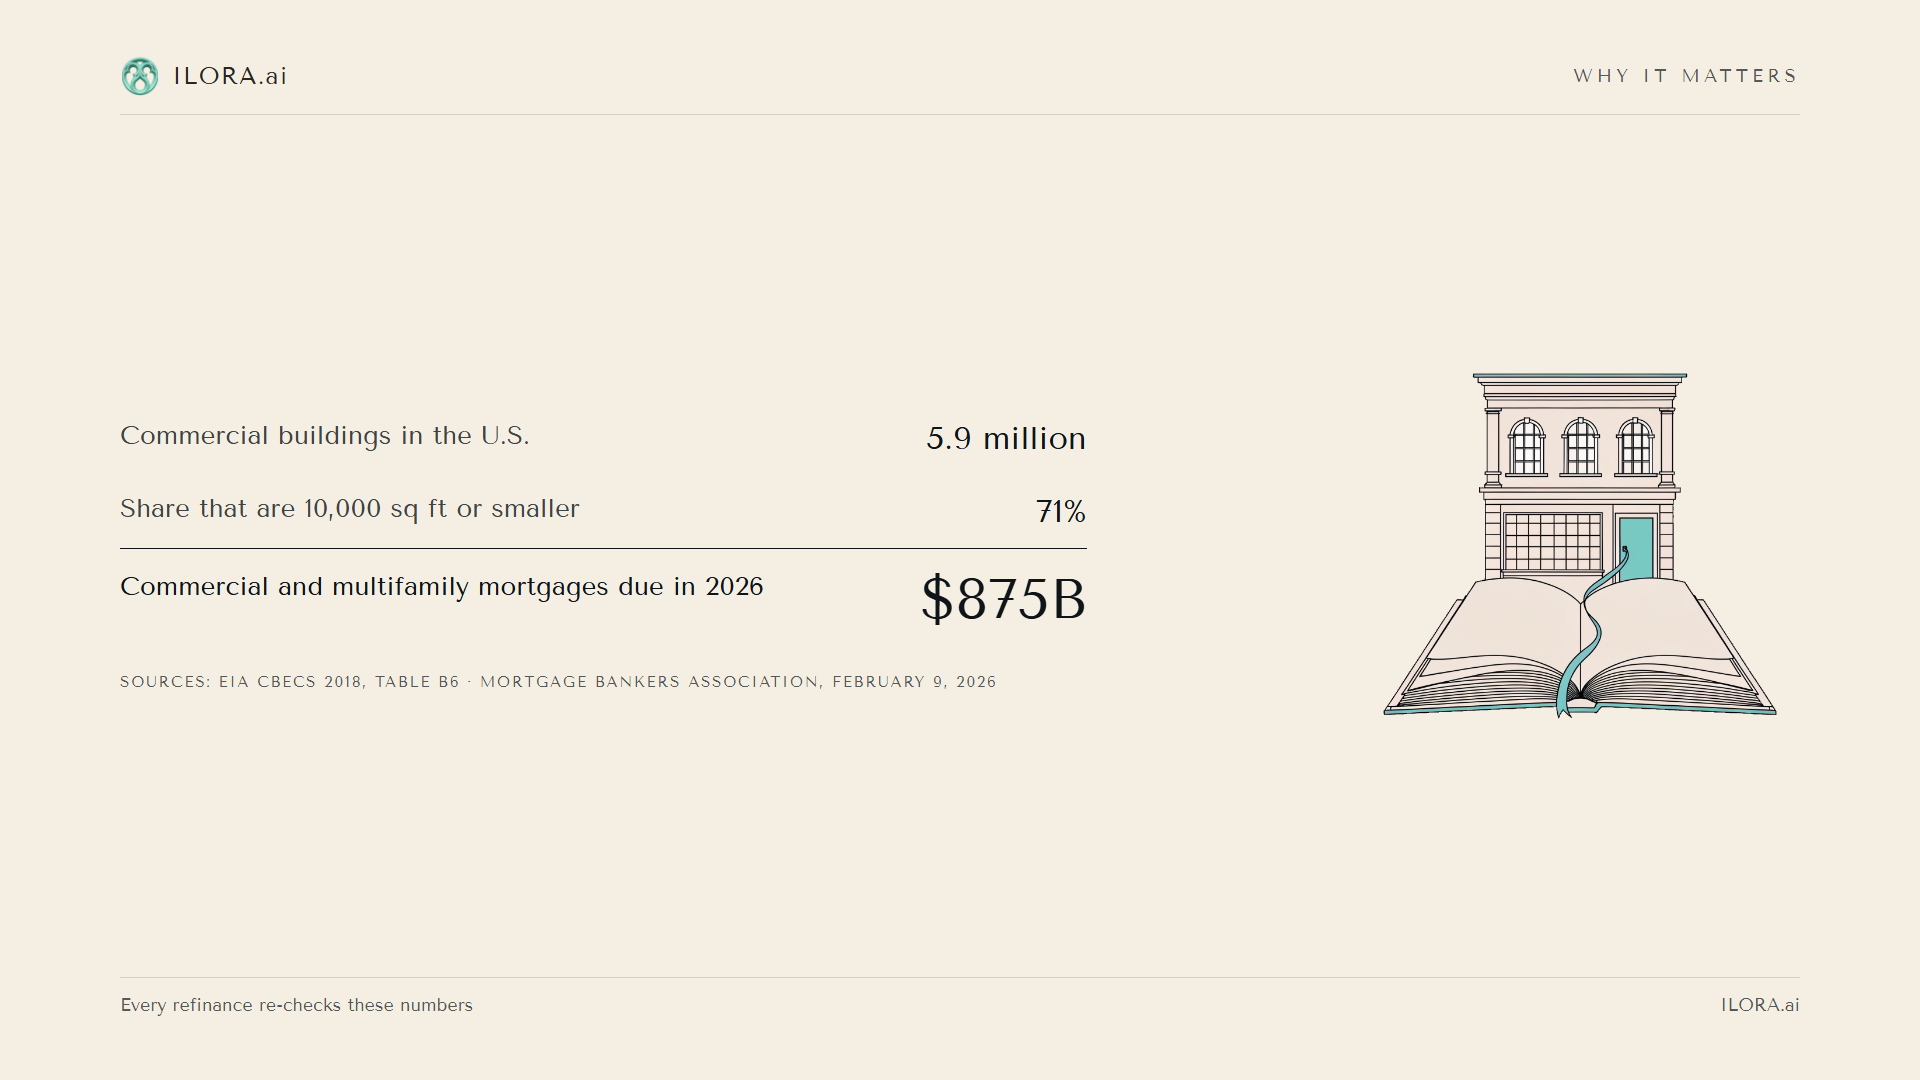
Why it matters: 5.9 million U.S. commercial buildings, $875 billion of mortgages due in 2026.
Inspiration
An independent owner's rent roll says $412,000 a year. The income statement says $398,500. Nobody notices the $13,500 gap until a lender or a buyer does, and by then it is a price cut or a delayed refinance. Large firms pay analysts to tie these documents out every month. The owner of one strip center or one small apartment building checks them alone, if at all.
There are 5.9 million commercial buildings in the U.S., and 71% of them are 10,000 square feet or smaller (EIA, CBECS 2018, Table B6). In 2026, $875 billion of commercial and multifamily mortgages come due (Mortgage Bankers Association, February 9, 2026), and every refinance re-checks these numbers.
What it does
Press Review my portfolio and the analyst checks every property, then writes a memo in two parts:
- Money to collect, largest first, each with the property, the amount and the cause: $9,000 from a March rent step at Suite 104 that was never billed, $5,190 from Unit B-12 showing occupied with no rent posted, and $4,500 from a CAM reconciliation posted to base rent. $18,690 in total.
- Leases to renew: three leases at Tamarind Grove end within 90 days, $108,000 of annual rent.
Then ask follow-ups by typing or by voice: "Show me the lines for the first one" returns the lease clause, the rent roll line and the ledger lines behind the gap, with the fix. "Which leases expire in the next 90 days?" and "Tell me about the second one" work the way an owner would ask. Answers are read aloud in a natural Amazon Polly generative voice.
Both properties, all tenants and every number are fictional. The issues were built into the data on purpose and the tests assert each one to the dollar.
How we built it
- NVIDIA Nemotron on Nebius Token Factory. Nemotron 3 Nano answers each question; its reasoning pass is switched off, so most answers come back in 2 to 7 seconds. Nemotron 3 Super plans the portfolio review with reasoning on: it lists the properties, then runs the snapshot, the rent roll check and the lease check for each one, one tool call at a time, and writes the memo. Calls go to Token Factory's chat-completions endpoint with function calling; no provider SDK is needed.
- The model never produces a number. Five tools on an MCP server (Model Context Protocol, spec 2025-11-25, Streamable HTTP) do the arithmetic and return structured results with output schemas and source citations. Nemotron decides which tool to call and writes the words.
- Guardrails we added after testing on real Nemotron: plain text only, state only what a tool returned, follow-ups like "the second one" refer to the latest list, each review starts on a fresh thread so every check runs, and an empty model reply is reported as an error instead of shown as silence.
- Deployment: one AWS Lambda function URL serves the page, the MCP endpoint and the model route; the model itself runs on Nebius Token Factory. Requests are capped per hour per caller and in total.
- Tests: 47 tests, including the Nemotron message conversion, model selection and a full portfolio review asserted to the dollar.
Challenges we ran into
- Nemotron 3 Nano's first answers came back blank: its reasoning used the whole token budget before any answer text. Turning reasoning off for questions fixed it and cut latency from about 12 seconds to 2 to 7 for most questions. The review keeps reasoning on, where planning eight steps benefits from it.
- The review once answered from tool results already in the conversation instead of running the checks. Starting every review on a fresh thread made it run all seven checks every time.
- "Tell me about the second one" first picked from an older list. One instruction about which list a follow-up refers to fixed it.
- The voice played as the browser's robotic fallback online: the audio was being corrupted on its way out of Lambda. Sending it as binary fixed it.
Accomplishments that we're proud of
- A full portfolio review on Nemotron 3 Super in about 12 to 18 seconds, with every figure matching the tests.
- A clear split between what the model decides and what the tools compute, so a wrong number cannot come from the model.
What we learned
- Reasoning models need room: the token budget and the reasoning switch matter as much as the prompt.
- A small, explicit rule about conversation state does more for follow-up questions than a longer system prompt.
What's next for ILORA.ai Building Analyst
Connect the tools to ILORA.ai's document pipeline so the review runs on an owner's real rent rolls, statements and leases, add Tavily search for local market rent context, and move the page to Nebius Serverless Endpoints.
Built With
- amazon-polly
- aws-lambda
- aws-sam
- express.js
- model-context-protocol
- nebius-token-factory
- node.js
- nvidia-nemotron
- typescript
- vite
- vitest
- web-speech-api
- zod

Log in or sign up for Devpost to join the conversation.