-
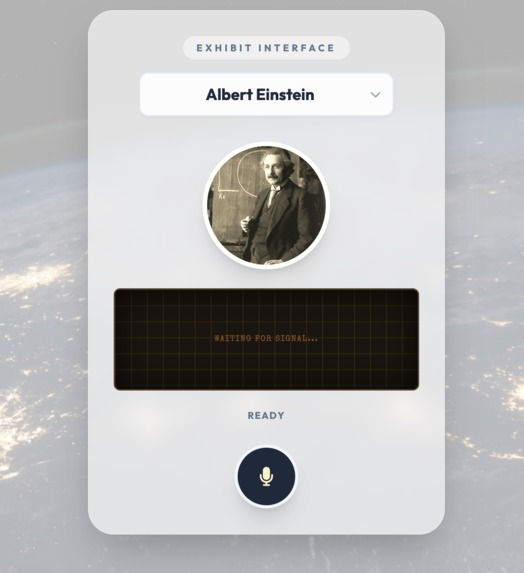
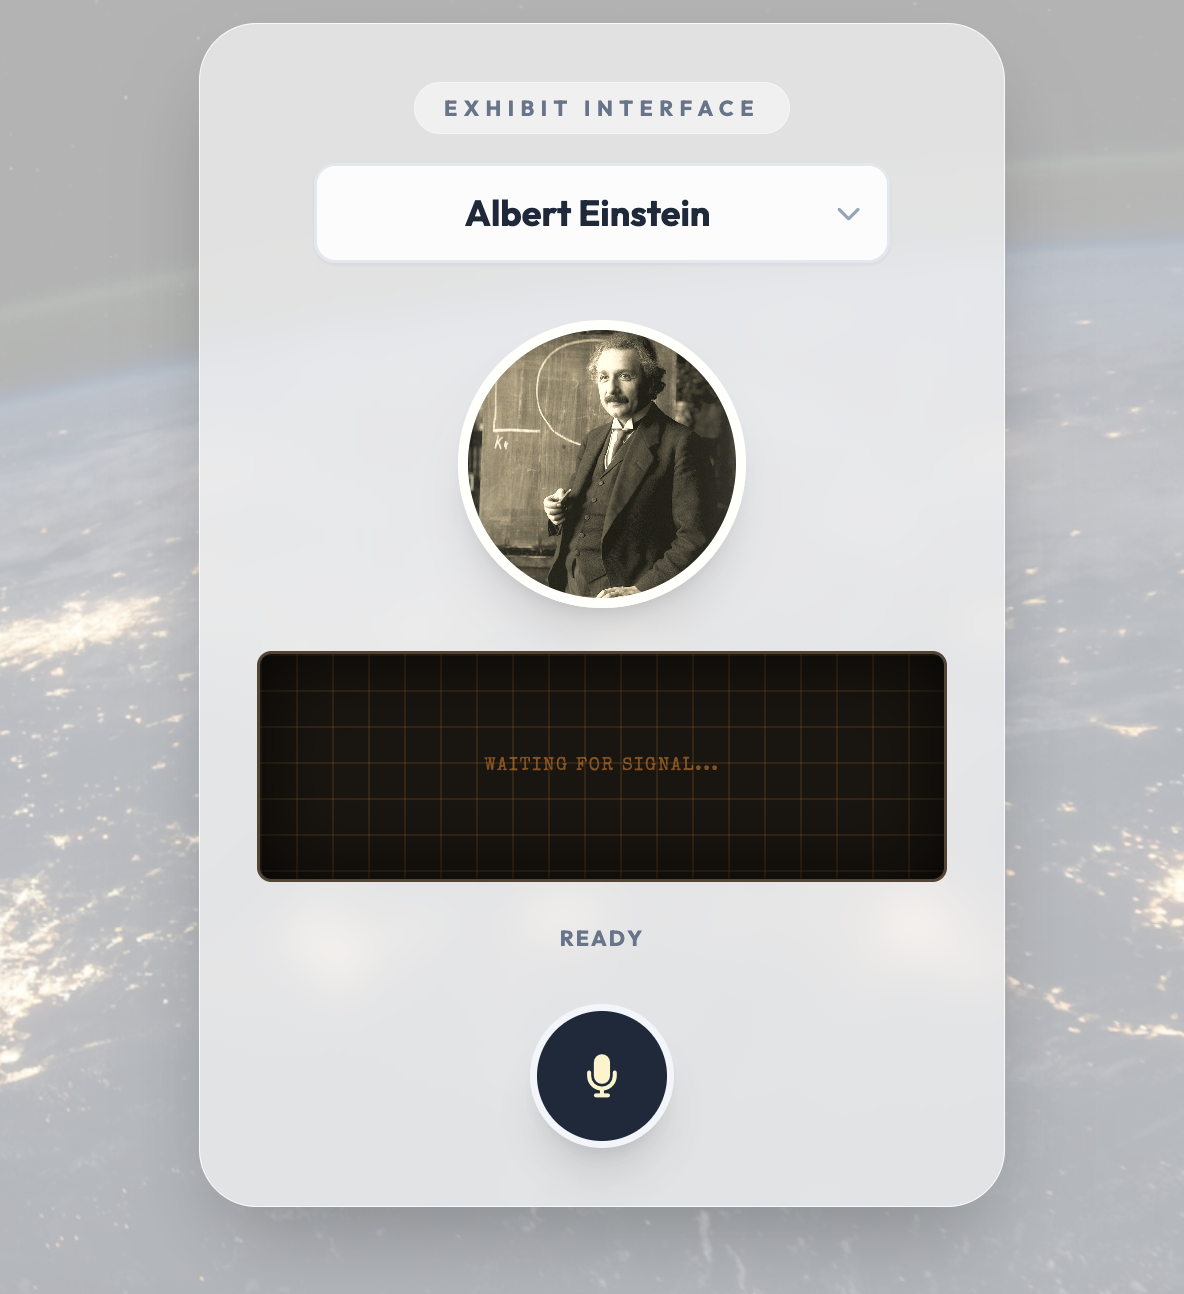
User Interface
-
Inspiration
We believe history shouldn't be trapped behind a glass case or a silent placard. History has the power to captivate, educate, and connect us across time. Our team was inspired by a simple question: What if you could just ask? We wanted to make history irresistible for kids and adults alike by turning a museum visit into a chat with a legend. Imagine visiting a historical site and hearing the stories directly from the people who lived them, in their own voice
Beyond that, we wanted to solve the language barrier in global tourism. Whether you are in a museum in Tokyo or Paris, HistoVox ensures that a historical figure can speak to you in your native tongue, making cultural education truly universal and accessible.
By bringing historical voices to life, we create a new medium for cultural preservation that resonates with modern audiences.
What We Learned
This project pushed us far beyond our comfort zones, teaching us invaluable lessons about both technology and history.
The complexity of voice synthesis: We discovered that creating believable historical voices requires more than just text-to-speech—it demands careful attention to accent, cadence, emotion, and historical context.
Data scarcity challenges: Finding authentic audio data for historical figures is incredibly difficult. Most recordings from the early 20th century are of poor quality, and anything before that simply doesn't exist.
How We Built It
Frontend: A responsive web interface built with HTML/CSS and JavaScript to handle audio recording and UI feedback.
Backend: Python with Flask framework for handling server-side logic and API routing
AI Integration: Gemini API served as our core engine for language detection and contextual understanding. OpenRouter API for accessing state-of-the-art language models.
Voice Synthesis: ElevenLabs was utilized to generate high-fidelity, era-appropriate voices that match the character’s identity.
Challenges We Faced
Audio Preprocessing & Compression: Handling raw audio from a microphone and compressing it for fast API transmission without losing the quality needed for speech-to-text.
Finding Historical Audio Data: It was challenging to find high-quality reference audio for figures who lived before the age of recording to train our voice models.
Character consistency: Mapping the real-time language detection to the correct output voice required complex logic to ensure the figure didn't "switch" personalities when switching languages.
Built With
- css3
- elevenlabs
- flask
- freewili
- html
- javascript
- jupyter
- openrouter
- python


