-
-
Search Engine
ALGOsearch (Education)
Inspiration
Googling coding questions from google and searching for the desired approach is quite annoying. Why not develop our own search engine which target a particular dataset?
What it does
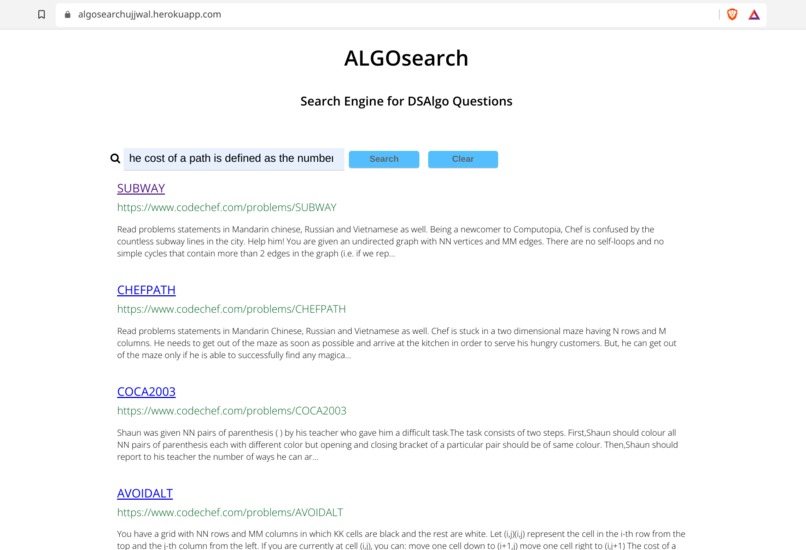
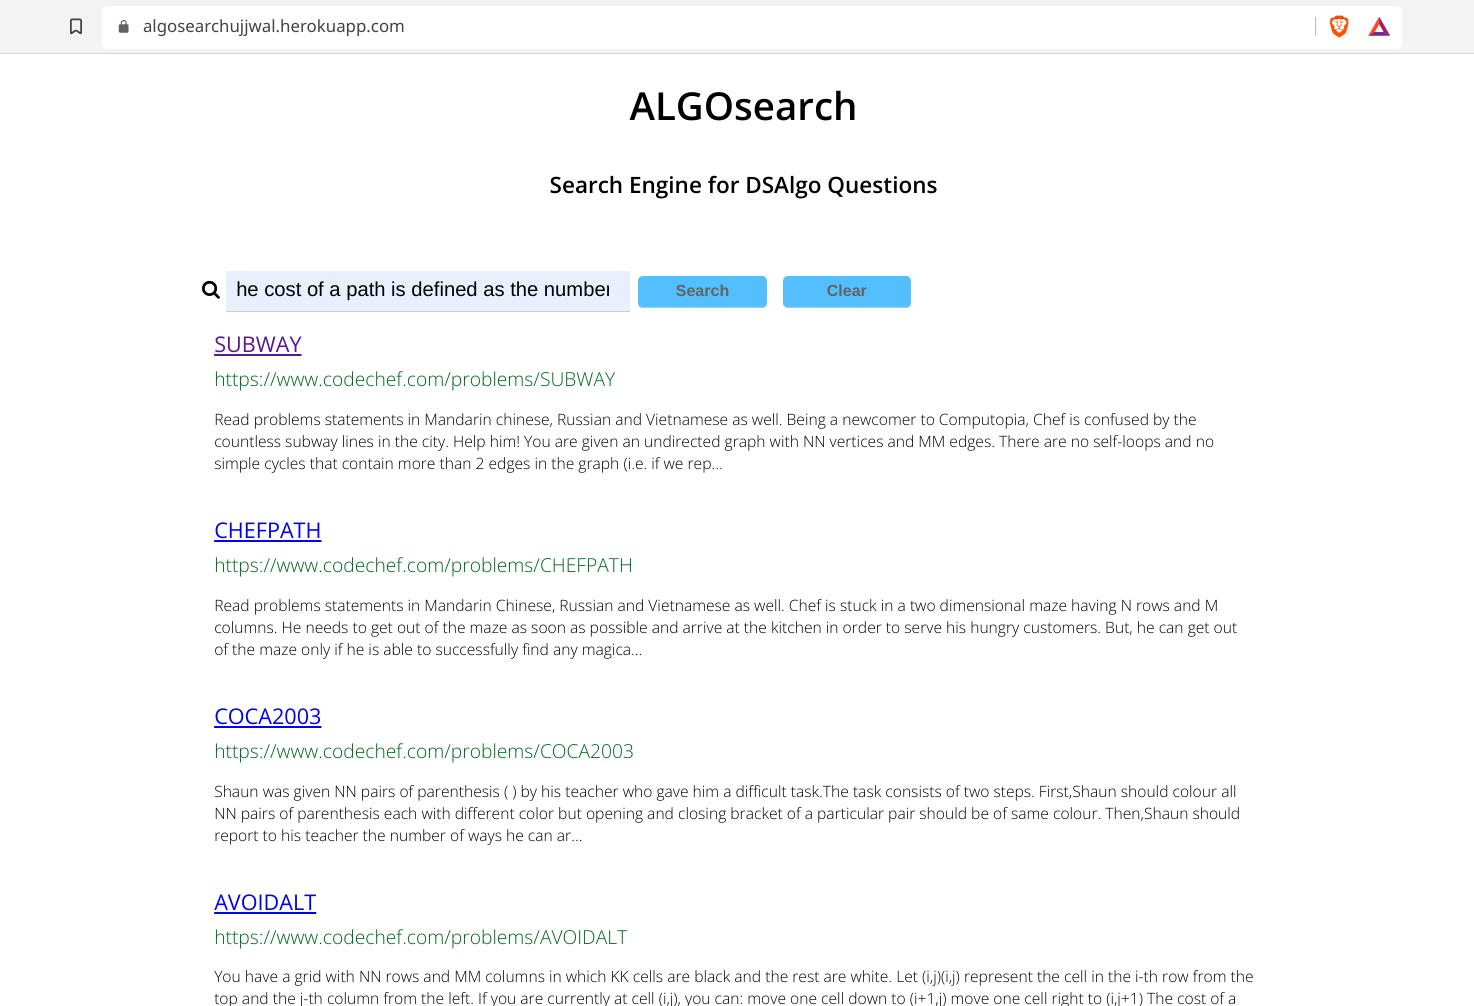
ALGOsearch is a Search Engine designed specifically for Data Structure and Algorithm questions in platforms like codechef and codeforces.
How we built it
– Scrapped more than 3300 DSA Problems in python from coding platforms using BS4 and Selenium Web Driver – Implimented the TF-IDF algorithm from scratch in nodejs to generate the corpus and rank the search results among the scrapped problems – Used reactjs as frontend framework and successfully deployed the application using heroku CLI: archujjwal.herokuapp.com
Challenges we ran into
– The first challenge I ran into was to scrap the data properly. I handled in an awesome way using error throwing techniques in Python programming language. – Implementing TF-IDF machine learning algorithm in nodejs was another challenge which took alot of time to tackle.
Accomplishments that we're proud of
– The search result is very accurate in the target corpus.
What we learned
– How search Engine Works? – TF-IDF Machine Learning Algorithm – Web Scraping in python
What's next for Algosearch
– I aim for increasing the accuracy of the search engine and expanding the dataset.
Web Application
It uses tf-idf Algorithm to implement search. The server is live on https://algosearchujjwal.herokuapp.com/.
Installation [development]
Dependencies
Local Building
Clone or unzip the repository.
git clone https://github.com/ujjwall-R/Funathon-Submission.git
cd Funathon-Submission
Install the dependency modules for both server and client side of the application. The client side is a ReactJS app built using create-react-app.
npm install
cd client
npm install
cd ..
Rebuilding the DataSet [optional]
The DataSet is already built in ./DataSet. Anyways you can rebuild the DataSet if you wish. Give the problem tags to build the dataset.
Mac/Linux:
cd DataSet
rm -rf IDF.txt TFIDF.txt keywords.txt magnitude.txt problem_titles.txt problem_urls.txt Problems
mkdir Problems
python -u scrapper.py
Windows:
cd DataSet
rmdir Problems
del IDF.txt TFIDF.txt keywords.txt magnitude.txt problem_titles.txt problem_urls.txt
mkdir Problems
python -u scrapper.py
After building the DataSet for problem tags of your choice, buid the TF IDF data. Note that you have opted to build your own corpus. This may take some time.
node calc.js
cd ..
Usage
Now you are ready to go and start the web application. In the root directory, start the server.
nodemon index.js
Start the react app in another terminal.
cd client
npm start
Visit your localHost address where the client side app is running and enjoy searching.


