-
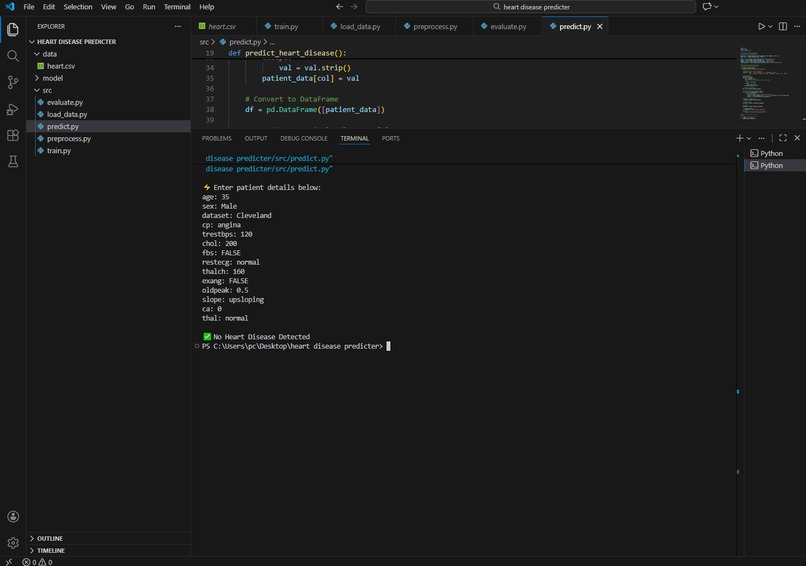
A terminal run
Inspiration
What it does
How we built it
Challenges we ran into
Accomplishments that we're proud of
Heart Disease Predictor - Project Overview This is a machine learning pipeline project designed to predict the presence of heart disease in patients based on medical attributes.
📖 The Project Story The Problem Heart disease is one of the leading causes of death worldwide. Early detection is critical for patient survival and recovery. Your project builds an intelligent system that analyzes patient medical data and predicts whether a patient has heart disease, enabling doctors to make informed decisions quickly.
The Solution This project creates an end-to-end machine learning workflow with 5 key modules:
- 📊 Data Loading (load_data.py) Reads patient data from heart.csv (922 patients with 16 medical attributes) The dataset contains patient information like age, sex, blood pressure, cholesterol levels, and chest pain types Displays basic statistics about the dataset
- 🔧 Data Preprocessing (preprocess.py) This is the most critical step that transforms raw data into ML-ready format:
Removes unnecessary columns (like ID) Converts text to numbers (e.g., "Male"→0, "Female"→1) using label encoders Handles missing values by imputing with median values Normalizes features using StandardScaler (puts all values on same scale) Splits data into 80% training and 20% testing sets Saves all preprocessing tools for later use
- 🤖 Model Training (train.py) Trains three different machine learning models: Logistic Regression - Simple, interpretable baseline Random Forest - Powerful ensemble model with 200 trees SVM - Support Vector Machine for complex patterns Each model learns patterns from training data to identify heart disease indicators
- 📈 Model Evaluation (evaluate.py) Tests all three trained models on unseen test data Compares performance using: Accuracy - Overall correctness Confusion Matrix - Shows true/false positives and negatives Classification Report - Precision, recall, F1-scores Selects the best performing model and saves it as heart_model.pkl
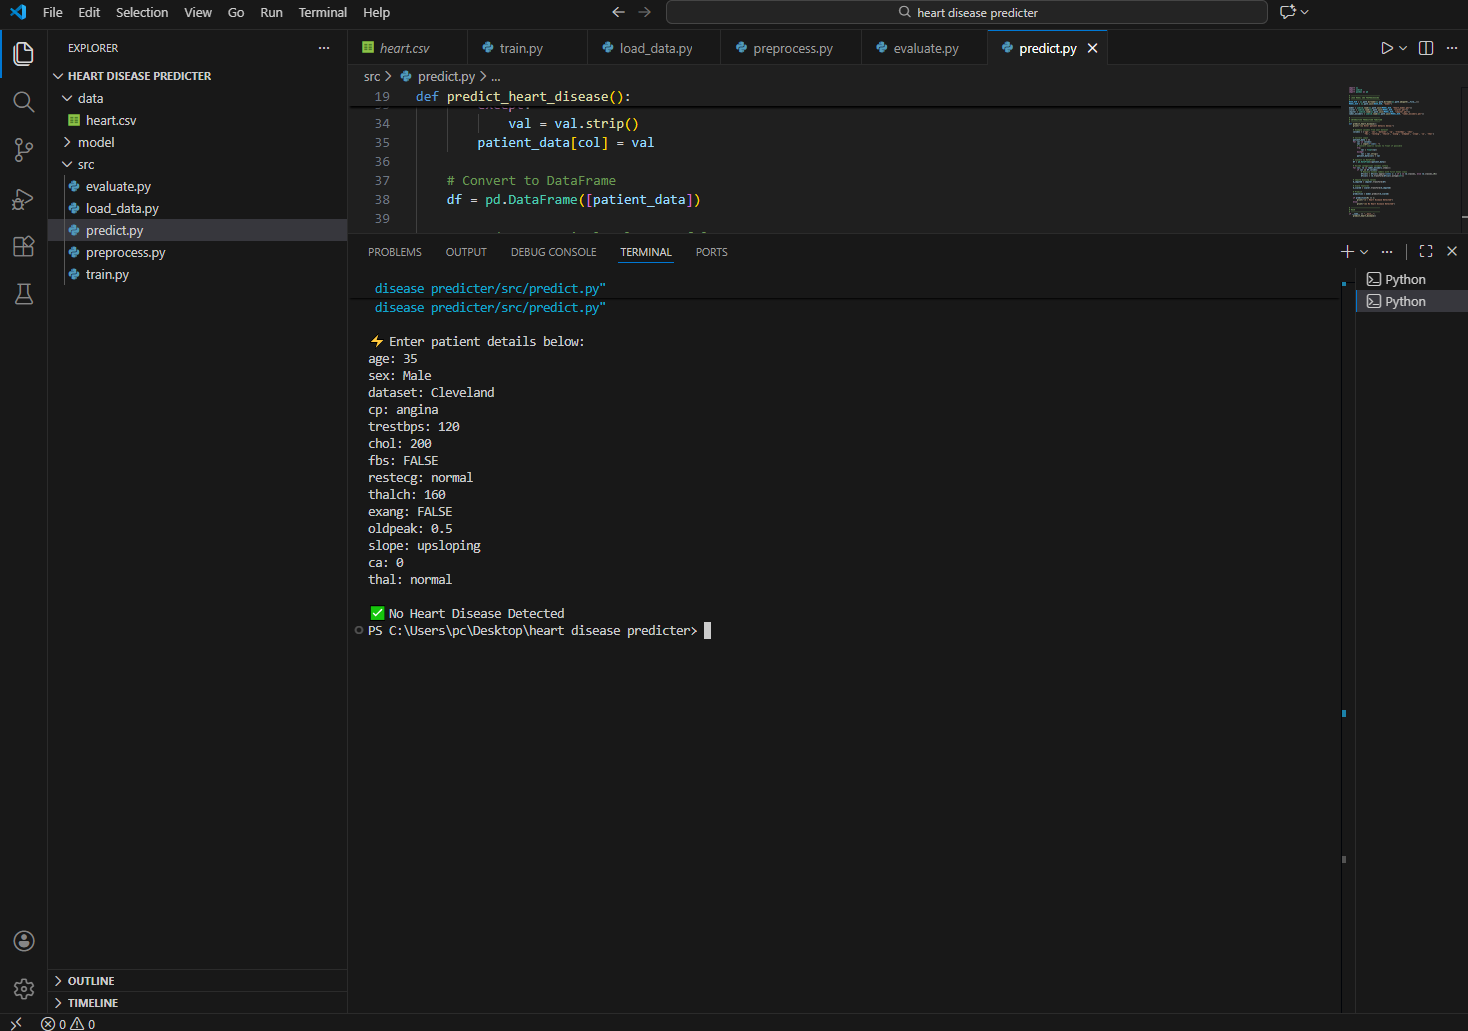
- 🎯 Prediction (predict.py) The final delivery mechanism for real-world use Loads the best trained model Takes patient data as input (14 medical features) Automatically processes the data (encoding, imputing, scaling) Outputs: ✅ "No Heart Disease" or ⚠️ "Heart Disease Detected" 📁 Project Workflow 🎯 Key Features ✨ Automated target detection - Finds heart disease column automatically ✨ Robust preprocessing - Handles missing values and categorical data ✨ Model comparison - Tests multiple algorithms to find the best one ✨ Production ready - Saves all preprocessing tools for consistent predictions ✨ User-friendly - Interactive prompt for entering patient data
📊 Data Attributes The model uses 14 patient features:
age - Patient age sex - Gender cp - Chest pain type (typical angina, atypical, etc.) trestbps - Resting blood pressure chol - Cholesterol level fbs - Fasting blood sugar restecg - Resting ECG results thalch - Max heart rate achieved exang - Exercise induced angina oldpeak - ST depression slope - ST slope ca - Number of vessels thal - Thalassemia type target - Heart disease presence (0=absent, 1=present) This is a complete, professional ML pipeline ready to identify patients at risk of heart disease! 🏥💪
What we learned
What's next for CardioX
Built With
- joblib
- pandas
- python
- scikit-learn
