-
-
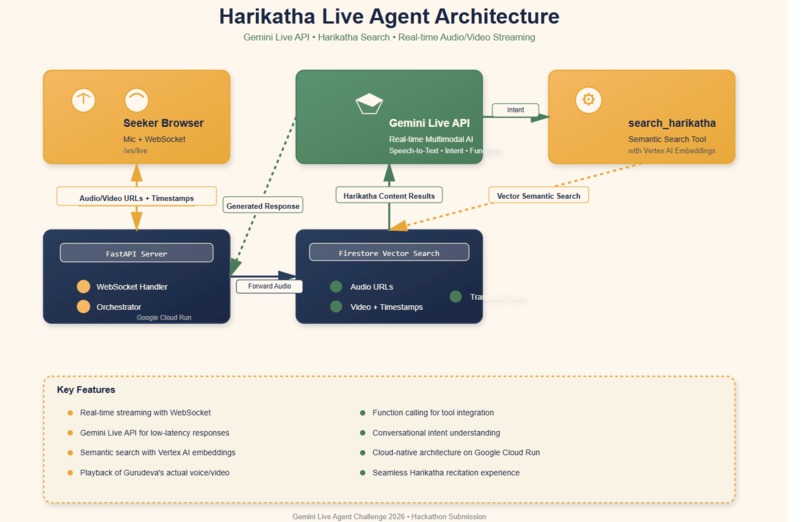
Architecture Diagram
-
-
-
-
-
-
-
-
-
-
-
-
Inspiration
The rise of AI deepfakes poses a unique danger in spiritual contexts — a devotee could receive words fabricated in their guru's voice and never know. Over 2,500 hours of Srila Bhaktivedanta Narayana Goswami Maharaja's recorded harikatha exist across thousands of files, largely inaccessible to seekers worldwide.
One of my deepest concerns with the advent of AI — deepfakes, synthetic voices, fabricated content — is the danger this poses in a spiritual context. To address this, the Harikatha Live Agent is built around a single principle: the source of truth is the archive. Every answer must trace back to an actual recorded moment — a real lecture, a real voice, a real timestamp. The AI never speaks for Gurudeva. It only finds where Gurudeva already spoke.
What It Does
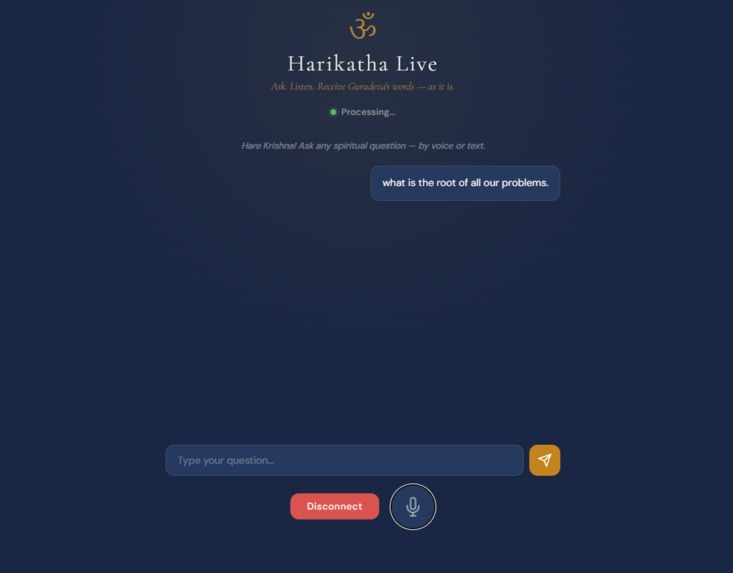
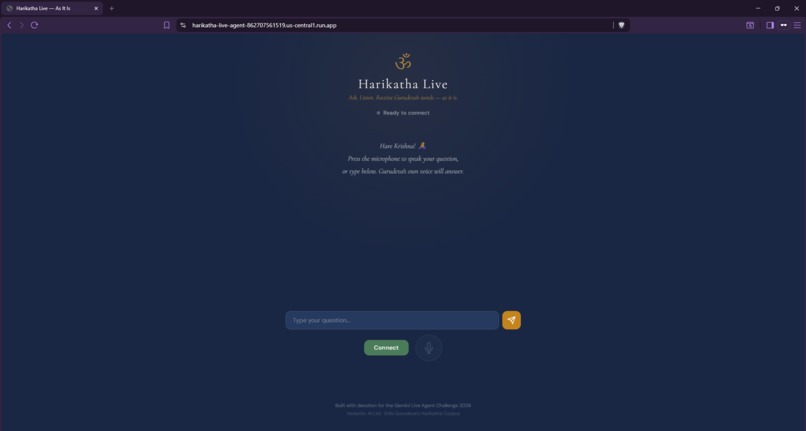
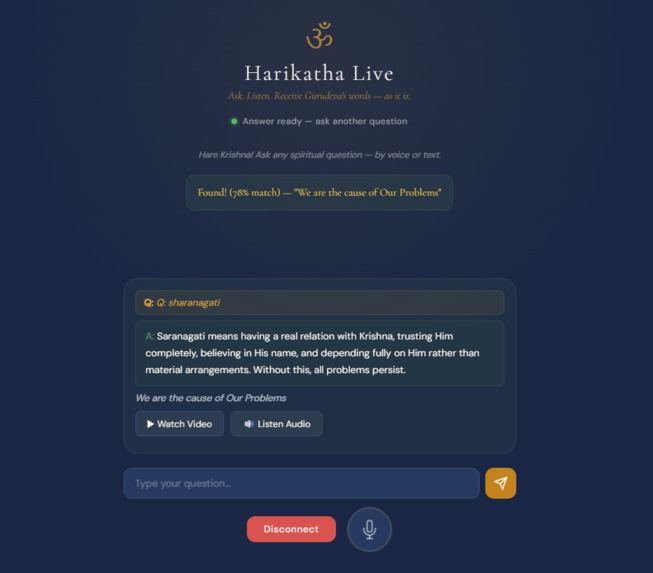
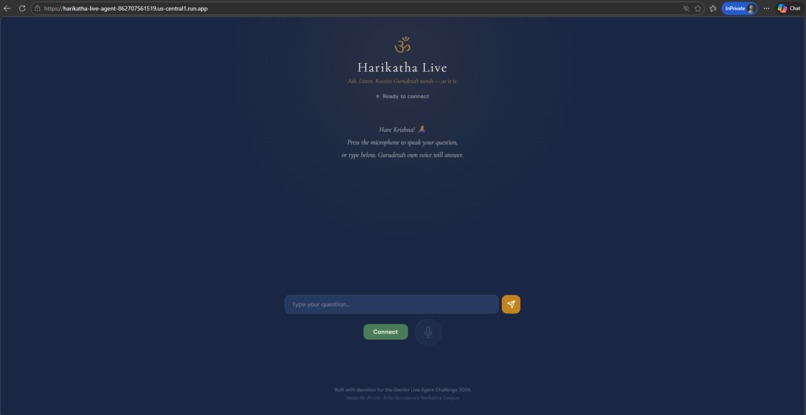
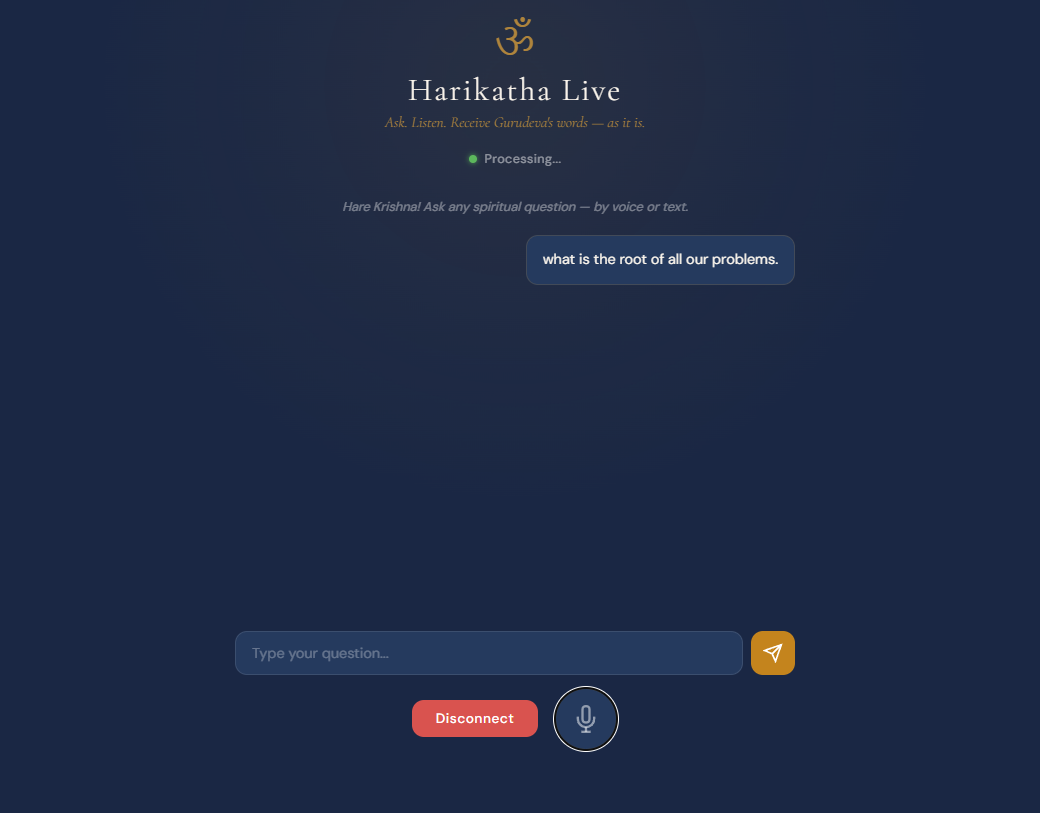
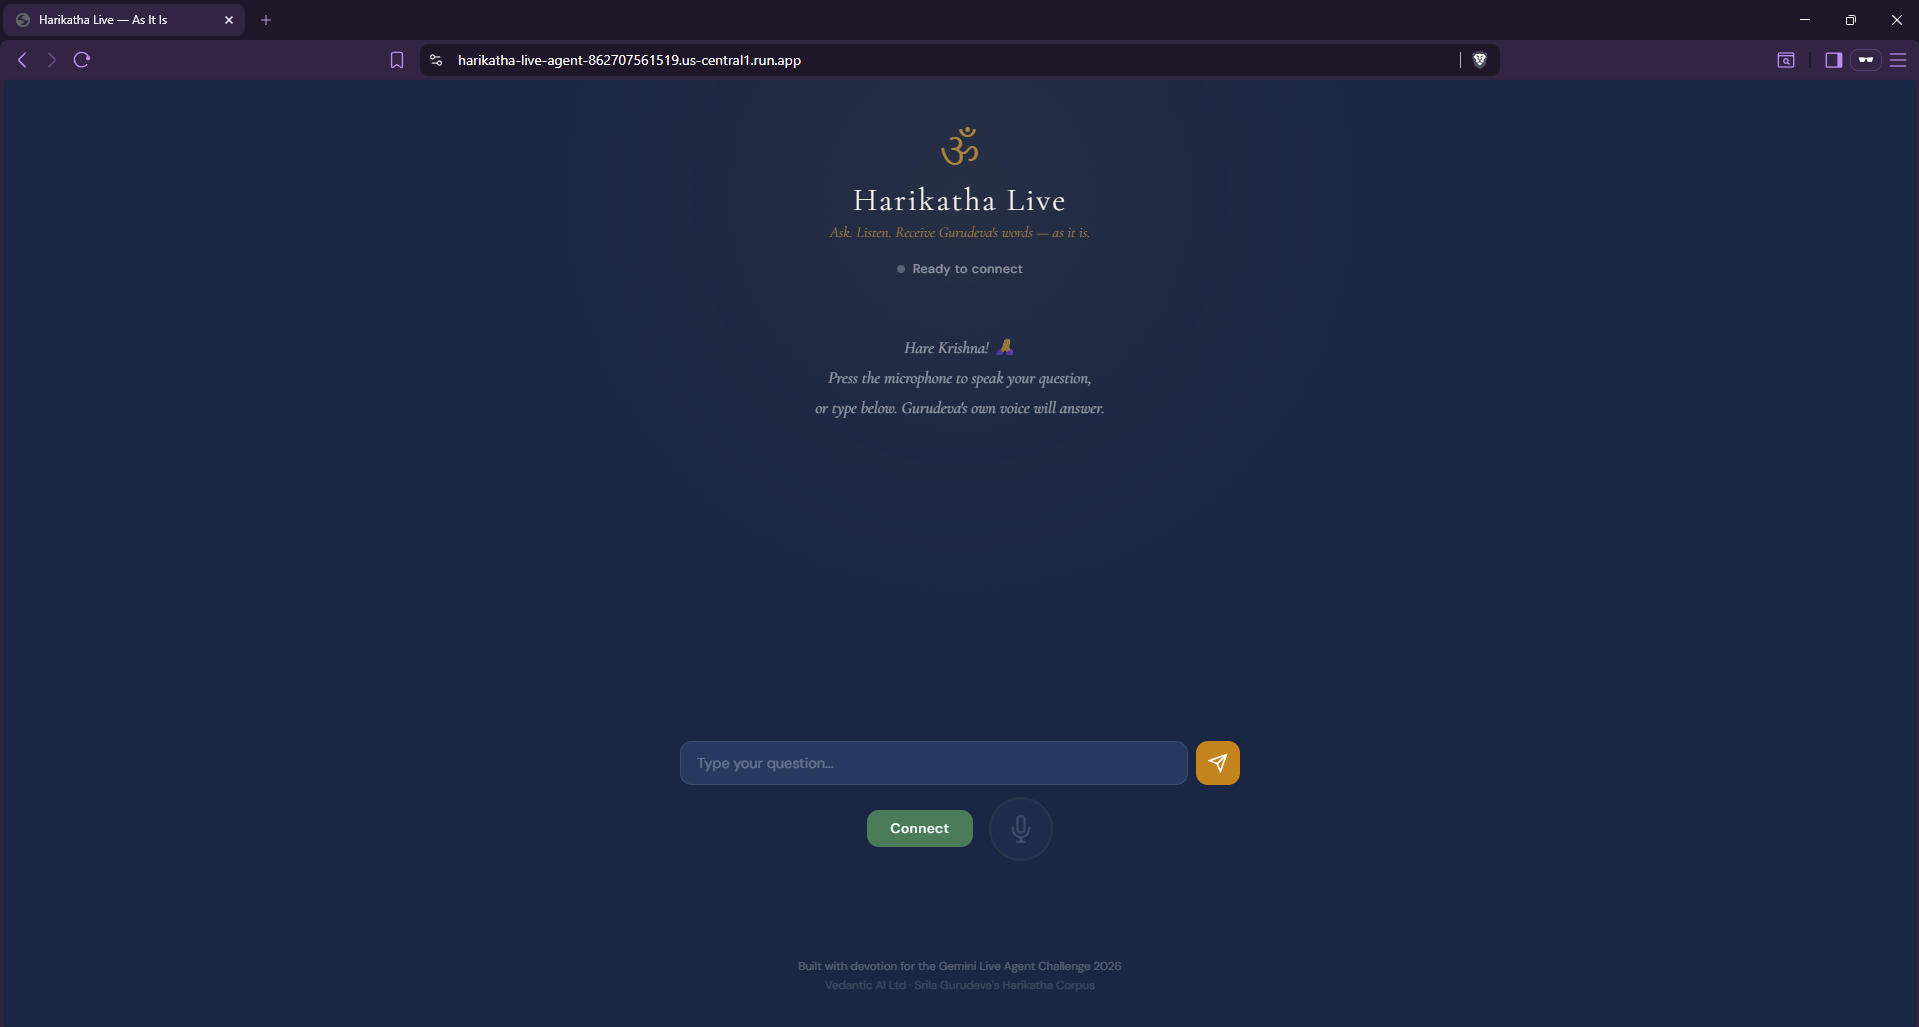
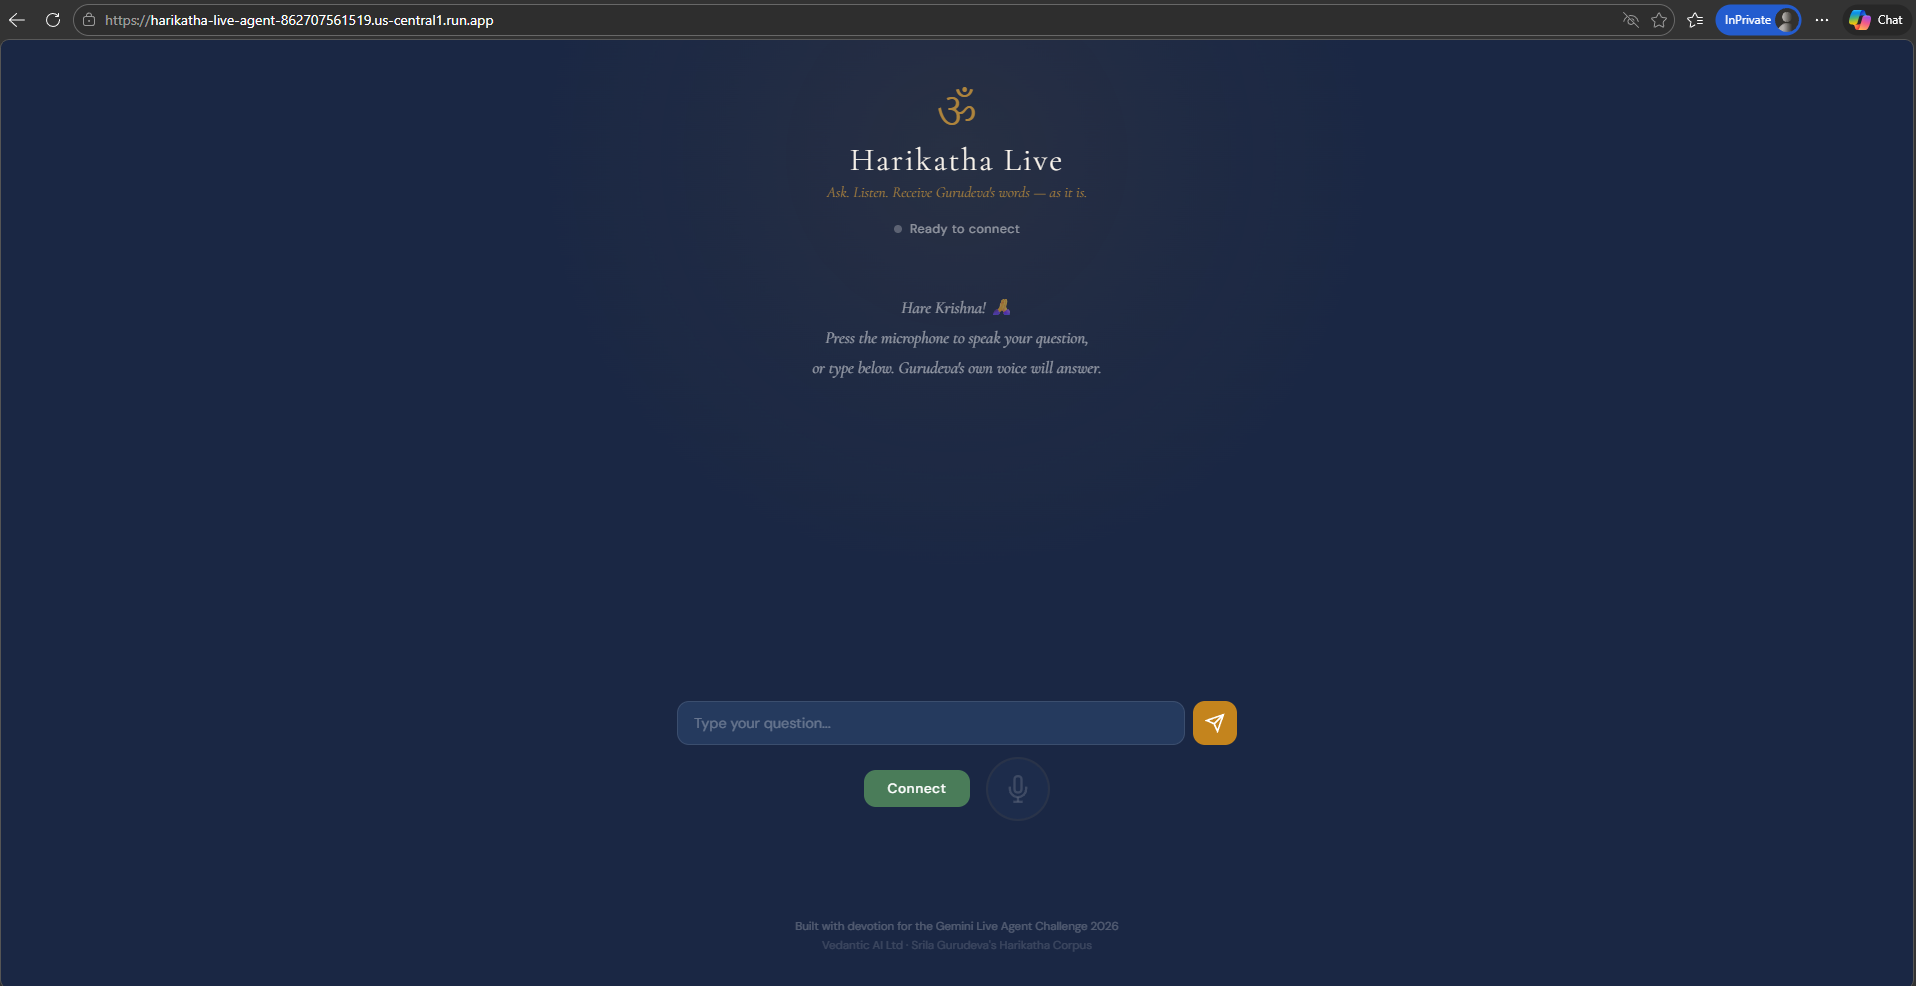
Harikatha Live lets seekers ask spiritual questions by voice or text and receive answers in Gurudeva's actual recorded voice — retrieved from the real corpus, never synthesized, never fabricated.
Designed for the seeker first:
- Text or voice input — ask your question by typing or speaking, whatever your situation allows
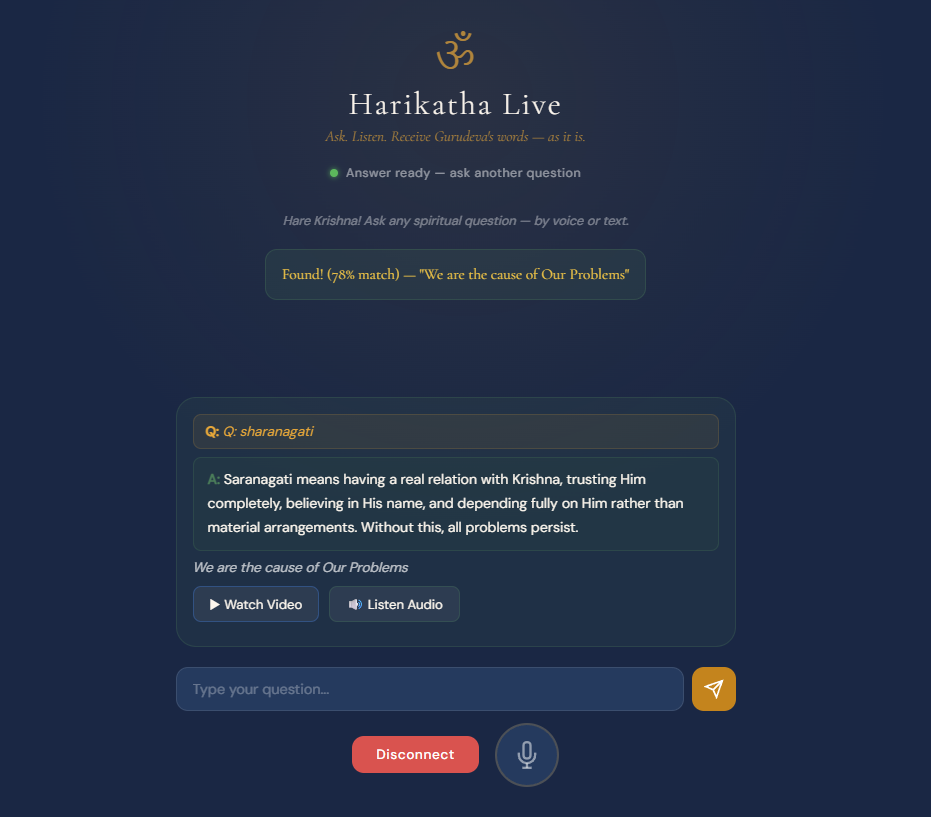
- Text, audio, or video response — the answer appears instantly as text, with optional audio and video on demand. In a public place? Read the transcript. Can you listen? Hear Gurudeva's voice. Want the full presence? Watch the video.
- Barge-in — ask a new question at any time, even while an answer is playing. The agent listens continuously, just like a real conversation.
The AI is the librarian, not the speaker.
How We Built It
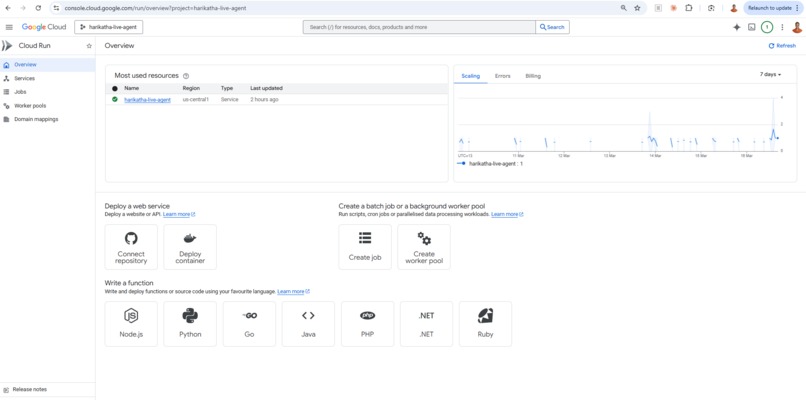
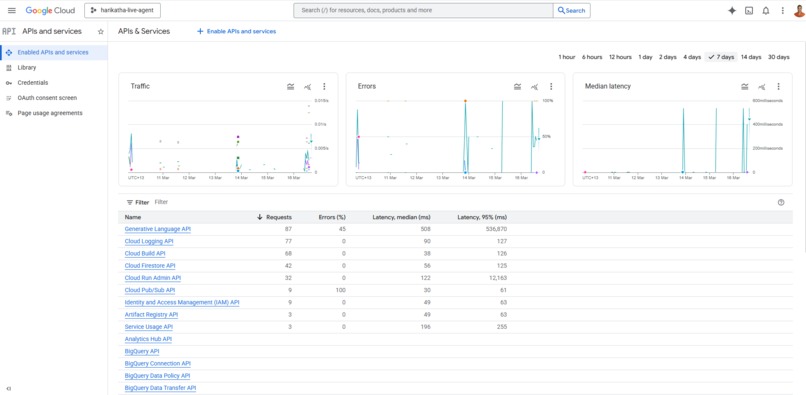
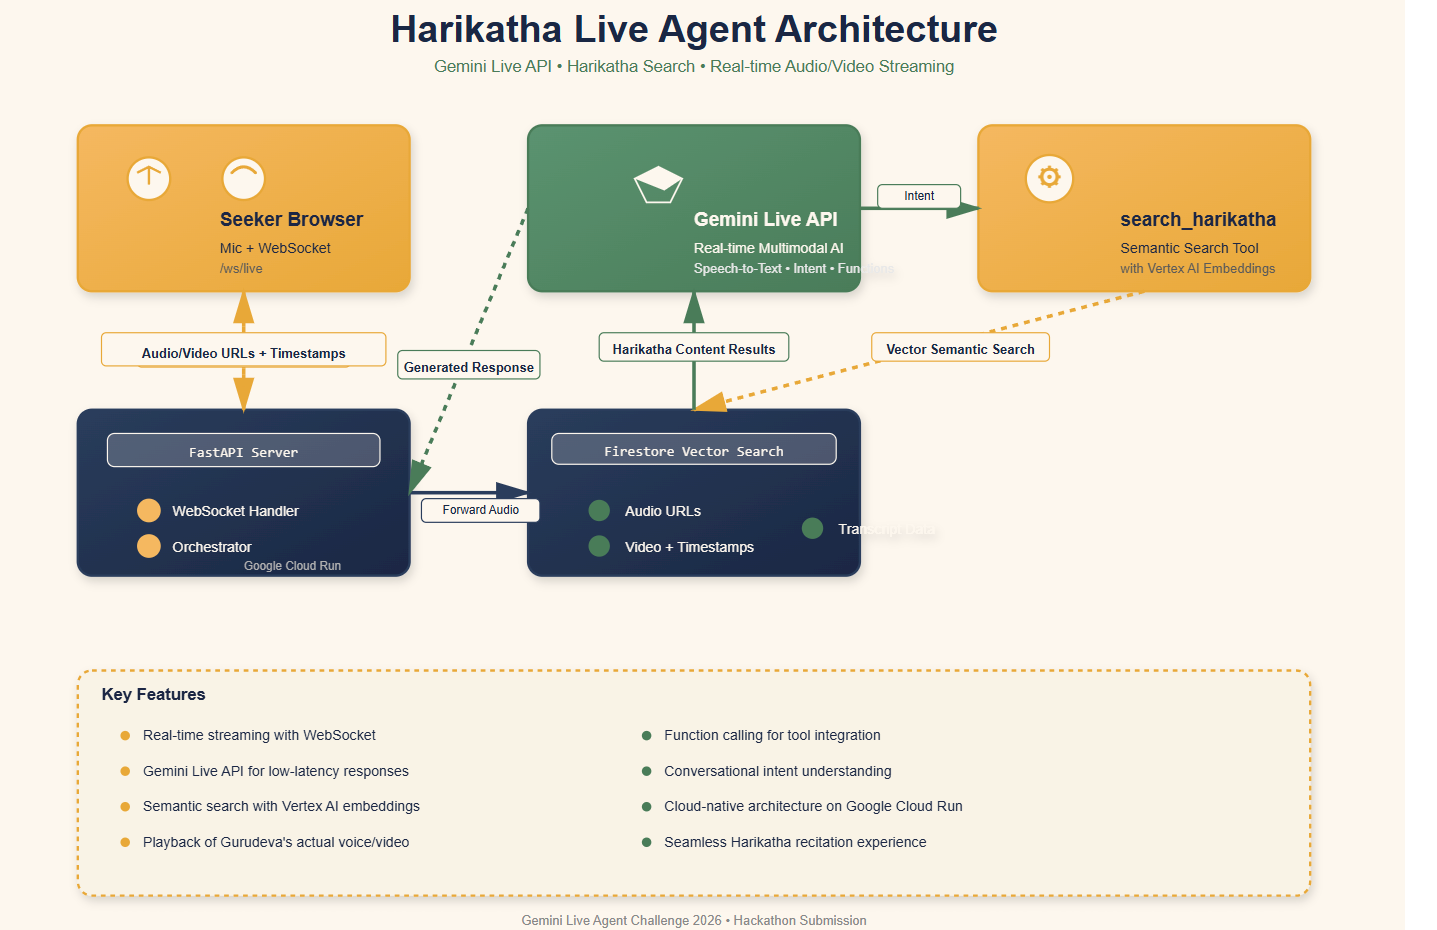
Gemini Live API handles real-time voice input and intent understanding
via a FastAPI WebSocket proxy on Cloud Run. When a question arrives,
Gemini calls a custom search_harikatha function tool. The backend
generates a semantic embedding using Gemini Embedding 001 (3,072
dimensions) and searches Firestore using cosine similarity. The matching
segment is returned with its exact start and end timestamp — audio and
video play from that precise moment only.
Seeker (voice/text)
  → Gemini Live API (intent + speech)
  → FastAPI Backend (Cloud Run)
  → Firestore Vector Search
  → Timestamped Audio/Video Segment
  → Gurudeva's real voice answers
Challenges We Ran Into
- Sanskrit terminology breaks standard embeddings — spiritual vocabulary requires domain-aware search strategies
- Transcription of accented English mixed with Sanskrit loses fidelity — three years of pipeline struggle shaped this project
- Gemini Live API WebSocket proxying required careful bidirectional relay with tool call interception
- Preventing Gemini's internal reasoning text from leaking to the UI
- Audio stopping precisely at the segment end timestamp
Accomplishments That We're Proud of
A seeker can ask "What is saranagati?" and hear Gurudeva's actual voice answer — at the exact timestamp, from the real recording.
Zero fabrication. Zero synthesis. As it is.
What We Learned
Multimodal embedding is the strategic unlock — embedding audio directly without transcription bypasses three years of pipeline pain. Gemini Embedding 2 (released March 2026) makes this possible for Phase 2.
What's Next for Harikatha Live Agent
- Index all 2,500+ videos and 7,000+ audio recordings
- Migrate to Gemini multimodal embeddings — embed audio directly, no transcription needed
- RLHF review pipeline with trusted Vaishnava reviewers
- Make Gurudeva's complete corpus searchable by any seeker worldwide
- Full system operational around early 2027
Built With
- ai
- api
- cloud
- docker
- fastapi
- firestore
- gemini
- genai
- javascript
- live
- python
- run
- sdk
- vertex
- websockets

Log in or sign up for Devpost to join the conversation.