-
-
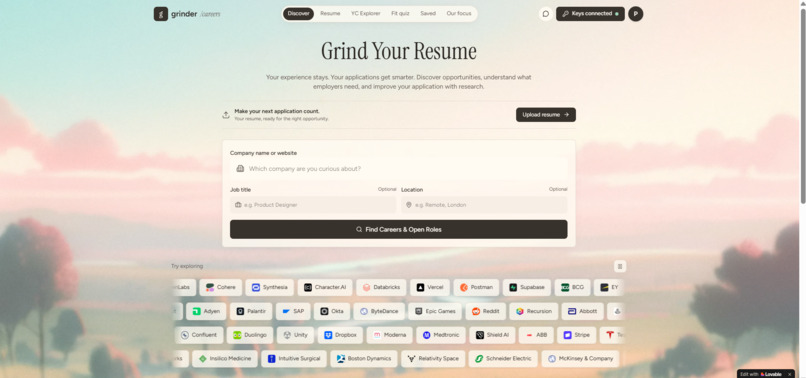
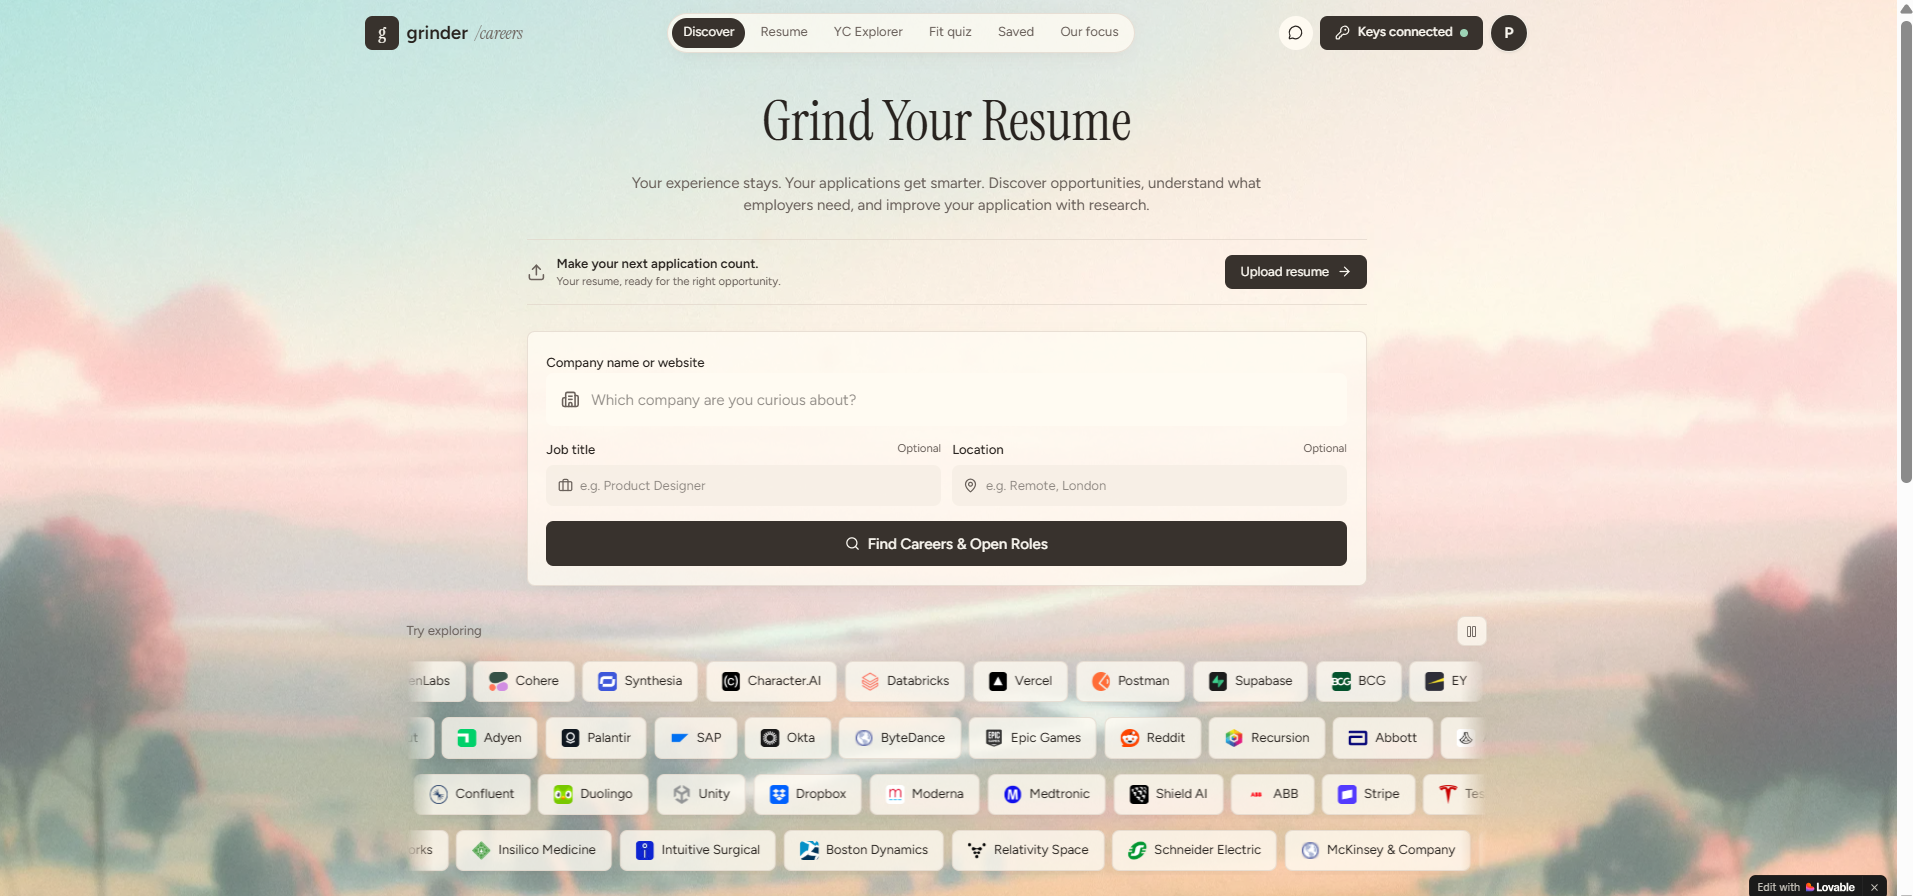
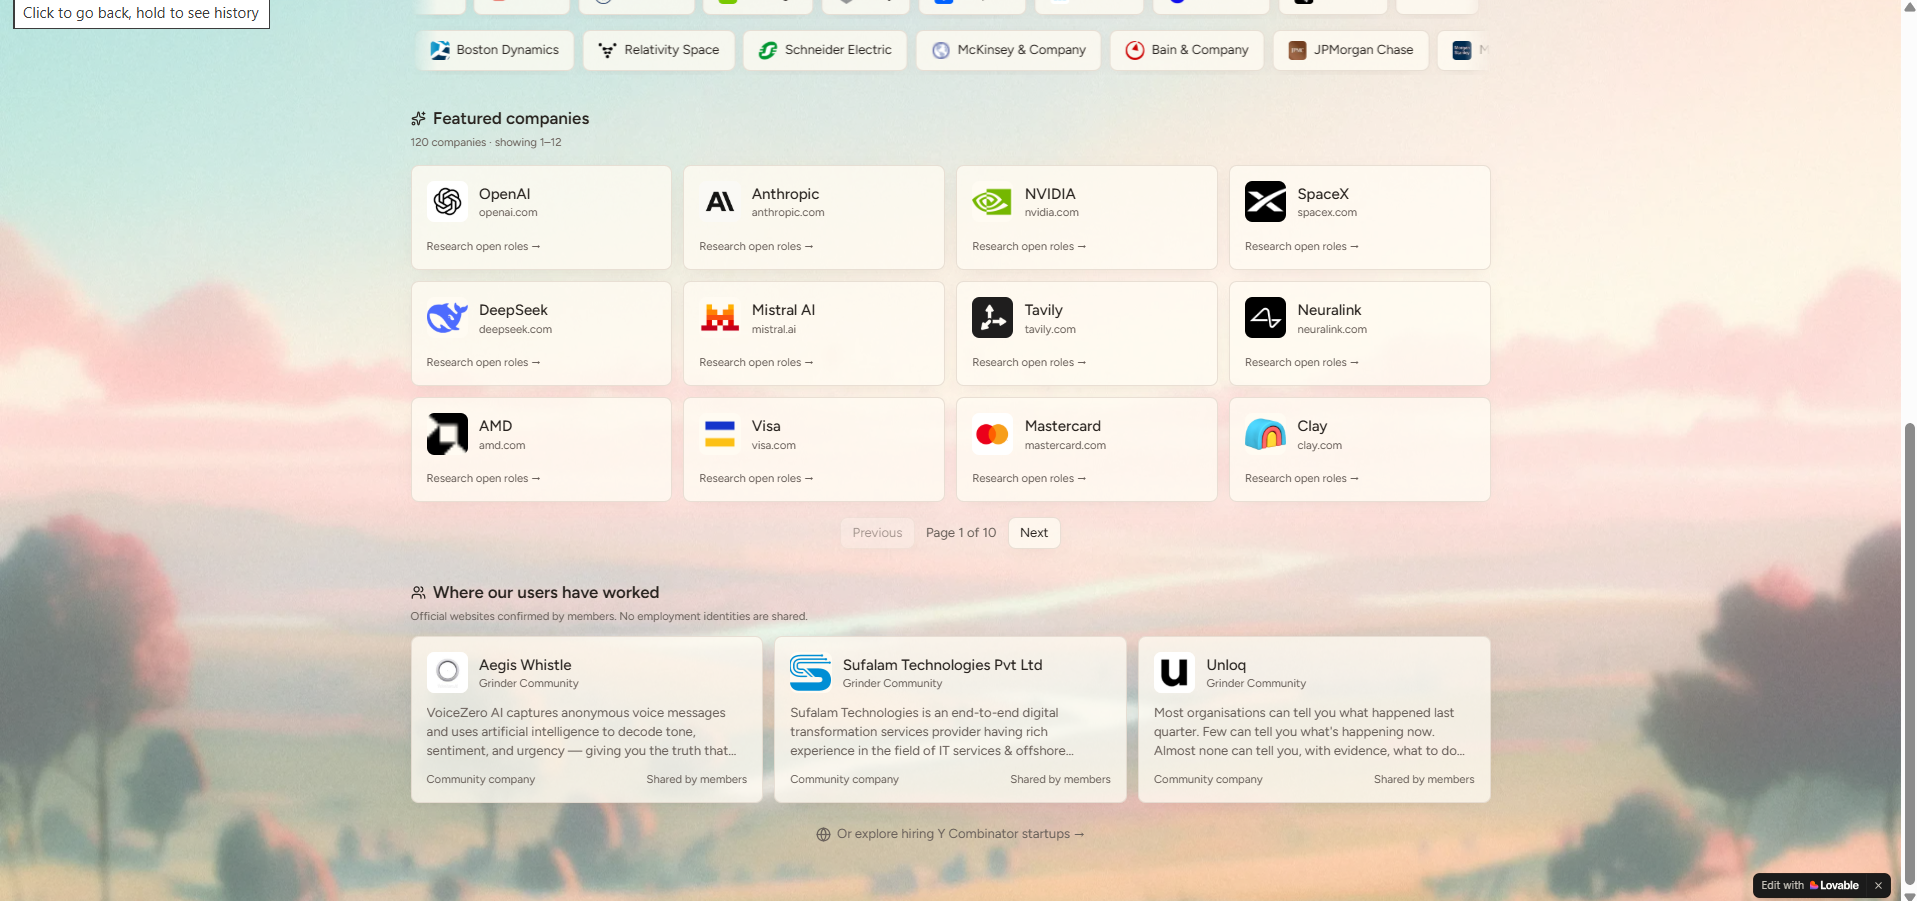
Grinder Discover
-
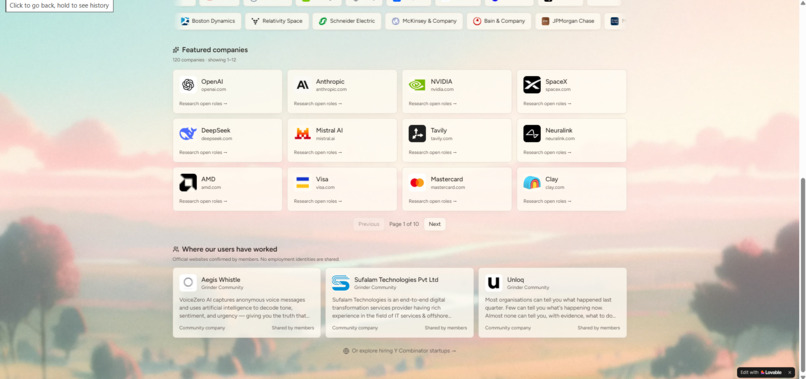
Featured and Users who worked
-
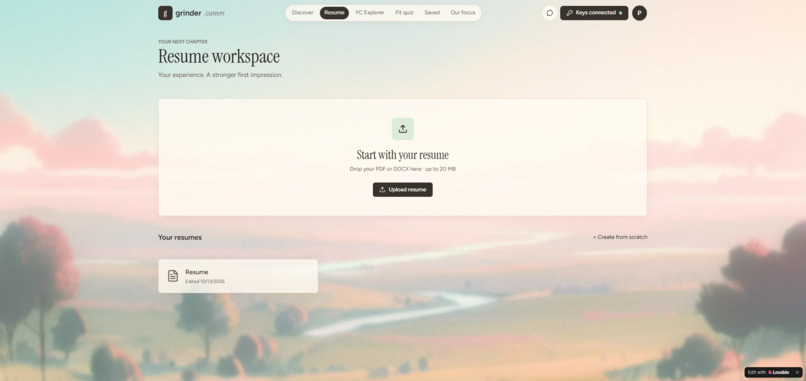
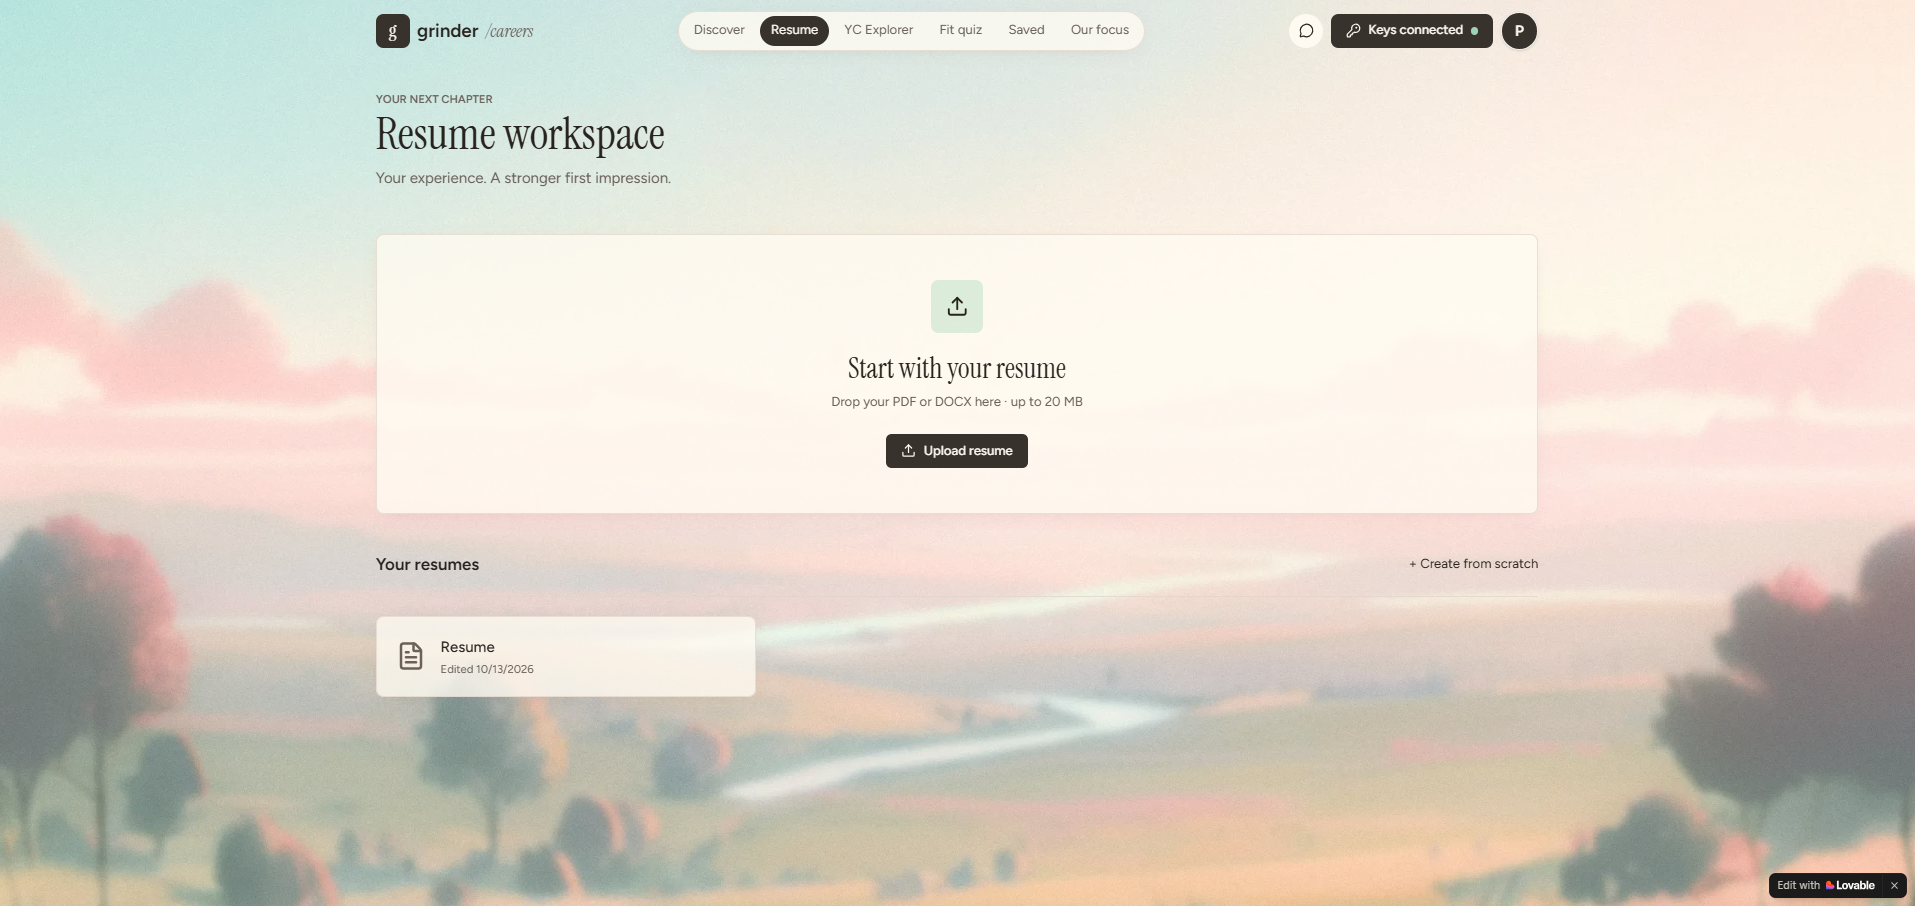
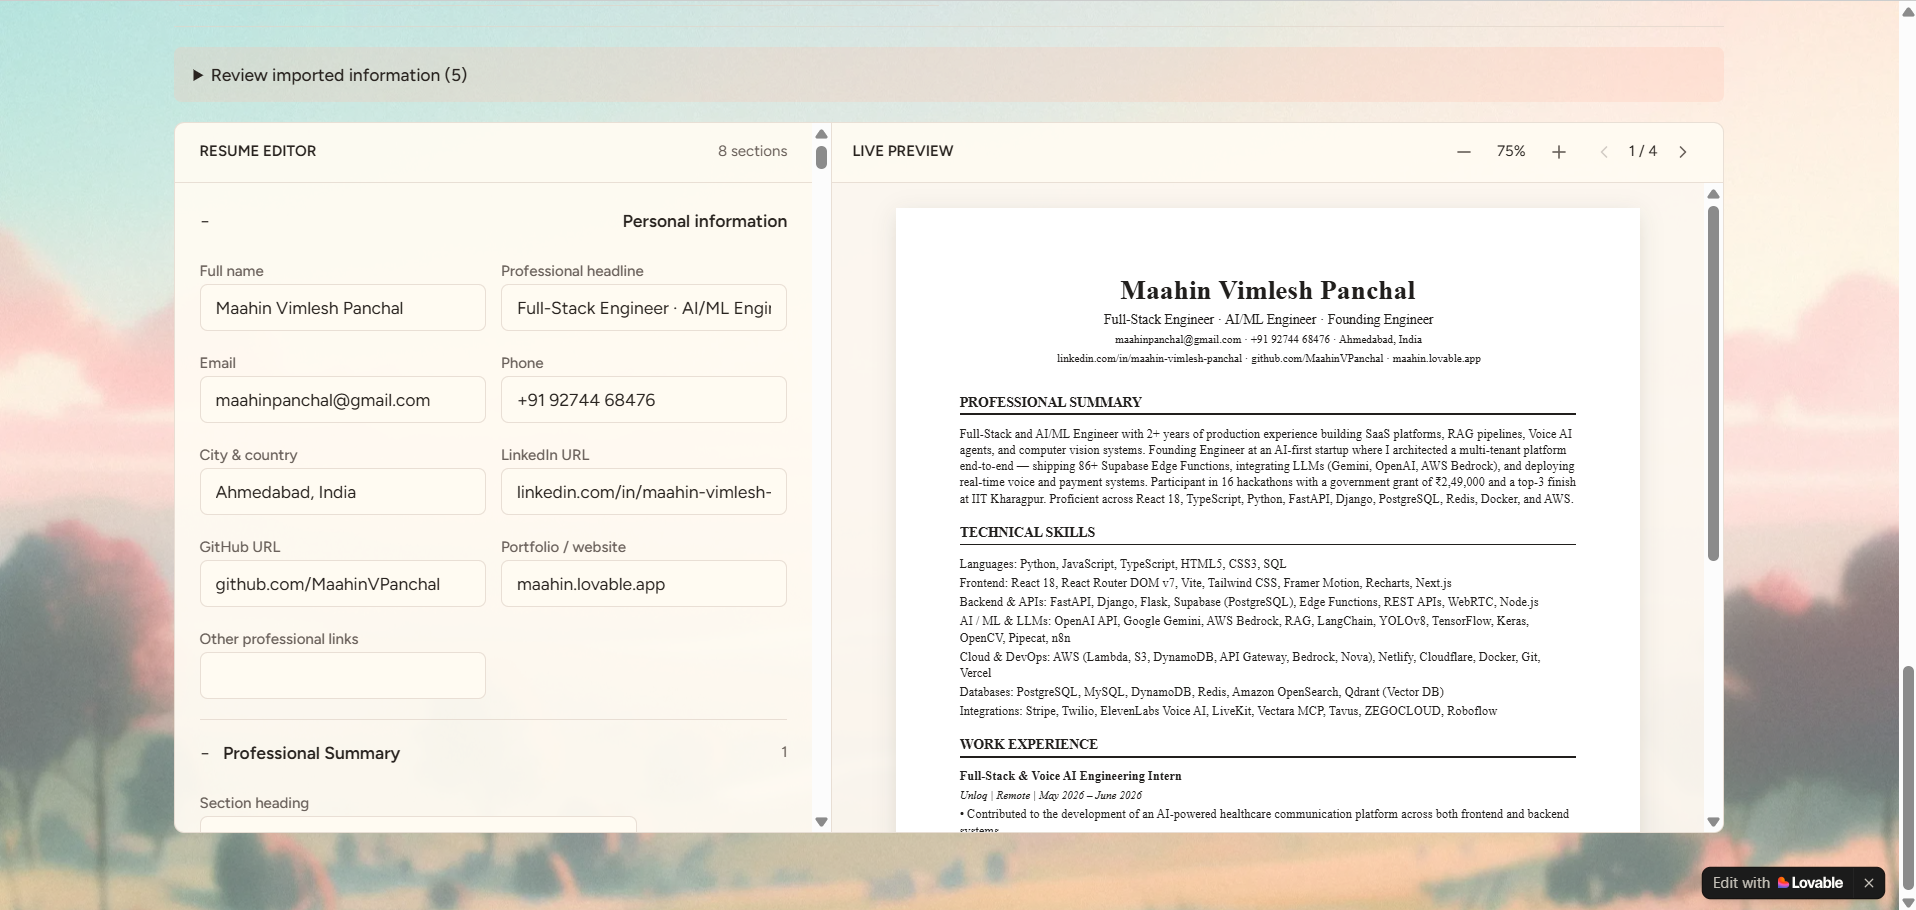
Resume workspace
-
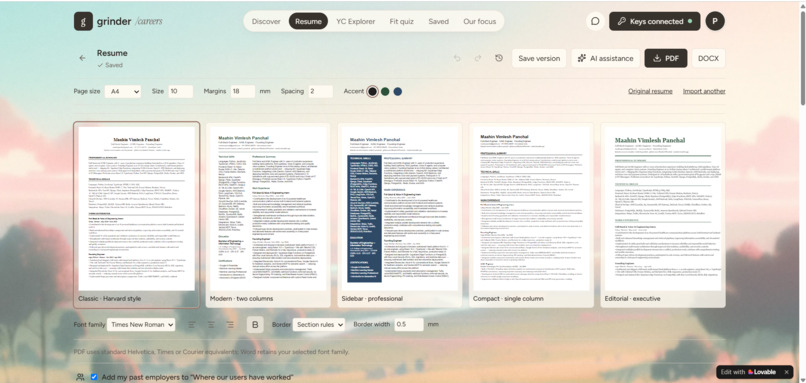
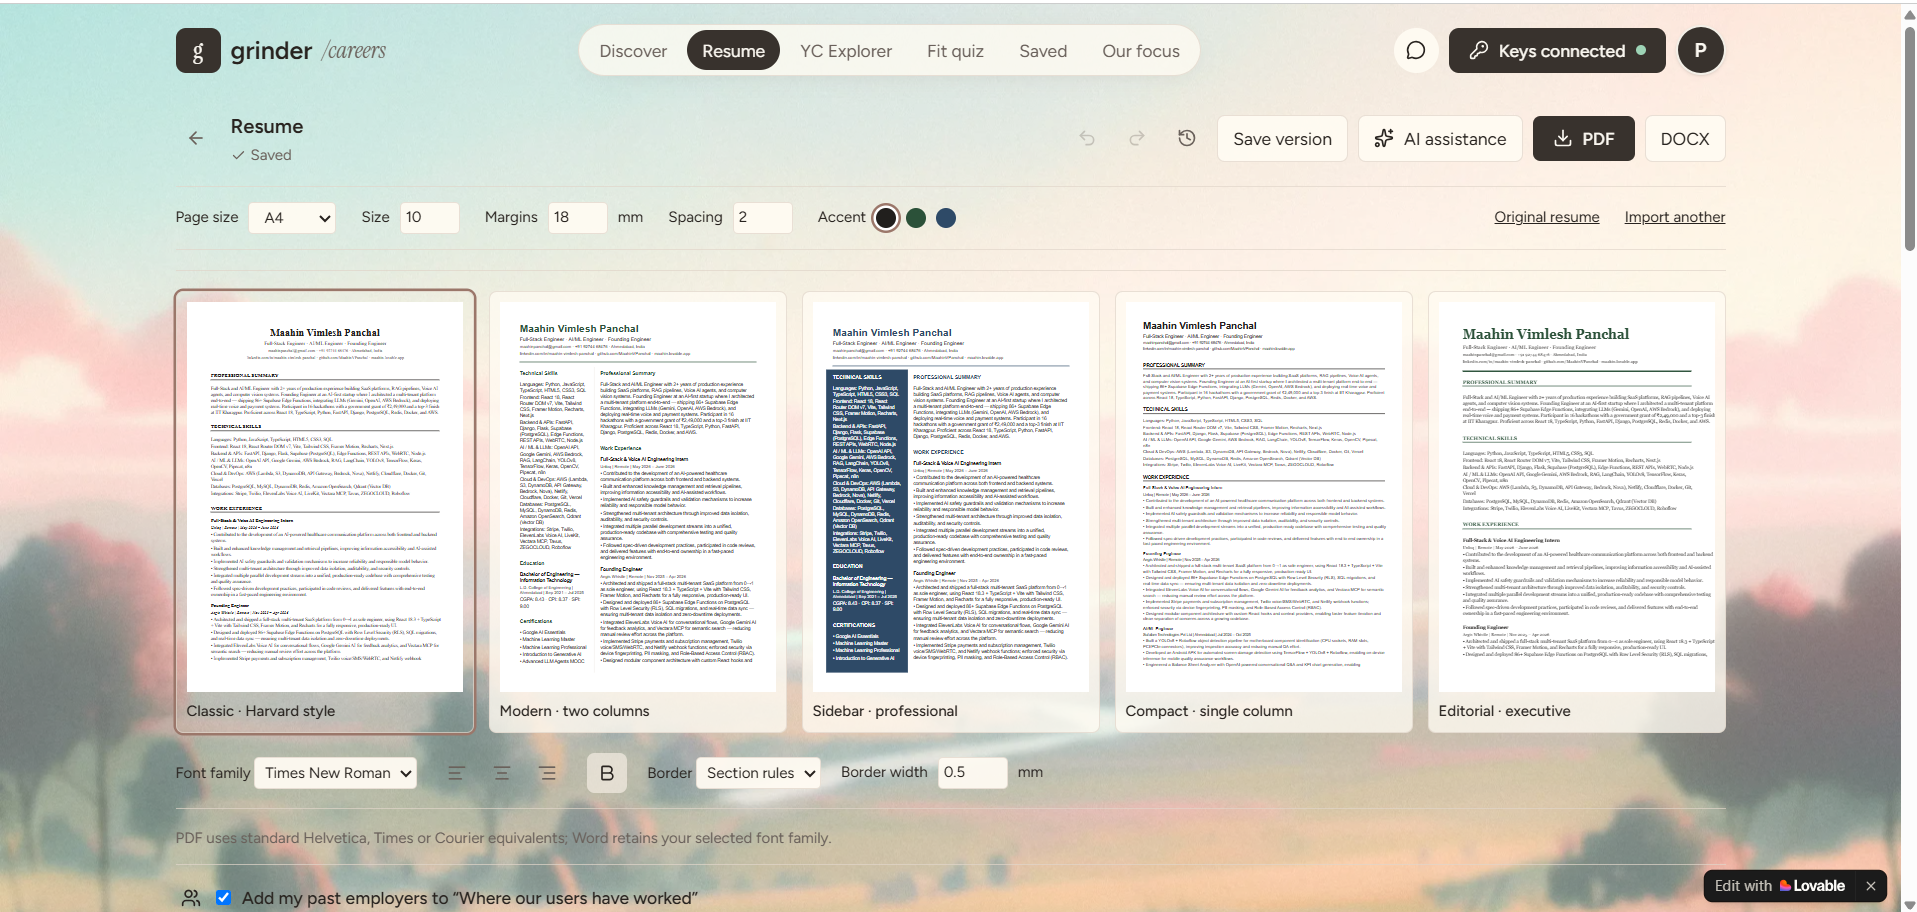
Tailor your resume
-
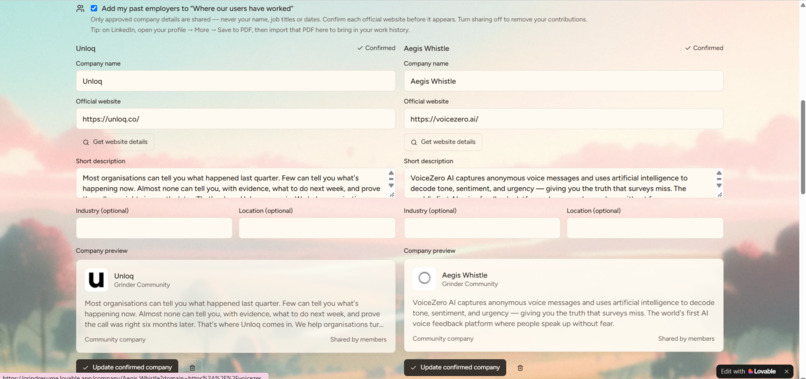
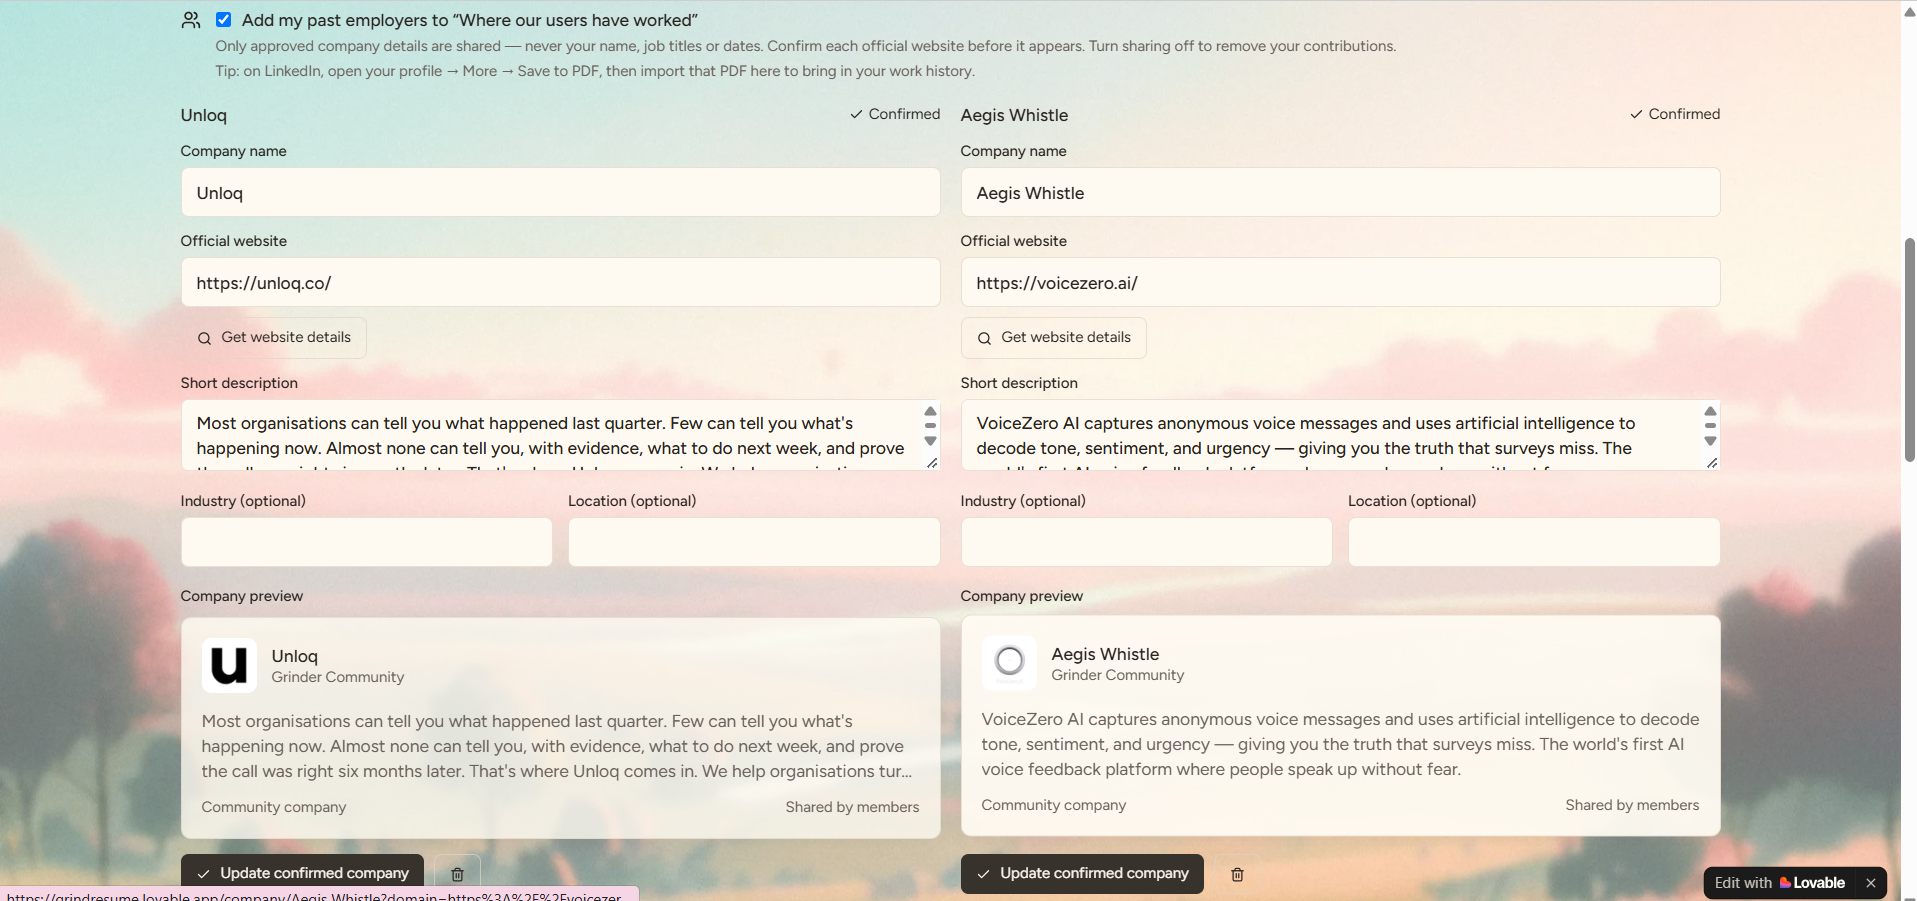
Add your past company details
-
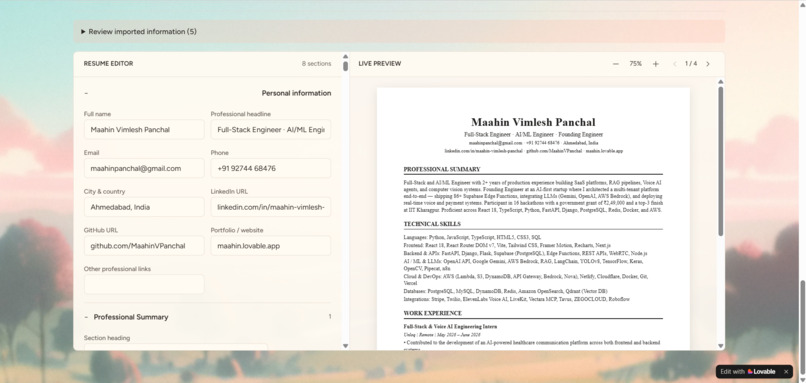
Live preview
-
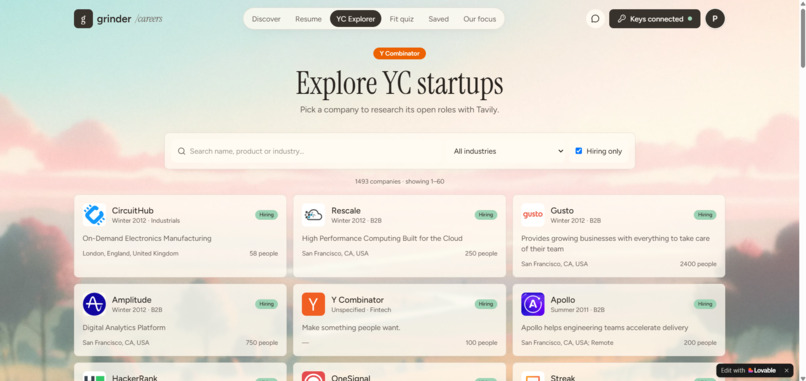
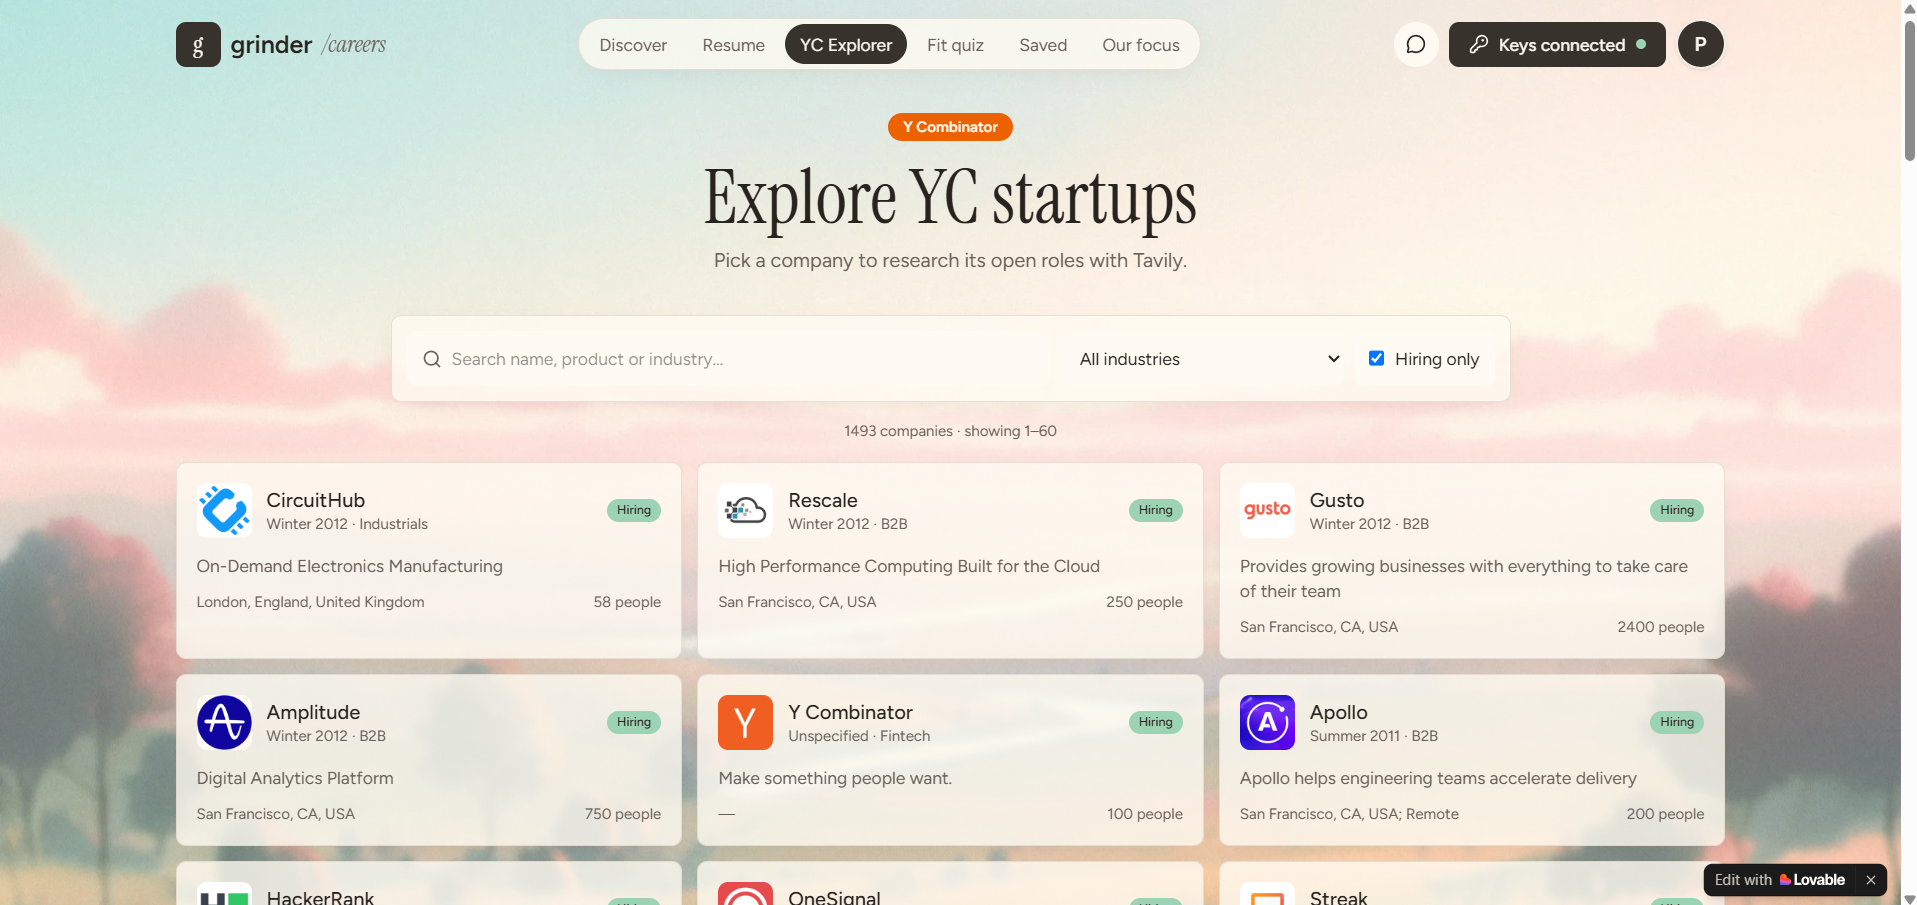
YC jobs hiring or open
-
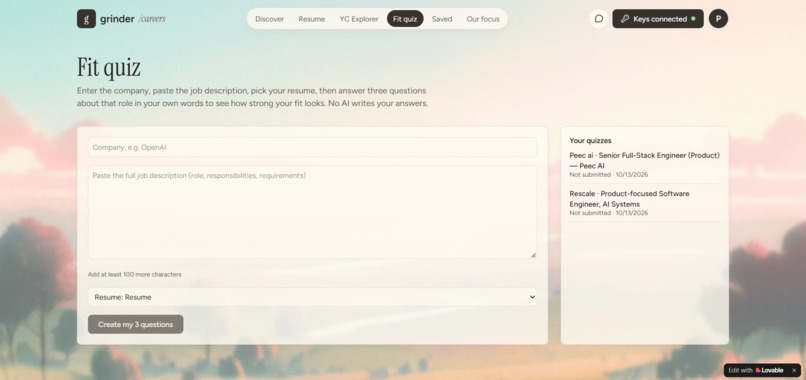
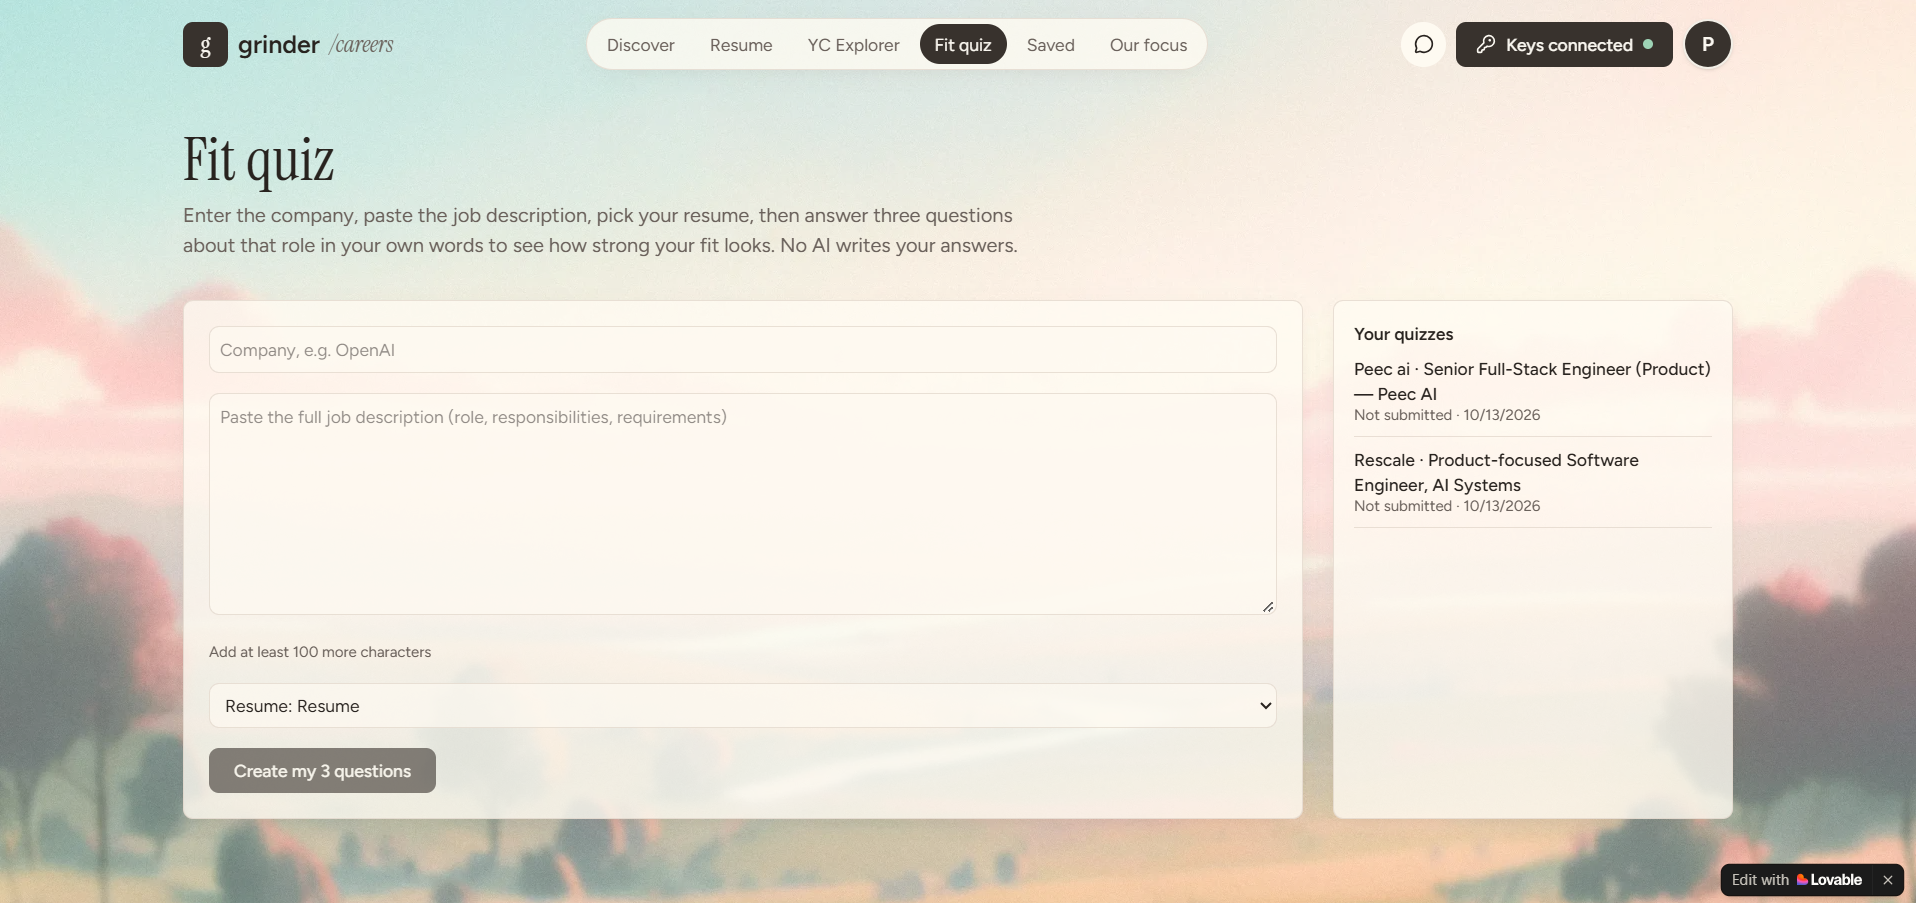
Fit quiz is the way to get quiz based on requirements and resume
-
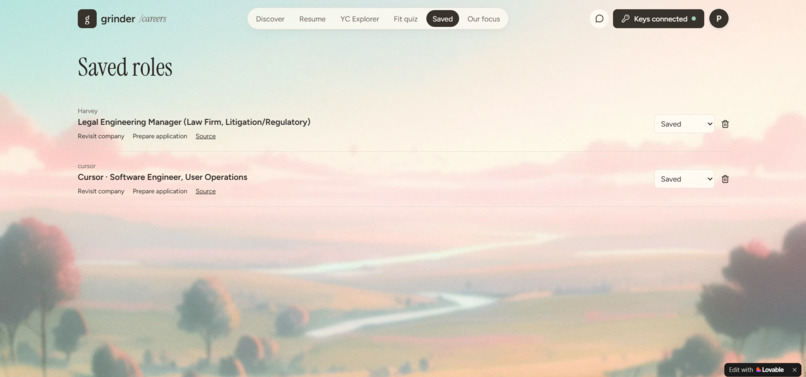
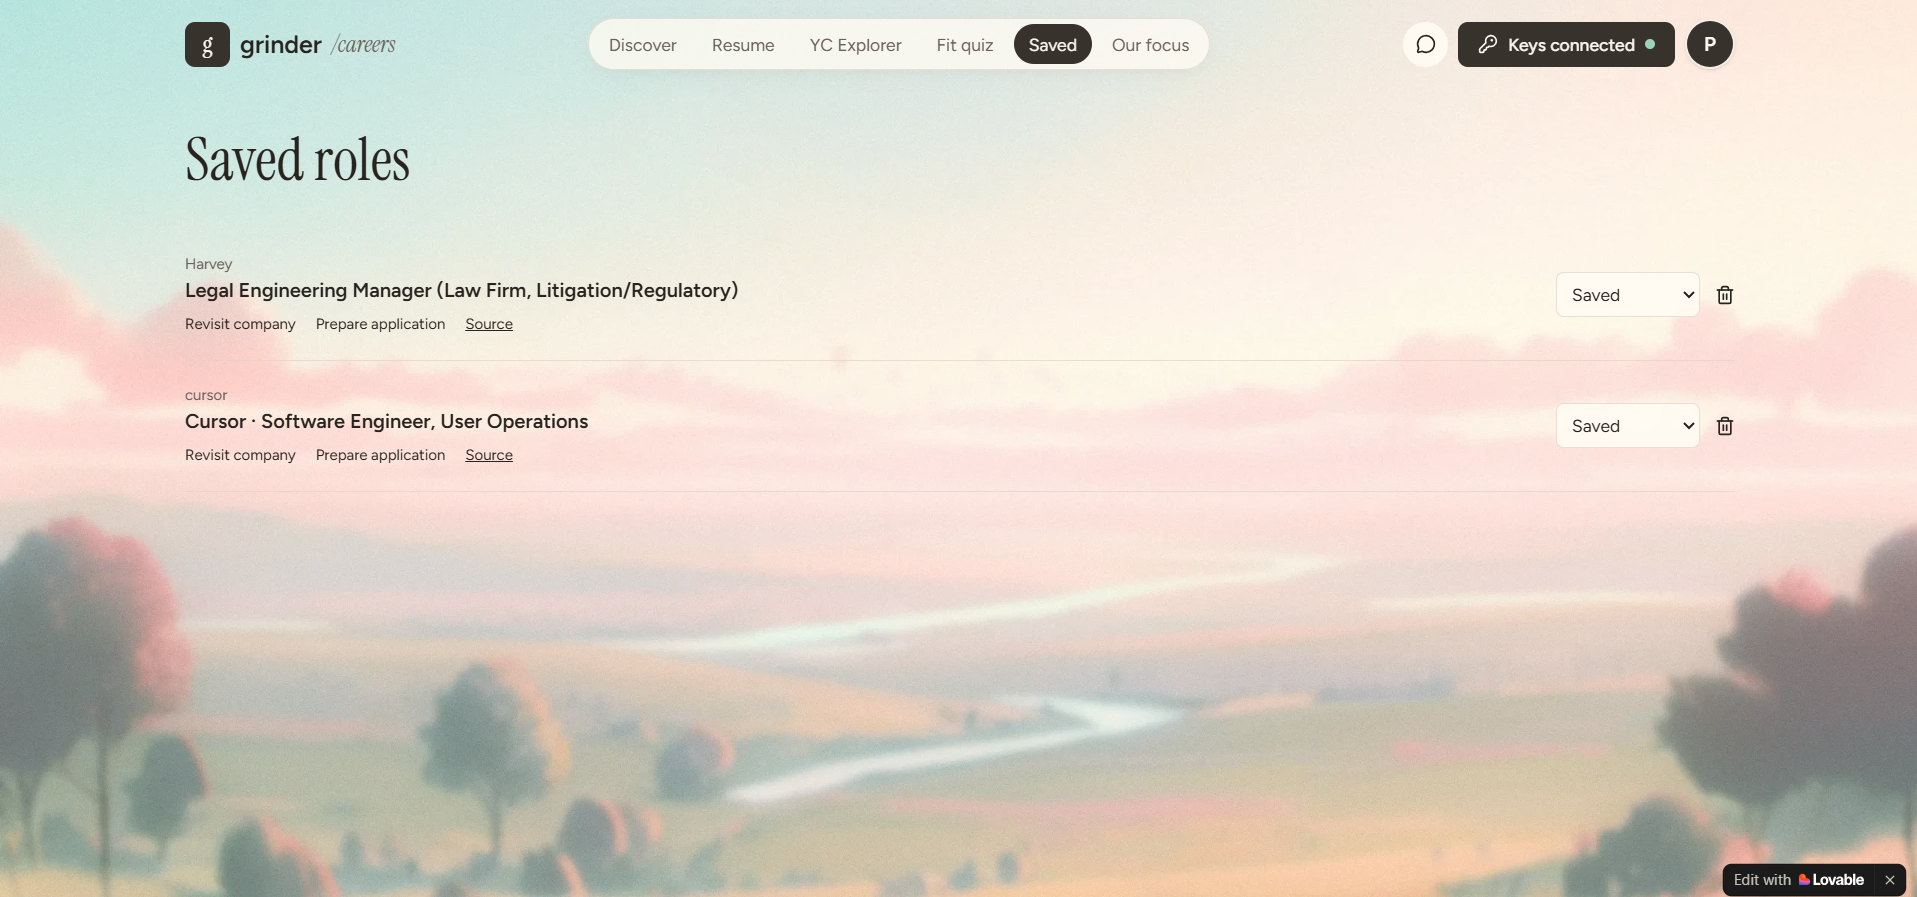
Saved jobs
-
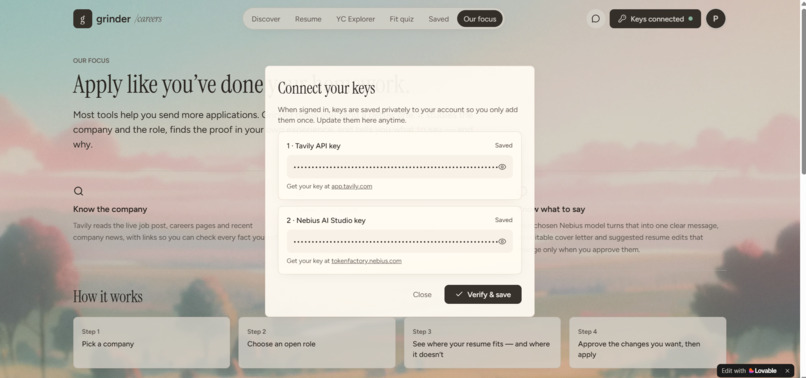
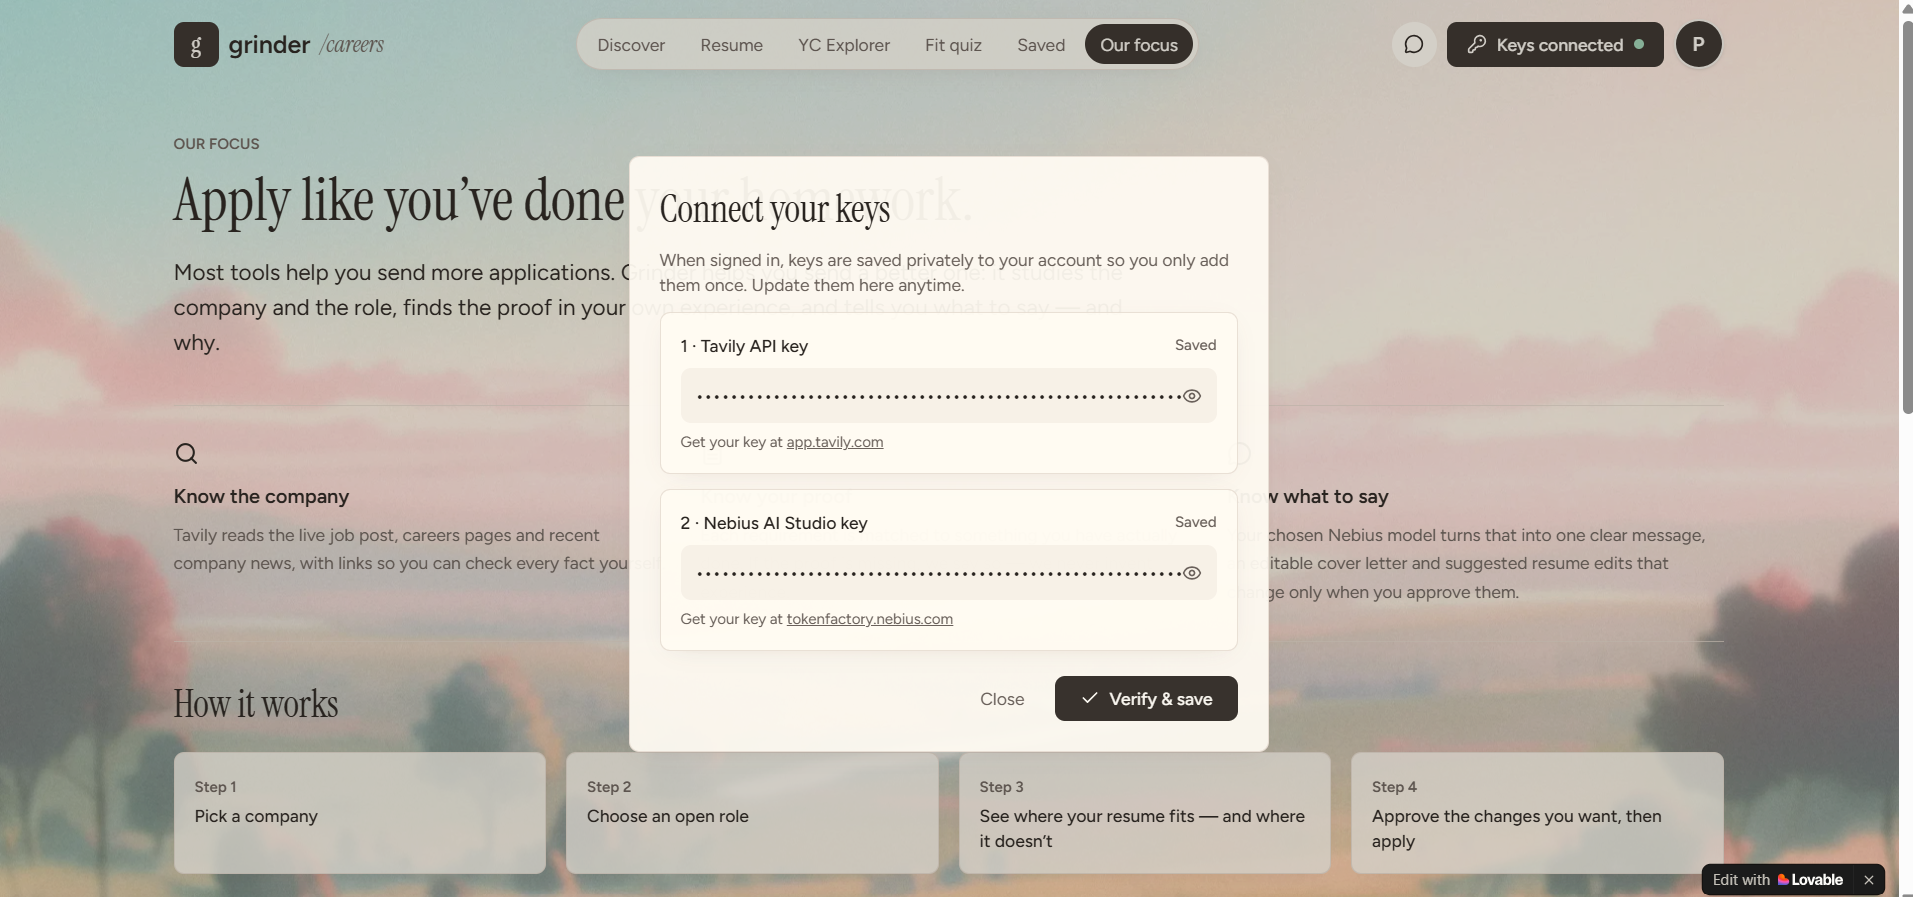
Connect your keys
-
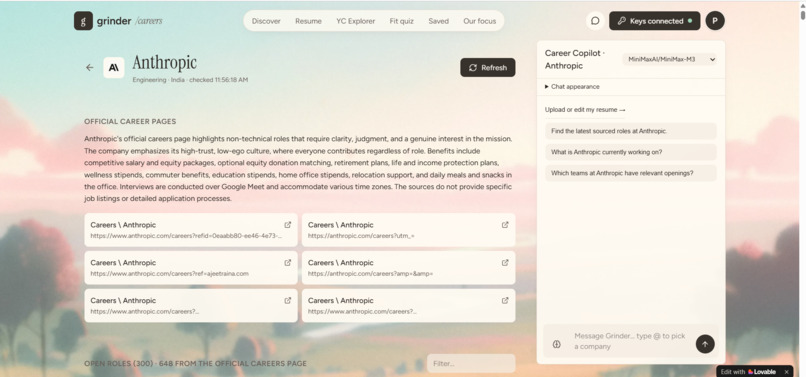
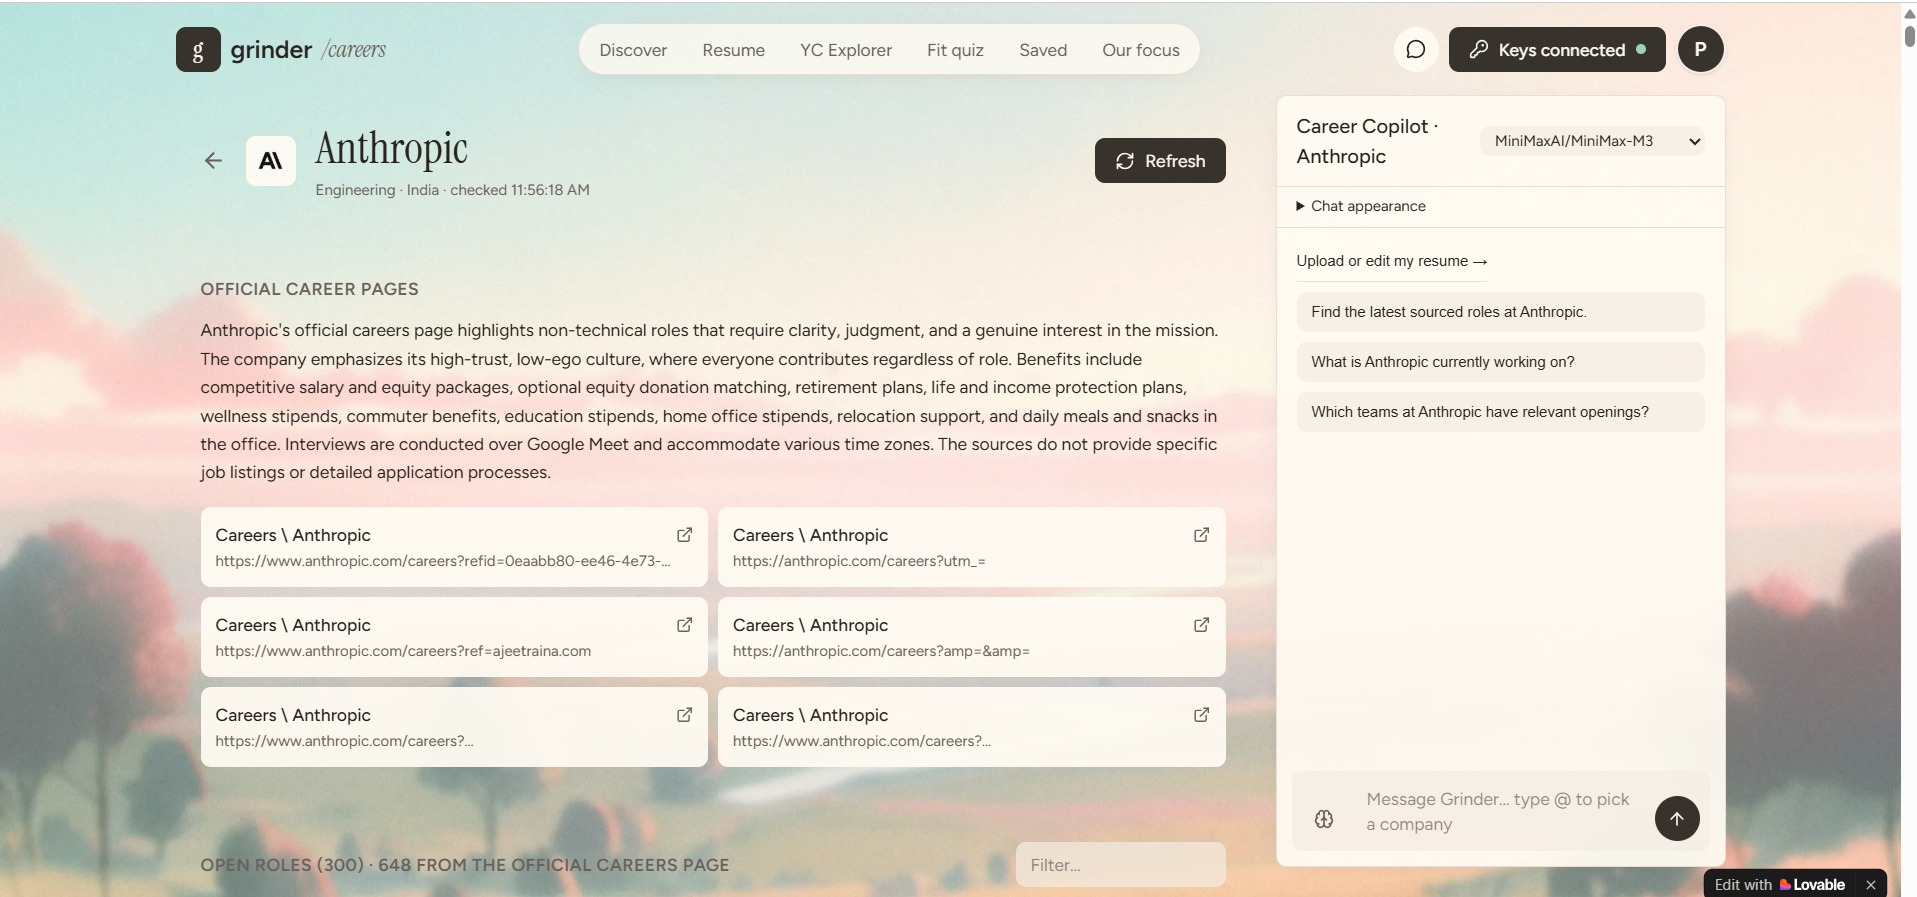
Tavily use case for searching jobs
-
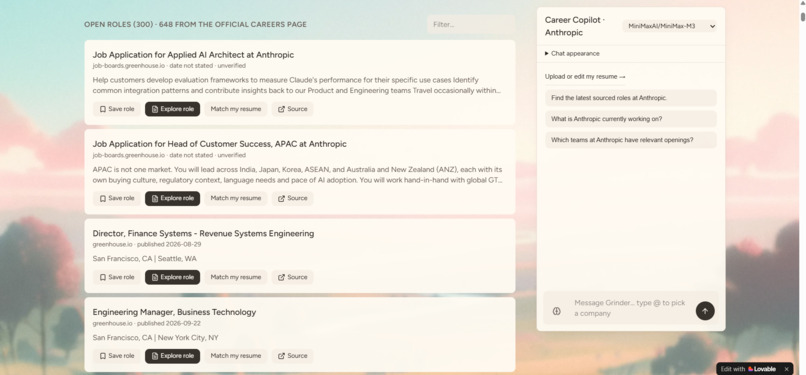
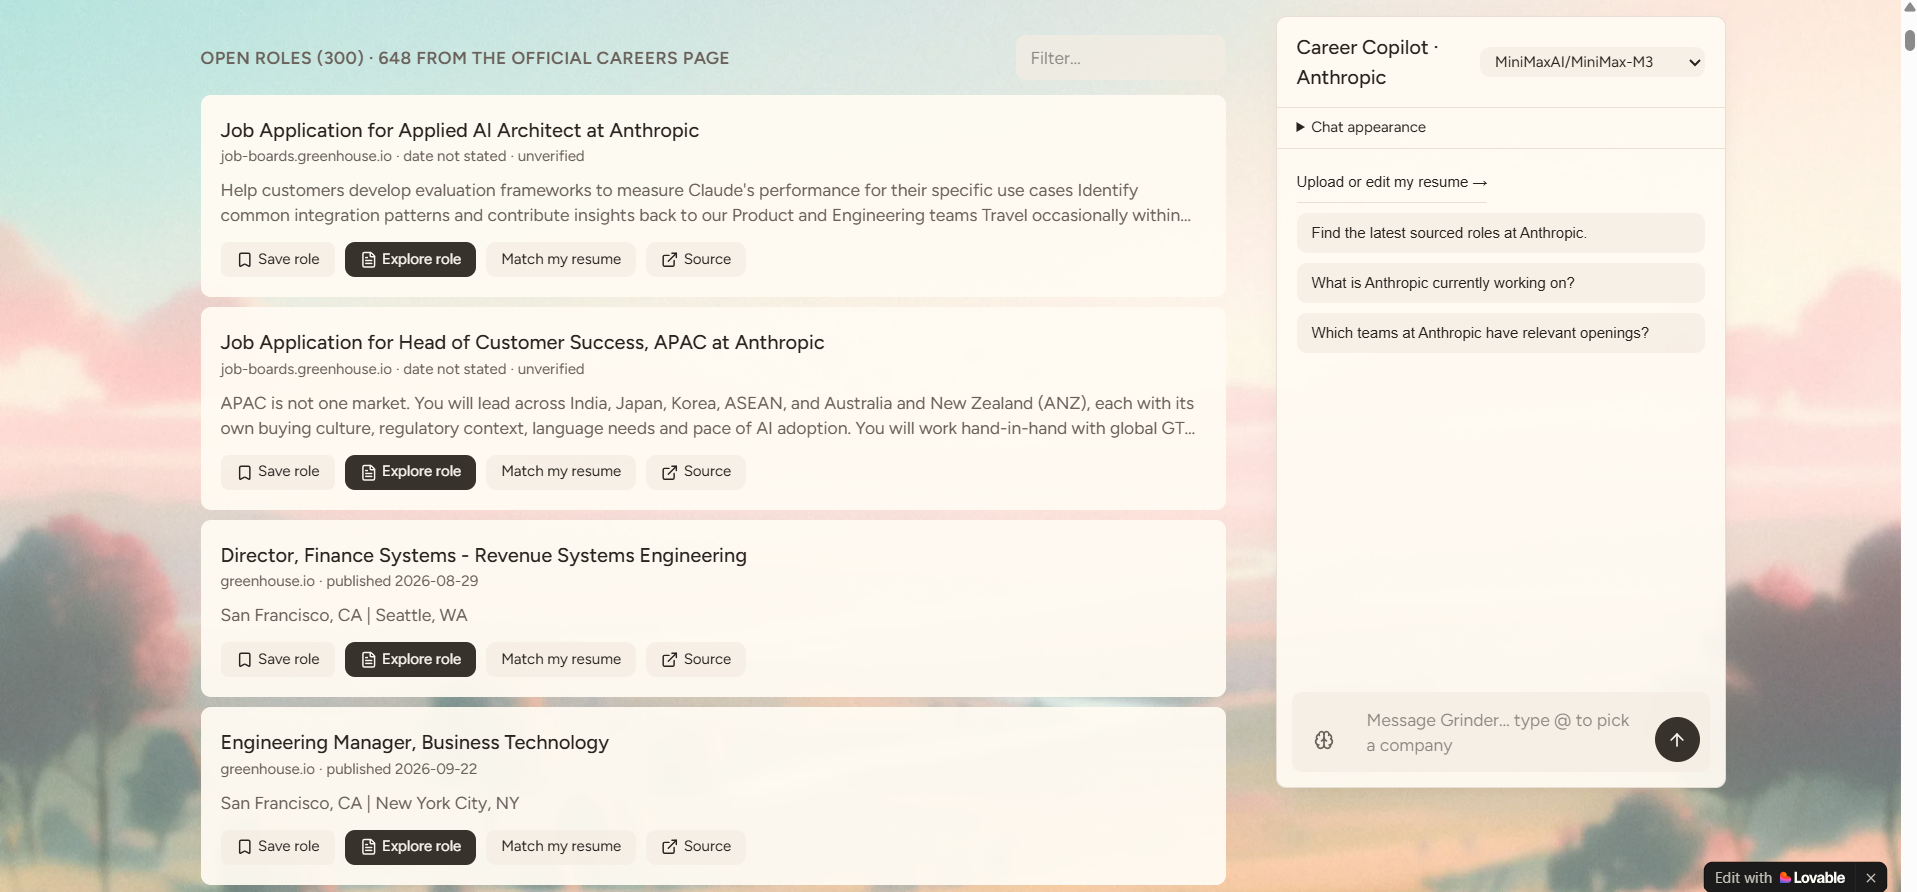
Search across 300 roles
-
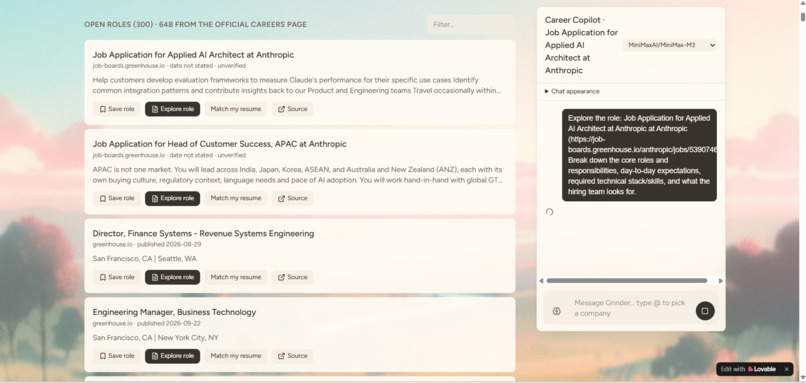
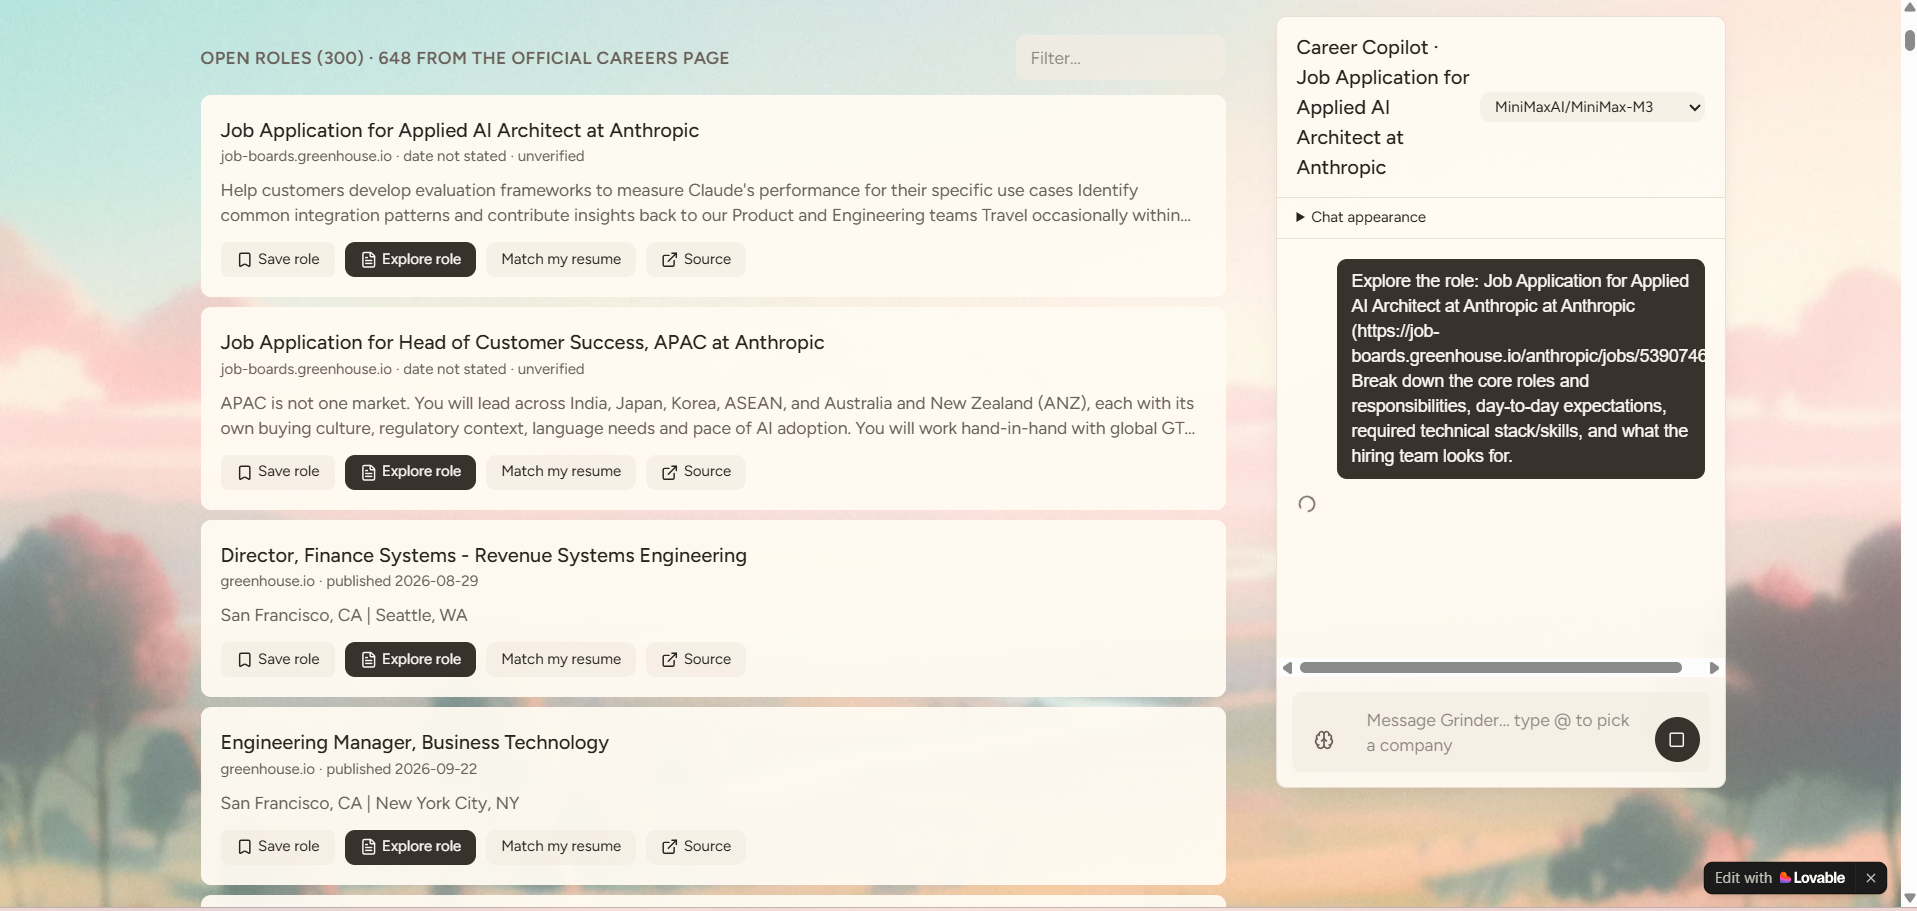
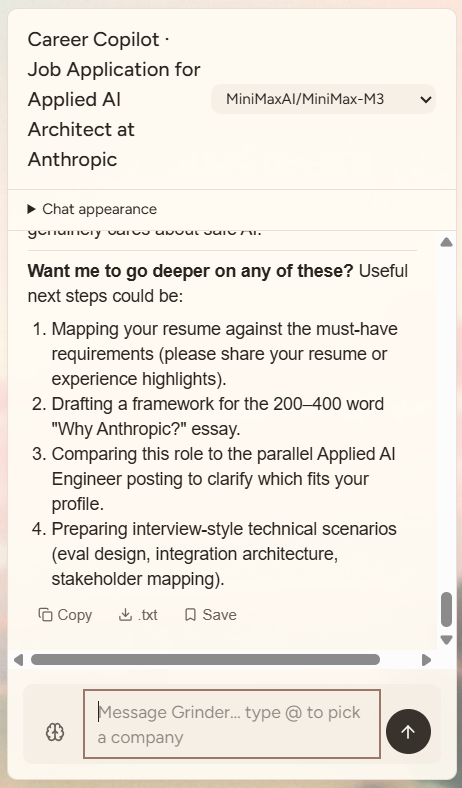
Explore role through chat with Nebius on clicking get ready
-
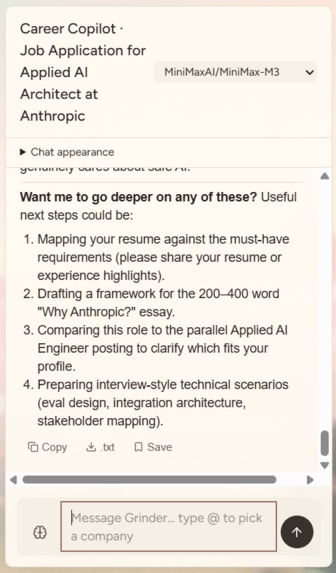
Copilot response for explore job
-
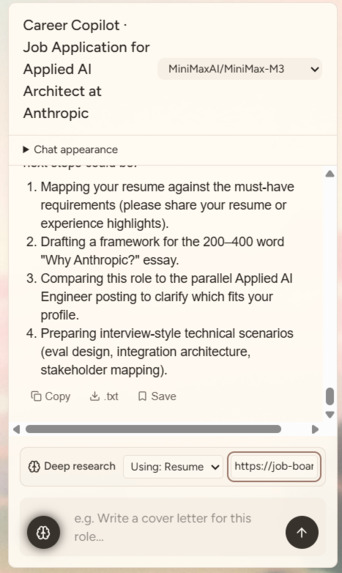
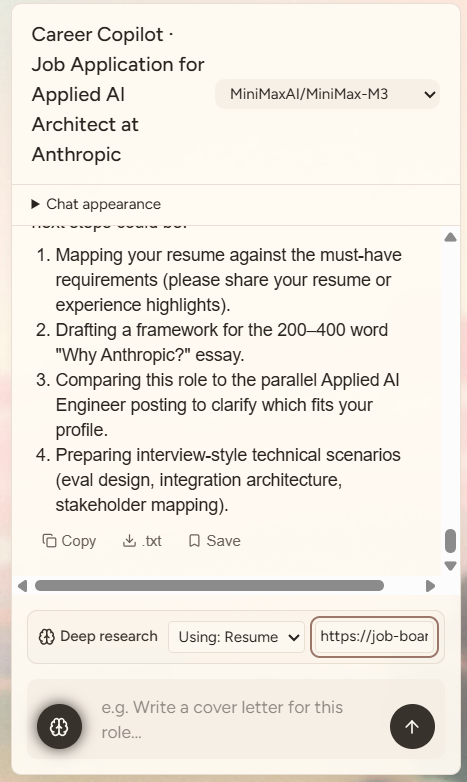
We can also do deepresearch powered by tavily and nebius models with specific job url with resume.
GrinderResume
Inspiration
Job searching today is dominated by two flawed extremes.
1. Traditional job boards (LinkedIn, Indeed)
Traditional job boards are static, noisy databases flooded with expired listings, sponsored spam, and opaque applicant tracking systems (ATS). They provide candidates with little actionable feedback about why their profiles match—or fail to match—a role.
2. Generic AI resume builders (ChatGPT wrappers, Teal, Resume.io)
Many AI resume tools rely on uncalibrated generation. They produce sycophantic, buzzword-heavy cover letters and may fabricate unverified skills or experience. When candidates face actual hiring managers or technical interviews, this fabricated facade quickly crumbles.
Furthermore, frontier LLMs operate in an informational vacuum without reliable access to live company engineering updates, current job openings, and dynamic, client-rendered ATS platforms.
We built GrinderResume to bridge this gap by uniting two specialized AI infrastructures:
- Tavily AI: Solves the real-time, grounded-knowledge problem by discovering and extracting job openings and technical initiatives from live career pages. It helps bypass stale search indices and client-rendered ATS roadblocks.
- Nebius AI: Addresses calibrated reasoning and domain specialization by running high-throughput, open-weight models such as DeepSeek-V3, MiniMax-M3, and Llama 3.1. Strict evidence constraints help prevent hallucinations, while structured candidate interactions feed a continuous dataset flywheel designed for Nebius Token Factory fine-tuning.
What It Does
GrinderResume is an active career intelligence copilot, document workspace, and post-training data flywheel.
1. Live ATS Role Discovery — The Tavily Engine
Automatically discovers and maps live openings from leading technology companies and Y Combinator startups. Instead of relying solely on stale aggregator listings, it extracts authentic job opportunities from ATS platforms such as Greenhouse, Ashby, and Lever.
2. Evidence-Grounded Role Breakdown — Explore Role
Gathers real-time intelligence about company initiatives, technology stacks, role requirements, and day-to-day responsibilities. It delivers evidence-backed role analysis without generic, filler-heavy recommendations.
3. Fact-Locked Resume Matcher — Match My Resume
Compares candidate resumes against specific job requirements using calibrated analysis and supporting evidence.
The system enforces zero-hallucination guardrails by design:
- Refuses to invent skills, qualifications, or experience.
- Assigns calibrated match verdicts: Strong, Moderate, or Stretch.
- Identifies specific technical and experience gaps.
- Builds concrete learning paths to help candidates address those gaps.
4. Active Candidate Fit Quiz
Unlike platforms that simply ghostwrite answers for candidates, the Fit Quiz challenges applicants with role-specific engineering and behavioral scenarios that they must answer in their own words.
Nebius-powered models evaluate the candidate's technical depth, clarity, and authenticity.
5. Persistent Multi-Template Resume Workspace
Provides an interactive resume editor with five typographically calibrated templates:
- Classic
- Modern
- Minimal
- Compact
- Executive
The workspace aims to maintain 100% byte-identical visual parity across browser previews, PDF exports, and DOCX exports.
6. Admin Data Lab and Nebius Fine-Tuning Flywheel
Logs completed interactions, search queries, and graded assessments in real time.
Administrators can inspect platform storage, validate datasets against Nebius Conversational JSONL requirements, preview conversation turns, and export partitioned training datasets in chunks of up to 50 GB.
How We Built It
We designed an edge-first, high-throughput architecture that combines real-time web intelligence with calibrated inference using open-weight models.
1. Real-Time Web Intelligence — Tavily AI
Tavily powers live ATS harvesting and in-depth role discovery through a three-stage pipeline:
- Official career-page discovery: Uses Tavily Search to identify official company career domains.
- Direct HTML and structured-data extraction: Parses raw HTML and embedded
<script type="application/ld+json">data, helping bypass client-side rendering challenges on platforms such as Ashby. - ATS fallback discovery: Uses targeted, quoted-keyword searches to discover listings hosted on non-standard subdomains or pages.
2. Calibrated Inference and Post-Training — Nebius AI
Nebius AI Studio
Powers real-time Career Copilot streaming, structured candidate assessments, and resume fact-checking using high-performance inference infrastructure and models such as MiniMax-M3, DeepSeek-V3, and Llama 3.1.
Nebius Token Factory Pipeline
Captures interaction telemetry in structured conversational formats, including records following the OpenAI/Nebius-style schema:
{
  "messages": [
    {
      "role": "user",
      "content": "Example candidate question"
    },
    {
      "role": "assistant",
      "content": "Example response"
    }
  ]
}
The pipeline includes an automated client-side validator and partitioner designed to split exports into training datasets of up to 50 GB per chunk.
3. Full-Stack Application
Built with the following technologies:
- Framework: TanStack Start v1
- Frontend: React 19
- Build tool: Vite
- Styling: Tailwind CSS v4 design tokens
- Rendering and backend: Server-side rendering (SSR) and edge server functions
The application maintains a consistent visual identity across its interface and document workspace.
4. Storage and Security
Uses PostgreSQL with Drizzle ORM and row-level security (RLS) to enforce multi-tenant data isolation across user resumes and administrative data tables. API keys are encrypted to help protect sensitive credentials.
Challenges We Ran Into
1. Client-Rendered ATS Applications — The Ashby Problem
Modern ATS platforms often render job listings on the client side through React hydration. As a result, conventional scraping and extraction methods can return empty or incomplete page content.
Our solution: We built a dedicated server-side parser that extracts structured JSON-LD schemas directly from raw HTML before falling back to Tavily search.
2. Context-Window Saturation on Massive Job Listings
Companies such as Cursor and Anthropic can host hundreds of open roles simultaneously. Processing these listings generated more than 40,000 characters of context, which initially exceeded request-size limits.
Our solution: We engineered an intelligent context-clamping pipeline that prioritizes and preserves the target role while compressing auxiliary listings.
3. Preventing LLM Sycophancy
LLMs can default to flattering candidates with generic statements such as "You are a great fit!" even when important prerequisites are missing.
Our solution: We implemented strict negative constraints in our Nebius system prompts, requiring the models to identify missing skills, avoid unsupported claims, and provide evidence for their assessments.
4. Validating Massive Fine-Tuning Datasets
Preparing production data for Nebius Token Factory required consistent JSONL formatting and partitioning. Large exports also introduced the risk of browser memory exhaustion.
Our solution: We developed a client-side validation and partitioning workflow designed to process large datasets in manageable chunks while checking conversation-role syntax line by line.
Accomplishments We're Proud Of
1. Moving Beyond Traditional Resume Builders
We didn't build another AI wrapper that generates generic resume bullets. GrinderResume is an evidence-grounded career companion that helps candidates understand their actual strengths, identify missing skills, and prepare for demanding hiring processes.
2. A Grounded, Three-Part Architecture
We connected three complementary capabilities into one coherent interface:
- Tavily: Live web discovery and research.
- Nebius: Calibrated inference using open-weight models.
- Structured workspace: Resume editing, candidate assessments, and data management.
3. Production-Oriented Data Flywheel
User activity can become structured training data from day one. The platform supports exporting conversational datasets for Nebius Token Factory, with automated validation and 50 GB chunk partitioning.
4. High-Precision Career Harvester
Built a harvesting pipeline capable of discovering and collecting 250+ live roles directly from company domains with zero user configuration.
What We Learned
1. Grounded Retrieval Beats Pure Parameter Scale
Combining verified web information from Tavily with real candidate data and open-weight models on Nebius can produce more evidence-based career guidance than relying on ungrounded model responses alone.
2. Testing Candidates Is More Valuable Than Doing the Work for Them
One of the highest-value uses of AI in career preparation is not generating generic cover letters. It is simulating realistic interview scenarios and helping candidates articulate their own knowledge and experience under pressure.
3. Post-Training Readiness Starts With Architecture
Designing application storage around structured conversational data from the beginning makes it easier to transform ordinary product interactions into organized datasets suitable for future model training.
What's Next for GrinderResume?
1. One-Click Nebius Token Factory API Submission
Enable administrators to initiate fine-tuning jobs directly from the Admin Data Lab using a stored Nebius API key, with in-app training metrics, loss curves, and epoch checkpoints.
2. Interactive Mock Interview — Hot Seat
Introduce real-time voice and text simulations in which an AI hiring manager probes candidates on the specific weaknesses identified by the Fit Quiz.
3. Reverse Interview Question Generator
Use Tavily to research company engineering blogs, technical updates, and outage postmortems, helping candidates prepare thoughtful, high-signal questions for their interviewers.
4. Targeted Resume Variant Engine
Generate tailored resume variants by reordering bullet points and adapting technical terminology to specific ATS listings, while strictly preserving verified candidate facts.
Suggested Next Steps
To strengthen the hackathon submission and demo, the following supporting materials can be prepared:
- Short Video Script / Pitch Walkthrough: A 60–90-second script demonstrating the live product and explaining how Tavily and Nebius power its core features.
- Slide Deck Outline / Architecture Diagram: A concise visual explanation of how data flows from Tavily search to Nebius inference and ultimately into Token Factory dataset exports.
Built With
- bun
- fine-tuning
- generative-ai
- lovable
- nebius
- nebius-token-factory
- supabase
- tailwind-css
- tanstack-router
- tavily
- typescript


Log in or sign up for Devpost to join the conversation.