-
-
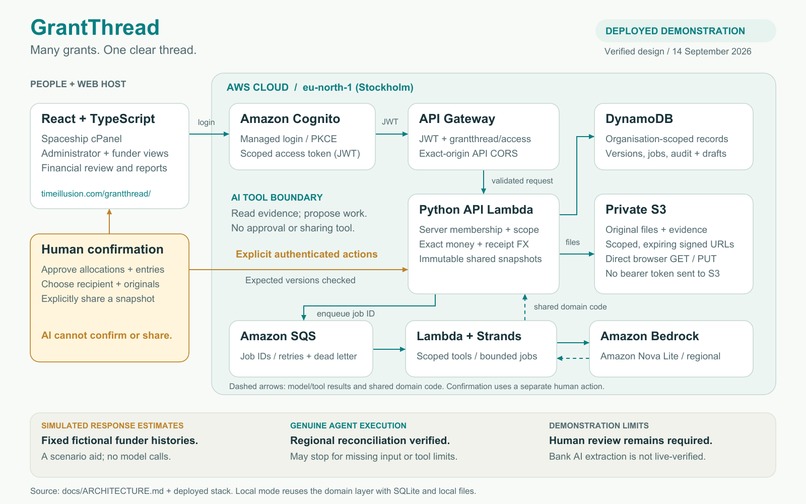
GrantThread architecture: scoped Strands tools on AWS, with human approval for financial changes and sharing.
Inspiration
Grant administrators often explain the same activity to several funders, each with different reporting and evidence requirements. The challenge is keeping the facts consistent while sharing only the right information. GrantThread connects spending, evidence, human decisions and funder conversations in one workspace.
Our primary user is the professional grant administrator. The funder receives a deliberately shared package, while the grantee retains control of its internal working records.
What it does
GrantThread records an expense once and keeps proposed grant allocations separate from confirmed money. Reviewers inspect the original evidence, correct an invalid split and prepare reports from confirmed records. They explicitly select the report version and original attachments a funder receives. A source-linked conversation preserves the question, reply and acknowledgement around that shared package.
The editable demonstration contains three fictional grants. A venue proposal allocates EUR 1,200 against a EUR 1,000 expense, creating a clear decision for the reviewer. Each visitor can create a personal copy, switch between Grantee and Funder views and use Restore demo to return to the starting scenario.
A Strands agent uses Amazon Bedrock to inspect authorised records, check readiness and propose review work. It can identify missing evidence and save an incomplete draft, but cannot confirm financial entries, apply canonical allocations or publish a report. Those actions require authorised human review. Runs can stop for missing input or configured budgets, and service throttling can prevent completion; the interface retains the actual outcome.
Additional tools support reviewed spreadsheet imports, financial workbook exports and currency conversion using entered funding-receipt rates. Bank PDF parsing is deterministic and limited to a supported text layout; general AI bank extraction has not been demonstrated. Response estimates use explicitly simulated funder histories, not live forecasts. All bundled demonstration records are fictional.
How we built it
The frontend uses React and TypeScript, with static assets hosted through Spaceship cPanel. A shared Python domain layer supports local SQLite development and an AWS deployment using Cognito, API Gateway, Lambda, DynamoDB, private S3 and SQS.
Strands Agents orchestrates scoped tools through Amazon Bedrock Nova Lite. Deterministic calculations validate money and allocations; confirmed structured records drive factual report content. Source versions, permission checks and selected-attachment manifests connect a reported figure to the evidence a reviewer is allowed to inspect. AWS SAM defines the cloud infrastructure.
Codex assisted with implementation. The public repository includes an MIT licence and local setup instructions.
Challenges we ran into
An invoice amount, a grant allocation and proof of payment are different facts. Treating them as interchangeable can conceal missing evidence or double-count spending. We kept those records distinct and made confirmation explicit.
Sharing also required a clear boundary between the grantee's working records and a funder's published snapshot. Original attachments are selected deliberately instead of exposing an entire workspace. Imported document text does not grant the agent new authority.
Live model runs exposed another practical challenge: bounded agents do not always finish. We preserve missing-input, budget and throttling outcomes instead of presenting an incomplete run as a successful report.
Accomplishments that we're proud of
We connected expense review, report preparation, selected evidence sharing and a resolved funder conversation in one working hosted application. The personal demo makes both roles testable from one account and supports repeat demonstrations without affecting another visitor's copy.
Recorded verification includes 280 passing local tests and a successful production build, alongside 18 actual browser checks covering sign-in, editing, sharing, original-document download, both roles and Restore. Separate cloud checks exercised isolation and restoration. These results validate the tested workflows; they do not establish production readiness, forecasting accuracy or guaranteed AI completion.
What we learned
The useful agent is one that makes uncertainty actionable. Missing payment proof or an invalid allocation should lead to a specific review task, not a confident-looking report. Exact calculations, source access and explicit human authority are as important as the model's reasoning.
We also learned to keep different kinds of evidence separate: local tests, browser behavior and real model execution each answer a different question. No administrator time-saving study has yet been completed.
What's next for GrantThread
Test with grant administrators and funder reviewers, measure repeated entry and review effort, improve agent completion within clear limits, and broaden supported document formats. Complete end-to-end signup email verification and strengthen account-wide operating controls before expanding beyond a small demonstration. Direct bank feeds, payments, automatic compliance decisions and spendable-cash forecasting remain outside the current demo.
Try it
Use Create demo account to create a GrantThread email/password account and your own fictional copy; no AWS account is required. Switch between Grantee and Funder to try both sides, and Restore demo to repeat. Real signup email delivery remains to be verified independently; local setup is available in the repository. Use fictional uploads only. AI results may stop for missing input, configured limits or service throttling.
Built With
- amazon-bedrock
- aws-lambda
- python
- react
- strands-agents
- typescript

Log in or sign up for Devpost to join the conversation.