-
-
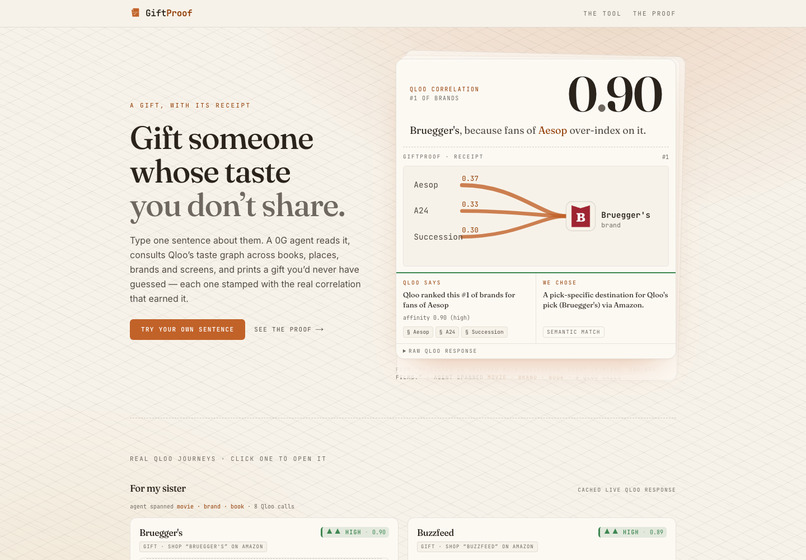
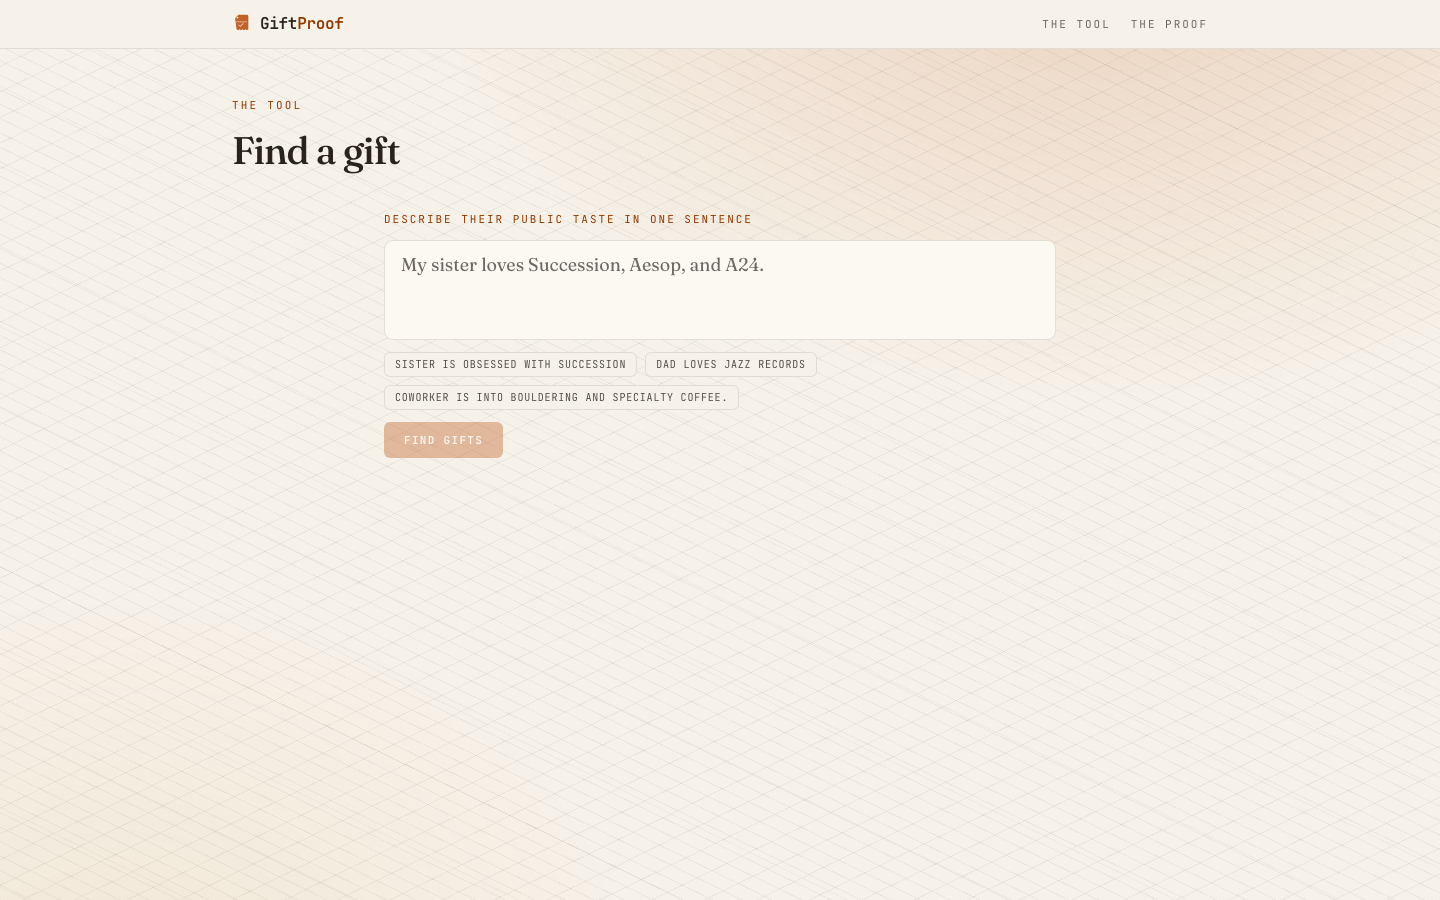
Landing page
-
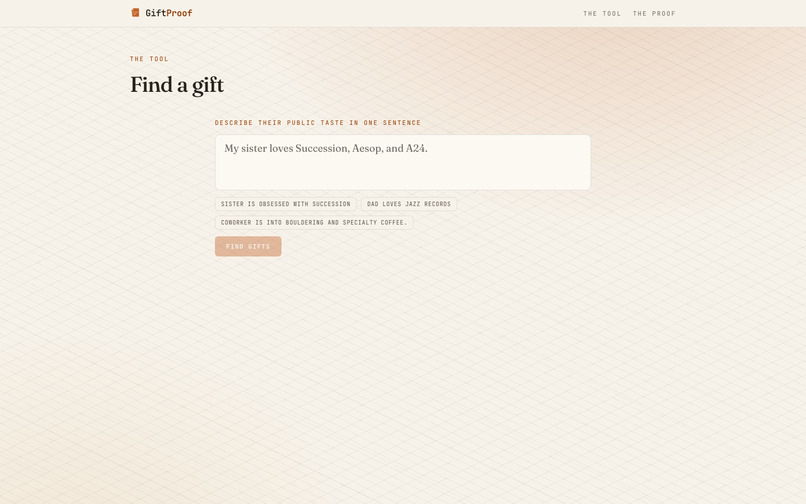
App page. Input details about your loved one, and watch qloo perform its magic
-
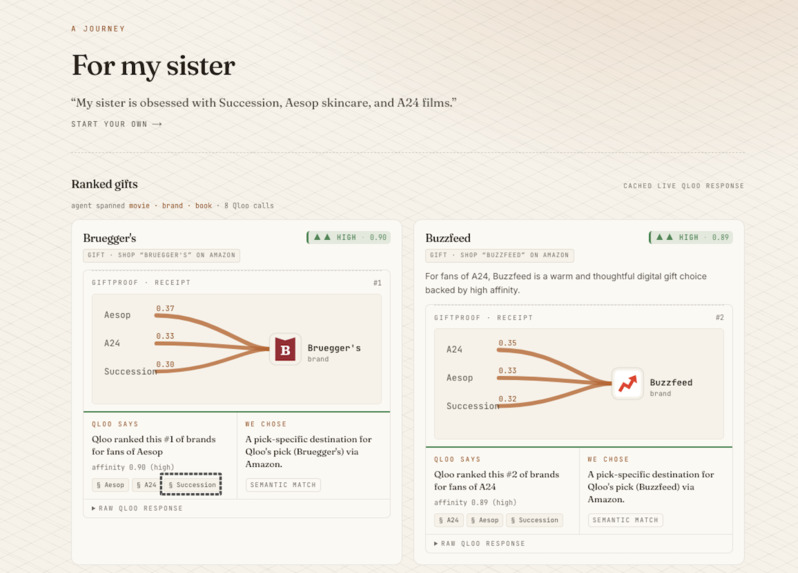
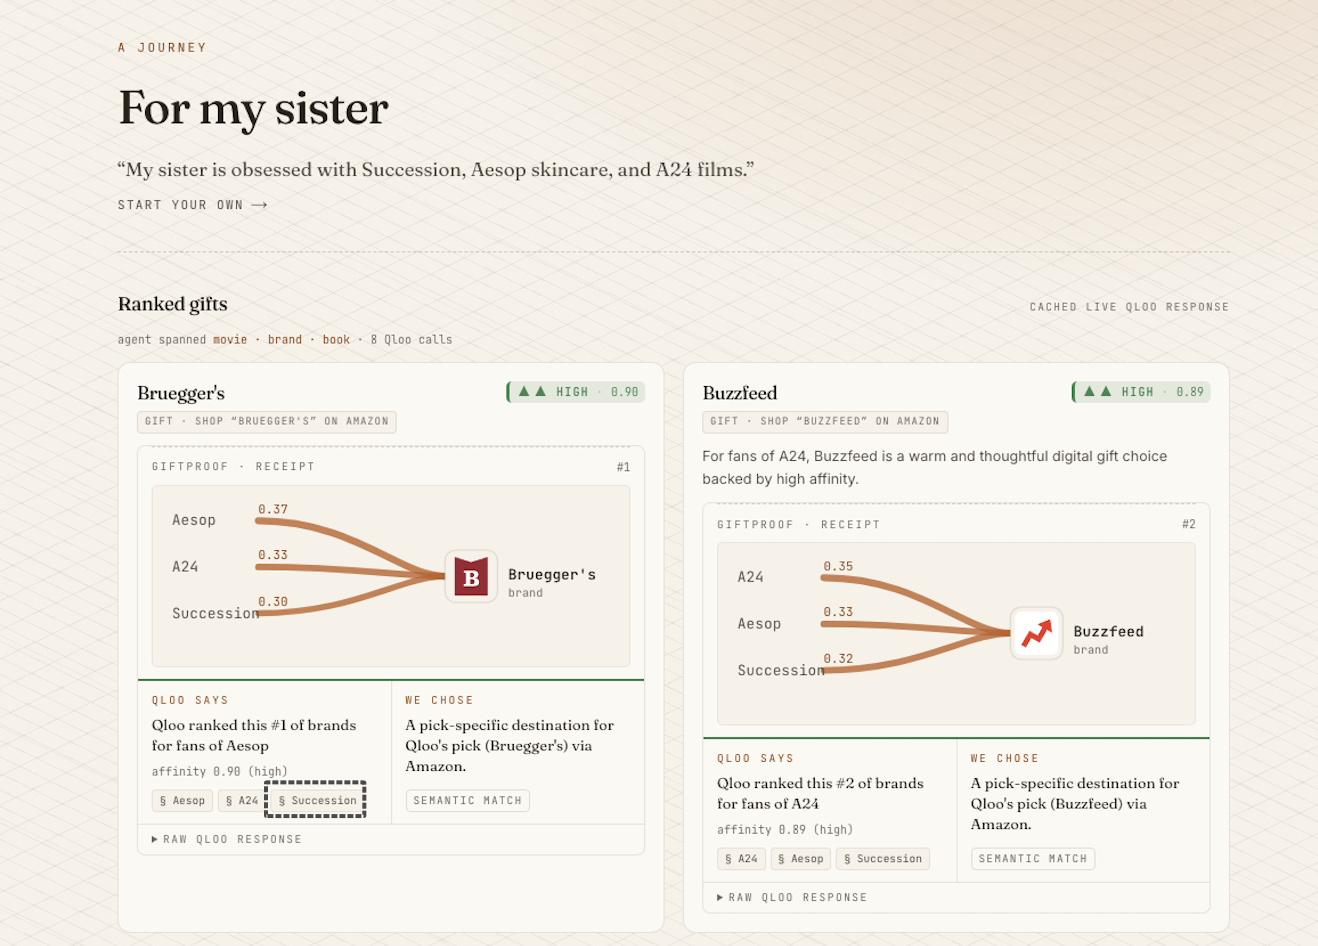
Result. A list of findings qloo generates, with the links to each of the products and how to get them.
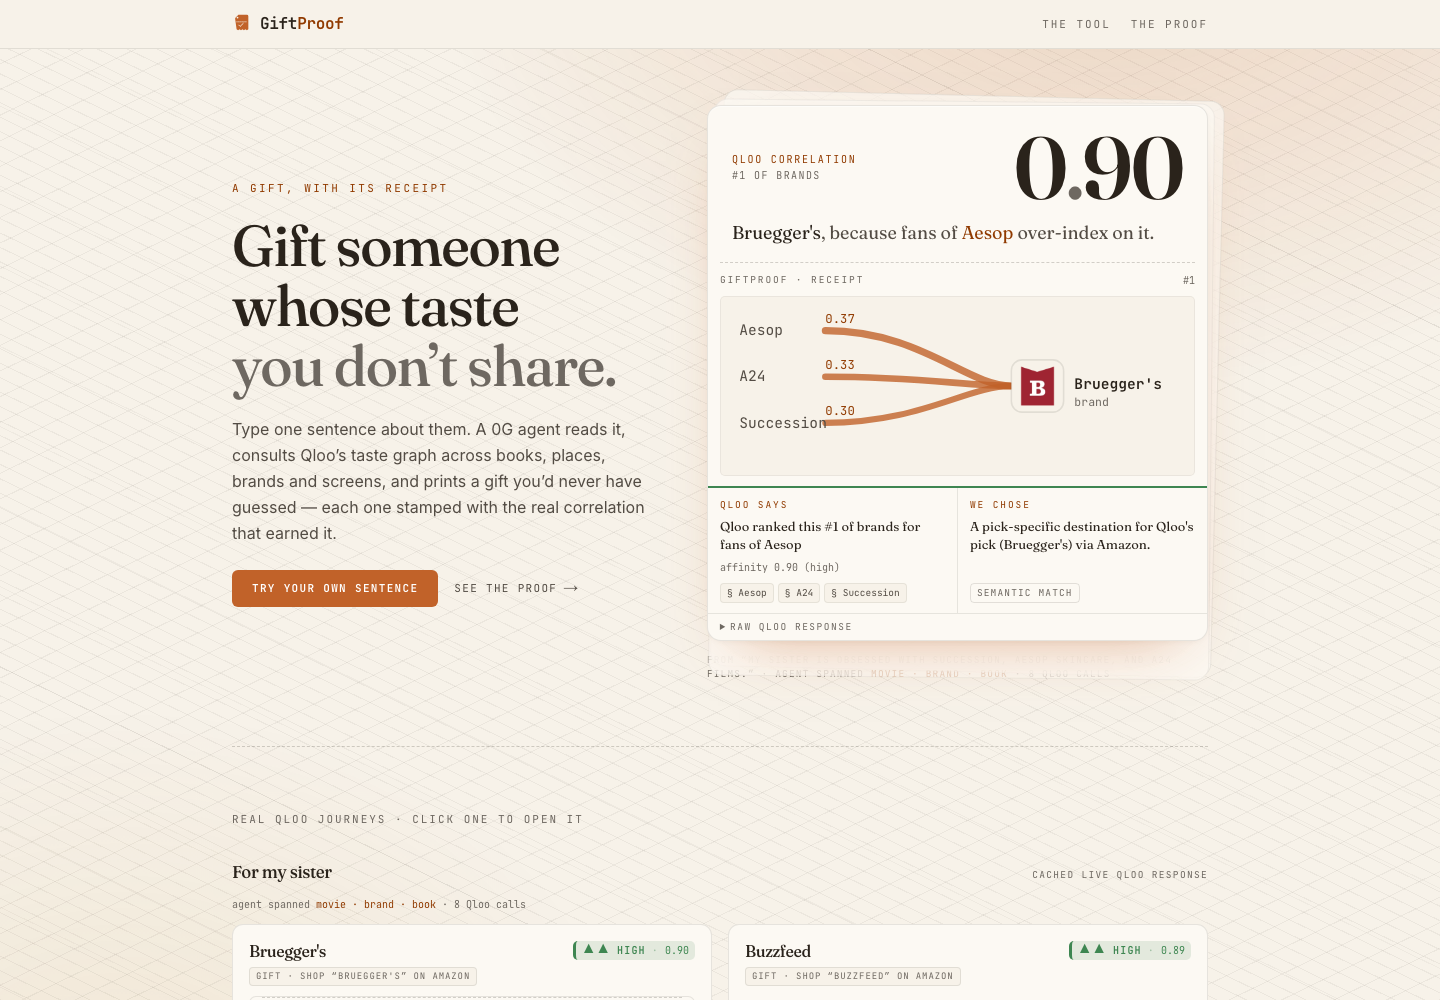
Inspiration
Buying a gift for someone whose taste you do not share (a parent, an in-law, a new partner) is a near universal, recurring problem. Keyword search and a generic chatbot both collapse to the giver's taste bubble or a safe cliche. We wanted an agent that reads only public taste, lets a real behavioral graph do the bridging across categories, and then proves every choice instead of asking you to trust it.
What it does
You type one sentence about someone, for example "my sister is obsessed with Succession, Aesop skincare, and A24 films." A Compute agent reads it, extracts the tastes, and chooses 2 to 4 giftable domains to target. Qloo's taste graph then ranks real gifts by cross domain affinity, and every pick arrives with a live receipt that shows which taste drove it and how strongly. Remove or add a taste chip and the whole grid re prints live.
What makes it Qloo powered
Qloo's own kill test is: "if your submission would work the same without Qloo, you are building the wrong thing." Delete the Qloo call and GiftProof returns nothing:
- A chatbot can guess "buy her an A24 tote." It cannot know that fans of Aesop, A24, and Succession over index on a specific brand. That correlation lives in Qloo's 250M plus entity graph, not in language.
- Every number on screen is a real Qloo field: affinity, explainability score, rank position. Nothing is fabricated.
- The language model never ranks. It extracts and narrates only. Qloo's numbers decide the order.
Five Qloo surfaces are load bearing and zero are decorative: /v2/insights cross domain ranking and feature.explainability (the core), /search and /v2/tags for resolution, and demographic signals.
How we built it
- Extract: the 0G agent pulls tastes plus 2 to 4 giftable domains from the sentence. It never ranks.
- Resolve: each taste maps to a real Qloo entity ID via
/searchor a tag via/v2/tags. No PII is sent to Qloo. - Rank cross domain:
/v2/insightsfans out across domains in parallel, ordered by Qloo's real affinity. - Refine (gated): a weak first ranking adds a tag signal and re queries once; sharp results skip it.
- Resolve to a gift: each pick maps to a buyable destination, keeping Qloo the chooser.
- Prove it: a "Qloo says / we chose" receipt is built from real explainability contributors and recomputes on every swap.
The reference journey makes 8 Qloo calls and returns 12 cross domain picks across 3 agent chosen domains, all with real contributors. Every headline number is recomputable by npm run verify-claims (it refuses read back).
Challenges we ran into
Reading Qloo's real explainability shape (it lives under query.explainability keyed by the input taste), staying quota frugal on the hackathon key (semaphore, LRU cache, debounce, stale cache on 429), and keeping the agent honest so the LLM never re ranks or fabricates.
Accomplishments that we are proud of
The receipt is a real instrument built from live Qloo data, every cited number is verifiable, and 5 of 5 Qloo surfaces are load bearing.
What we learned
Cross domain taste is a different capability from search or language. The hard work was making the correlation legible and provable so a giver trusts a surprising suggestion.
What's next
A deeper gift catalog with per domain deep links, richer demographic and geo signals, and saved shareable journeys.
Built With
- 0g-compute
- agent
- llm
- next.js
- qloo
- qloo-taste-api
- react
- tailwindcss
- typescript
- vercel
- zod


Log in or sign up for Devpost to join the conversation.