-
-
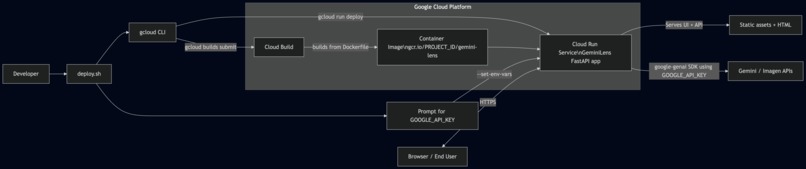
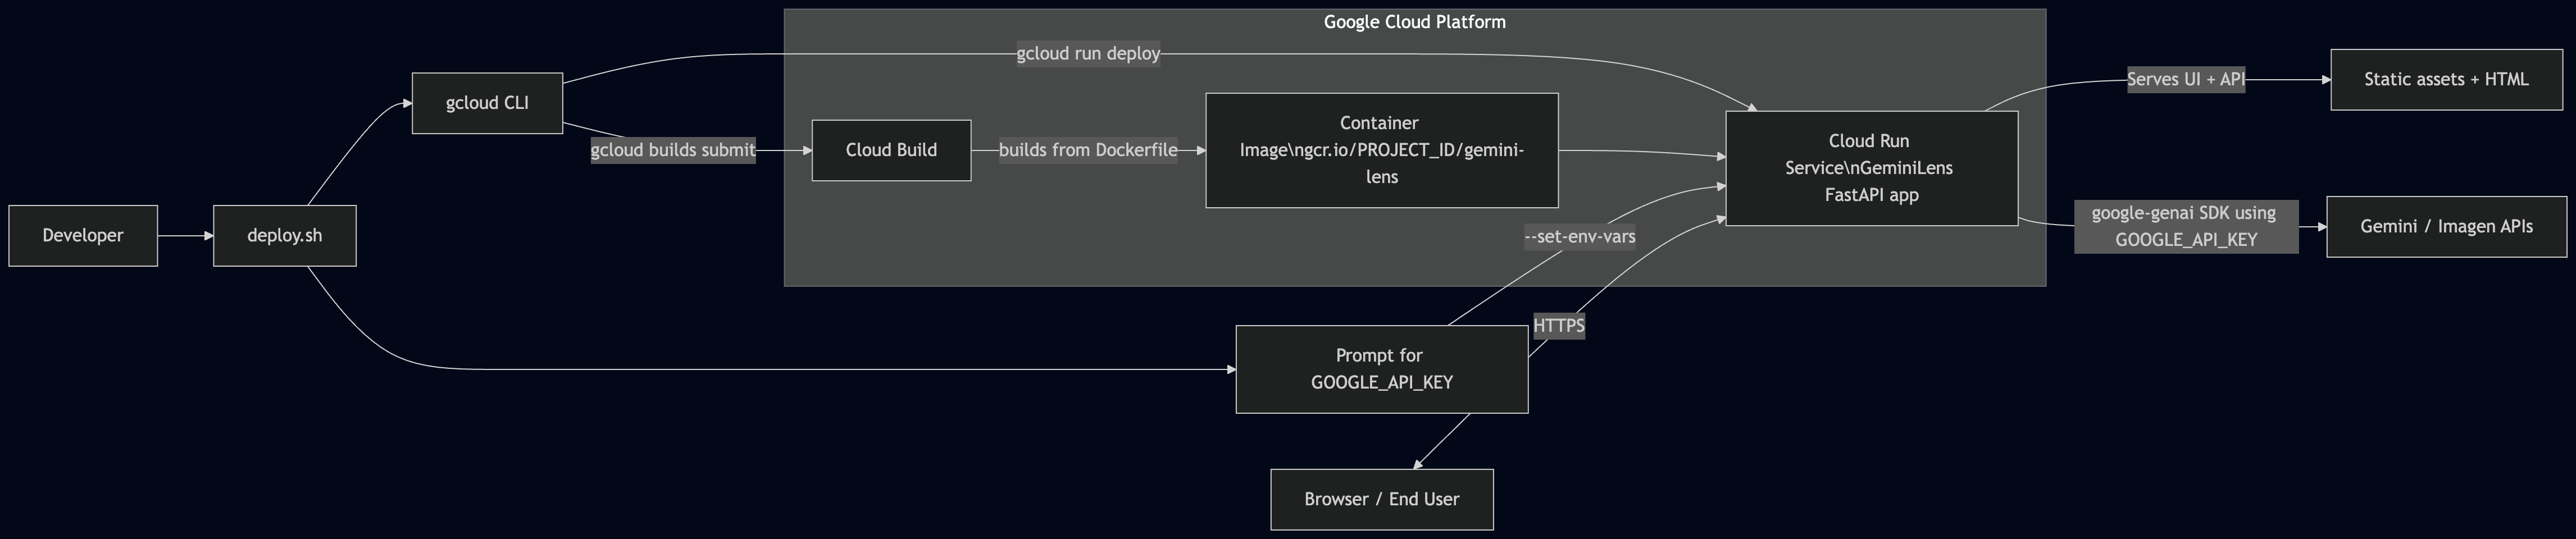
architecture diagram
Inspiration
We've all been there: staring at a dense wall of text in a textbook, wishing for a simpler, more visual way to grasp a complex topic. Static learning materials often fail to engage or adapt to a learner's needs. This frustration was the inspiration for GeminiLens. I wanted to build more than just a chatbot; I envisioned an adaptive AI academic mentor that could understand how to teach.
What it does
It would be like having a personal tutor who knows exactly when to switch from talking to drawing on a whiteboard or even showing a short video to make a concept click.
How we built it
GeminiLens is a multi-modal educational application built on a modern Python stack and deployed entirely on Google Cloud. The Core "Brain" - Gemini & Function Calling The heart of the application is a FastAPI backend powered by the google-genai Python SDK. The magic lies in combining the reasoning power of the Gemini model with Function Calling. I didn't just ask the model to answer questions; I gave it "tools" it could decide to use on its own.
Challenges we ran into
• Prompt Engineering: Crafting the perfect system_instruction was an iterative process. It was challenging to make the model reliably use its tools and format its final output correctly (like extracting the suggested follow-up questions) every time. • Handling Asynchronous Operations: Video generation with Veo isn't instantaneous. I had to implement a polling mechanism where the frontend requests a video, receives an operation_id, and then periodically checks a status endpoint (/api/video_status/{id}) until the video is ready to be displayed. • State Management: For a hackathon project, I used simple in-memory Python dictionaries to store the state of generated presentations and video operations. While this is fast and simple for a demo, a production-ready version would require a more robust solution like Firestore or Redis to persist state across service restarts or scaling events.
Accomplishments that we're proud of
I've combined several models to make multimodal output, and also It was pretty easy deployed to GCP.
What we learned
Building GeminiLens was a fantastic deep dive into the practical application of multi-modal AI. I learned that the true power of modern LLMs is unlocked when you combine their reasoning capabilities with the ability to take action via function calling. Furthermore, leveraging Google Cloud's serverless offerings like Cloud Run and Cloud Build made it incredibly fast to go from a local prototype to a globally accessible, scalable web application.
What's next for GeminiLens
Enhance prompts, adjust UI and UX, take a feedback from users.

Log in or sign up for Devpost to join the conversation.