-
-
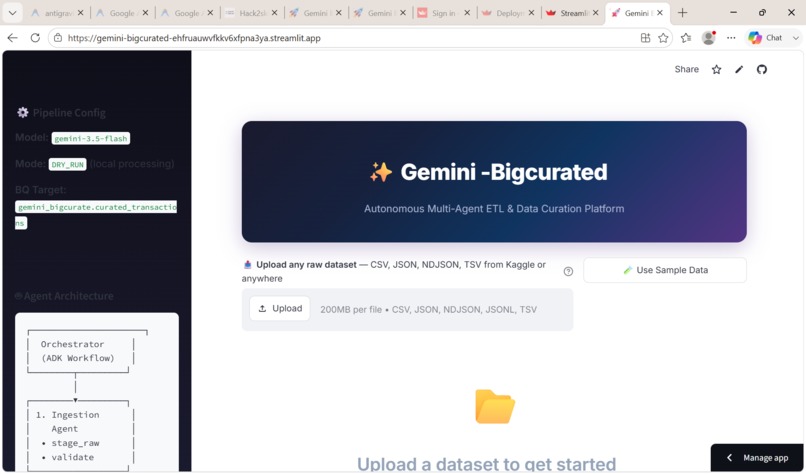
Gemini Bigcurated Multiagentic system
Inspiration Data engineering teams spend up to 80% of their time on the grueling, manual friction of ETL (Extract, Transform, Load) pipelines. Wrestling with dirty datasets, fixing broken encodings, inferring brittle schemas, and debugging failed data warehouse loads is a soul-crushing chore. We were inspired to build a system that completely eliminates this friction. We didn't just want a better script; we wanted an autonomous "data engineering team" that could handle the mess without human intervention.
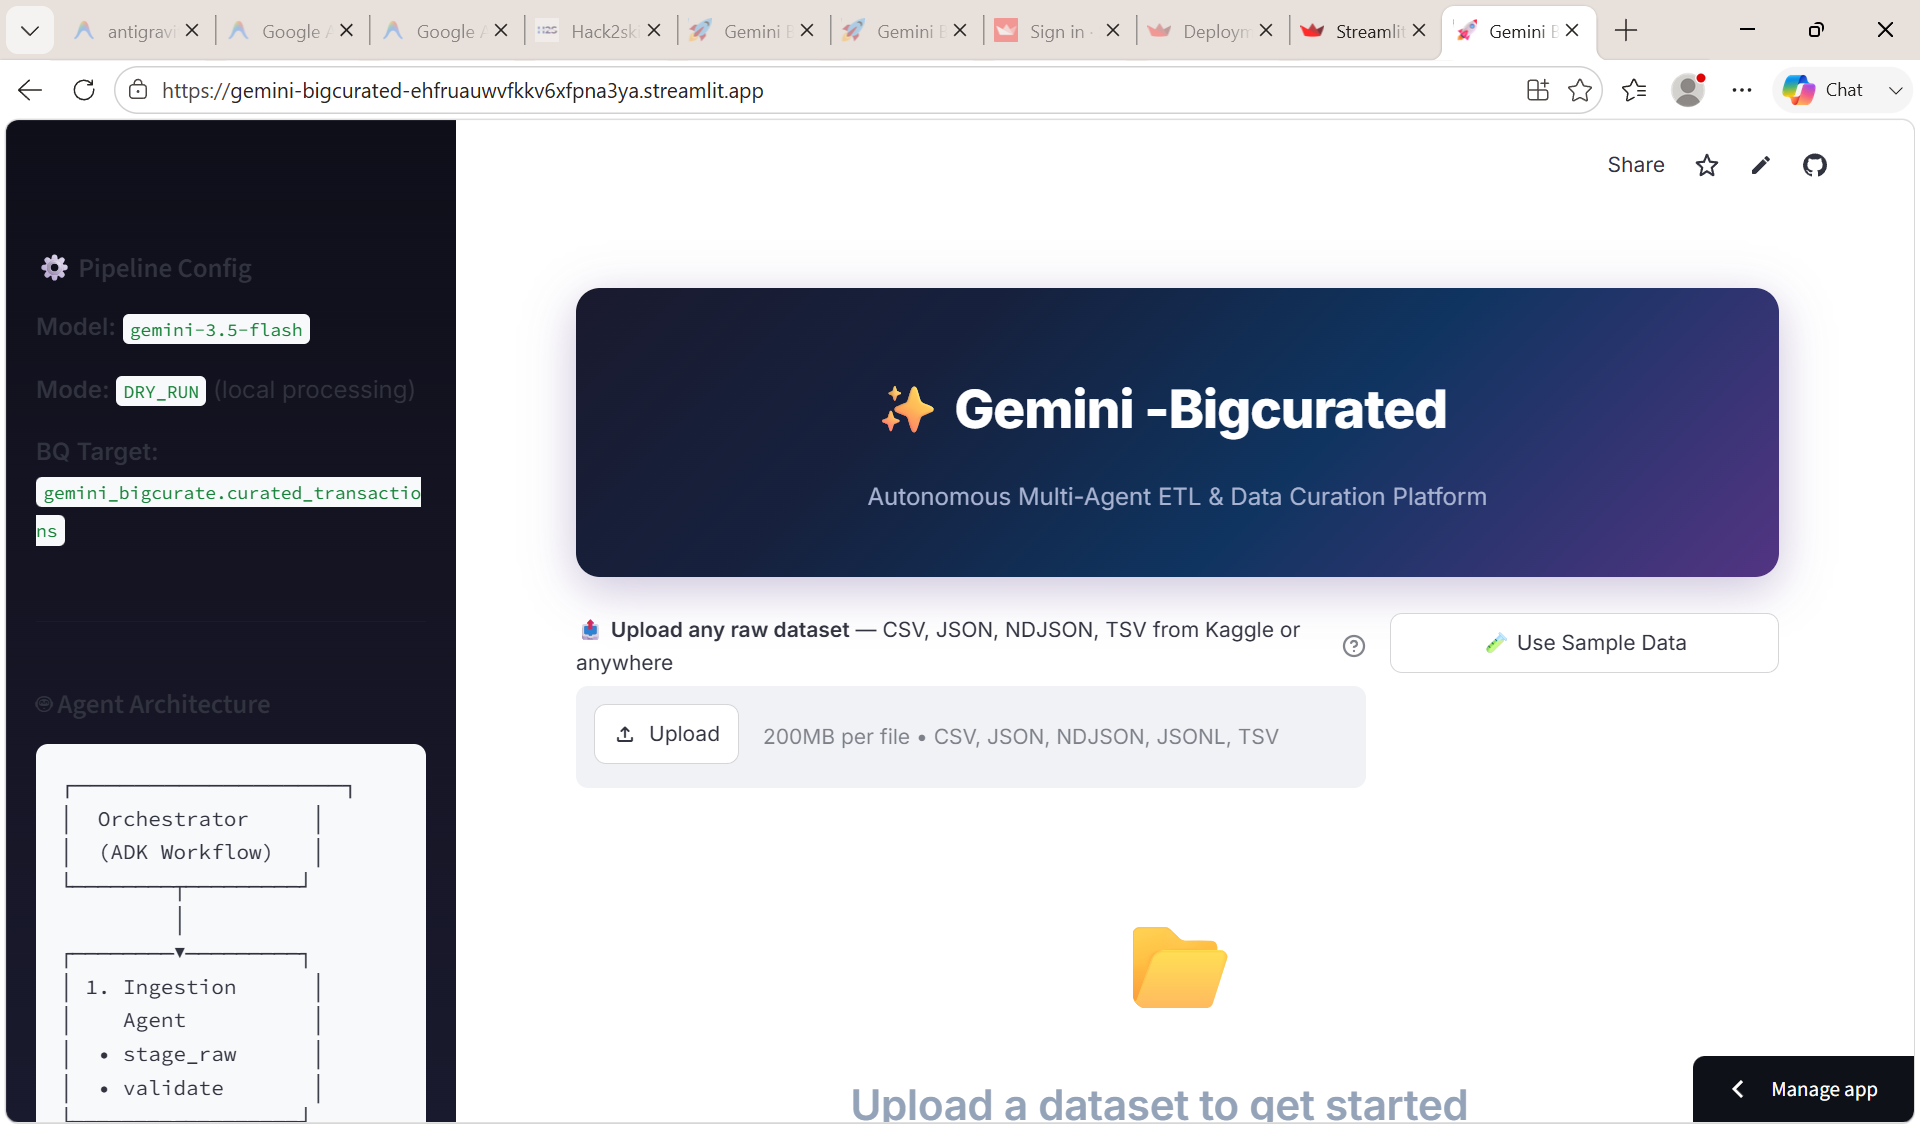
What it does Gemini-BigCurated is an enterprise-grade, autonomous multi-agent data orchestration platform. It completely automates the ingestion, cleansing, and loading of raw data into Google BigQuery.
You simply point the system at a raw dataset (CSV, JSON, TSV, etc.), and our Orchestrator Agent takes over. It autonomously delegates the workflow to three specialized worker agents:
Data Ingestion Agent: Stages the payload, validates MIME types, detects encodings, and performs SHA-256 cryptographic integrity checks. Transformation Agent: Leverages Polars to run lightning-fast data cleansing—healing nulls, isolating toxic records, deduplicating rows, and writing optimized Parquet files while auto-generating strict BigQuery schema contracts. BigQuery Loading Agent: Dynamically provisions partitioned tables in Google Cloud, executes the batch load job, and runs a 6-point SQL data quality audit to guarantee success. How we built it We built the system using a decoupled, multi-agent architecture powered by Gemini 1.5.
Core Logic: Python, utilizing a strict agentic workflow pattern where agents pass structured state (via JSON contracts) to one another. Data Processing: We chose Polars over Pandas to guarantee blazingly fast, memory-efficient data transformation on large datasets. Infrastructure: Integrated deeply with Google Cloud Storage (GCS) for staging and Google BigQuery for final data warehousing. User Interface: We designed a sleek, glass-morphism enterprise dashboard using Streamlit, giving users real-time visibility into the agents' decision-making and pipeline metrics. Challenges we ran into One of the biggest challenges in autonomous ETL is schema inference. When an agent encounters dirty data, dynamically predicting a strict BigQuery schema without throwing type-casting errors is incredibly difficult. We solved this by forcing our Transformation Agent to map robust Polars dtypes into BigQuery-compliant schemas before generating the final Parquet file, ensuring the BQ Loader Agent never fails on a schema mismatch.
Additionally, testing cloud infrastructure autonomously can get expensive quickly. We overcame this by architecting a secure DRY_RUN mode that simulates the entire pipeline using local temporary Parquet files and mock BigQuery audits, allowing for rapid iterations with zero cloud cost.
Accomplishments that we're proud of True Zero-Touch Autonomy: We successfully built a system that requires absolutely zero human "hand-holding" once the data is submitted. Production-Ready Engineering: The system doesn't just work on happy paths; it proactively isolates toxic rows and guarantees data integrity via SHA-256 checksums. Exceptional UI/UX: We wrapped complex multi-agent interactions in a beautiful, enterprise-ready dashboard that makes monitoring the pipeline a joy rather than a chore. What we learned We learned that in agentic architectures, specialization beats monoliths. By breaking the pipeline down into decoupled, distinct agents (Ingestion, Transformation, Loading) rather than relying on one massive LLM prompt, the system became exponentially more reliable, easier to debug, and infinitely scalable.
What's next for Gemini-BigCurated We plan to expand the platform from an automated ETL tool into a complete AI Data Platform. Our roadmap includes:
Real-time Streaming: Extending the Ingestion Agent to handle live Kafka and Pub/Sub streams. Auto-Visualization: Building a fourth "BI Agent" that automatically generates Looker dashboards based on the newly loaded BigQuery tables. Slack/Teams Integration: Allowing data engineers to simply drop a messy CSV into a Slack channel and have the agents reply 10 seconds later with the queried BigQuery results.

Log in or sign up for Devpost to join the conversation.