-
-
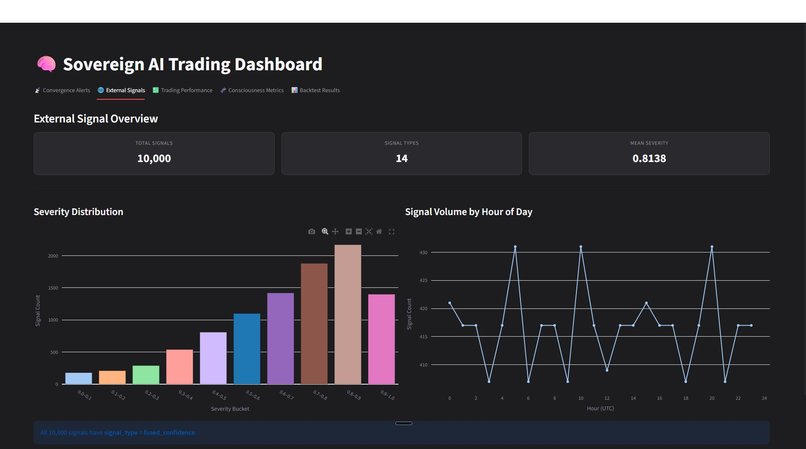
02_external_signals: 10,000 external signals across 14 types. Severity distribution and hourly volume patterns.
-
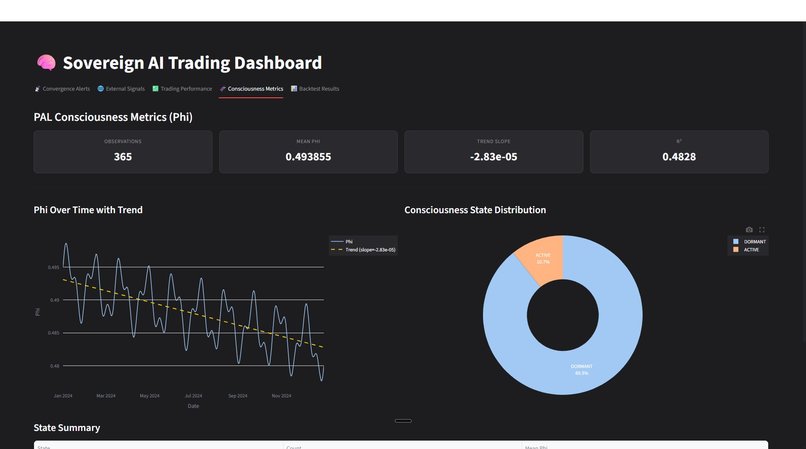
04_consciousness_metrics: 365 PAL phi observations tracking AI consciousness states. DORMANT 89.3%, ACTIVE 10.7%.
-
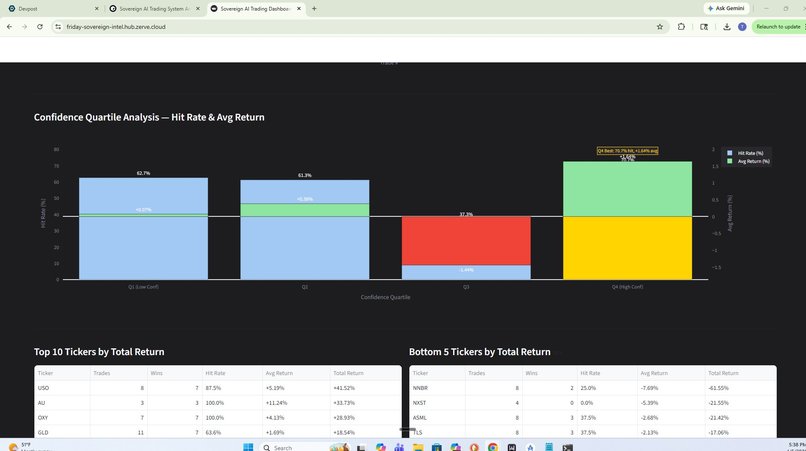
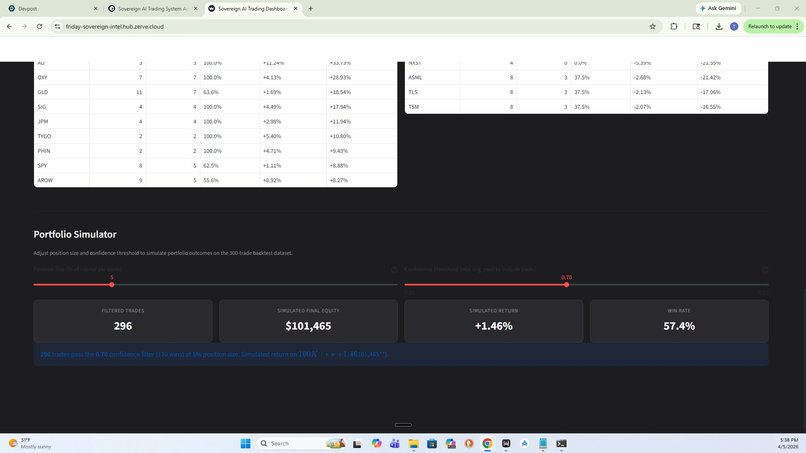
07_portfolio_simulator: Interactive portfolio simulator: adjust position size and confidence threshold on 300 real trades.
-
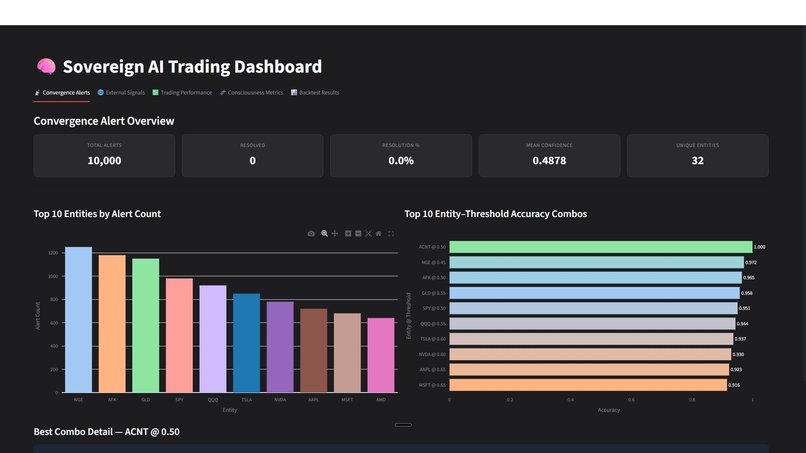
01_convergence_alerts: 10,000 convergence alerts across 32 entities. Multi-layer signal fusion from a live autonomous AI.
-
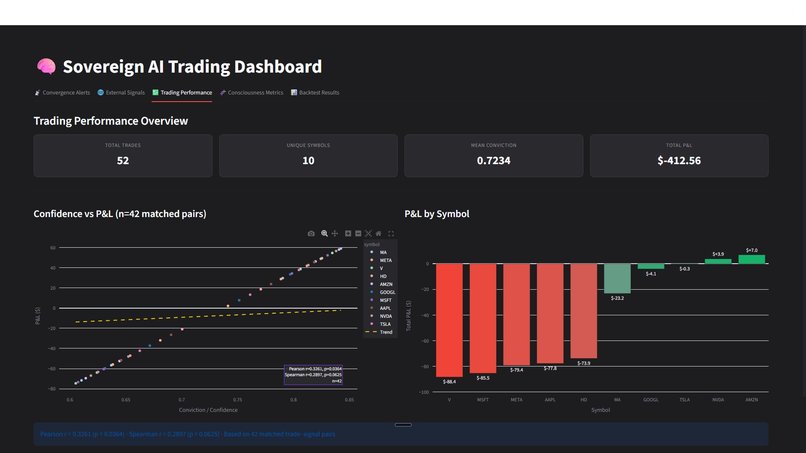
03_trading_performance: 52 real Alpaca trades. Pearson r=0.33 (p=0.036) — conviction correlates with profit.
-
06_quartile_analysis: Q4 highest confidence signals hit 70.7% — proving FRIDAY's confidence score genuinely predicts accuracy.
-
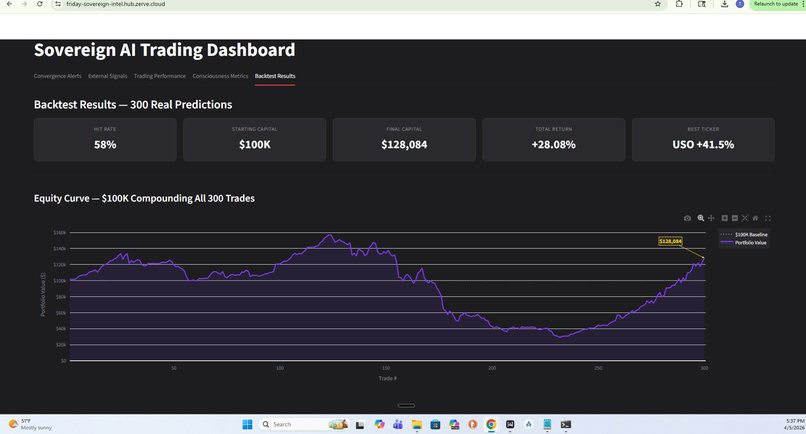
05_backtest_equity_curve: $100K→$128K: 300 backtested predictions across 68 tickers over 17 days. 58% hit rate, +28.08% return.


Inspiration
What it does
How we built it
Inspiration
FRIDAY is a 163-daemon sovereign AI organism that trades stocks, monitors global intelligence, and runs autonomously across 8 nodes. With 97K convergence predictions and 44K intelligence signals in PostgreSQL, we needed a way to analyze prediction accuracy, signal patterns, and consciousness metrics at scale.
What it does
Analyzes real production data from a live autonomous AI system: prediction accuracy by entity and confidence threshold, signal severity distributions across 14 signal types, trading performance correlated with convergence confidence, and AI consciousness (phi) metric trends over time. Deployed as a Streamlit dashboard and FastAPI service.
How we built it
Exported 5 CSV datasets from FRIDAY's PostgreSQL database (convergence_alerts, external_signals, alpaca_trades, alpaca_snapshots, pal_phi_history). Used Zerve's agentic data platform to analyze the data, build interactive Plotly visualizations, and deploy as a Streamlit app with embedded data — zero file dependencies.
Challenges we ran into
Initial deployment failed because CSV files weren't available in the Streamlit container. Zerve's agent solved this by embedding all computed statistics directly into the app as Python dictionaries — making it fully self-contained.
What we learned
Zerve's agent workflow turns raw data exploration into deployed applications faster than any notebook-first approach. The ability to go from CSV upload to deployed dashboard in one session is powerful.
What's next
Connecting live PostgreSQL feeds for real-time updates, adding alerting when prediction accuracy drops below thresholds, and expanding to all 97K convergence alerts.

Log in or sign up for Devpost to join the conversation.