-
-
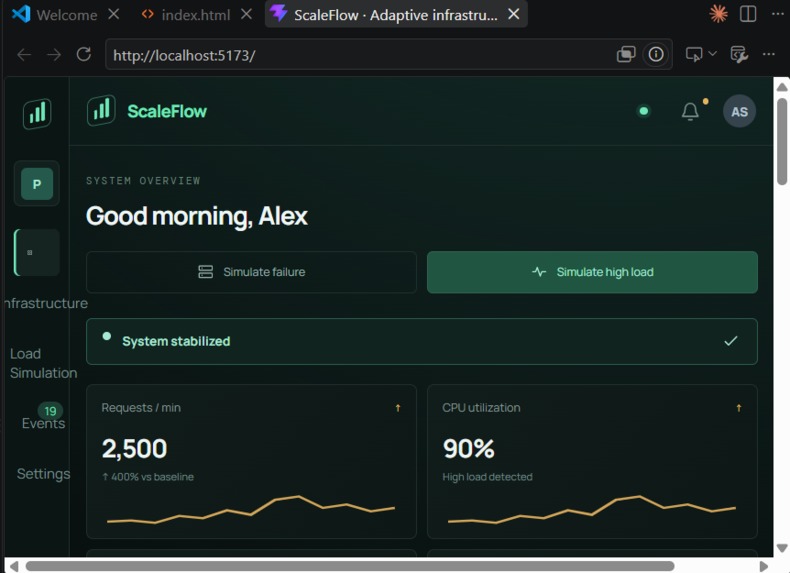
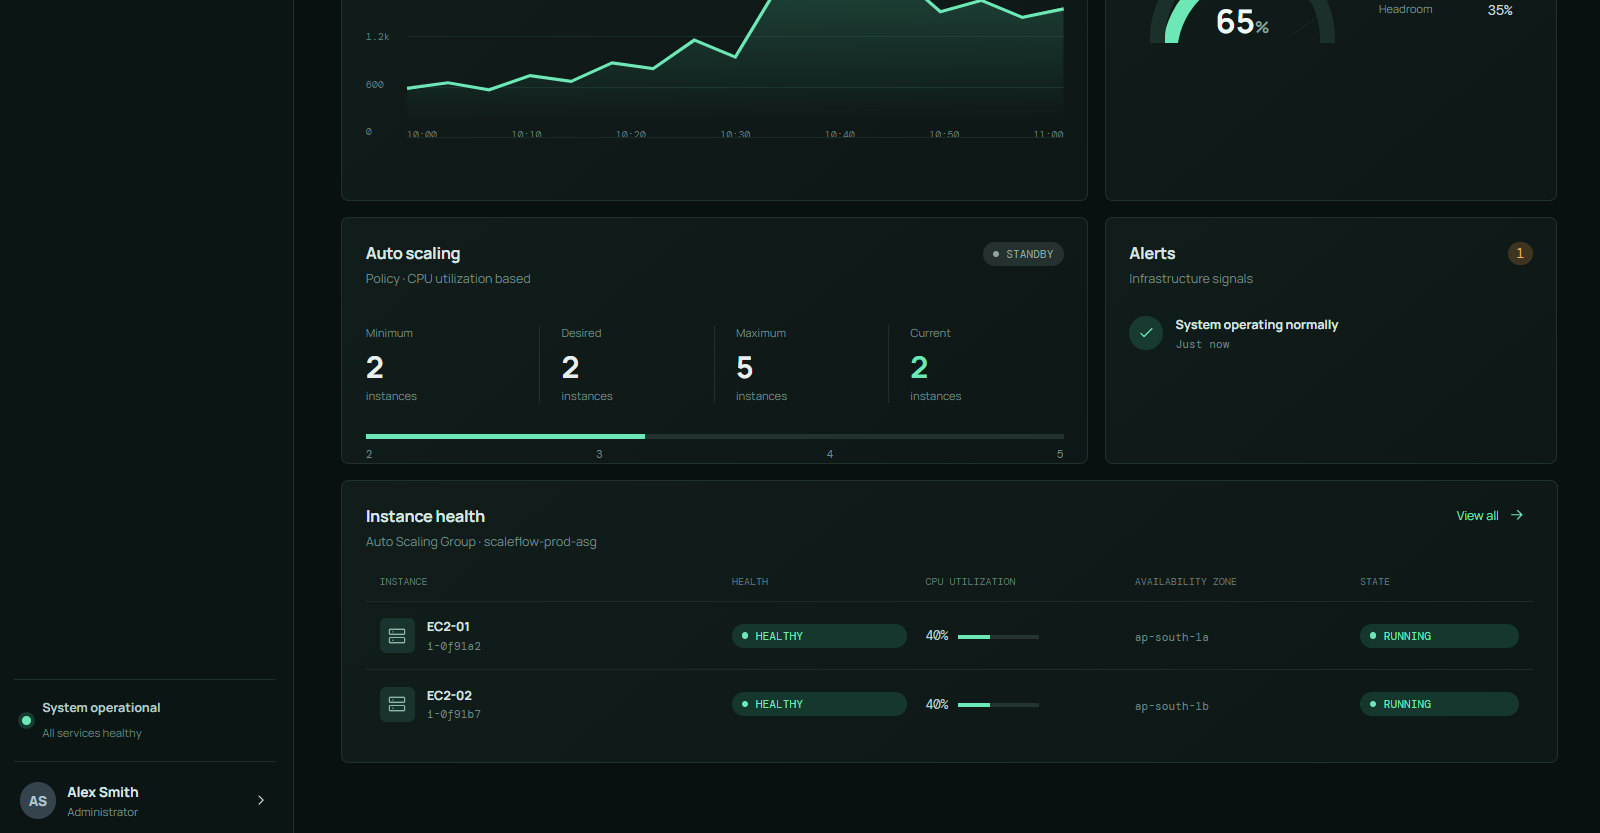
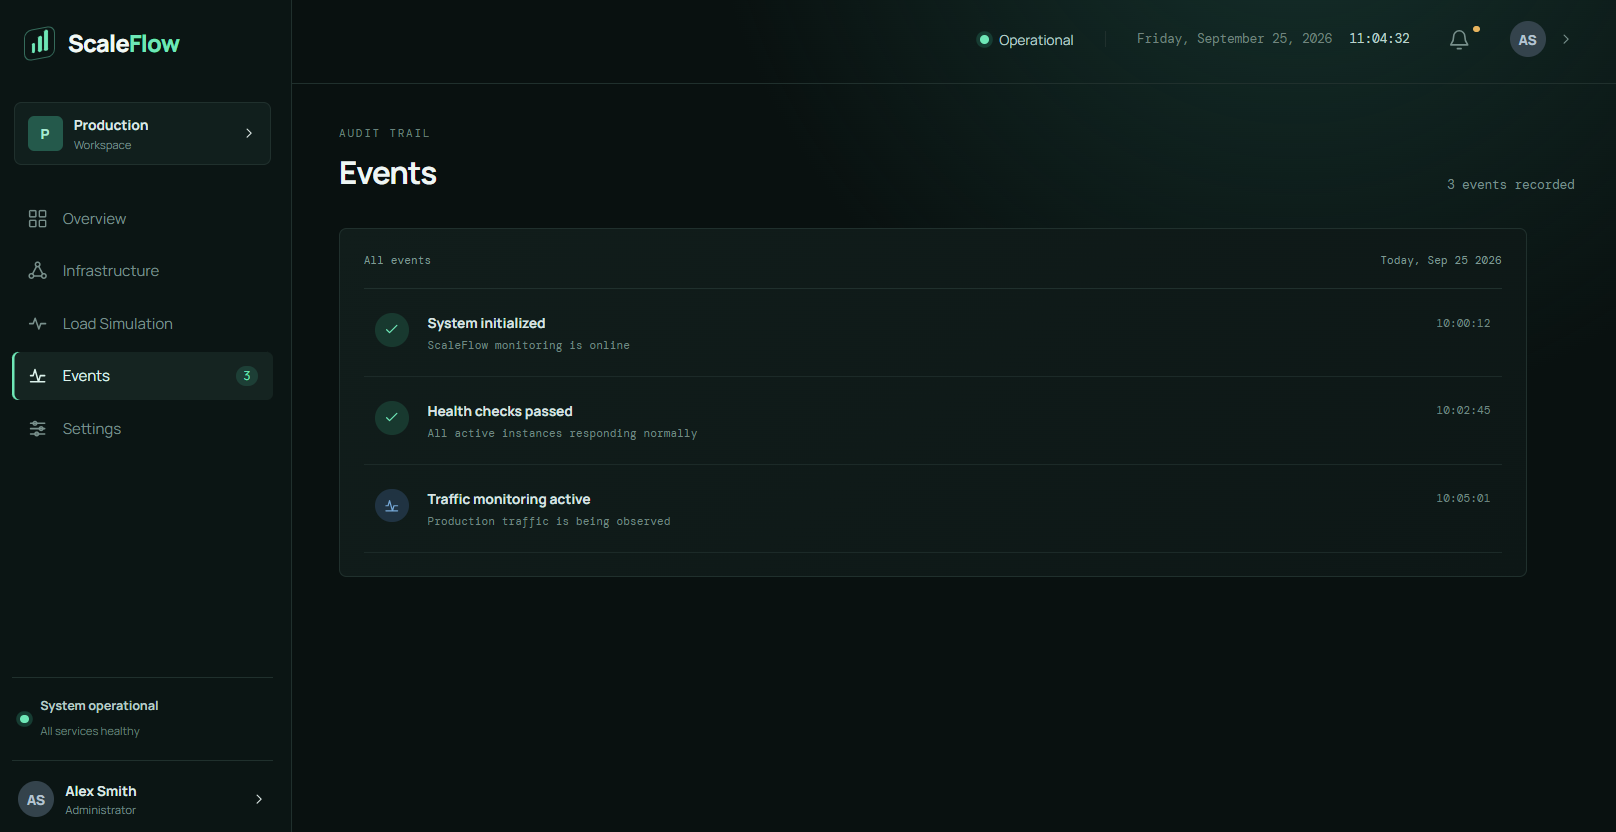
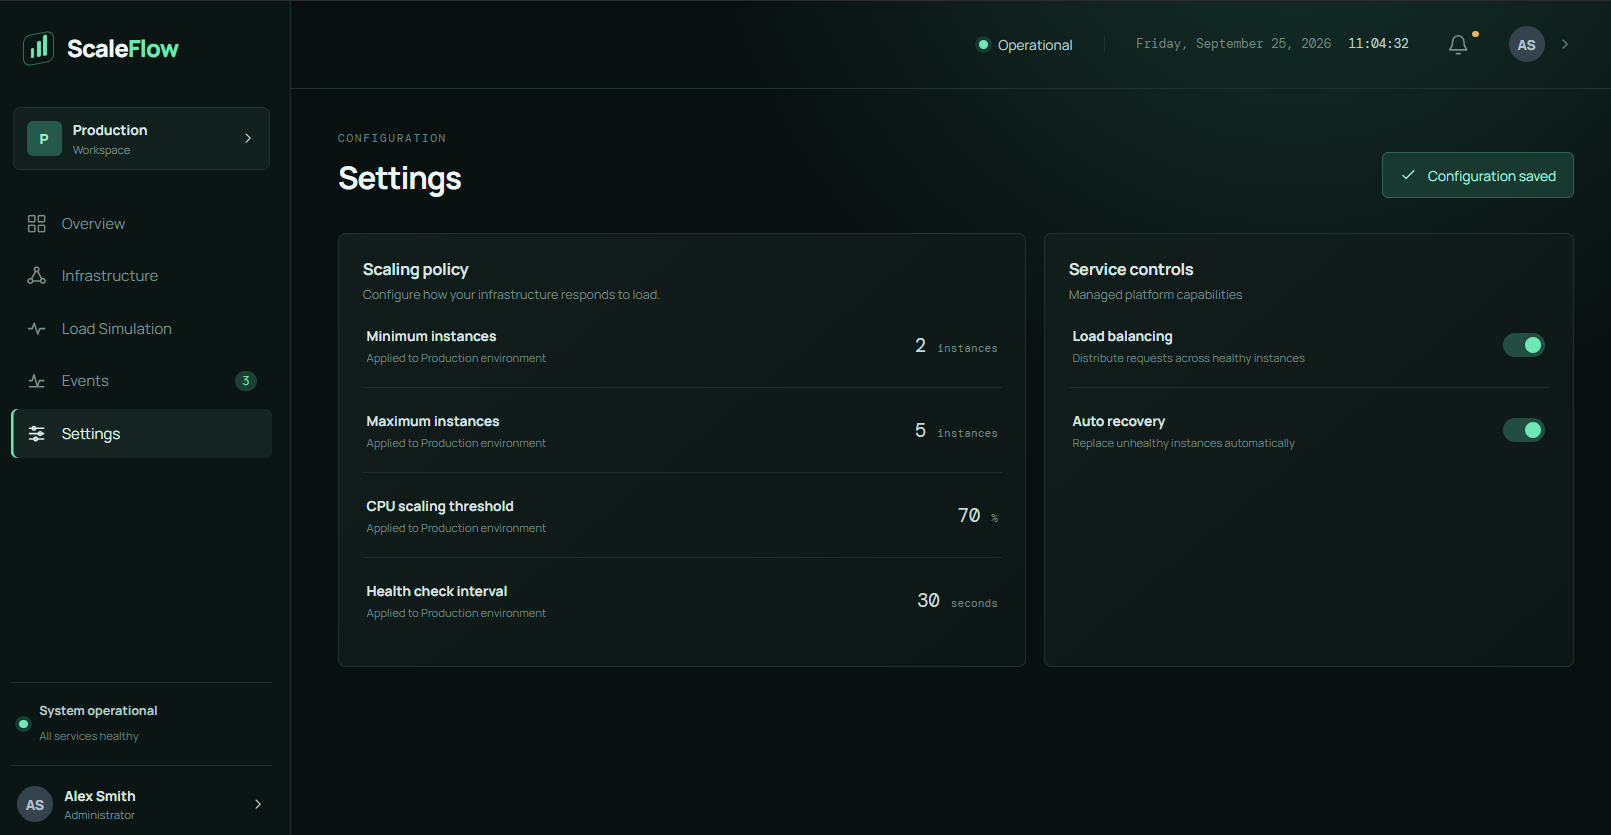
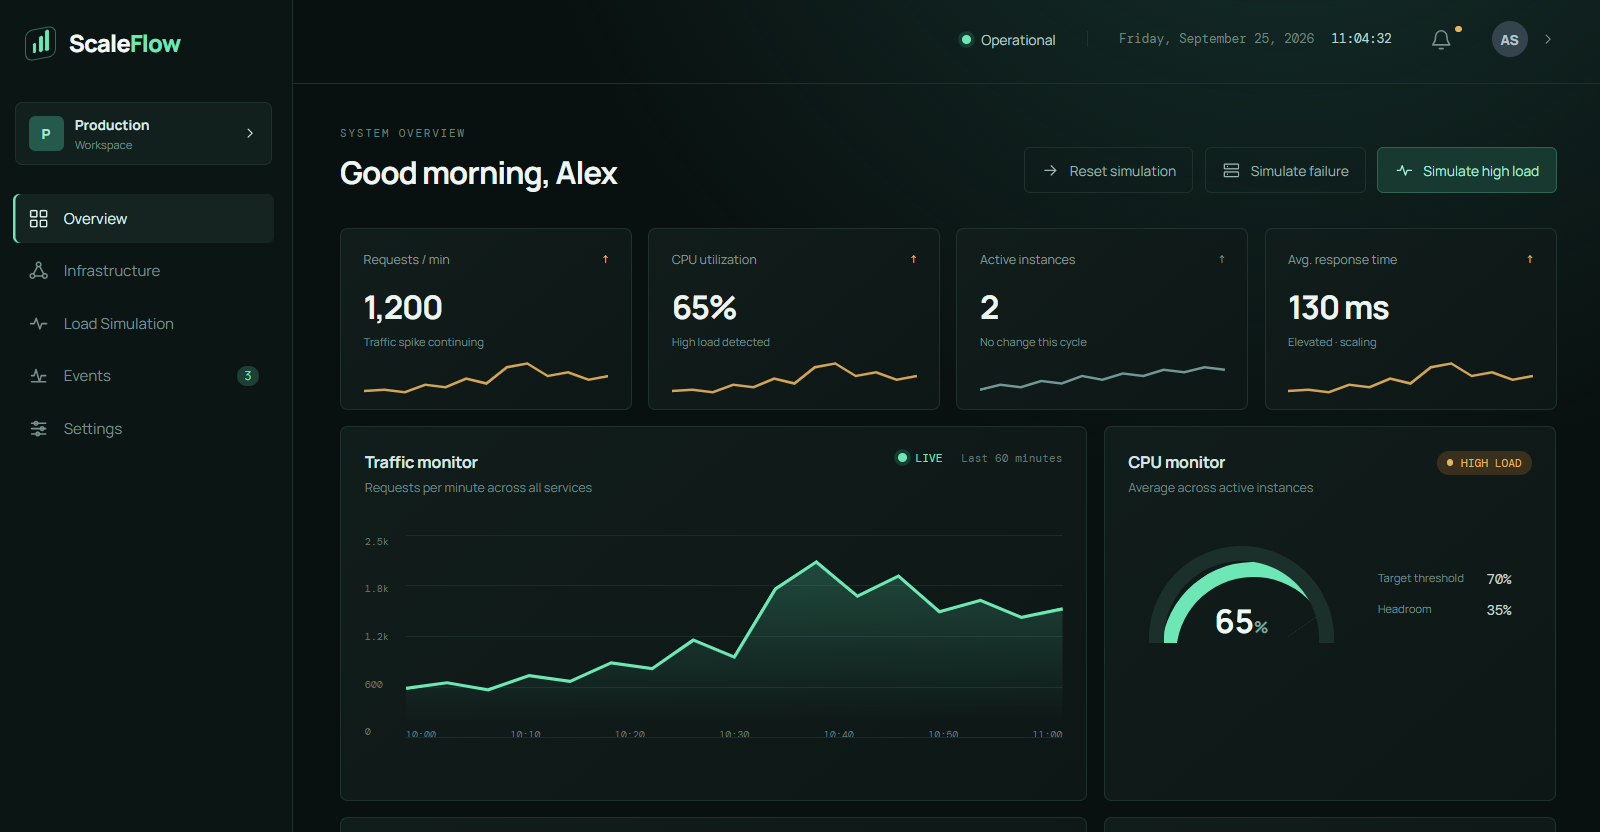
dashboard of our scaleFlow
-
-
-
-
-
-
Inspiration
Modern web applications can experience sudden and unpredictable traffic spikes. The real-time issue which we students usually face include college result portals during result announcements, registration systems when applications open, and online platforms during limited-time events. A system that works normally under low traffic can suddenly experience high CPU utilization, increased response times or service disruption when demand increases.
At the same time, keeping a large number of servers running continuously is inefficient because most of that capacity may remain unused during normal traffic.
We need a system in which cloud infrastructure can respond dynamically to these changing workloads instead of relying on manual intervention.
What it does
Our scaleFlow is a cloud-native infrastructure monitoring and scaling platform designed to demonstrate how applications can remain responsive during traffic spikes and recover from infrastructure failures.
How we built it
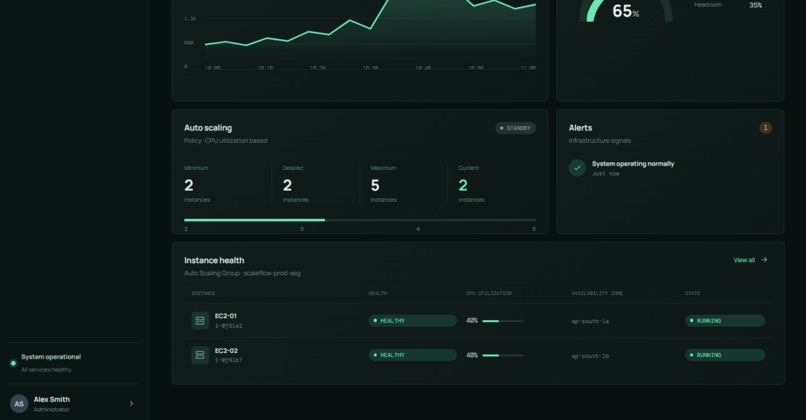
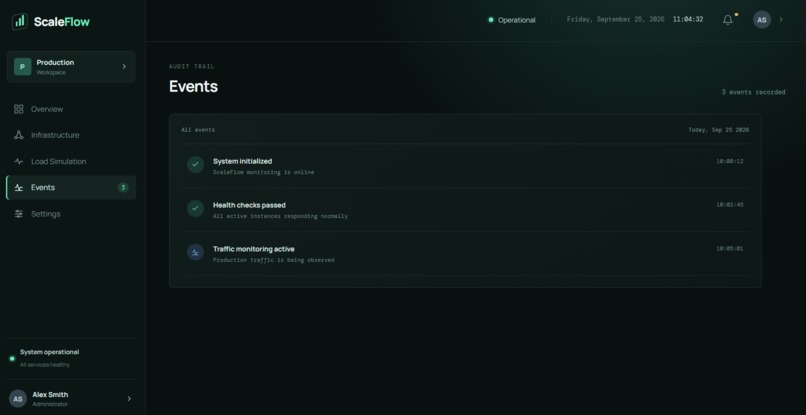
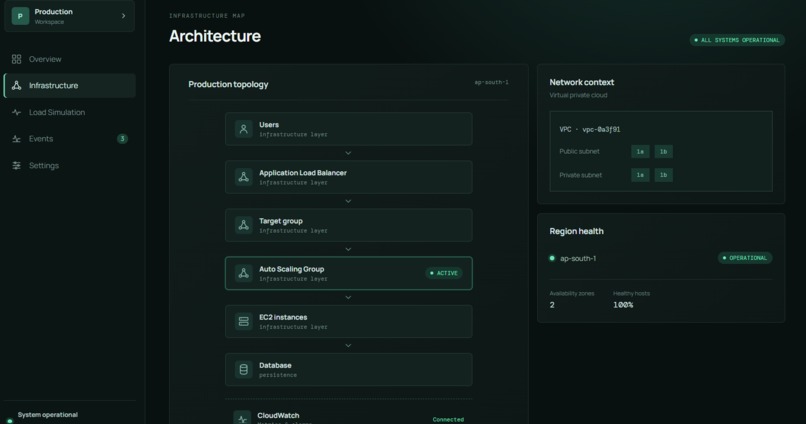
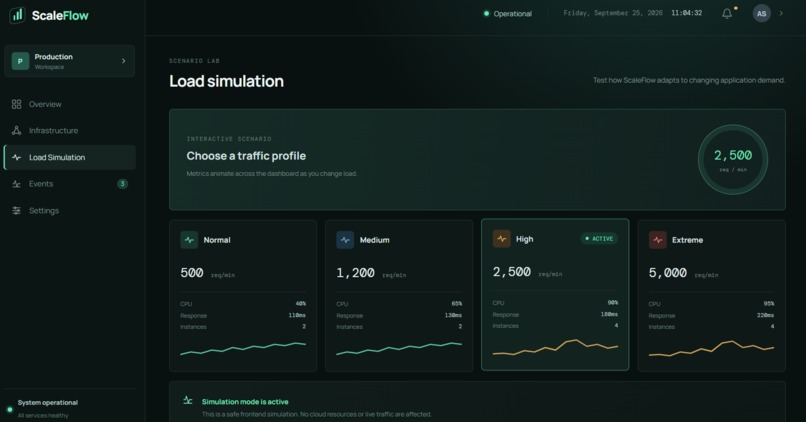
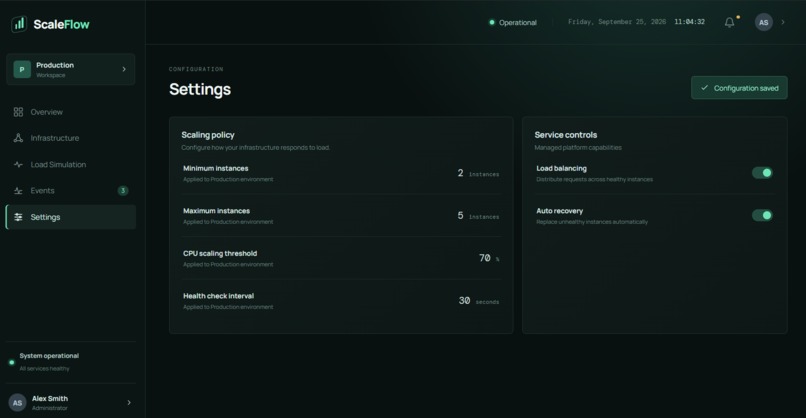
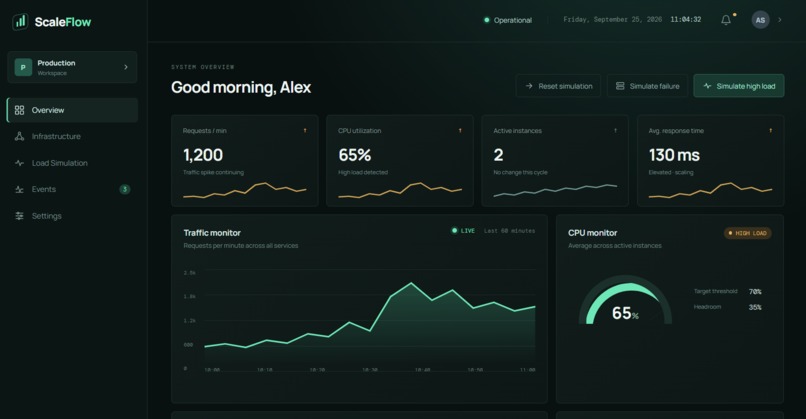
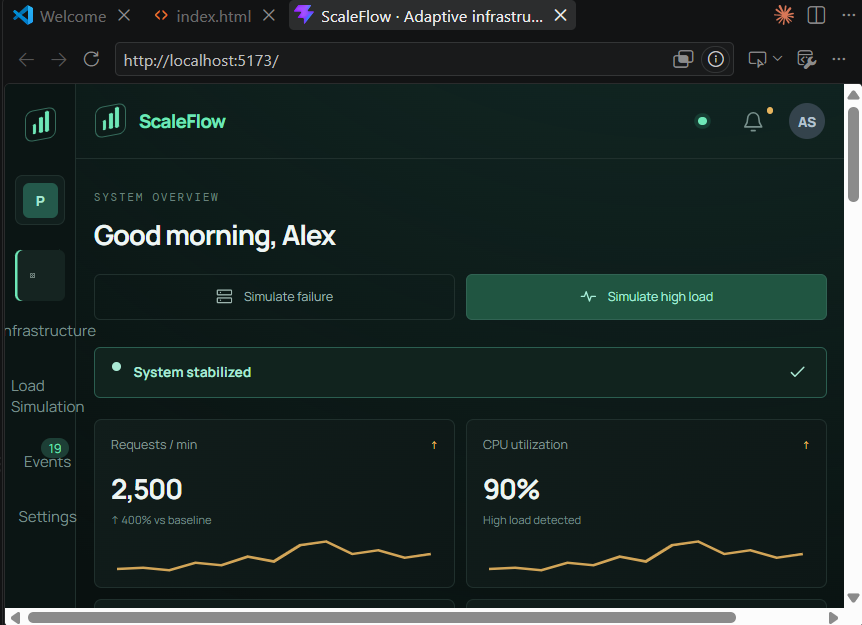
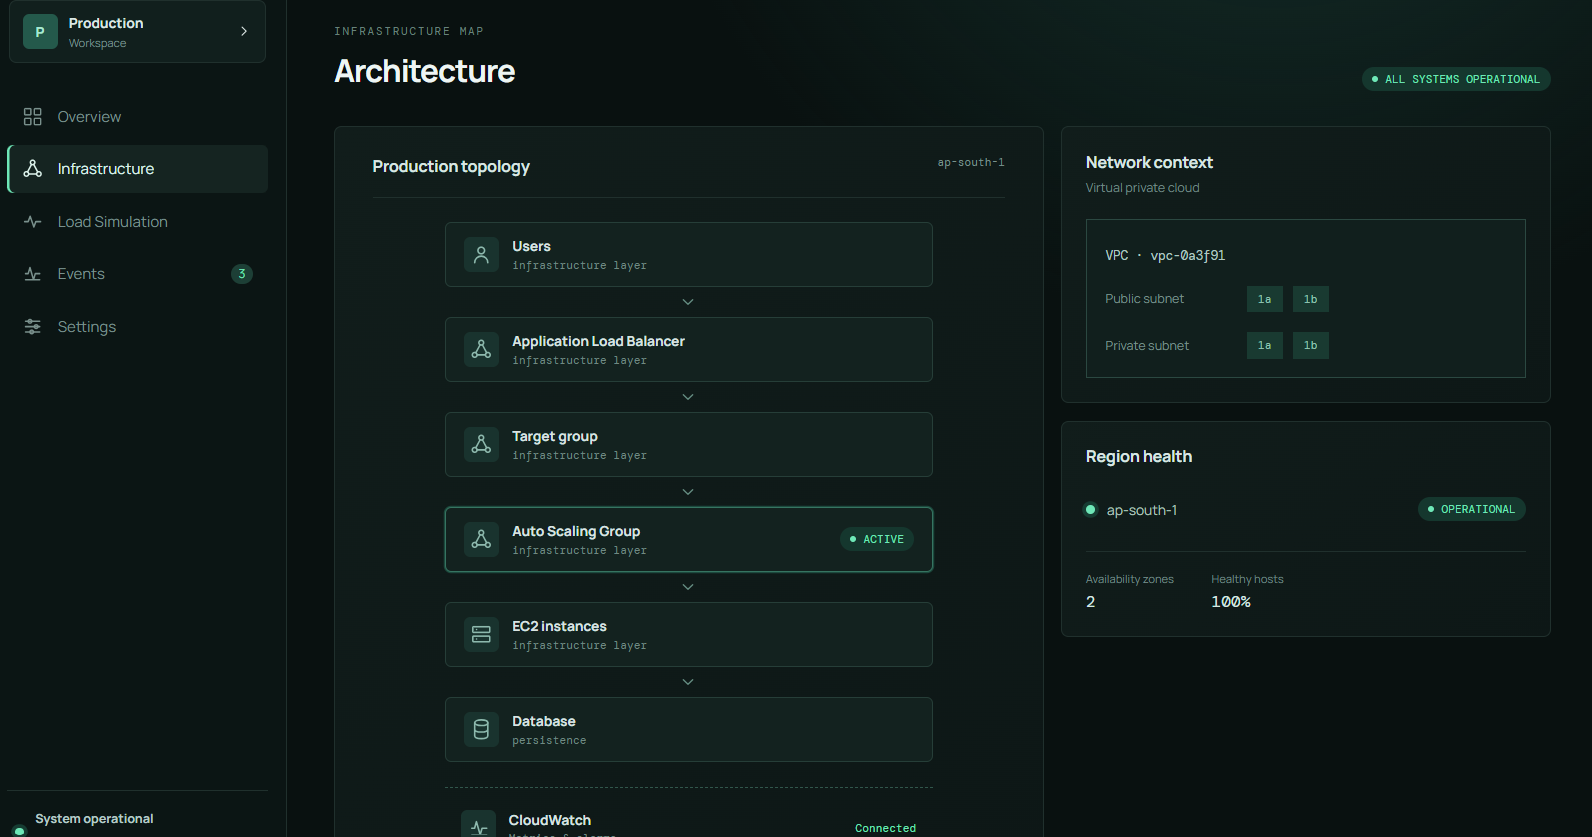
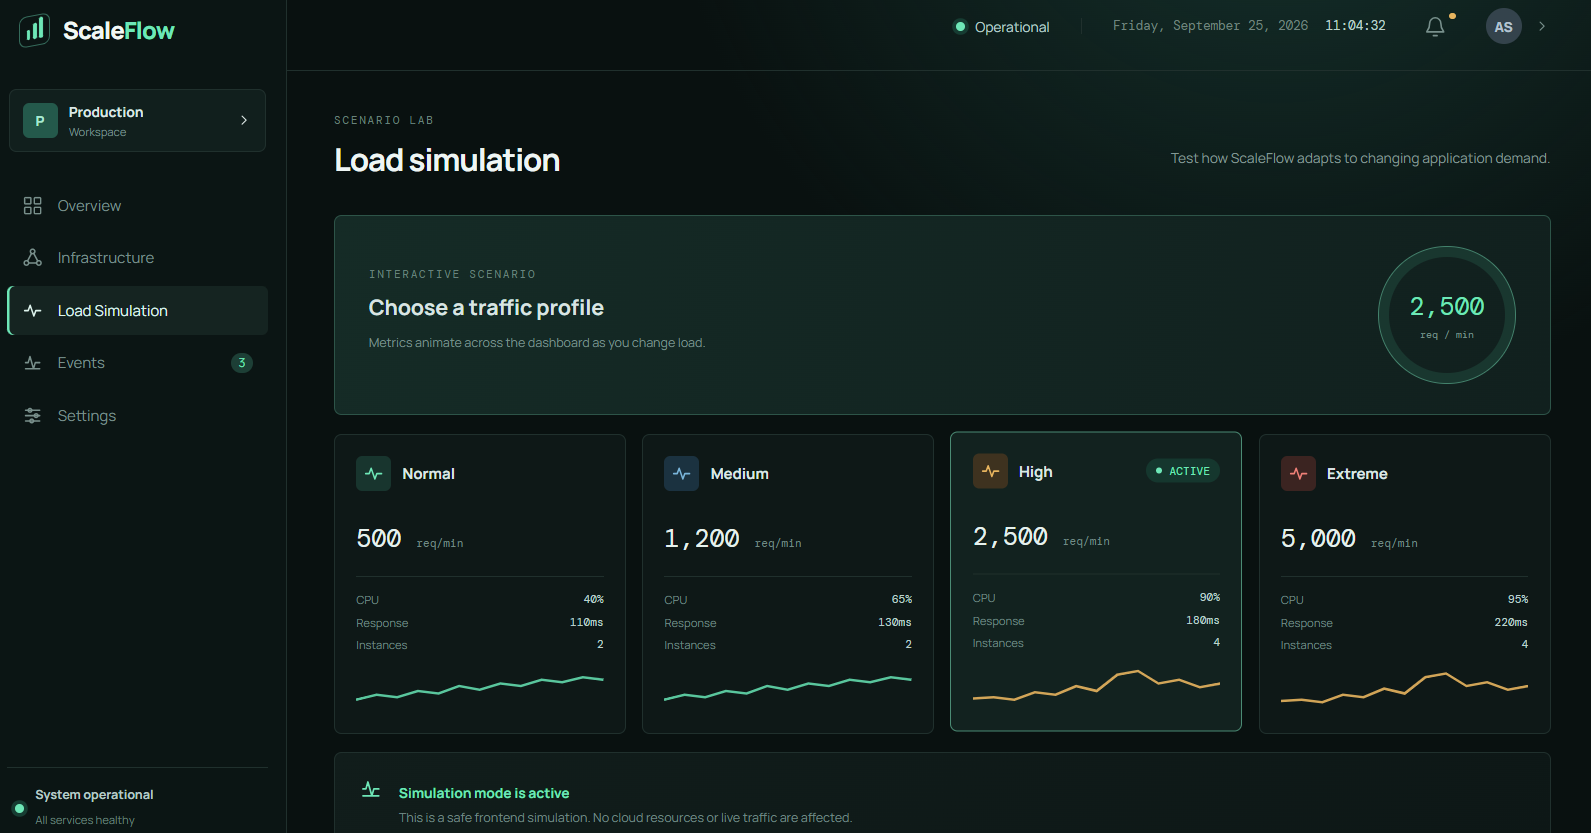
We built ScaleFlow as a React-based interactive dashboard to visualize cloud infrastructure behavior. We created simulations for traffic spikes, auto-scaling, instance failures and recovery. The dashboard shows metrics like CPU usage, requests per minute, response time, and active instances. We also designed an architecture view based on AWS services such as EC2, Load Balancer, Auto Scaling, and CloudWatch. For Round 1, we used simulated data to demonstrate how the proposed system would work.
Challenges we ran into
One challenge was understanding how different cloud services would work together in a real deployment. We had to simplify the cloud architecture without losing the main technical idea. Making the traffic spike and failure simulations feel realistic was another challenge. We also focused on presenting complex infrastructure concepts in a way that is easy to understand.
Accomplishments that we're proud of
We turned a complex cloud idea into a working interactive prototype. The dashboard shows traffic spikes, scaling, failures, and recovery. We connected concepts like load balancing, monitoring, and auto-scaling in one workflow.
What we learned
We learned how cloud services can work together to handle changing workloads. We understood concepts like horizontal scaling, load balancing, monitoring, and recovery better. We learned why keeping extra servers running all the time is not always efficient.
What's next for ScaleFlow
In the next round, we plan to connect ScaleFlow with real AWS services. We will implement EC2, Application Load Balancer, Auto Scaling, and CloudWatch. We will test the system with real traffic and measure its scaling and recovery performance. Our goal is to make ScaleFlow a practical and reliable cloud infrastructure solution.
Built With
- amazon-cloudwatch
- amazon-web-services
- cloud
- css
- ec2
- javascript
- loadbalancing
- react
- vite
- vpc


Log in or sign up for Devpost to join the conversation.