Inspiration
Fixing a failing test is mostly trial and error: read the trace, guess a root cause, edit, run the tests, repeat. LLM assistants shorten the loop, but they still hand you a single suggestion - and a wrong guess costs another round trip. We wanted a tool that races several plausible fixes and keeps only the one its tests confirm.
What it does
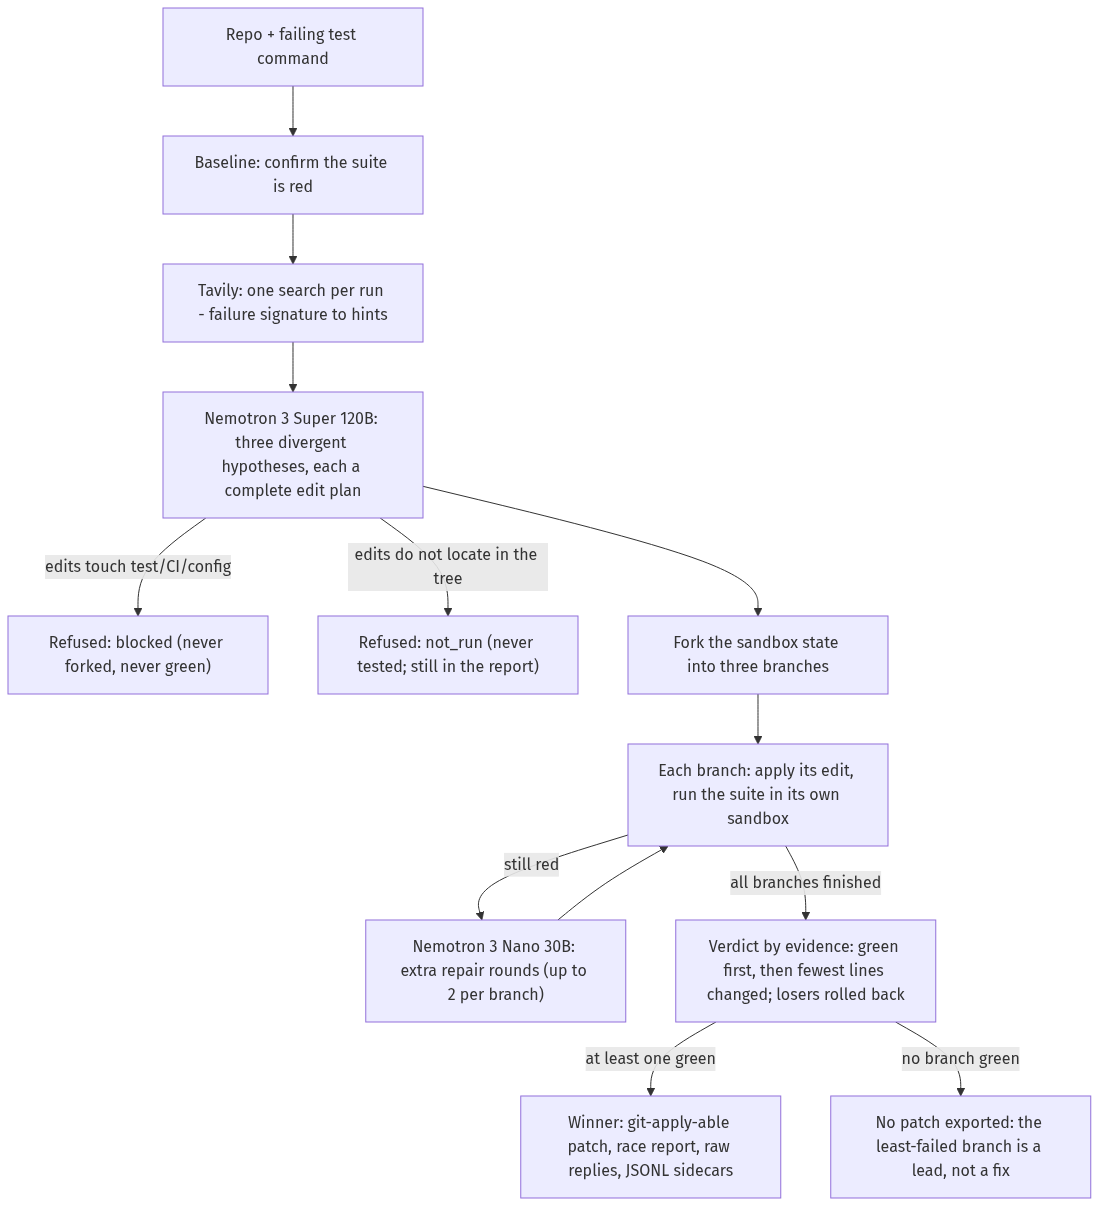
FixFork takes a Python repo and a failing test command. It confirms the failure first. Then it runs one real Tavily web search for the failure signature. It asks NVIDIA Nemotron 3 Super 120B (via Nebius Token Factory) for three divergent fix hypotheses. Each hypothesis comes with a concrete edit plan.
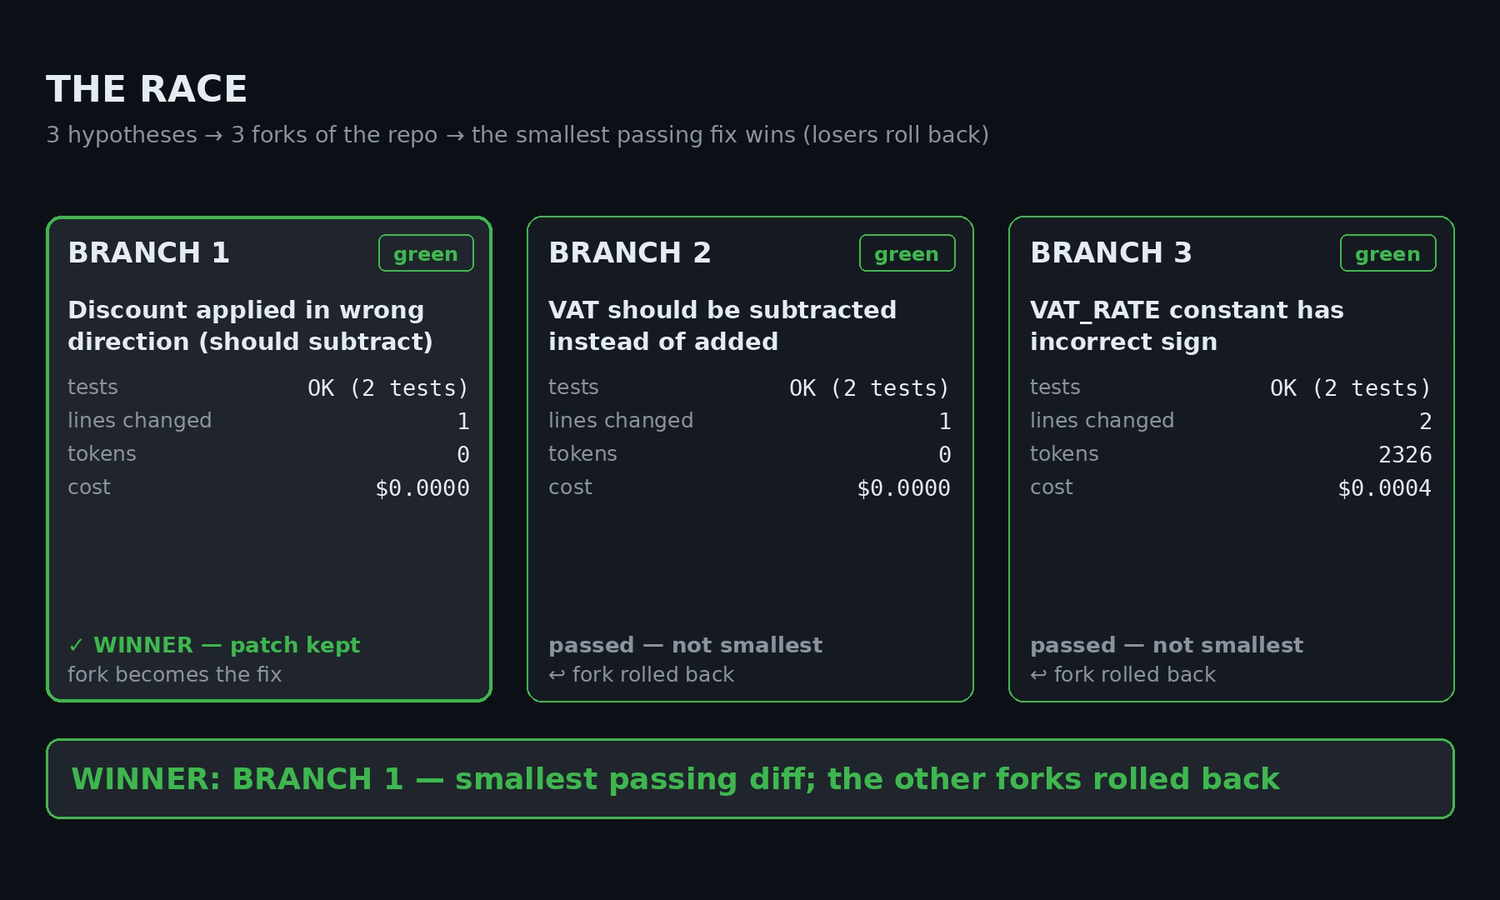
FixFork runs each candidate on its own forked branch. It iterates the failing branches with Nemotron 3 Nano 30B, up to two rounds per branch. Finally it keeps the branch whose tests pass. Ties go to the smallest change. Losers are rolled back, never merged.
If no branch goes green, FixFork exports no patch. The report names the least-failed branch as a lead, not a fix. Output: a git apply-able patch (only when a branch goes green), a self-contained HTML race report, raw model replies, and a JSONL event log. The report includes per-branch token and USD accounting.
Who it is for: the maintainer of a small Python project who has just received a bug report with a failing test. The same tool suits the contributor who wants to send a patch they can defend with test output. FixFork is not a code-review replacement. The maintainer still decides what merges.
Known limits: FixFork works on Python repositories only. The test command must be the project's own Python test run. The local backend gives each branch its own temporary directory on the host machine, with no operating-system isolation; the Token Factory Sandboxes backend runs the branches inside separate sandbox VMs. A race only helps when the project's own tests reproduce the failure.
How we built it
- Python 3.10+, standard library only. Our environment blocks package installs, so everything is plain REST against Token Factory's OpenAI-compatible API.
- A model router with reasoning-budget retry. When a reasoning model exhausts
max_tokens, content comes back empty withfinish_reason=length. The router retries with a doubled budget (4096 -> 8192 -> 16384 -> 32768). Every model reply leaves a receipt in
.attempts.jsonl, the events JSONL andloops.jsonl: client-side HTTP latency in ms, prompt/completion token counts, a computed USD cost, and a SHA-256 of the pre-parse raw response bytes. Three live Nebius Token Factory calls measured 1070, 1094 and 1101 ms, each with a distinct 64-hex digest; the samples are published inexamples/live-receipts/, andcheck_receipts.pyre-checks them.A git-style sandbox abstraction (checkpoint, fork, rollback) with two backends. The first is local temp-dir branches: the default, with no isolation. The second is the live Token Factory Sandboxes backend (opt-in). There, fork and rollback move content-addressed state images. A full three-branch race ran in the sandboxes on 2026-09-29.
Evidence-based judging: passing tests first, then fewest lines changed. Per-branch cost tracking is built in.
Challenges we ran into
- Reasoning-budget exhaustion is silent unless you know the pattern - we found the retry by experimenting.
- Sandbox access states are opaque from outside. With a Project header present, a wrong id, a missing role and missing beta access all look identical. The service answers HTTP 200 with every permission false, or 403 Insufficient permissions: list.
- Package installs were blocked in our environment, so the HTTP client, patch export and test-runner glue are all standard library.
Accomplishments we're proud of
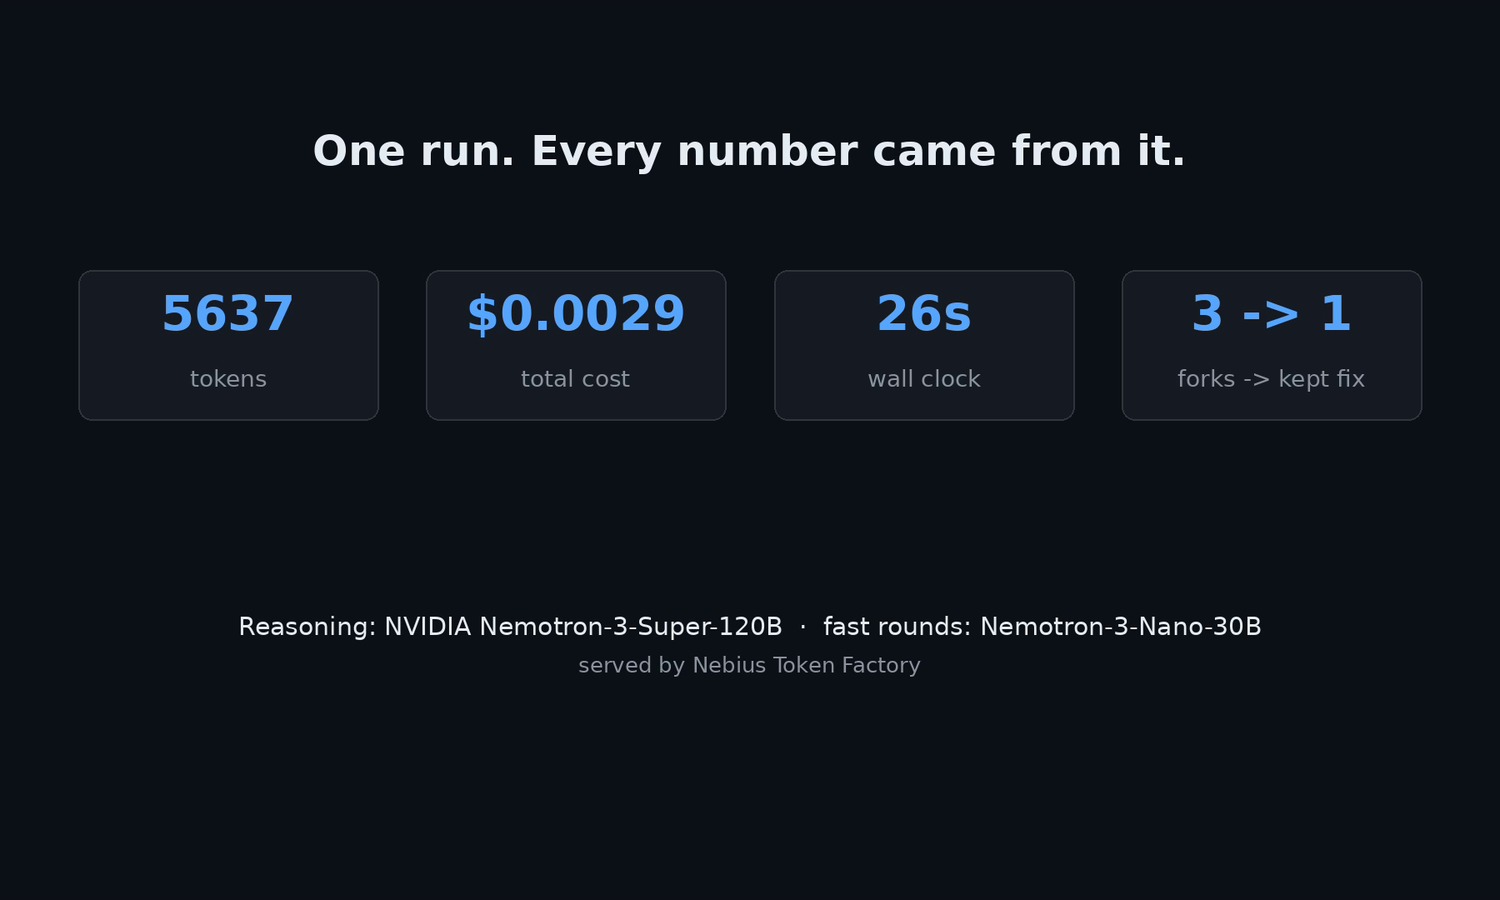
- A recorded demo run turned 2 failing tests into a passing 1-line fix. It took 26.4 s end-to-end and about $0.003 in model API cost. The exported patch re-applied cleanly with
git applyon a pristine checkout. - The repo ships 303 unit tests. The pipeline was validated through real end-to-end runs during development. One later run used live Tavily web grounding (five sources).
- The test suite is the referee, and it is protected. Proposed edits to test files, CI workflows or build/config files are refused before any sandbox work (
blocked). Such a branch can never win. A regression test replays a recorded race. In it, a test-editing branch used to score green. Now it is refused while the real fix still wins. The exported patch is re-checked, so renamed or quoted protected paths are withheld. Test-path conventions are matched case-insensitively:Tests/,__tests__/,testdata/. The refusal path (fixfork/guard.py) is exercised by 19 tests. In a 2026-09-29 replay on Nebius Token Factory Sandboxes, the test-editing branch was blocked before any sandbox operation ran. That branch used 0 operations, in a 10-operation run. The two source-only branches then raced. The winner's patch re-applied and the tests passed. - A full three-branch race ran entirely inside Nebius Token Factory Sandboxes (2026-09-29). The baseline failed inside the VM. Three branches forked from one state. The winning 1-line patch was exported from the sandbox VM and re-applied cleanly outside with
git apply. The race used 13 sandbox operations, measured at $0.0044 in sandbox cost. - A run against a real external repository (python-humanize, 2026-09-29) turned 6 failing tests into a winning patch. The patch re-applied with
git applyoutside the pipeline. The repository's own test suite then reported 310/310 passing. The dev-only dependency files were excluded. - A real-world result (merged 2026-09-30): FixFork was pointed at a live upstream issue in python-poetry/tomlkit (#619, stdlib
foldsupport). The runs reproduced the failure and located the fix area. The run traces are public in the repo (examples/tomlkit-619/). Neither run finished the patch on its own. The final patch was completed and verified by hand from the run report: 10 source lines plus 2 regression tests. It passed tomlkit's own full suite (1,060 passed). The maintainer merged it into tomlkit master 66 minutes after the pull request opened (PR #620: +52/-1 across 2 files, 24/24 CI checks green). - A multi-site result (2026-10-01): FixFork was pointed at a live upstream issue in OpenCTI-Platform/connectors (#7778, greynoise connector: the
classificationfield can be missing). Its third live run on the case fixed all seven occurrences of the unguarded access in one file, on its own. All three branches of the race went green (11/11 tests). The exported patch re-applied cleanly on a pristine fixture, taking the suite from 3 failed / 8 passed to 11 passed. A fix for the same issue is submitted as PR #7821. It was completed by hand from FixFork's run report, with a signed commit verified by GitHub. The automated review recommends approval; the maintainer review is pending. - An end-to-end sandbox result (2026-10-01): the same case was then fixed and verified end to end on the Nebius Token Factory Sandboxes backend (VM-level isolation). It was reproduced twice. The baseline failed inside the sandbox VM (3 of 11 tests). The reply's three hypotheses shared one edit set: two duplicates were dropped, one unique edit was kept. The branch fixed all seven occurrences of the unguarded access and went green (11/11 tests). The exported patch re-applied on a pristine checkout (11 passed). 34 of 34 sandbox operations succeeded on each run.
- A further upstream case (2026-10-06, habit-hooks #129): dependencies declared in
setup.py,setup.cfgor aPipfilewere silently never checked. The red baseline was reproduced first (3 of 6 tests failing). Then all three branches of the race went green (6/6 tests on every branch). A fix for the case is submitted as PR #200. Its acceptance run was measured separately on the case's 7-test suite. It goes from 4 failed / 3 passed to 7 passed, re-verified on a fresh clone. The commit774a1c1carries a GitHub-verified signature. No CI checks have run yet (first-time-contributor workflow approval pending). - A capability-test result (2026-10-10, Nuitka #4063): a race ran against a live upstream issue in a C-toolchain repository (a wrong
list.indexerror message under CPython 3.14, fixed in C source). The race produced a working fix: one of its two branches went green in one round with a one-line change. An independent referee, a fresh copy built inside an isolated box under CPython 3.14.3, took the baseline from red to green (2/2 message checks). The patch was then refined by hand to follow the repository's version-gating convention and re-verified under CPython 3.13.12 and 3.14.3. No pull request was opened for this case - it was run as a capability test. The run traces are public inexamples/nuitka-4063/. - A further upstream case (2026-10-16, habit-hooks #136):
initnamed a language from a single file inside a dependency directory (node_modules,vendor,site-packages,.venv,venv). The init path now drops files inside those directories before detection; a real source file elsewhere in the project still names its language. A fix for the case is submitted as PR #201. Its acceptance run, measured on the case's test set (init, recommend, report and listing tests), goes from 6 failed / 41 passed to 47 passed, re-verified on a fresh copy inside an isolated box. The commit078871842daccarries a GitHub-verified signature. - One Tavily search per run is a real runtime call. The tests remain the only verdict.
What we learned
- Evidence beats eloquence: letting tests pick the winner lets you accept fixes you would not trust from prose alone.
- Cost transparency changes behavior: per-branch token accounting makes "is this still worth it?" an explicit decision.
- Good retries matter more than good prompts when models think silently.
What's next
- Token Factory Sandboxes backend for real branch isolation on Nebius infrastructure - now wired and verified live; next it becomes the default backend.
- More languages beyond Python; packaging as a GitHub Action.
Requirements
- Python 3.10+ and
giton PATH; standard library only - nopip installneeded. - Live runs need internet access and a Nebius Token Factory API key. The Tavily search works keyless by default; an API key is optional.
- The repository README has full setup and quickstart instructions. It includes an offline demo mode (deterministic local router) that needs no API keys at all.
Links
- Code: https://github.com/tuyentran4992/fixfork.
- Narrated walkthrough: https://youtu.be/A6xS5TFVJs4.
- Demo page: https://fixfork.netlify.app.
