-
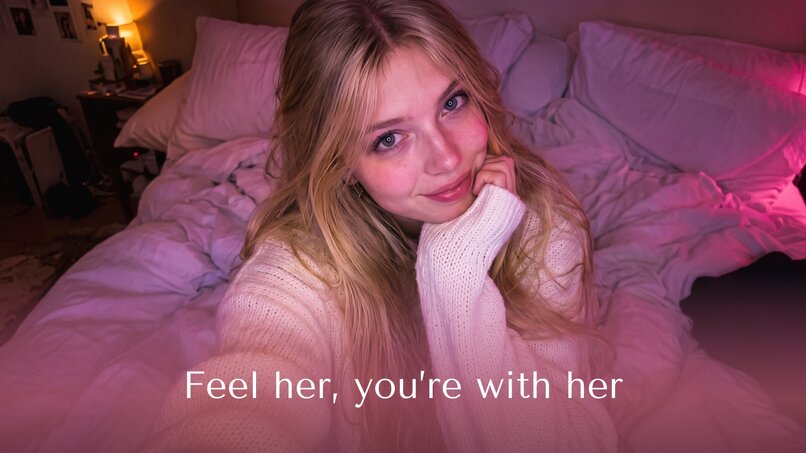
FeelHer - Browser-based 3D binaural AI voice companion
-
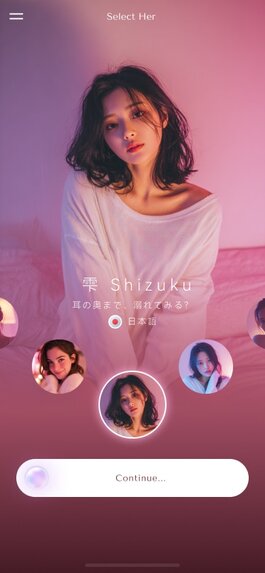
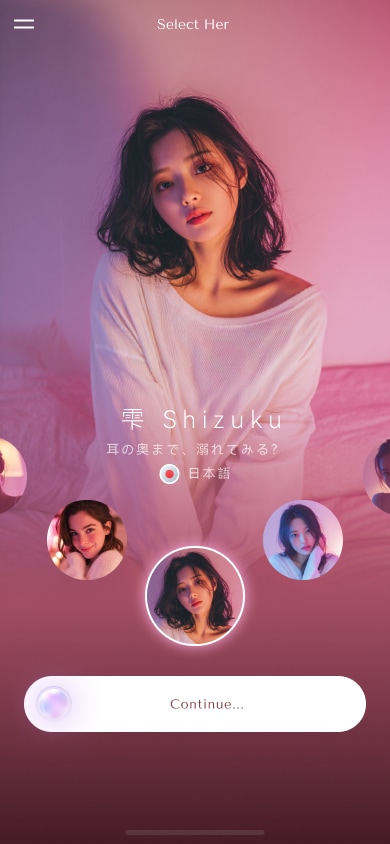
Shizuku - Japanese ASMR whisper companion
-
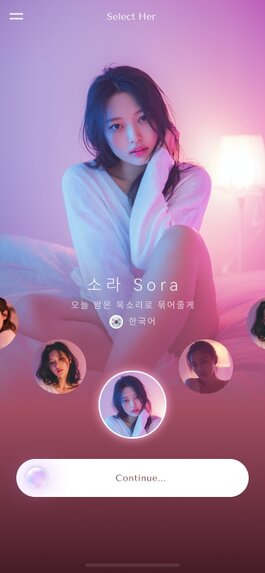
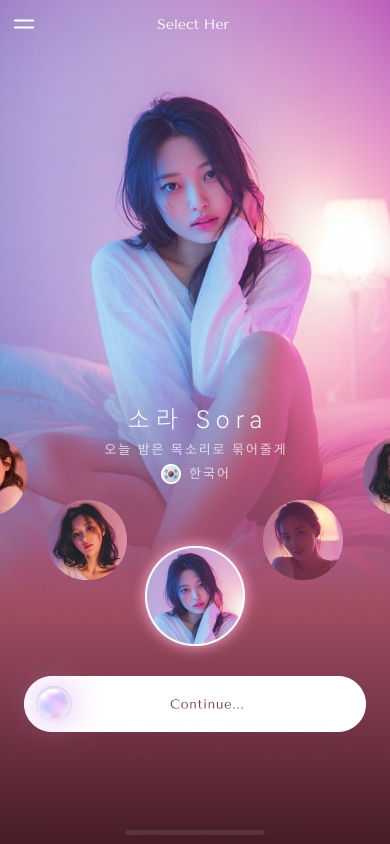
Sora - Korean emotional warmth companion
-
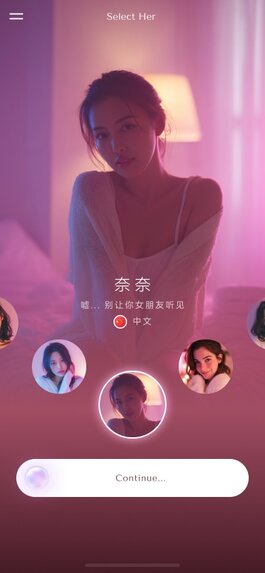
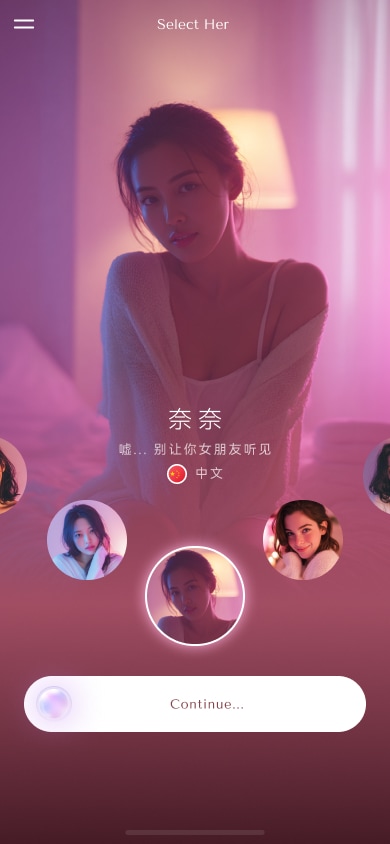
Nana - Mandarin bedside comfort companion
-
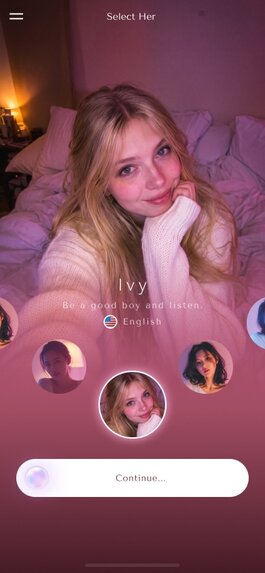
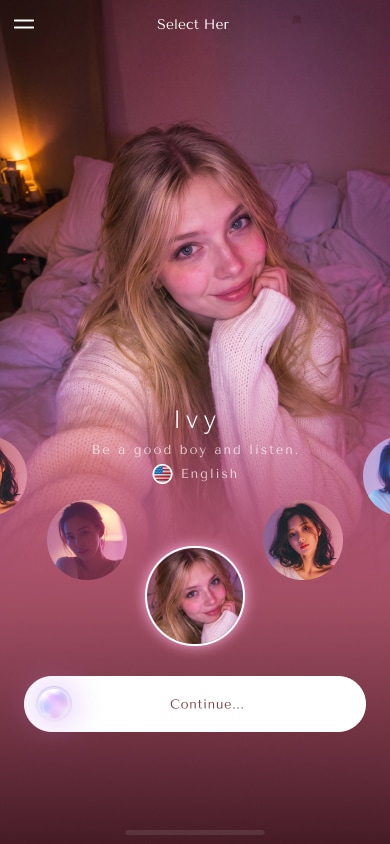
Ivy - English companion for intimate late-night conversation
Inspiration
Most current AI voice companions and chatbots feel emotionally detached due to turn-based latency and flat mono audio. You speak, wait 2–3 seconds for an API response, and hear a robotic voice that breaks immersion. We wanted to build something that feels genuinely intimate—like a private midnight phone call where she breathes, reacts to your voice in real time, and whispers directly into your ears.
What it does
FeelHer is a real-time full-duplex AI voice companion accessible directly in any web browser without downloads:
- 3D Binaural Spatial Audio: Audio is panned and acoustically modeled so her voice moves naturally around your ears when wearing headphones.
- Zero-Latency Full-Duplex WebRTC: Live sub-second voice streaming allows natural back-and-forth interruptions with zero awkward delays.
- Multilingual Personalities: Distinct emotional archetypes across English (Ivy), Japanese (Shizuku), Korean (Sora), and Mandarin (Nana).
How we built it
- Frontend: Next.js, React, TailwindCSS, and custom canvas-based voice activity visualizers.
- Audio Pipeline: Ultra-low latency WebRTC audio streams integrated with binaural Head-Related Transfer Function (HRTF) acoustic spatialization.
- Voice Engine: Optimized streaming speech synthesis pipeline tuned for intimate vocal textures and whisper frequencies.
Challenges we ran into
Achieving sub-300ms end-to-end voice latency while maintaining high-fidelity 3D binaural stereo panning inside standard mobile and desktop web browsers without native apps.
What's next for FeelHer
Expanding memory retention for continuous multi-day emotional continuity, introducing custom voice tuning, and enhancing acoustic ambient scene presets.
Built With
- ai-audio
- binaural-audio
- next.js
- react
- tailwind-css
- typescript
- webrtc

Log in or sign up for Devpost to join the conversation.