-
-
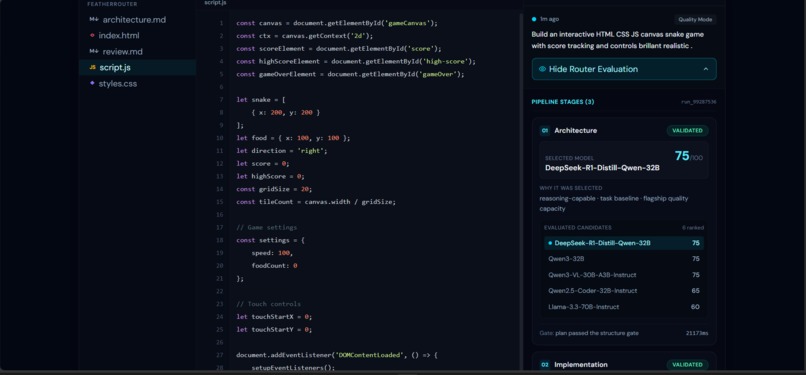
Interactive Workspace IDE & Transparent Model Router Evaluation Panel
-
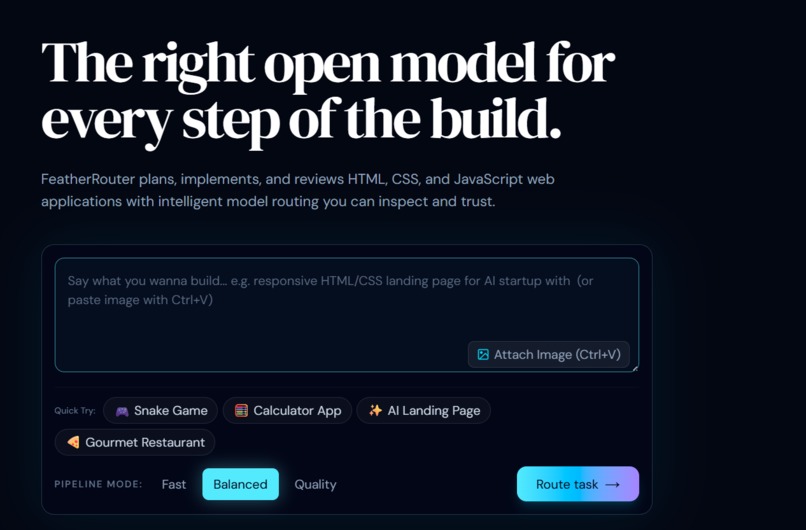
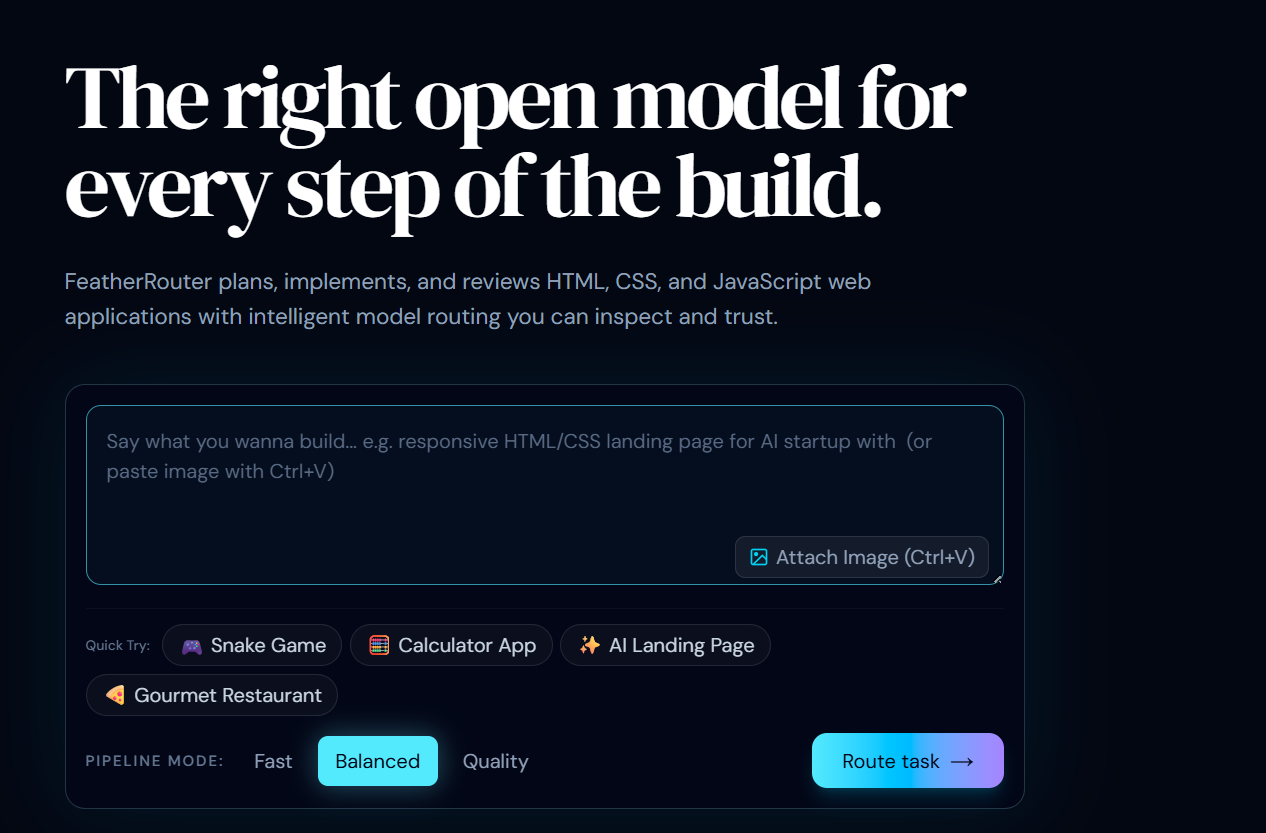
FeatherRouter Landing Page & Intelligent Task Composer Interface
Inspiration
Most AI coding assistants rely on a single monolithic LLM for every stage of development. However, empirically, no single model excels at everything — vision-capable models (like Qwen3-VL) excel at architecture layout from wireframes, specialized code models (like Qwen2.5-Coder-32B) excel at syntax synthesis, and instruct models (like Mistral-Small) excel at security auditing.
Forces a single model to handle all stages degrades output quality and increases error rates. We built FeatherRouter to create a dynamic multi-agent model router that breaks software generation into specialized pipeline stages and assigns the optimal open-source model per stage across 30,000+ models available on the Featherless API.
What It Does
FeatherRouter is an intelligent model orchestration platform for web application generation:
- Dynamic Task Analysis: Evaluates incoming user prompts and wireframe images using Gemini 2.5 Flash as a cognitive router.
- Stage-Aware Model Selection: Scores and ranks candidate models from the Featherless inventory based on capabilities, context window, and latency.
- Multi-Stage Execution: Dispatches specialized tasks across pipeline stages (Architecture Plan → Code Synthesis → Security Audit).
- Automated Quality Review (Layer 4): Audits cross-file DOM element matching, CSS contrast, and JS event listener bindings before rendering.
- Live Workspace & Web Preview: Provides an interactive code editor, real-time iframe browser preview with DOM polyfills, AI refinement bar, and 1-click ZIP export.
How We Built It
- Frontend & Canvas: Built with Next.js 16 (App Router), React 18, and TypeScript. Hand-crafted dark mode styling with zero external UI fluff.
- Cognitive Router Brain: Gemini 2.5 Flash (via Google AI Studio) acts as the high-speed routing head and automated quality reviewer.
- Model Execution Engine: Integrated with the Featherless API, accessing over 21,700+ open-source models (including Qwen2.5-Coder-32B, DeepSeek-R1, and Mistral-Small).
- Client-Side Preview Polyfill: Built a custom iframe bundler injecting DOMContentLoaded execution polyfills, smooth anchor scrolling, and link navigation interceptors.
Mathematical Scoring Model & Technical Challenges
To select candidate model $M_i$ for pipeline stage $T_k$, FeatherRouter evaluates a weighted fitness score:
$$S(M_i, T_k) = w_1 \cdot C(M_i) + w_2 \cdot L(M_i) + w_3 \cdot P(M_i, T_k)$$
Where $C(M_i)$ is context window capacity, $L(M_i)$ is observed inference latency, and $P(M_i, T_k)$ is historical task performance alignment.
Key Technical Challenges Solved:
- Client-Side Iframe Navigation Leaks: Solved link navigation bugs where clicking
<a>tags inside generated previews reloaded the parent application by implementing event capture interceptors with smooth anchor scrolling. - Model Output Deduplication: Resolved LLM code block repetition by detecting top-level entry point triggers (
DOMContentLoaded,initGame). - File Extraction Fallbacks: Built regex parsers that auto-extract embedded
<style>and<script>tags into distinctstyles.cssandscript.jsfiles if an LLM returns a single monolithic HTML file.
Accomplishments That We're Proud Of
- Shipped a 100% functional live production app deployed on Firebase Hosting with zero TypeScript compilation errors.
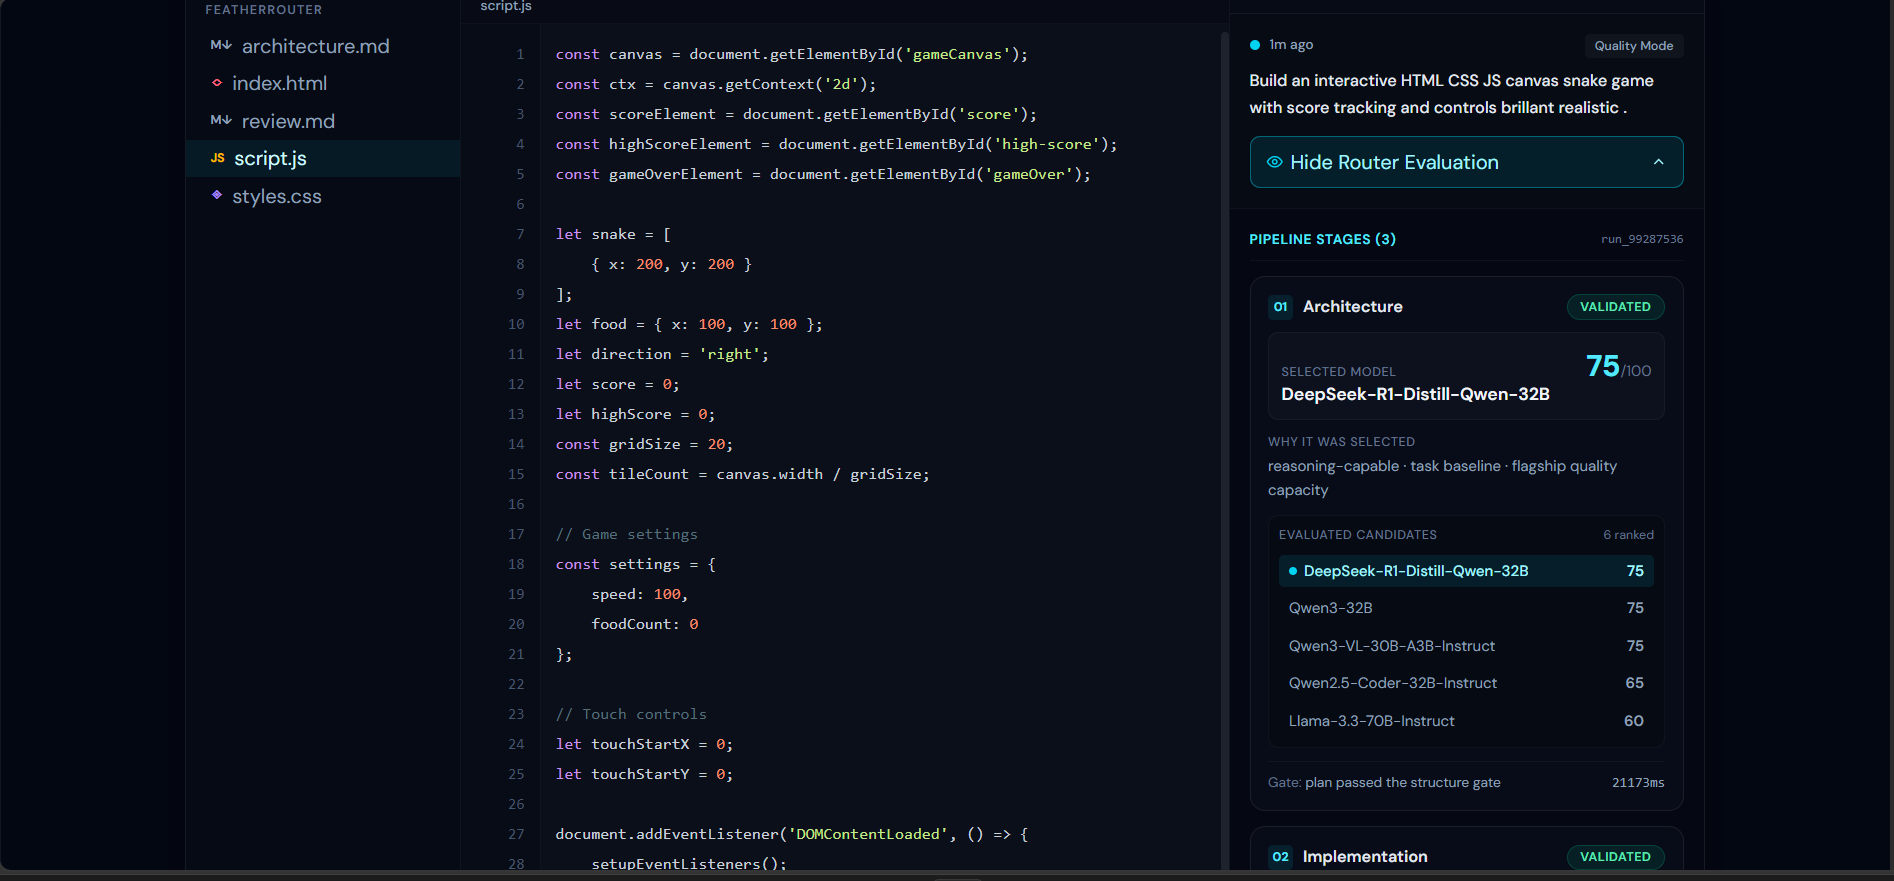
- Built a fully transparent routing drawer displaying real-time model marks ($/100$), candidate rankings, and natural-language selection rationale.
- Successfully orchestrated 4 distinct model stages with automatic fallback queues.
What We Learned
- Open-source models (like Qwen2.5-Coder-32B) rival proprietary models when given specialized, scoped task prompts rather than general instructions.
- Cross-file state alignment (matching JS
document.getElementByIdwith HTMLid="...") requires an explicit automated QA pass.
What's Next for FeatherRouter
- Custom Benchmark Suite: Expanding automated evaluation metrics for real-time model scoring.
- Multi-Framework Exports: Adding native support for Vue, Svelte, and React Native codebases.
- Local Model Routing: Supporting local Ollama / LM Studio endpoints alongside Featherless API cloud inference.
Built With
- ai-agents
- css3
- deepseek
- featherless
- featherless-api
- firebase
- gemini-api
- html5
- javascript
- mistral-ai
- model
- next.js
- qwen2.5-coder
- react
- routing
- tailwind-css
- typescript

Log in or sign up for Devpost to join the conversation.