-
-
project overview
Inspiration
I chose this problem because many students and graduates struggle to find jobs and scholarships to support their education and future careers. When searching online for opportunities, they can encounter scammers who waste their time, steal their personal information, or misuse it.
These scams can make students and job seekers lose money, trust, and confidence. I wanted to build Fake-Real Detector to help people recognize suspicious opportunities, understand the warning signs, and make more informed decisions before applying.
What it does
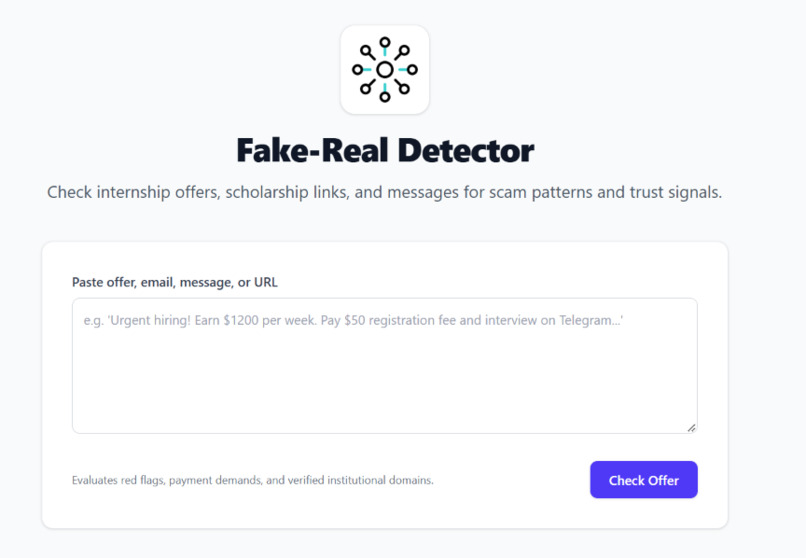
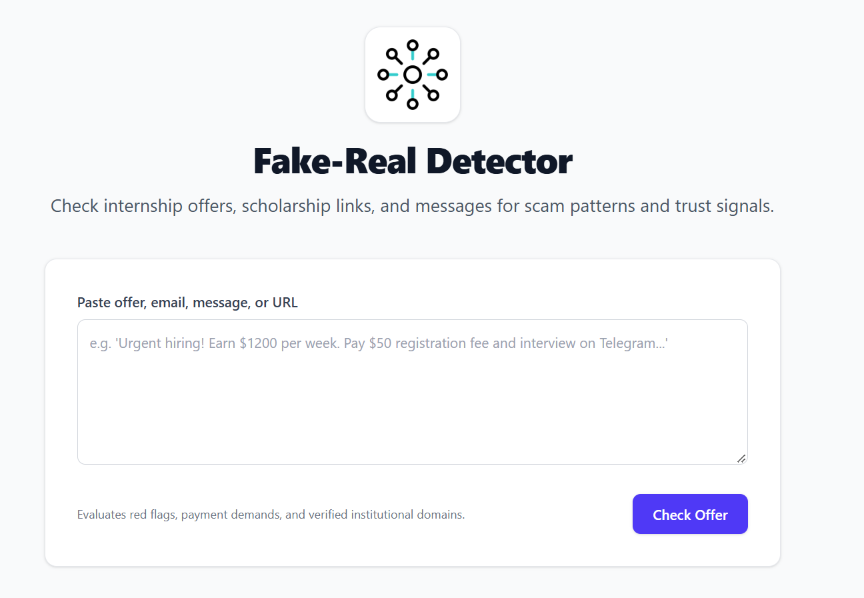
Fake-Real Detector helps students and job seekers by allowing them to paste the description, link, or other details of an opportunity they found on the web. The system analyzes the submitted information and rates the opportunity with a trust score from 1 to 10. It then provides the reasons behind its assessment and the evidence found in the submitted content to help users understand why the opportunity was rated that way.
How we built it
1. Planning and Architecture
I started by defining the project's scope, requirements, and technical specification before implementation. I organized the project into separate frontend and backend packages within an npm workspaces monorepo and divided development into four implementation slices.
2. Frontend Development
I used TypeScript to implement the frontend logic and Tailwind CSS to style the user interface. I separated user interaction from result presentation so that submitted opportunities could be analyzed and the resulting trust score, verdict, findings, and supporting evidence could be displayed clearly.
3. Backend Development
I used Node.js and Express to build the backend API responsible for receiving submitted content and coordinating the analysis process. The backend communicates with the frontend through the analysis API and returns structured results for presentation.
4. AI-Powered Analysis and Rule-Based Fallback
I integrated the OpenRouter API to provide AI-assisted analysis of submitted opportunities. I also implemented a deterministic, rule-based analysis engine that checks for suspicious patterns, such as upfront payment requests and unrealistic compensation, alongside selected positive trust signals.
The analysis orchestrator uses the AI service when available and falls back to the local rule-based engine when the AI request fails or returns an unusable result. This design reduces the application's dependence on an external AI service.
5. Testing and Verification
I implemented automated tests for the analysis rules, scoring and verdict generation, AI response handling, fallback behavior, API endpoints, input validation, and frontend presentation. These tests helped me verify individual components and important failure scenarios.
Challenges we ran into
1. Node.js 24 Installation Issues I encountered npm installation errors related to large SDK packages and OpenSSL on Windows. I solved this by replacing the external SDK with Node.js's built-in fetch API to communicate directly with OpenRouter, reducing dependencies and simplifying installation.
2. Unreliable AI API Connections Missing API keys, network timeouts, and API errors could interrupt analysis. I implemented a fallback strategy in orchestrator.ts that tries OpenRouter first and automatically switches to my local rule-based engine when AI analysis fails. I also added timeout handling, response validation, and automated tests.
3. Organizing the Project Keeping frontend and backend code together made dependencies and scripts harder to manage. I reorganized the project into an npm workspaces monorepo with separate frontend/ and backend/ packages, shared root commands, and CORS configuration for API communication.
4. Handling Empty Input I wanted empty or whitespace-only input to do nothing without showing unnecessary errors or sending API requests. I implemented validateAndSanitizeInput() in frontend/src/controller.ts and added tests to verify that invalid input never triggers a network request.
5. Showing Evidence Behind Each Result I wanted users to understand why an opportunity was flagged instead of receiving only a risk score. I updated the rule-based engine to capture matching text snippets and configured AI analysis to return supporting excerpts. The frontend displays these findings and evidence so users can understand the assessment.
Accomplishments that we're proud of
1. Planning Before Coding I organized development using scope.md, prd.md, spec.md, and checklist.md. This helped me define the requirements, design the architecture, and build the application step by step.
2. Reliable AI and Rule-Based Analysis I built a dual-engine system that combines OpenRouter AI with a local rule-based analyzer. If AI analysis fails or is unavailable, the application falls back to local rules to continue analyzing common warning signs and trust signals.
3. Automated Testing I created 32 automated tests, including 22 backend tests and 10 frontend tests. They cover analysis rules, AI failures, API validation, CORS, input handling, scoring, and result rendering using Node.js's built-in test runner.
4. Clear and Transparent Results I made the results easier to understand by presenting a trust score from 1 to 10, a risk verdict, a plain-English summary, and evidence snippets linked to the reasons behind the assessment.
5. Lightweight Project Architecture I organized the application into separate frontend/ and backend/ packages using npm workspaces. I also used Node.js's native fetch API to communicate with OpenRouter, keeping external dependencies to a minimum.
What we learned
1. Planning Before Coding I learned that defining the architecture, data contracts, and component responsibilities before coding helps prevent confusion and keeps development organized.
2. Combining AI with Rule-Based Analysis I learned that AI works better for this project when combined with deterministic rules. The local analyzer provides a fallback when the external AI service is unavailable, making the application more reliable.
3. Separating Components Makes Testing Easier I learned that separating input handling, API communication, result presentation, and analysis logic makes the code easier to maintain and test.
4. Keeping Dependencies Lightweight I learned that built-in Node.js features, such as fetch and the node:test runner, can reduce unnecessary dependencies and simplify installation and testing.
What's next for Fake-Real Detector
1. Browser Extension I plan to build a browser extension that allows users to check suspicious job offers and links directly from their browser without switching tabs.
2. Domain Verification I want to integrate domain age, DNS, and registration checks to help identify suspicious websites and recently created domains.
3. Scan History I plan to add an optional local history so users can review and compare previously analyzed opportunities.
4. Shareable Scam Alerts I want to generate privacy-friendly alert cards that students can share with others to raise awareness about suspicious job and scholarship offers.
5. Multilingual Analysis I plan to expand the detection rules and AI prompts to support multiple languages, helping more students and job seekers identify suspicious opportunities.
Built With
- css
- html
- javascript
- node.js
- regex
- rest-api
- typescript

Log in or sign up for Devpost to join the conversation.