-
-
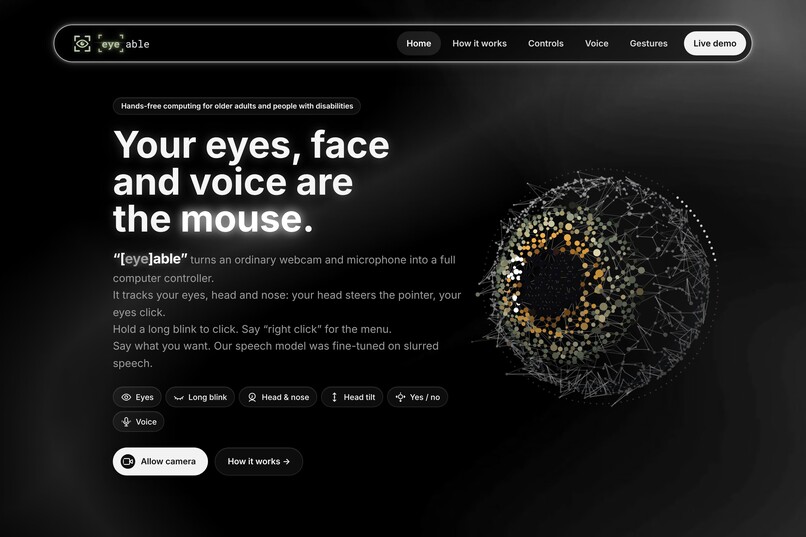
eyeable-01-home: [eye]able turns your laptop’s webcam and microphone into a hands-free mouse and keyboard.
-
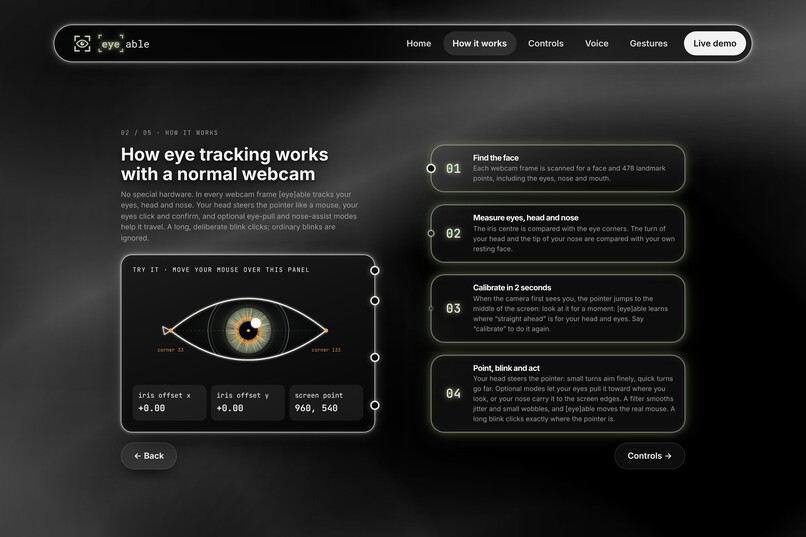
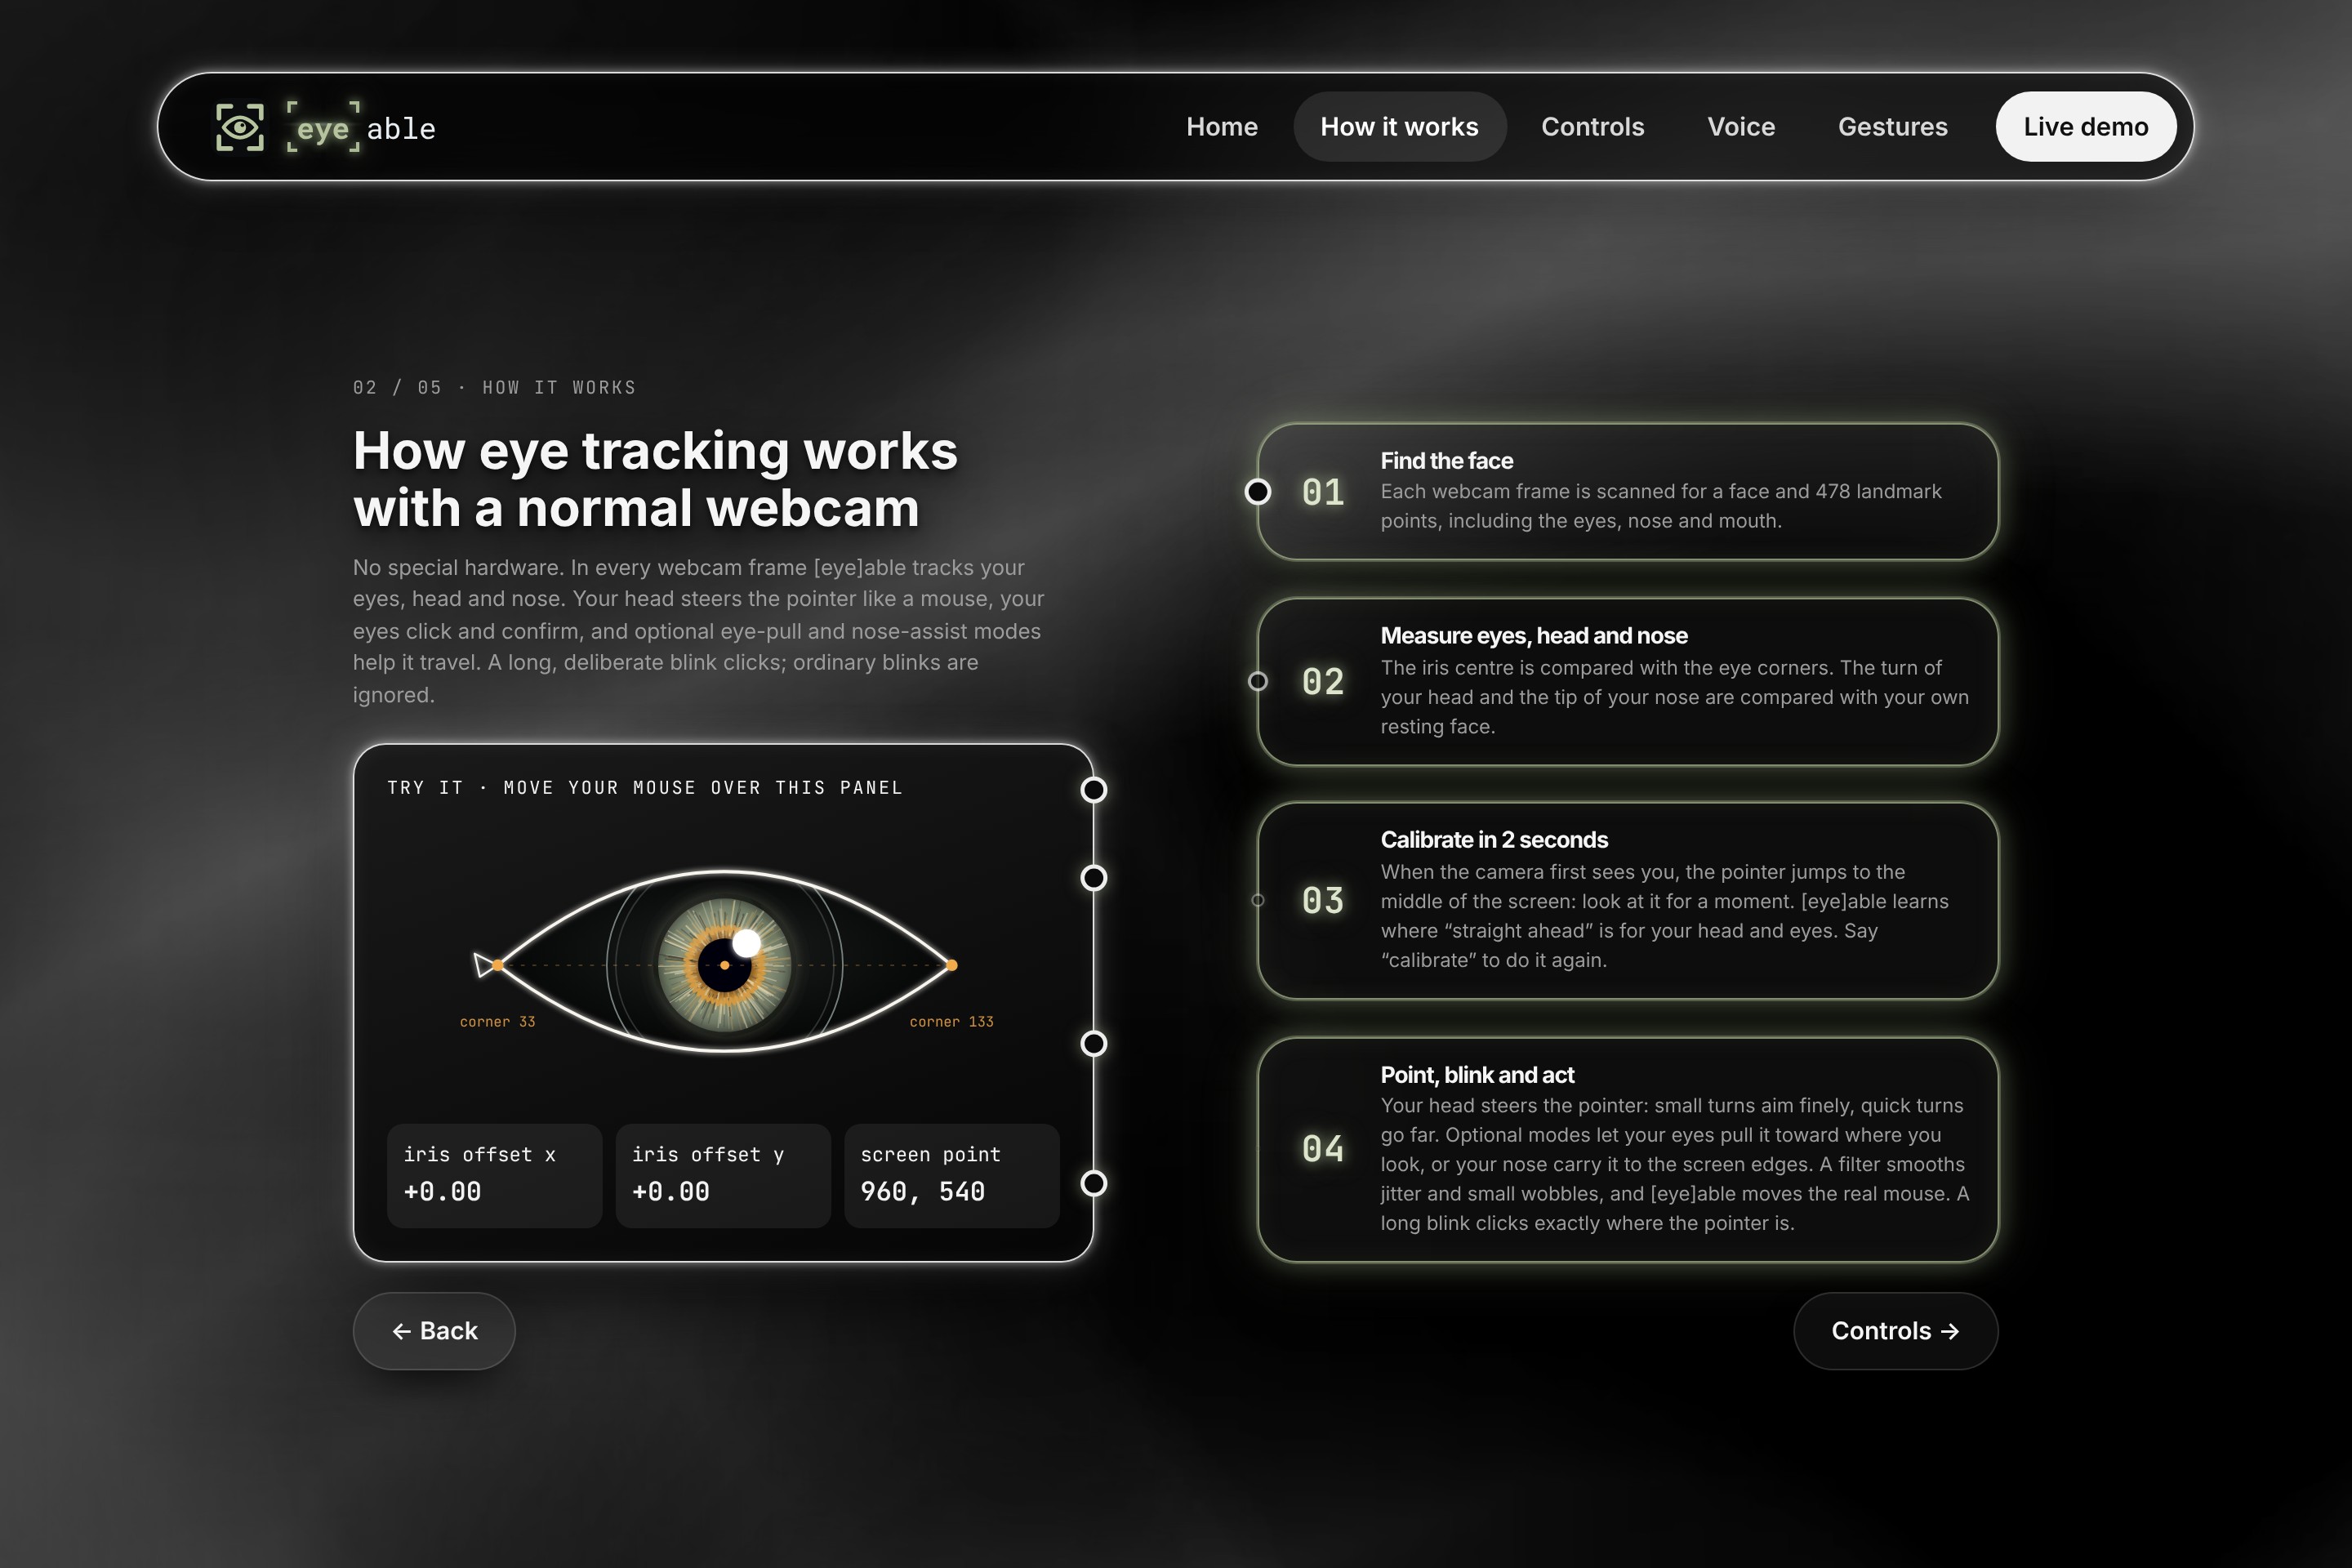
eyeable-02-how-it-works: How it works: find the face, measure eyes, head and mouth, calibrate in seconds, then point, blink and talk.
-
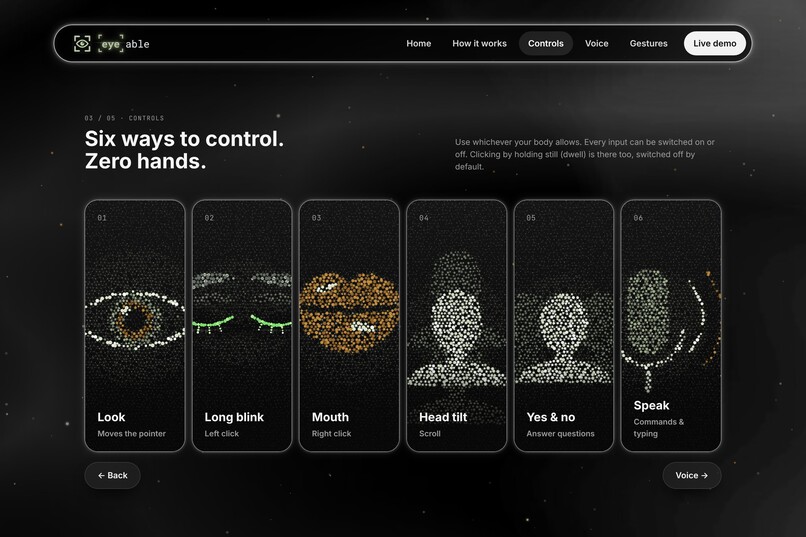
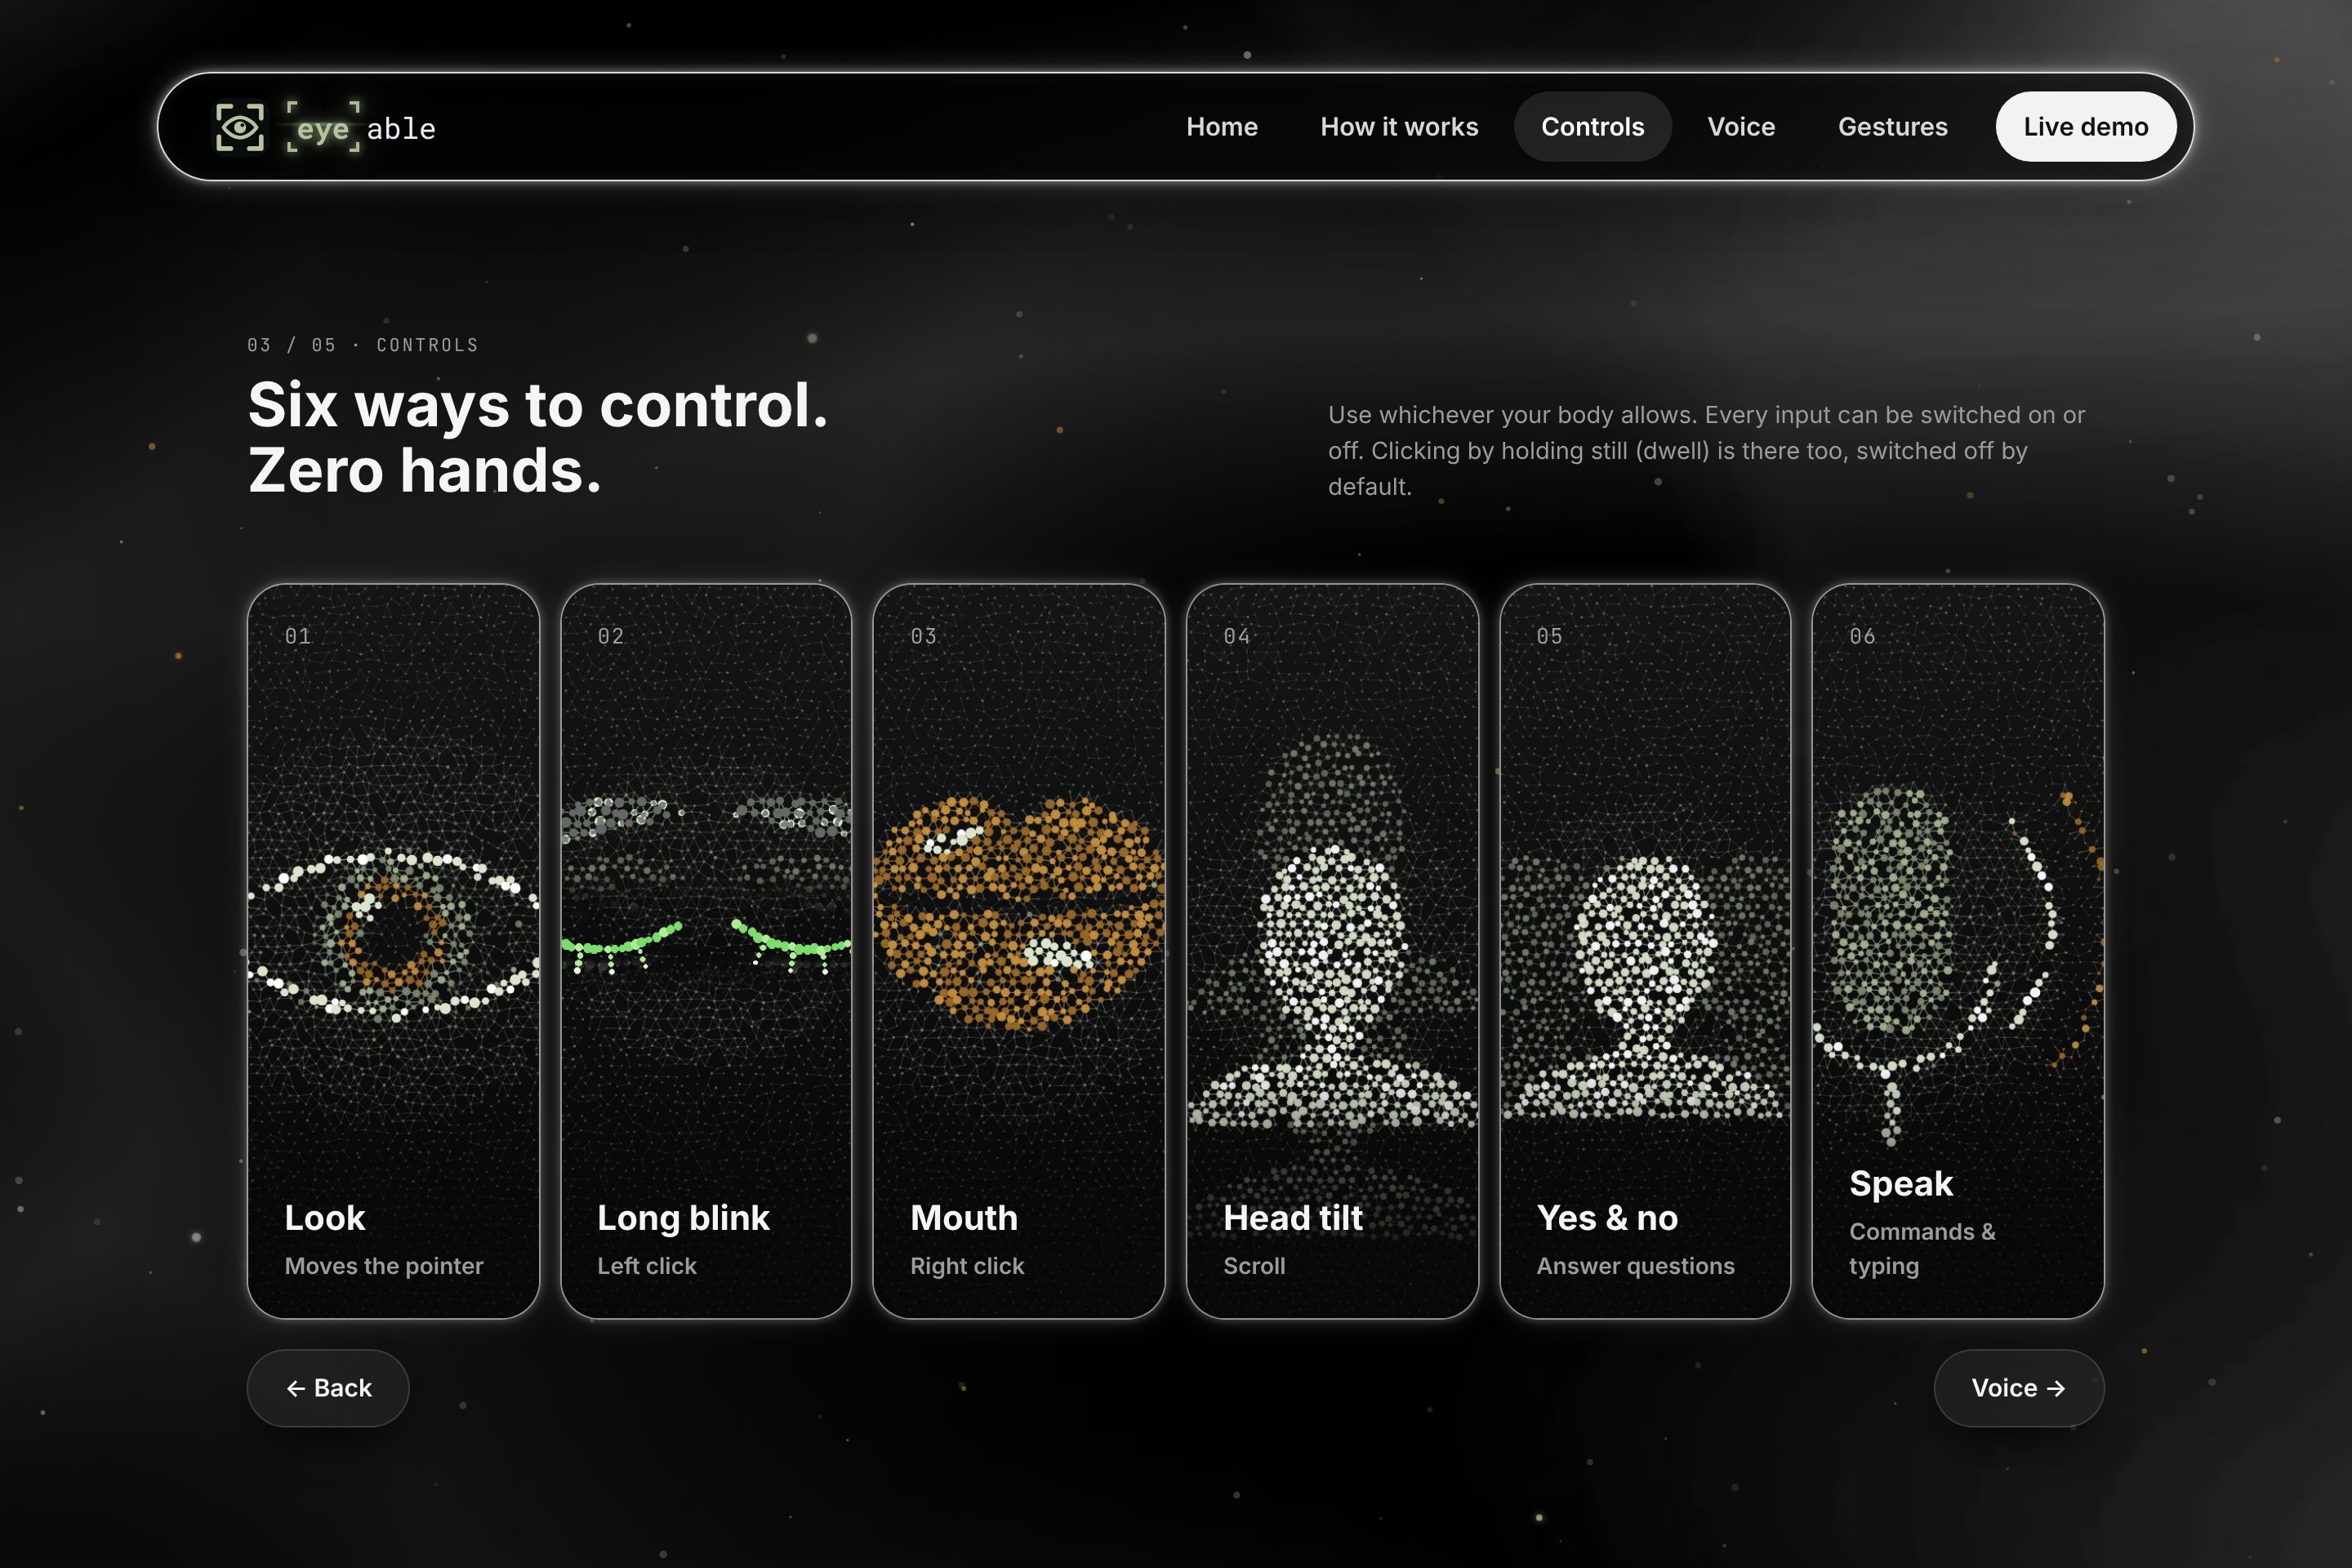
eyeable-03-six-ways-to-control: Six ways to control, zero hands. Use whichever inputs your body allows.
-
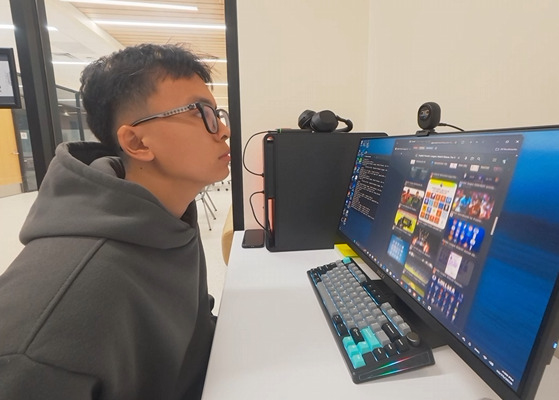
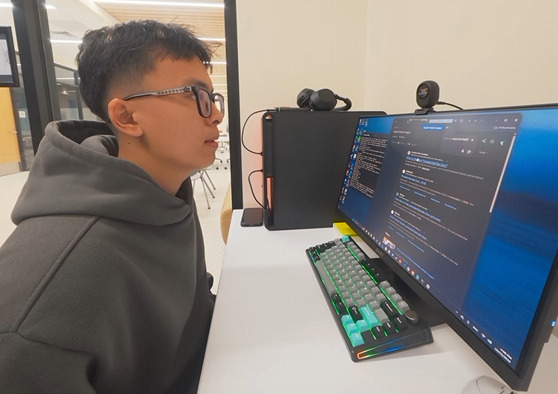
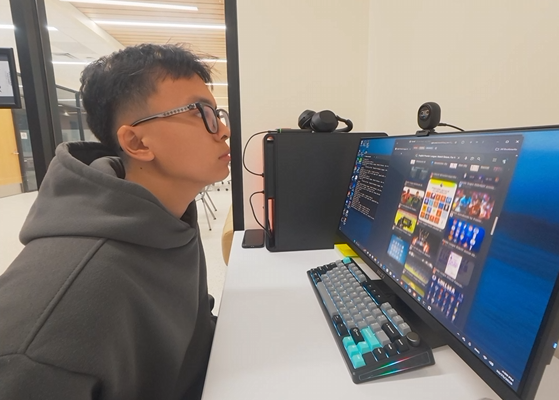
user using click and scroll features on WindowOS
-
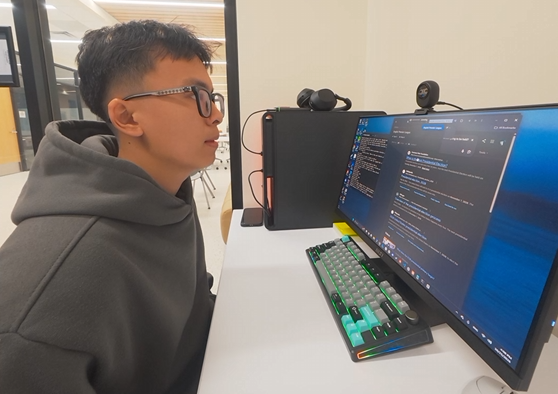
user using dictation features on WindowsOS
-
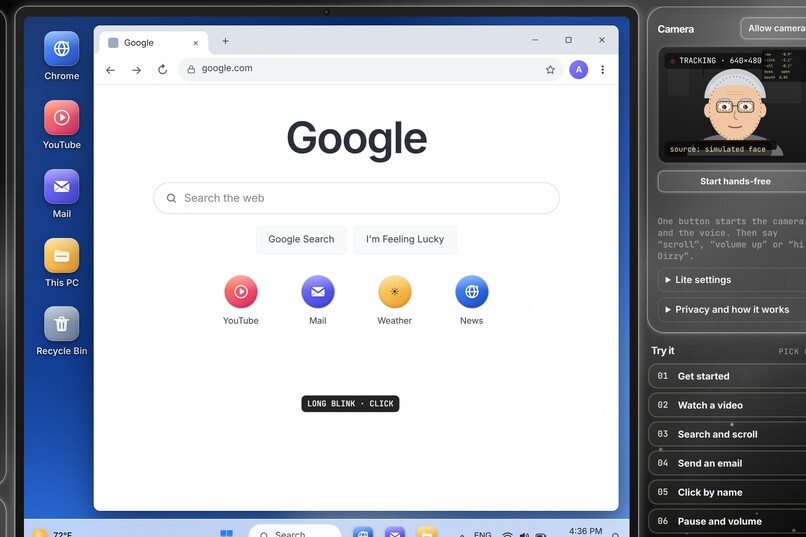
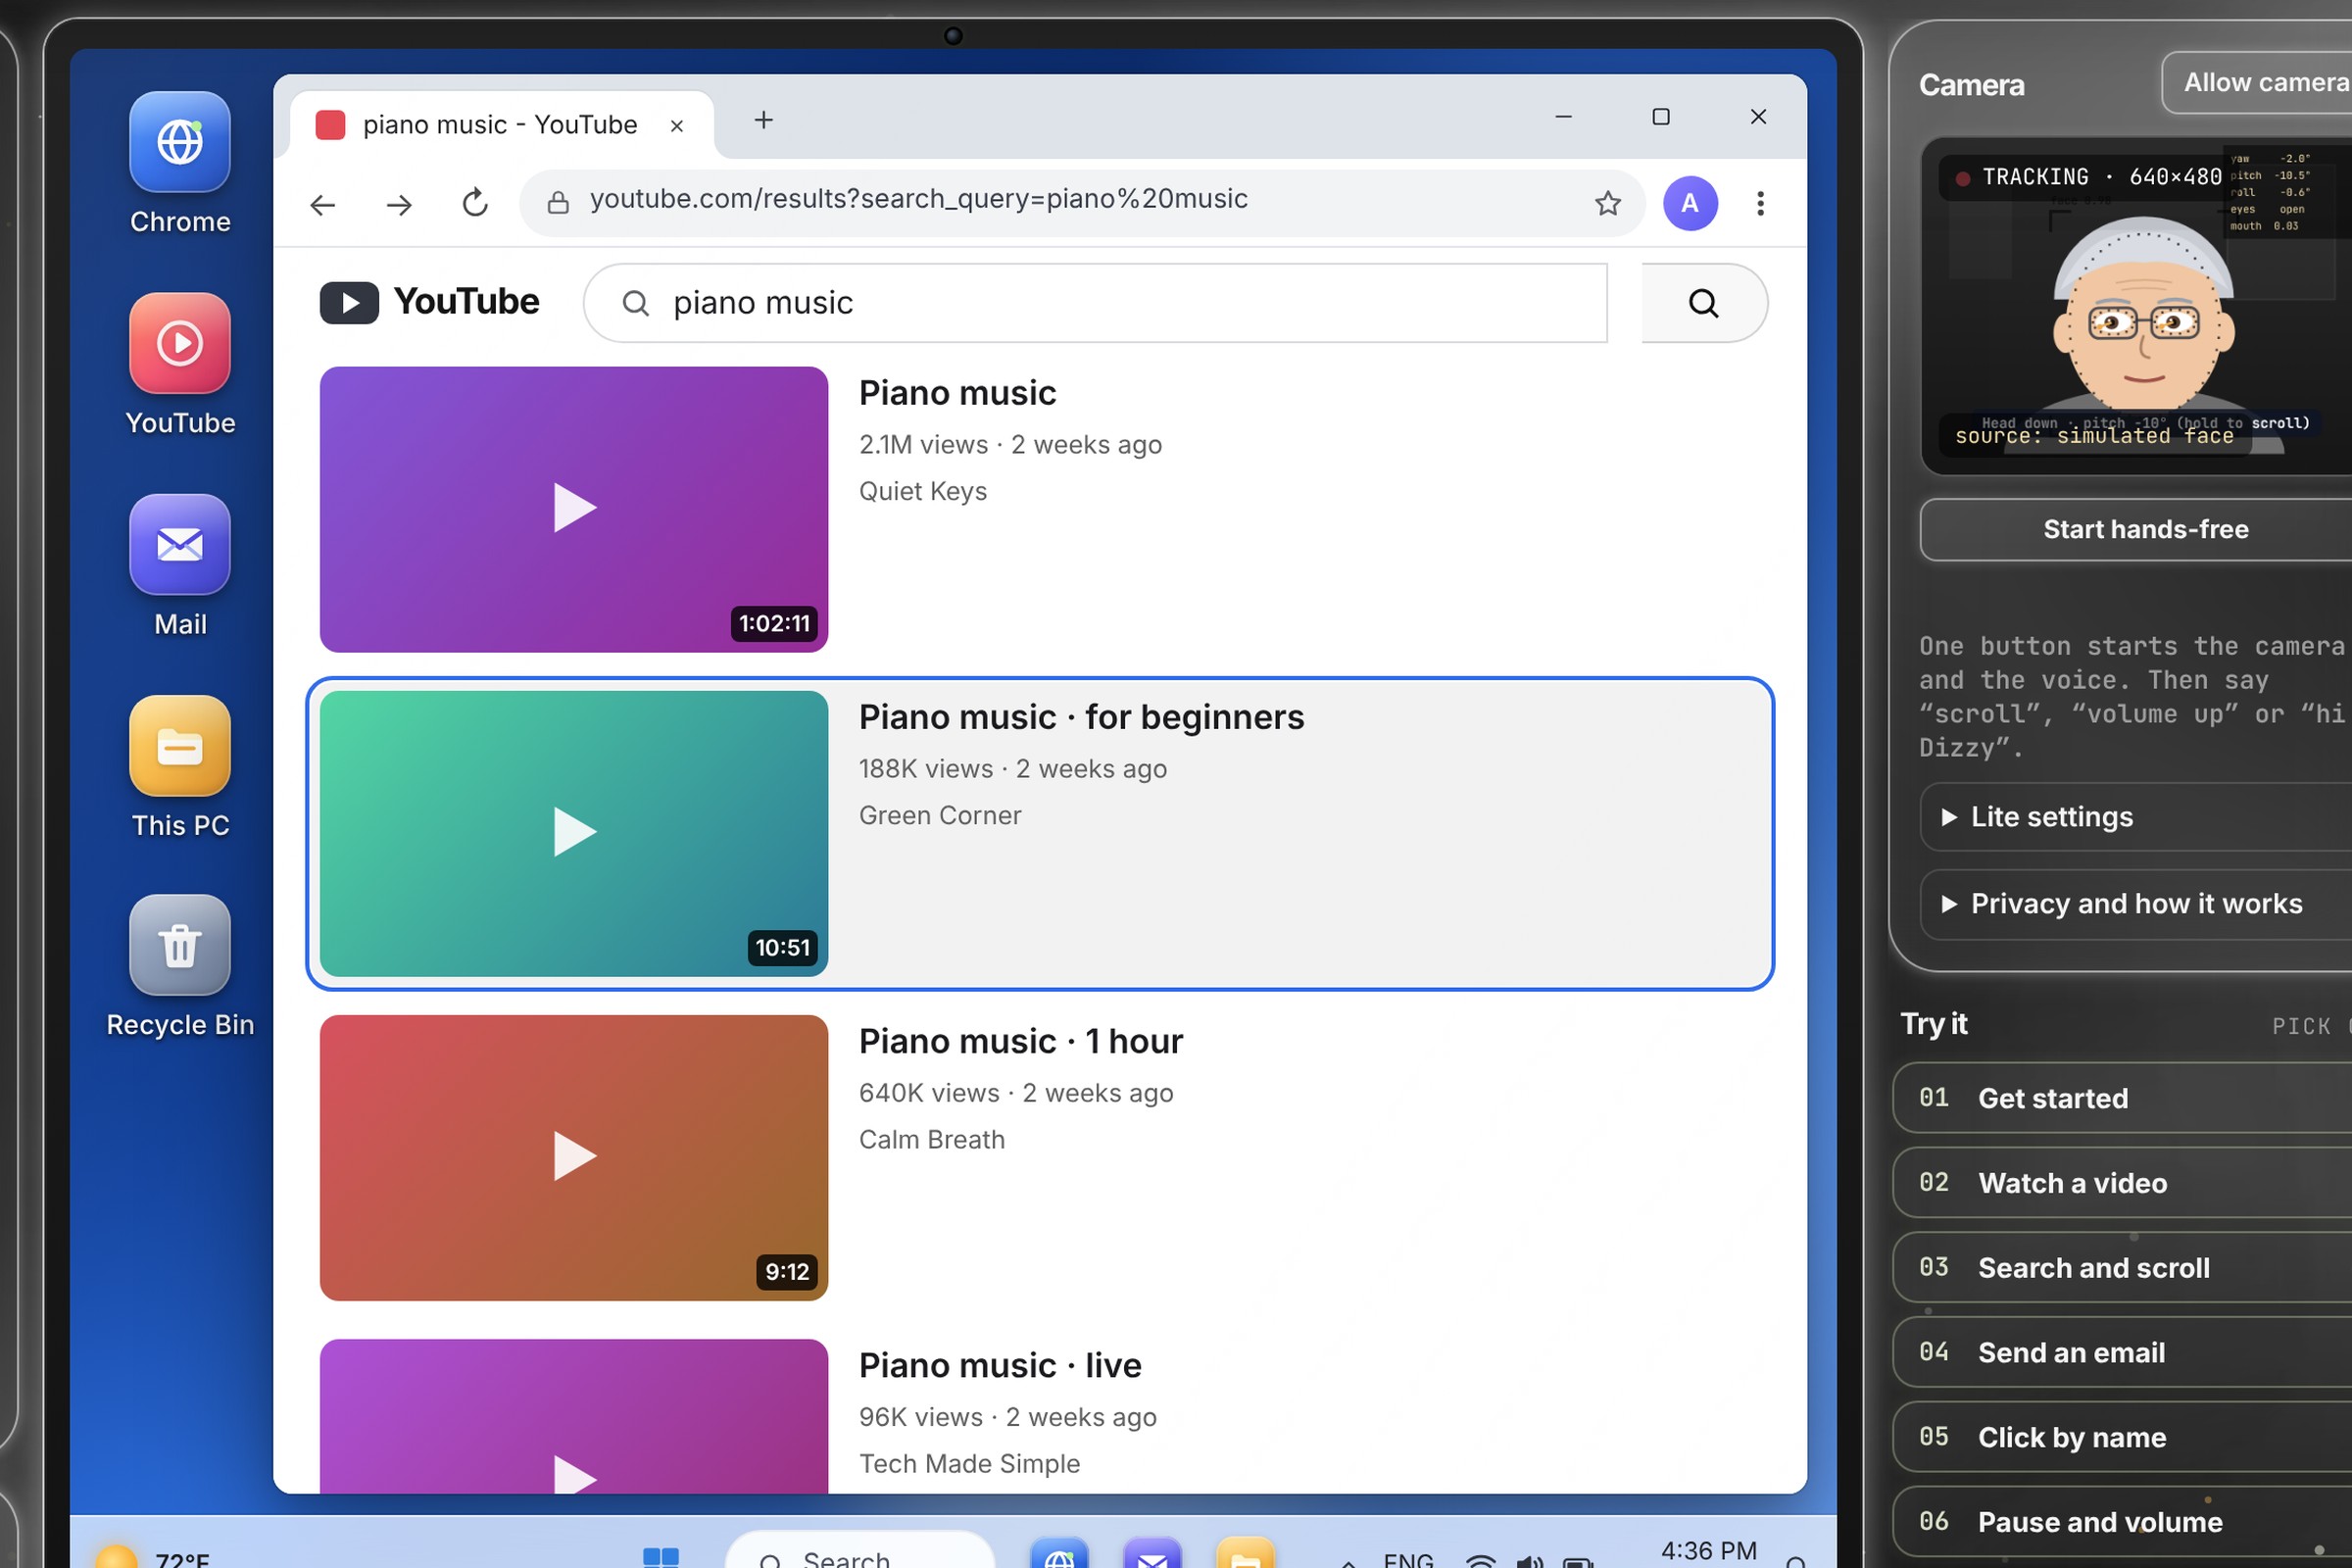
eyeable-14-closeup-long-blink-click: Close-up: a long, deliberate blink (0.4 to 1.6 s) clicks. Normal blinks never do.
-
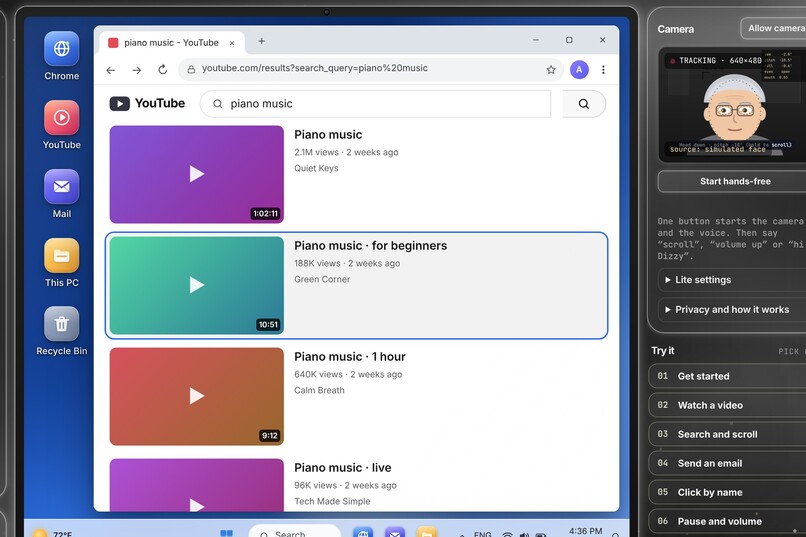
eyeable-12-closeup-choosing-a-video: Close-up: the pointer highlights a video, and a long blink opens it.
-
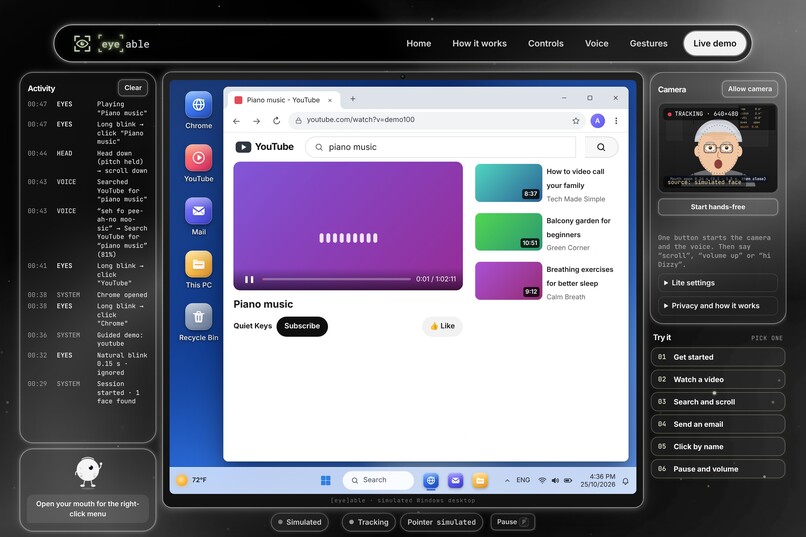
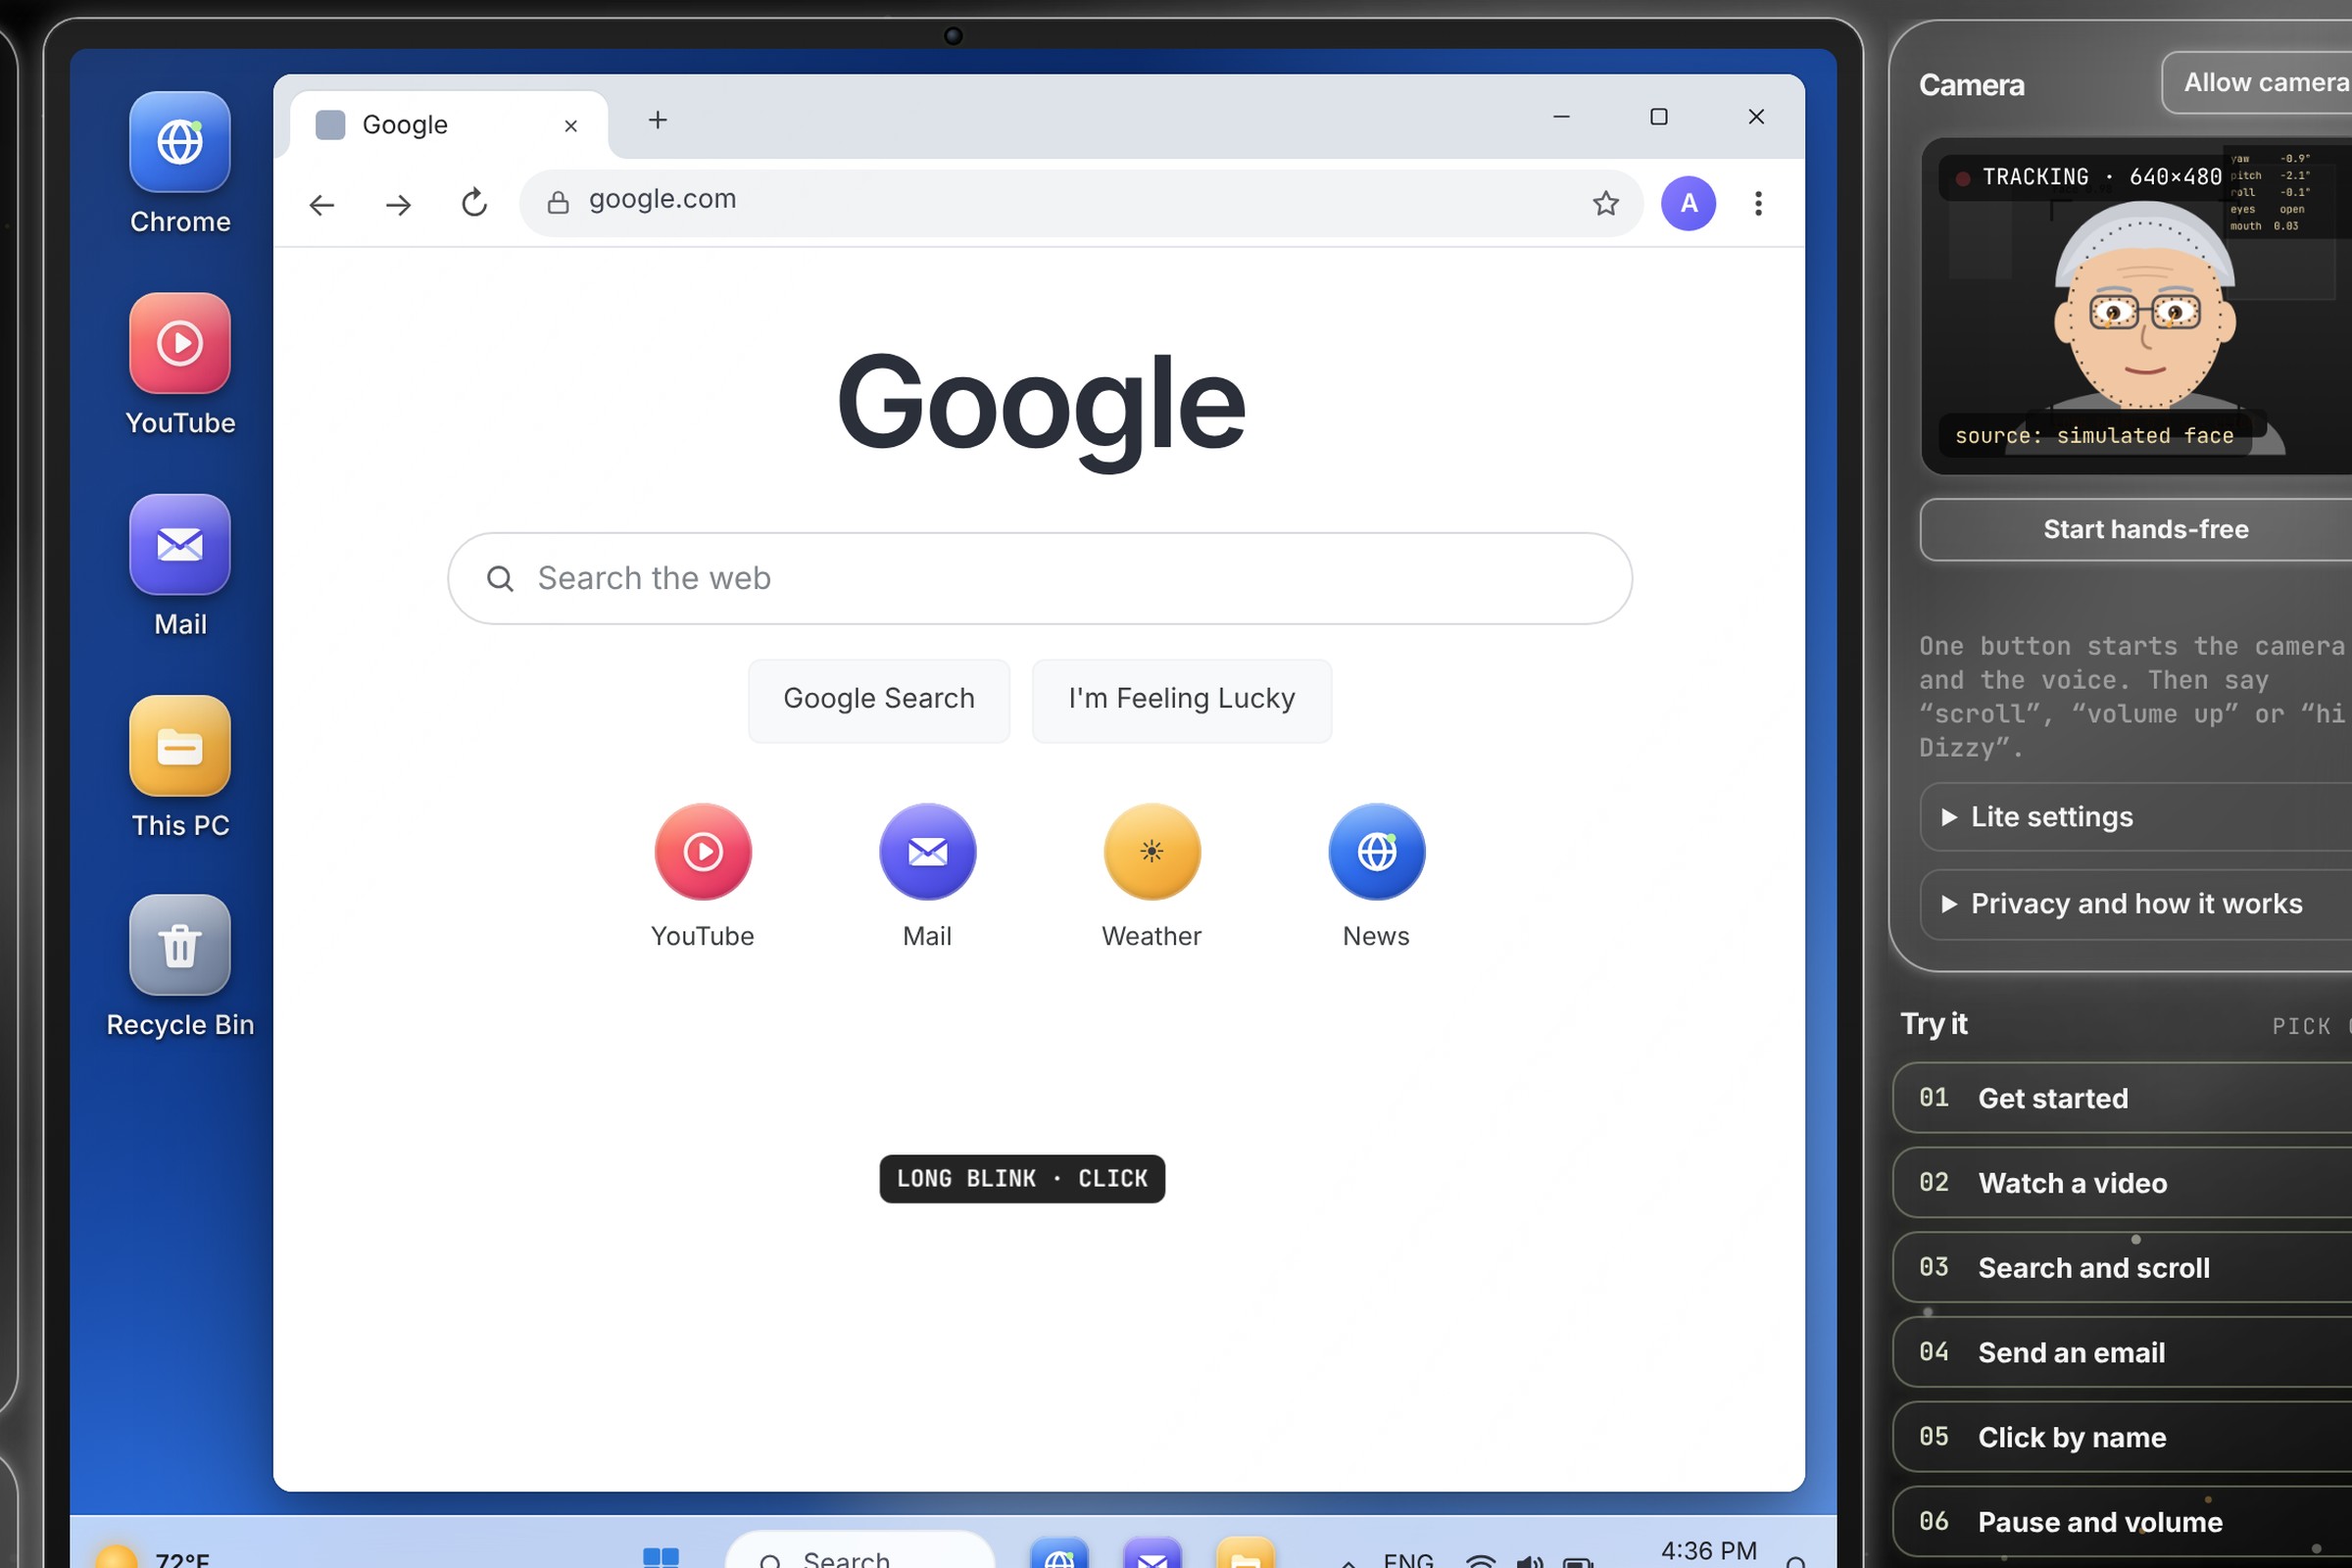
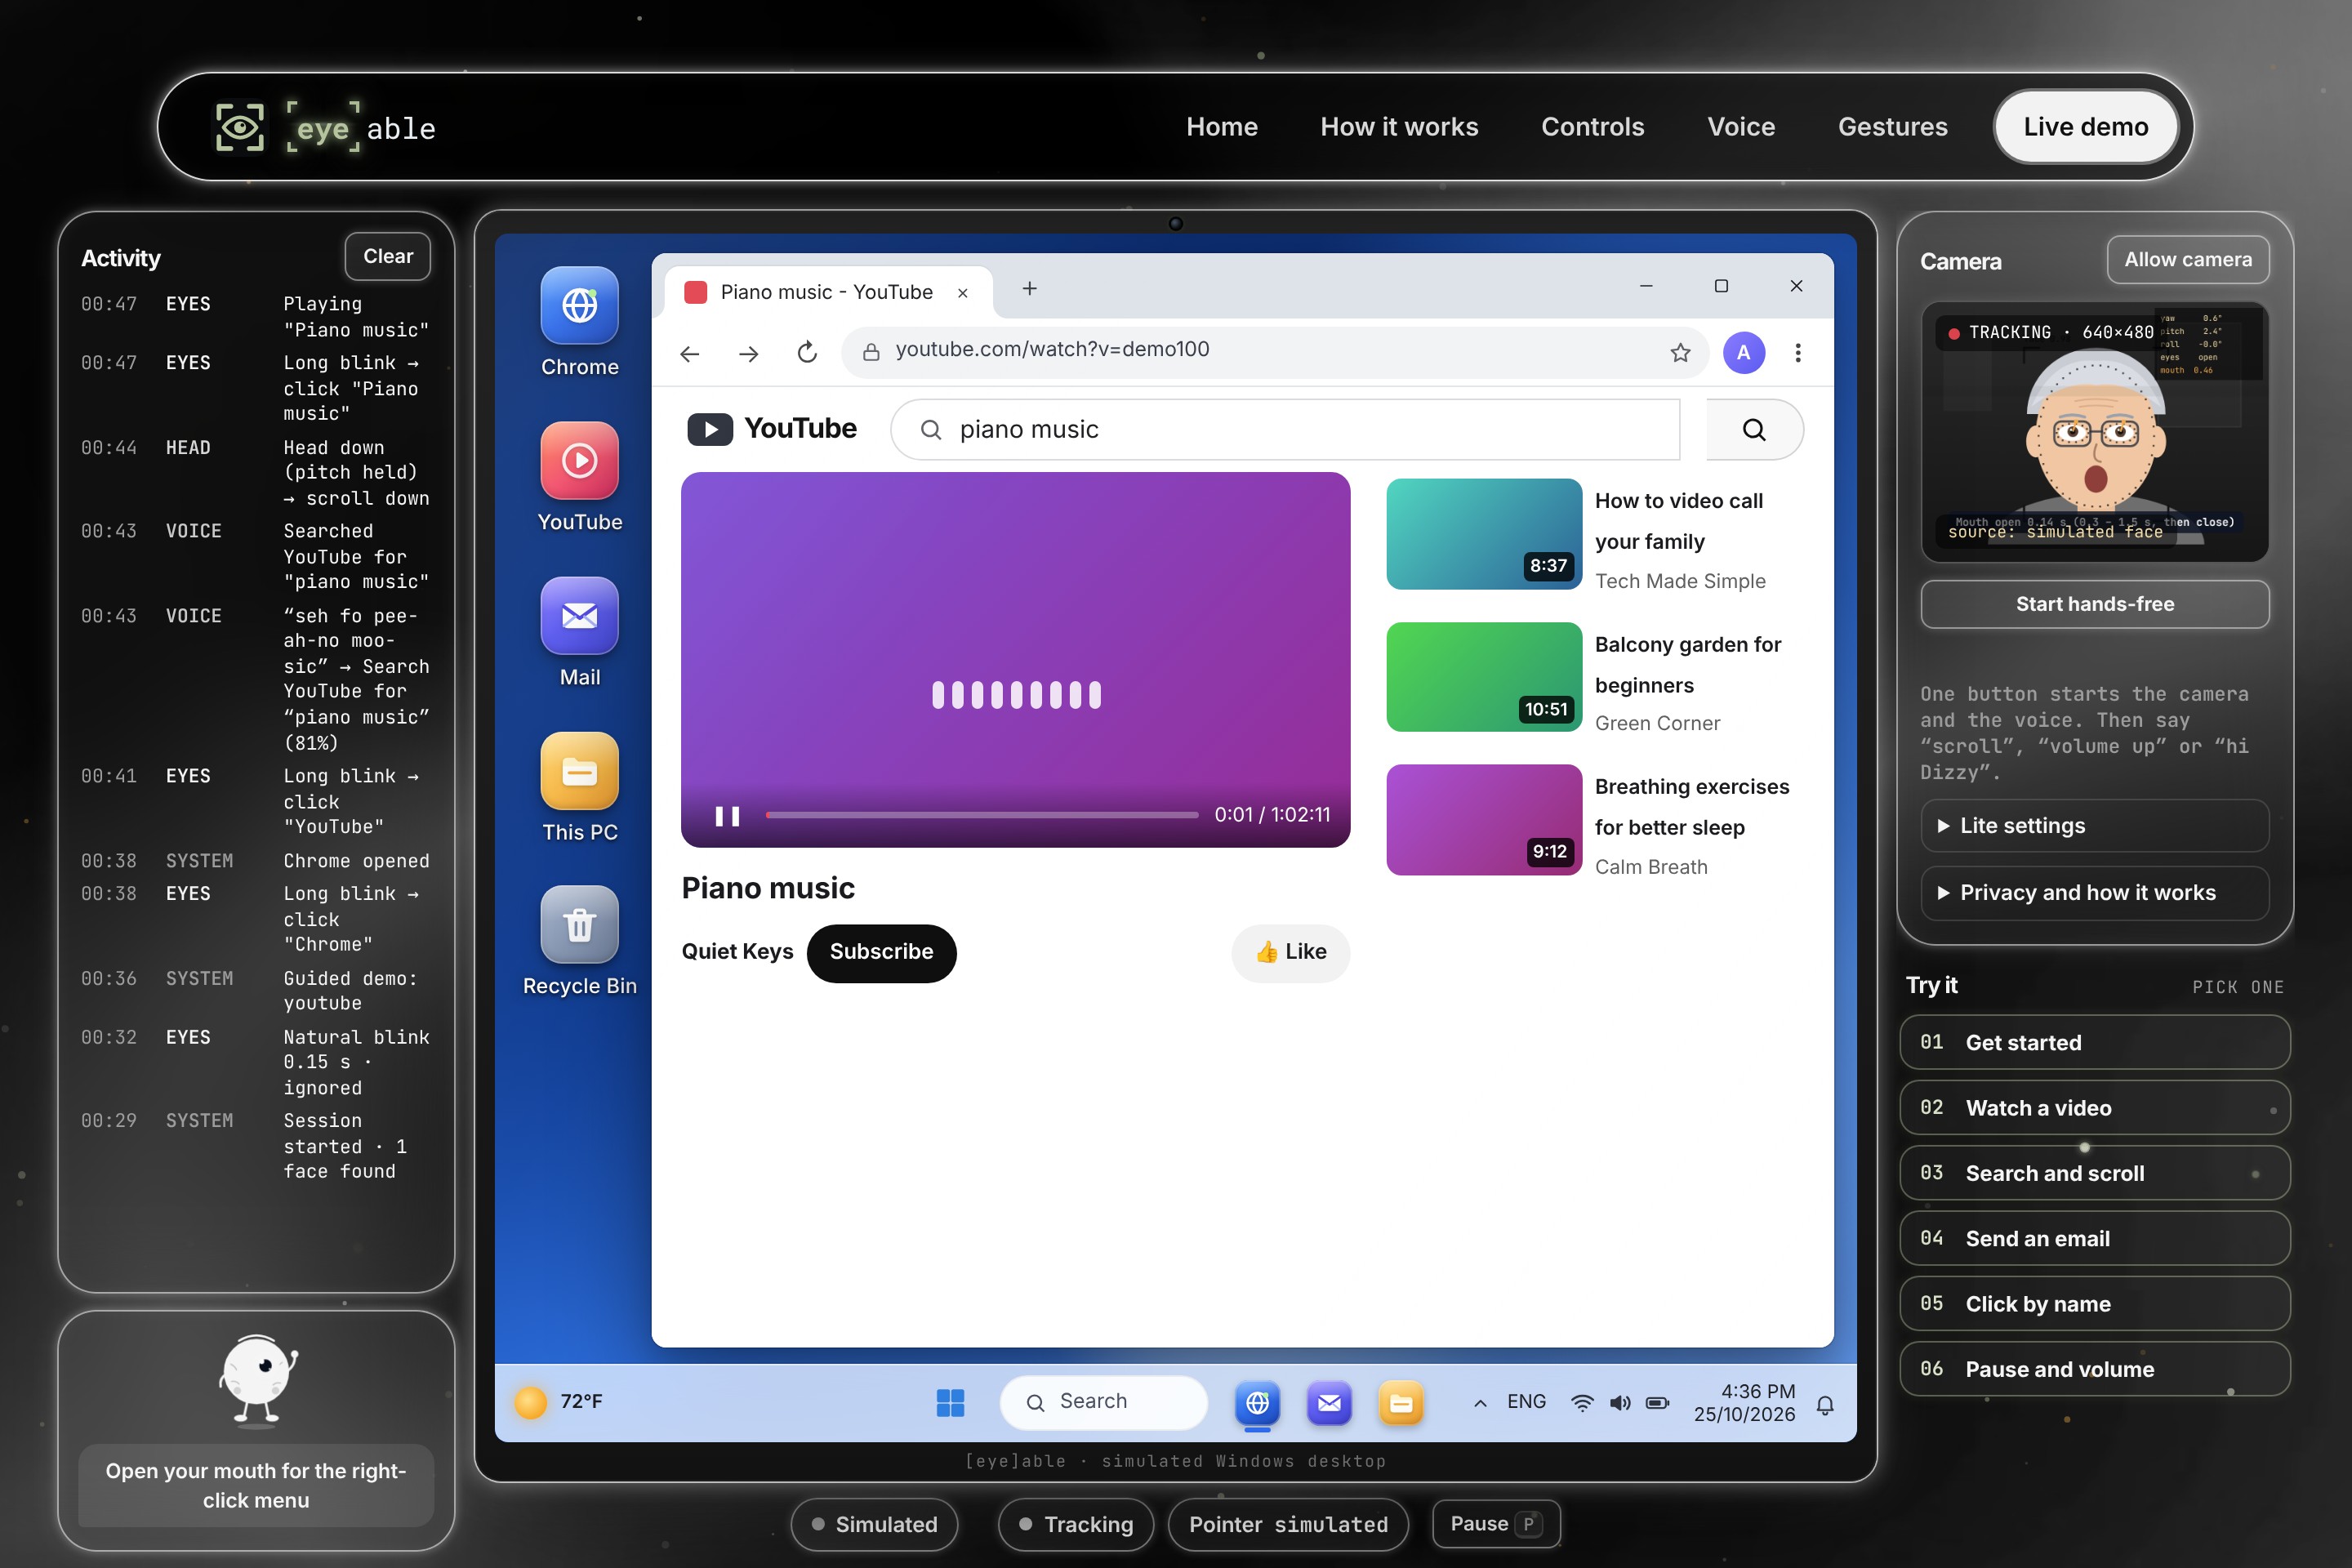
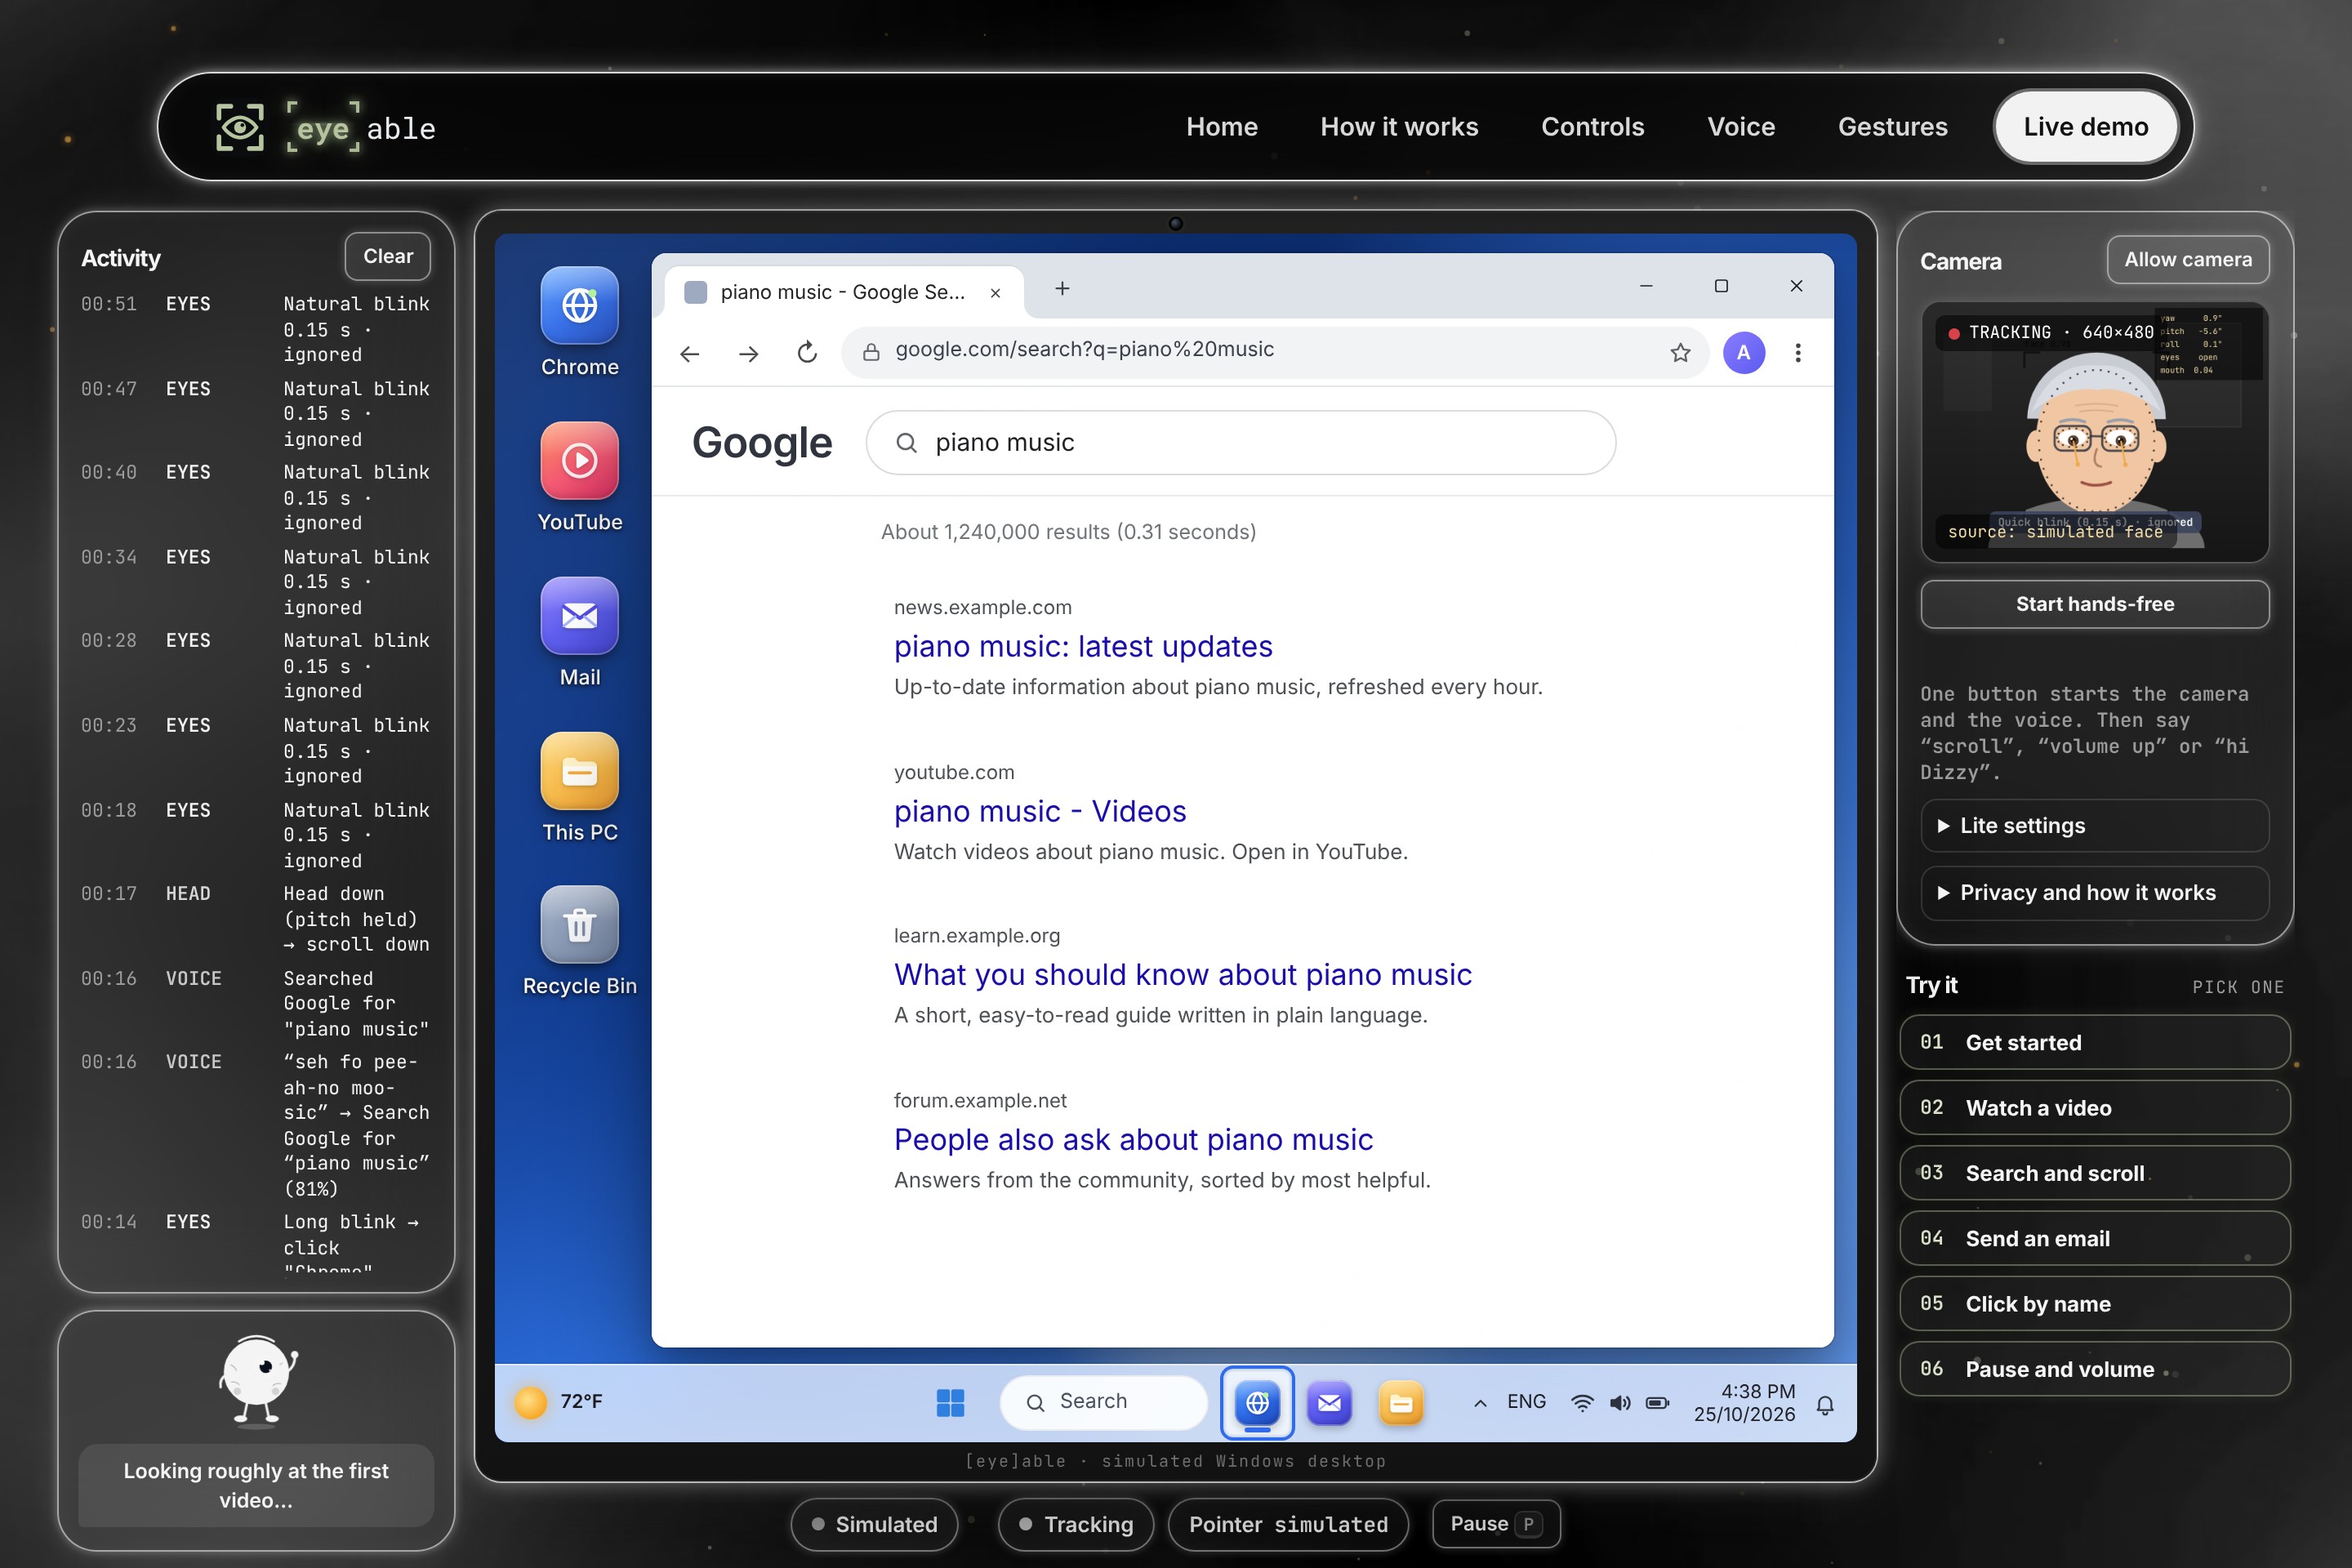
eyeable-07-live-demo-youtube-playing: Live demo: open YouTube, search and play a video without touching anything.
-
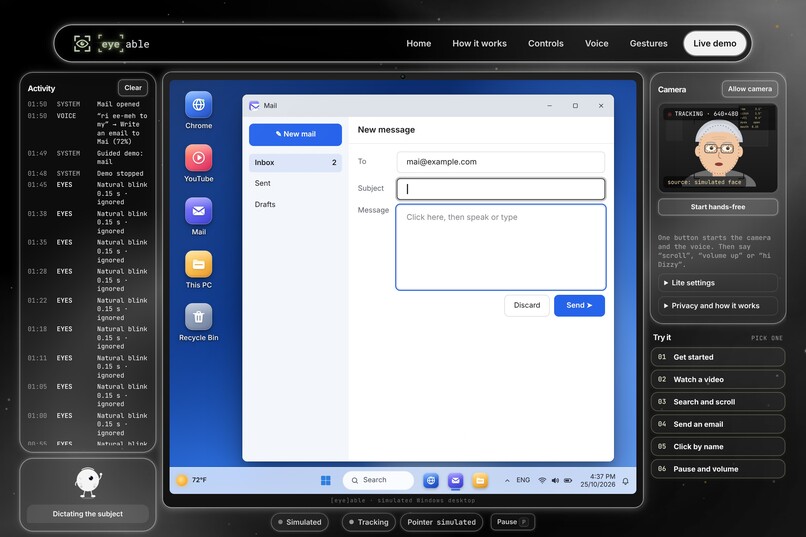
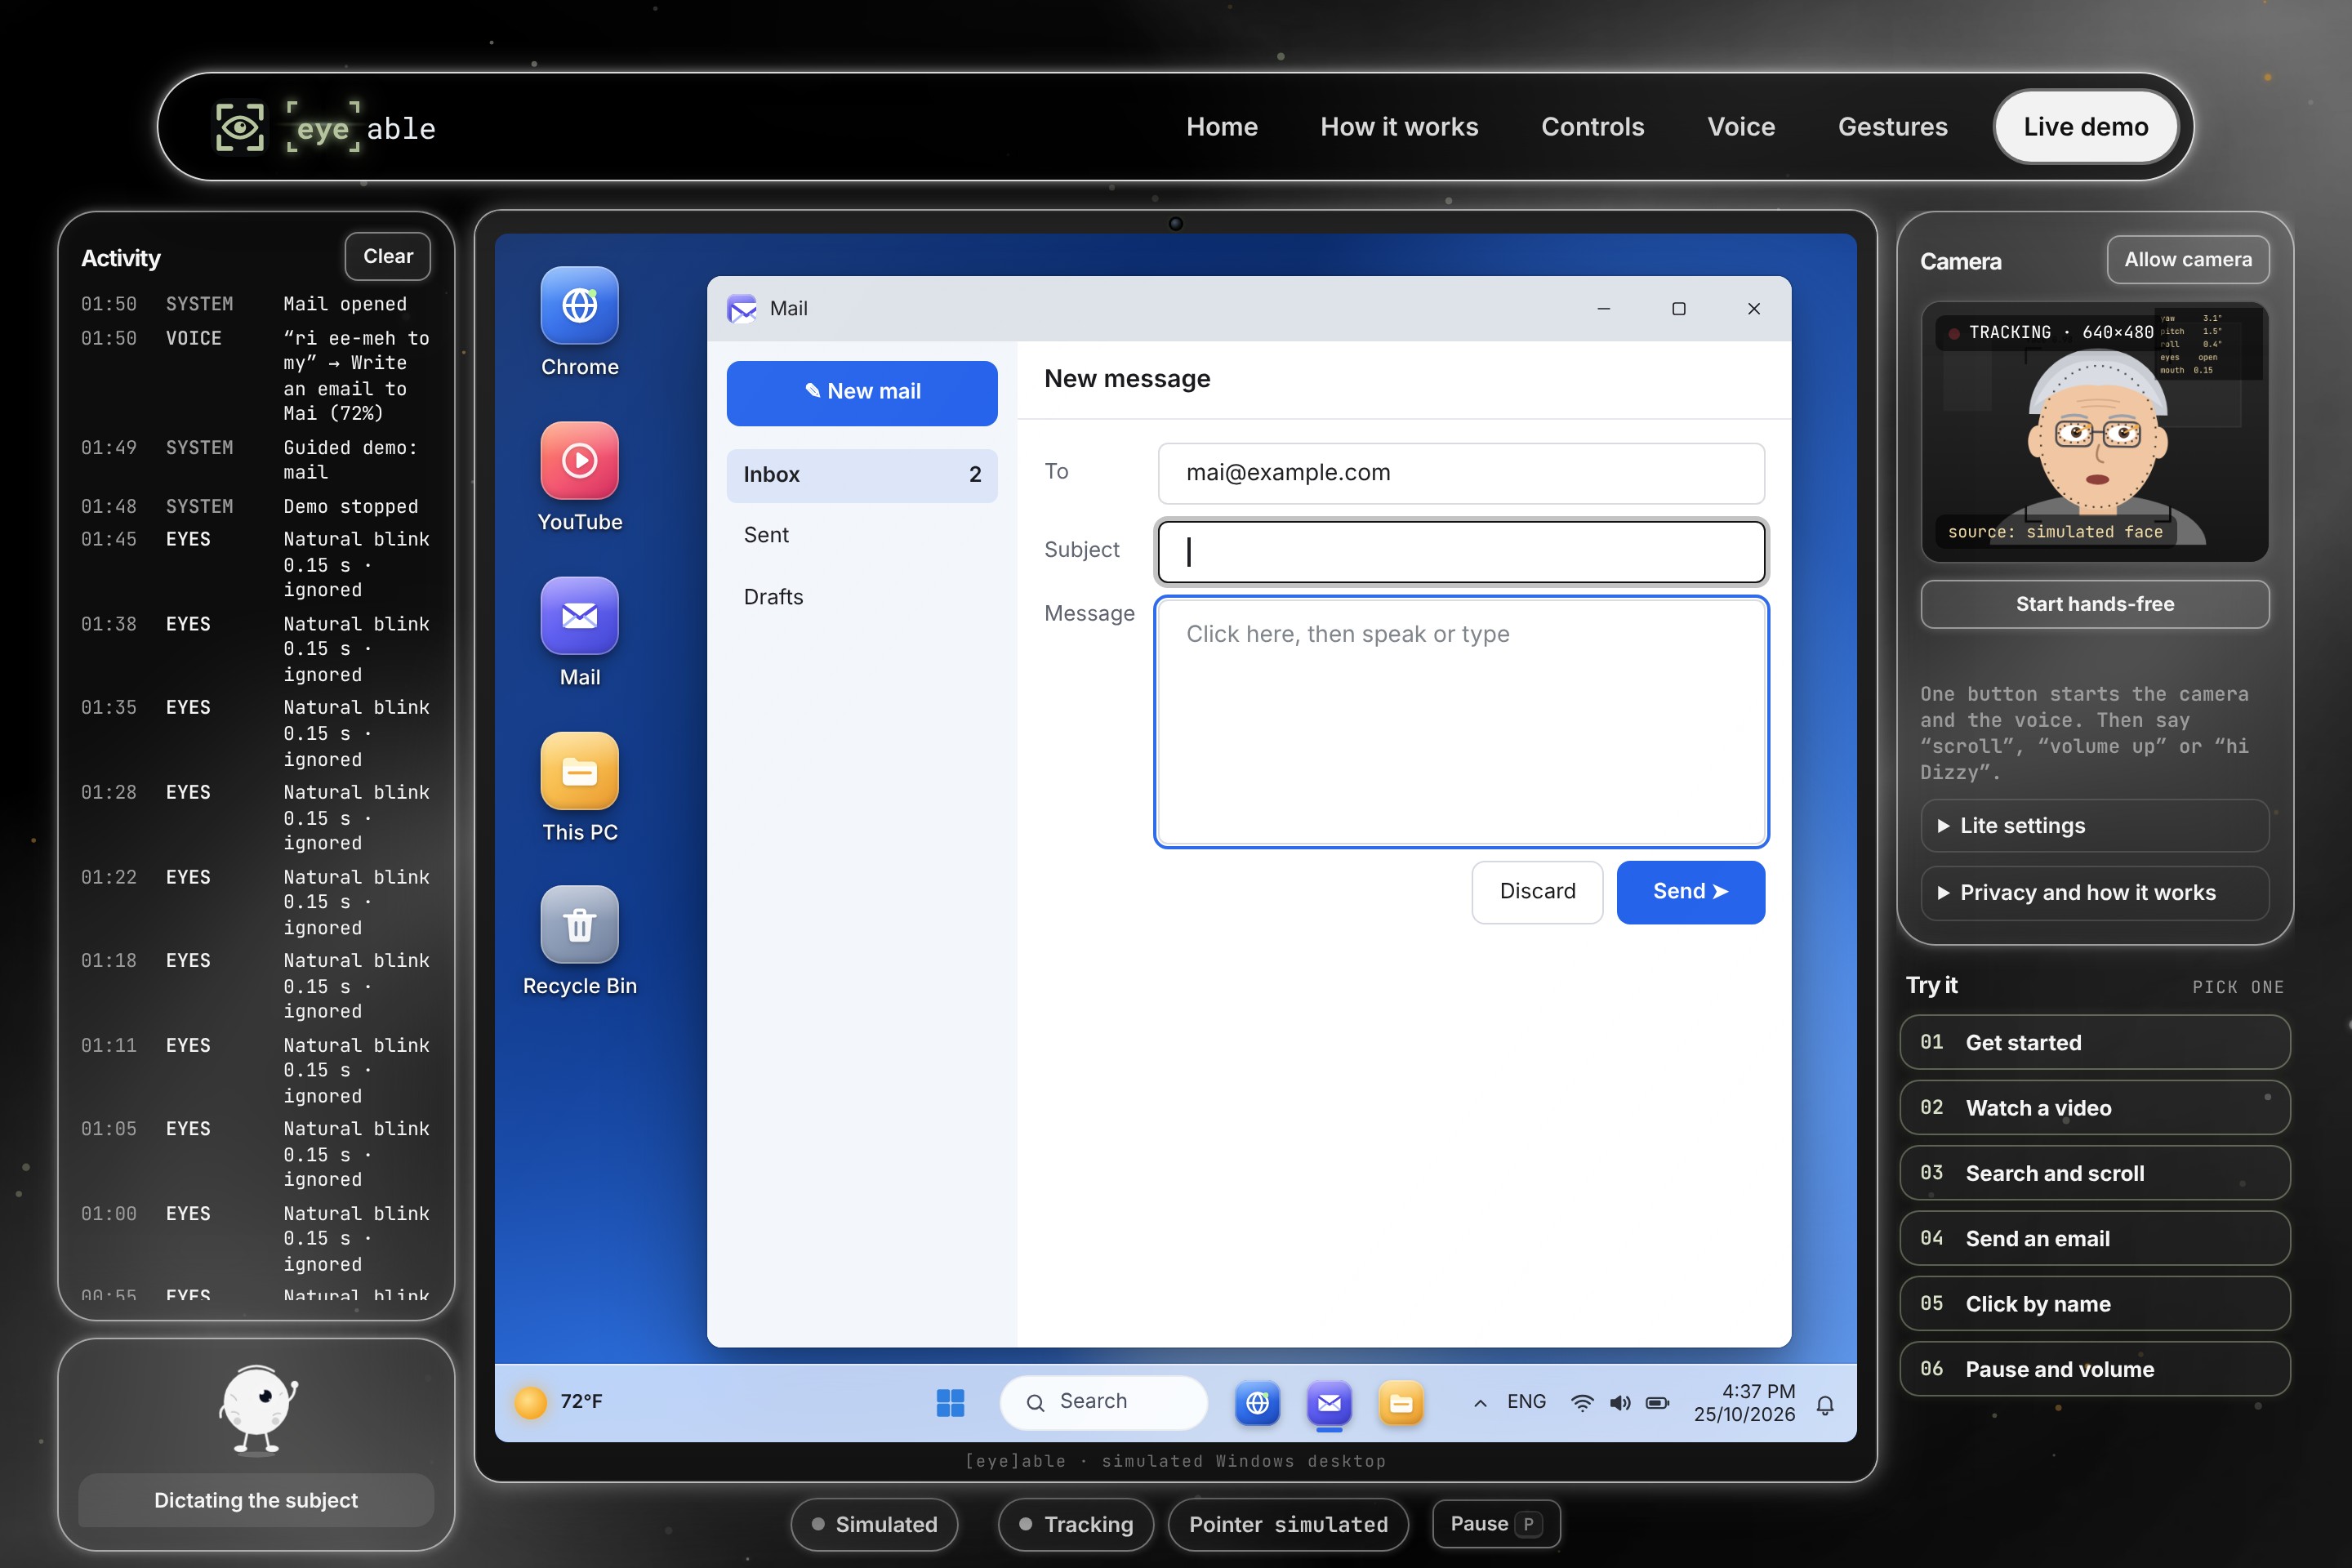
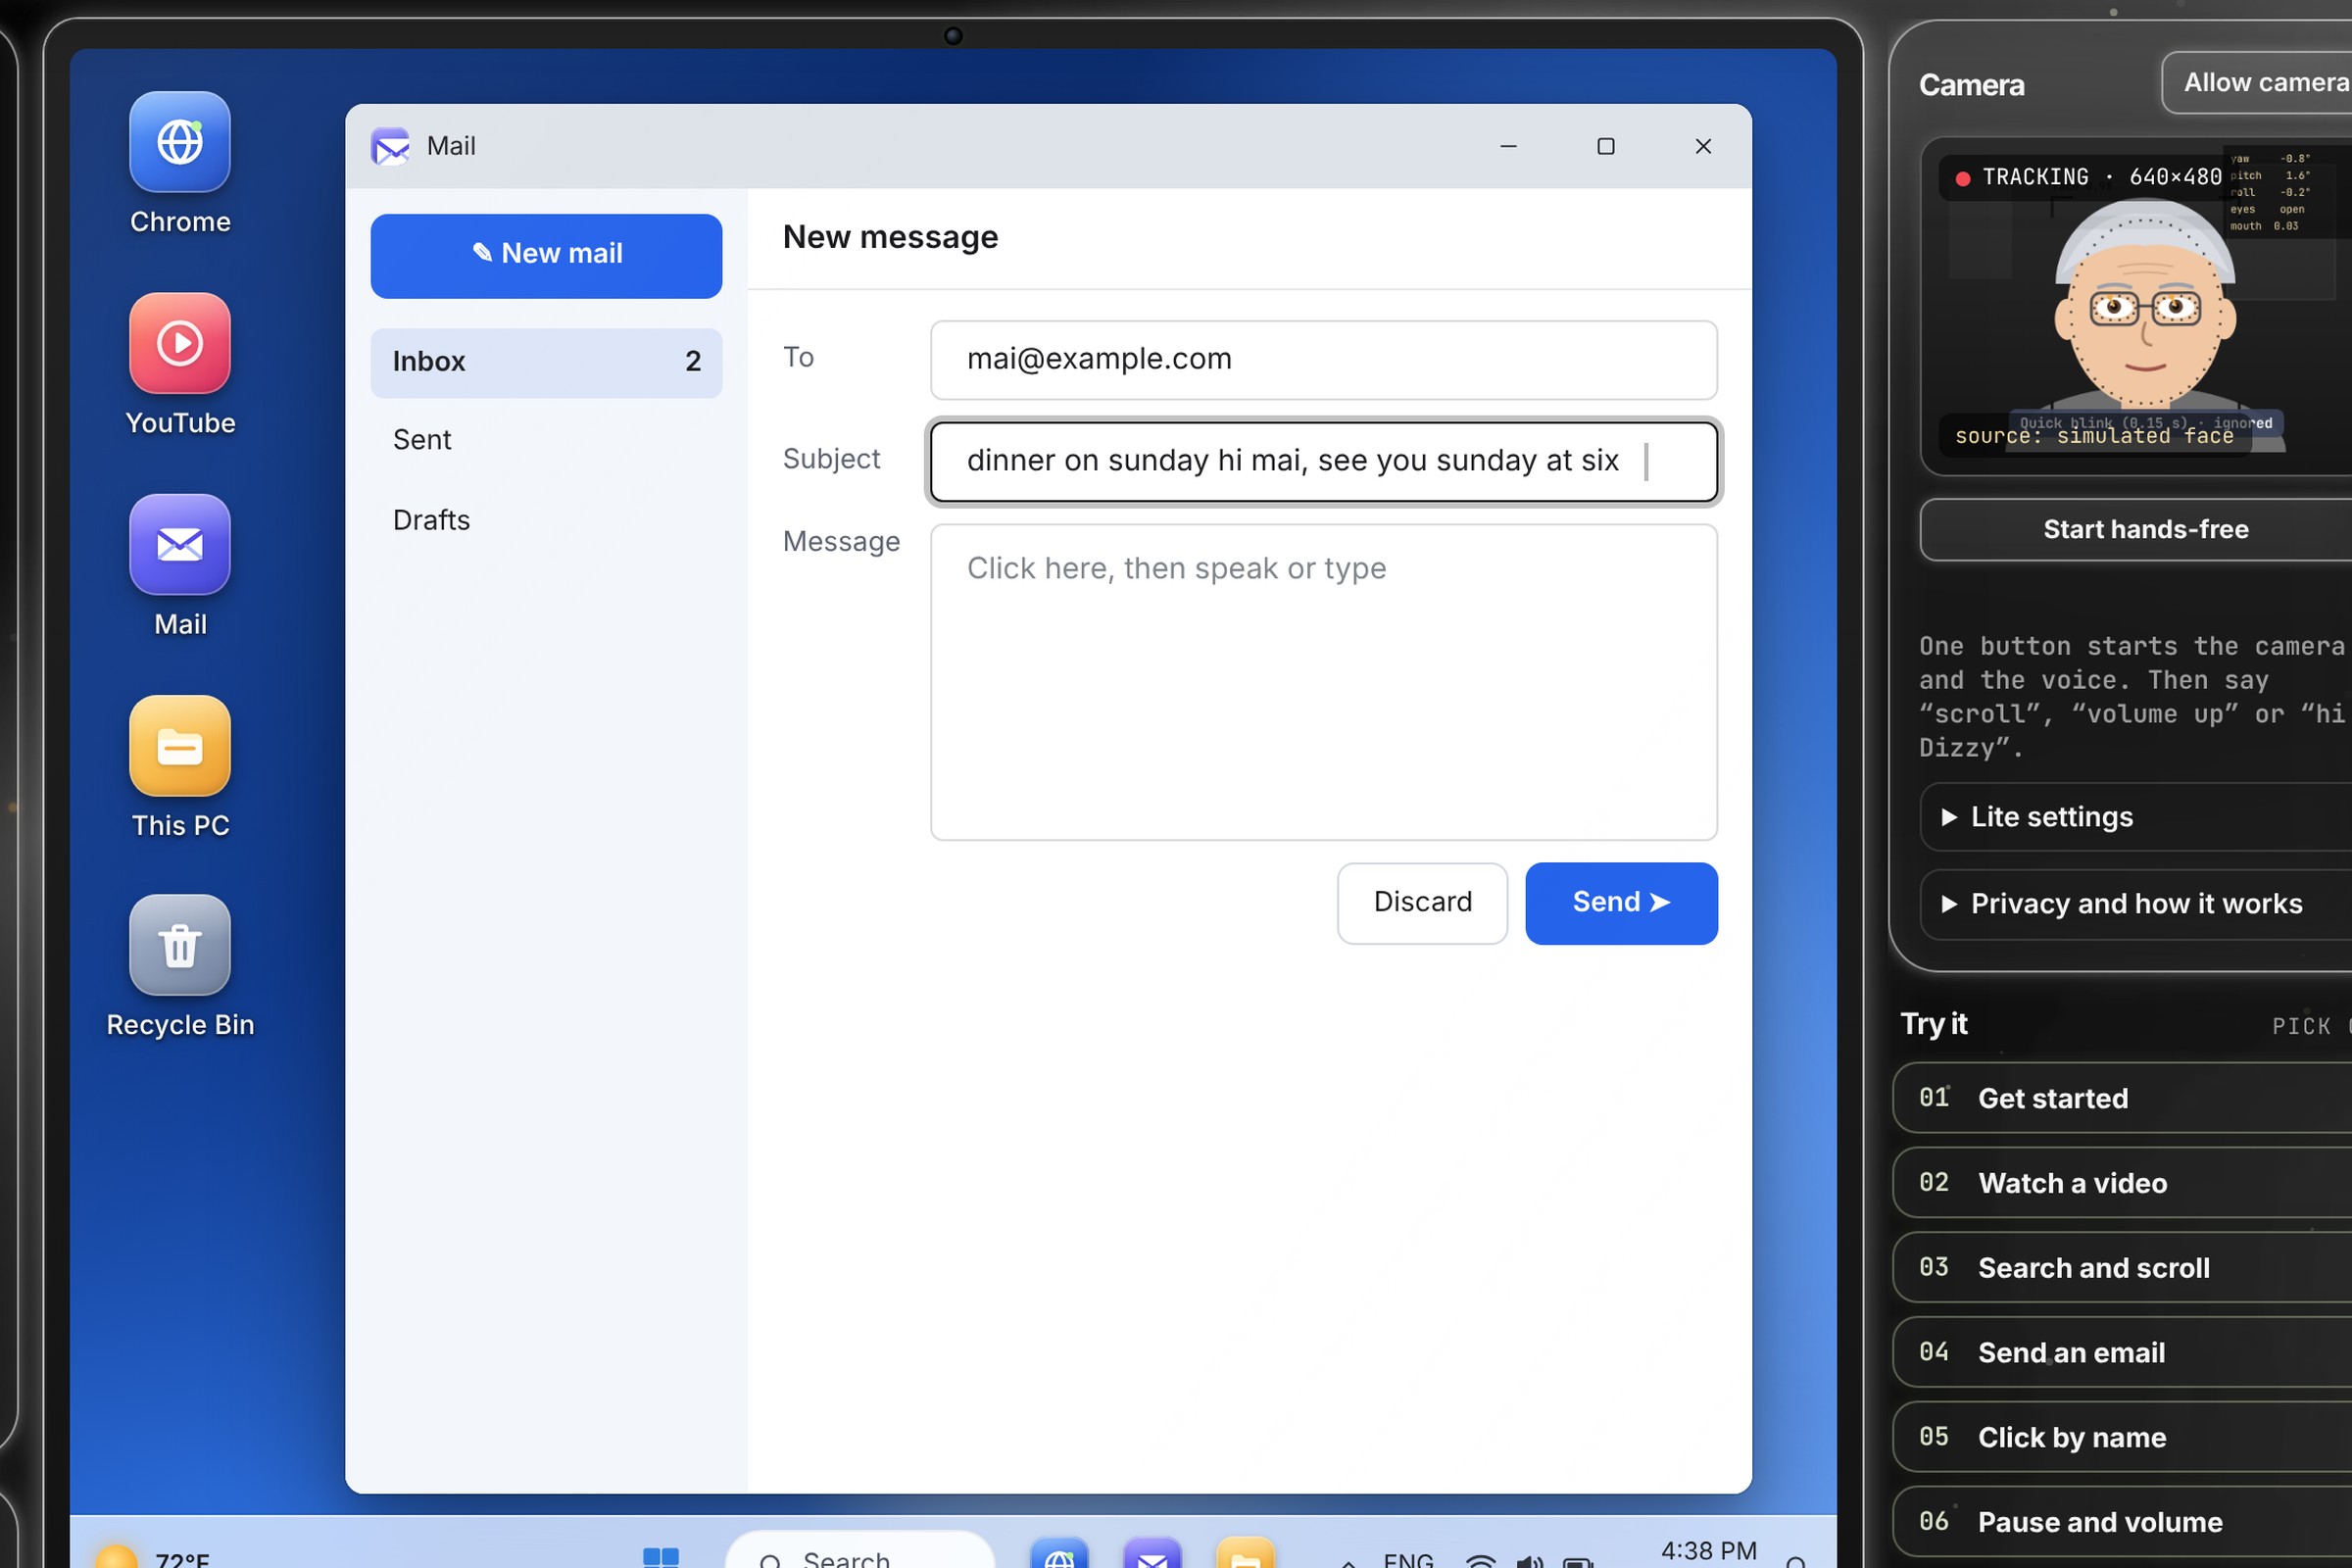
eyeable-08-live-demo-email: Live demo: start a new email by voice.
-
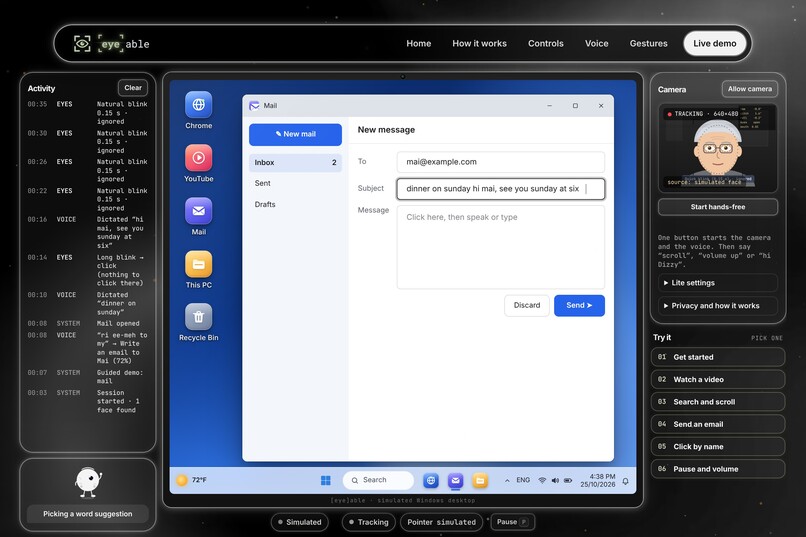
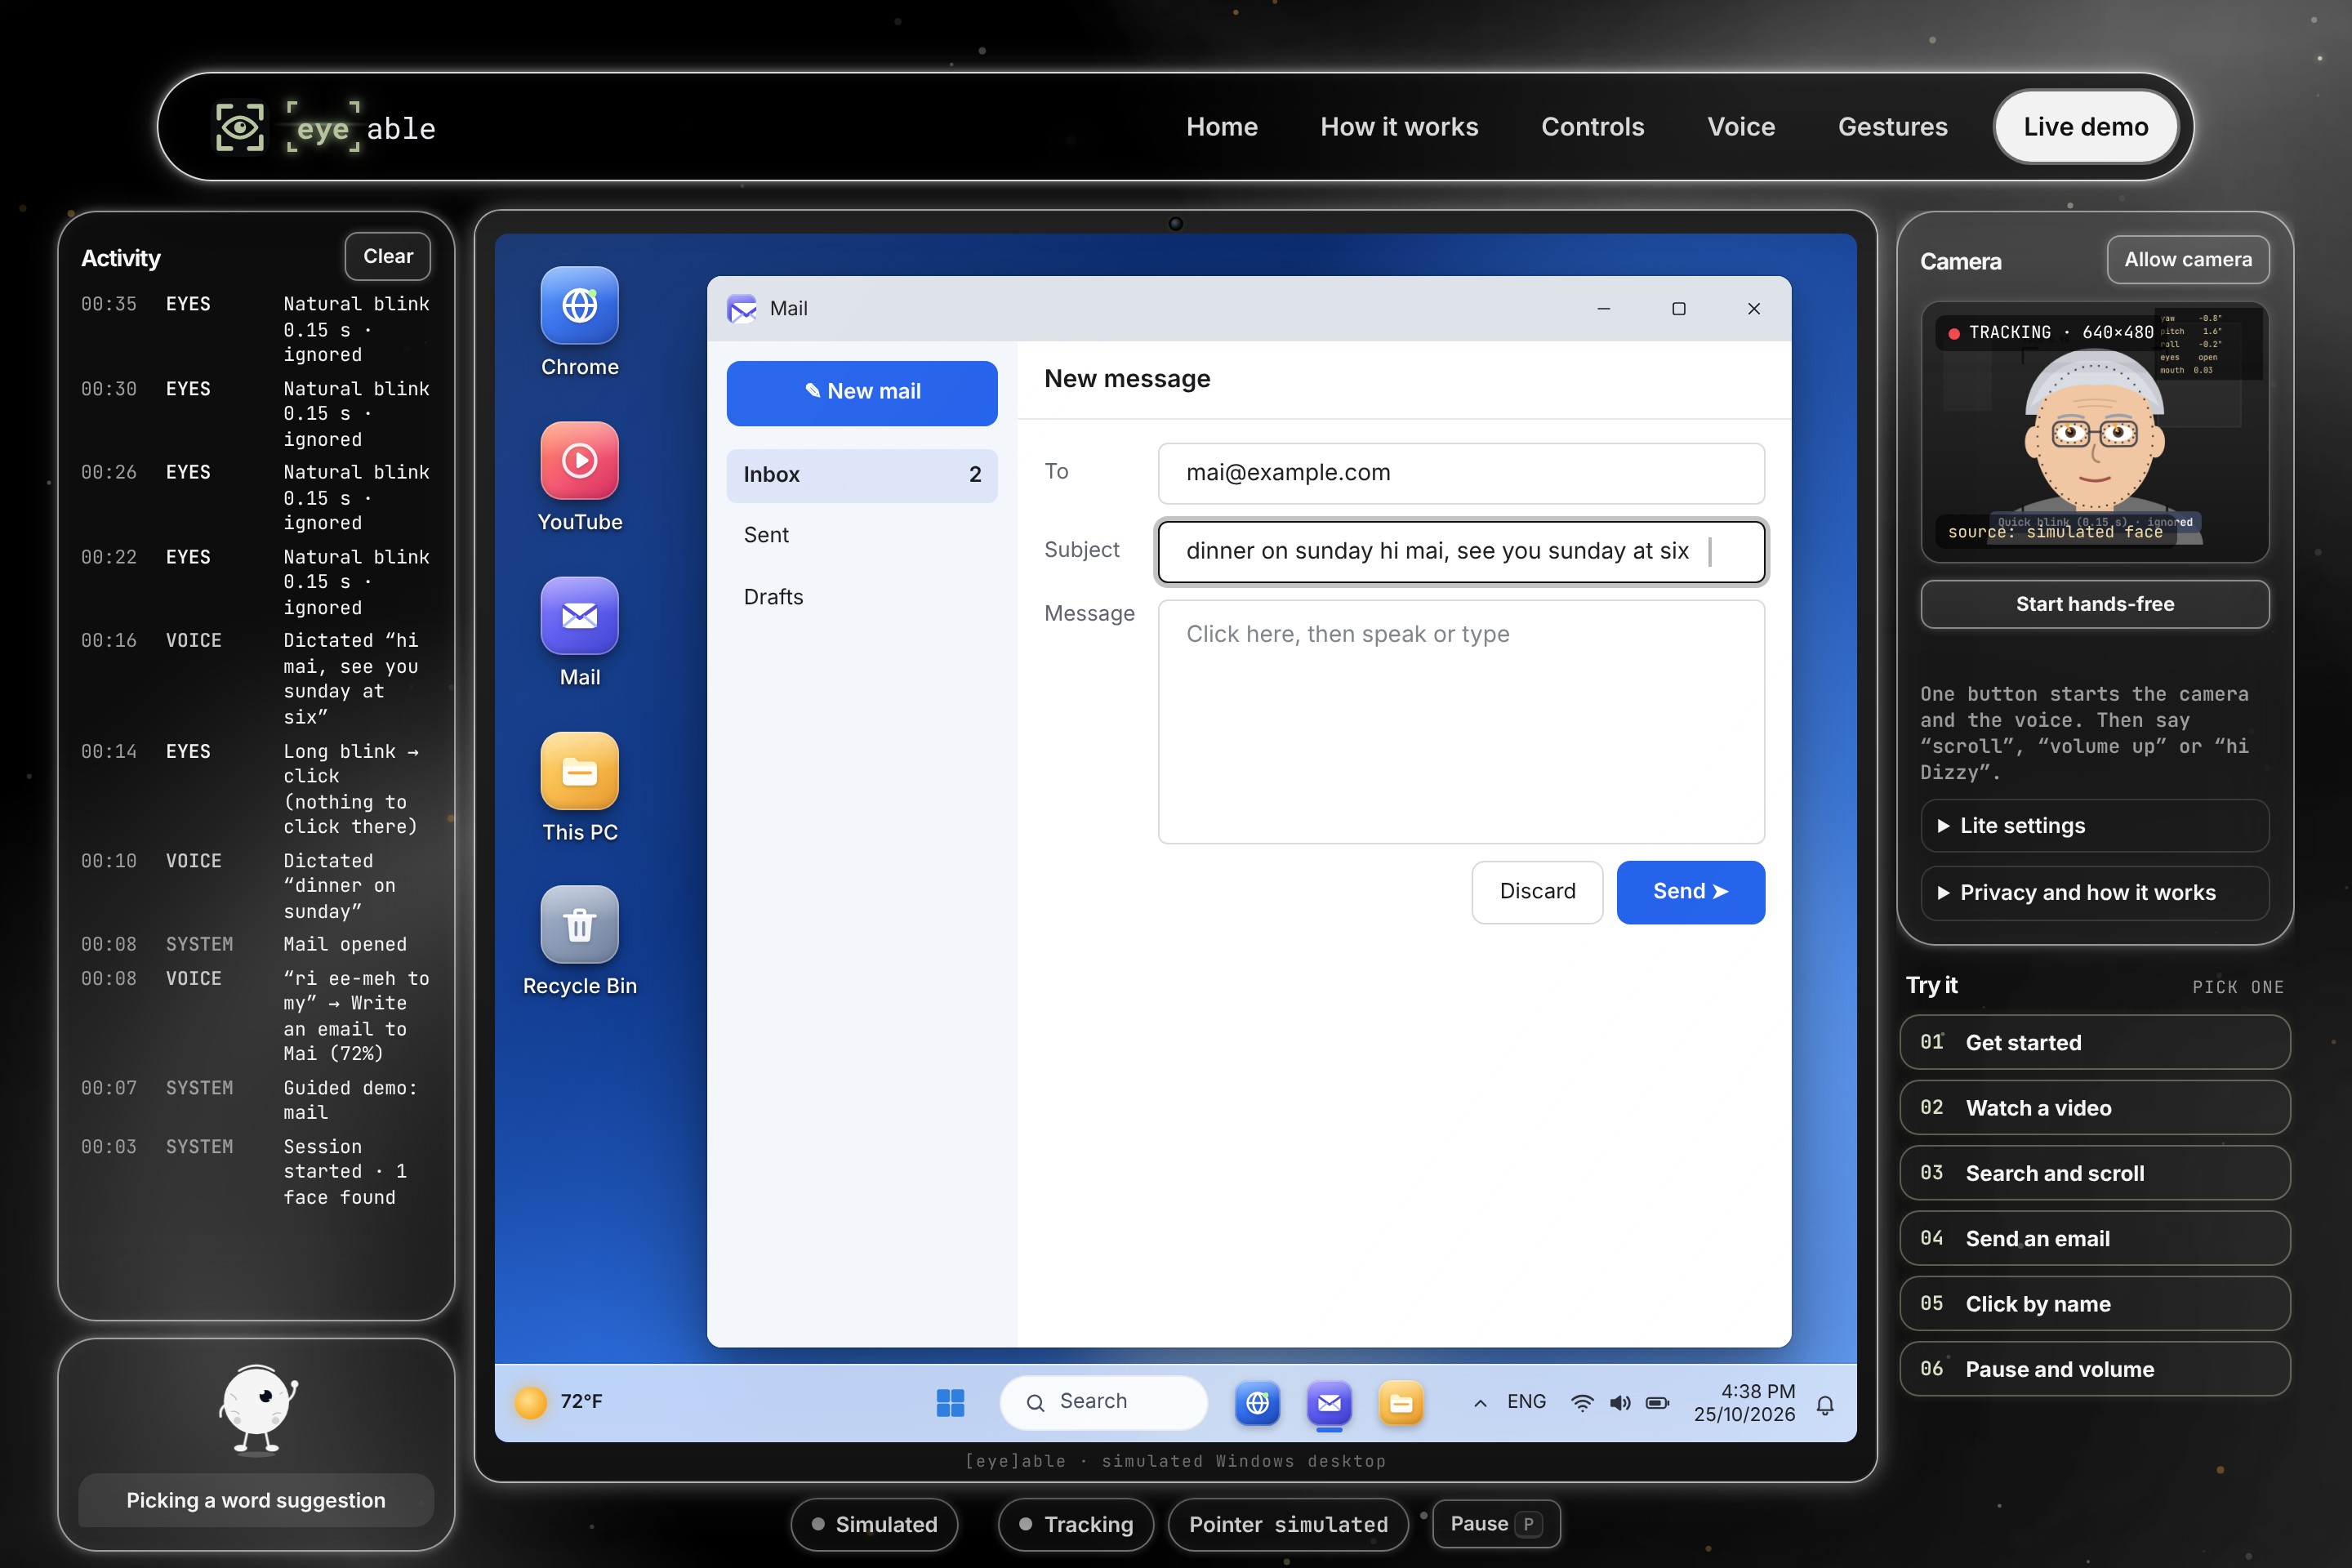
eyeable-09-live-demo-email-dictated: Live demo: dictation types the subject line as you speak.
-
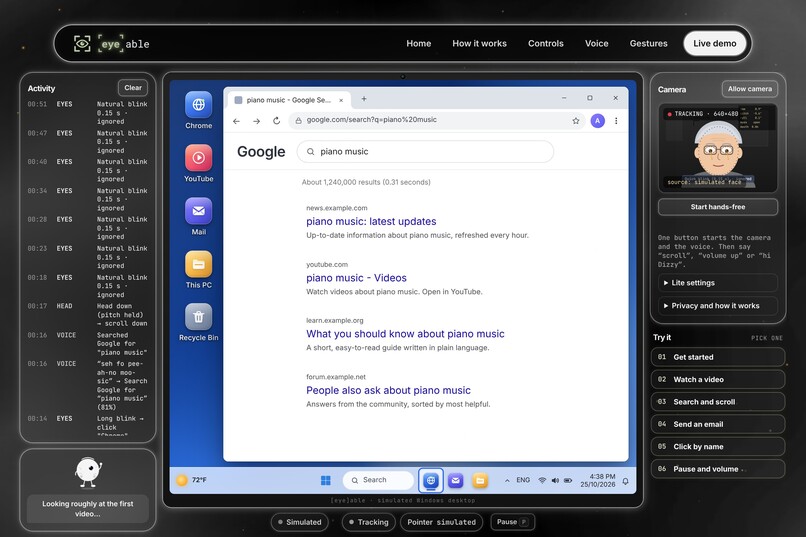
eyeable-10-live-demo-search-results: Live demo: search Google with your voice, then pick a result with your head and a blink.
-
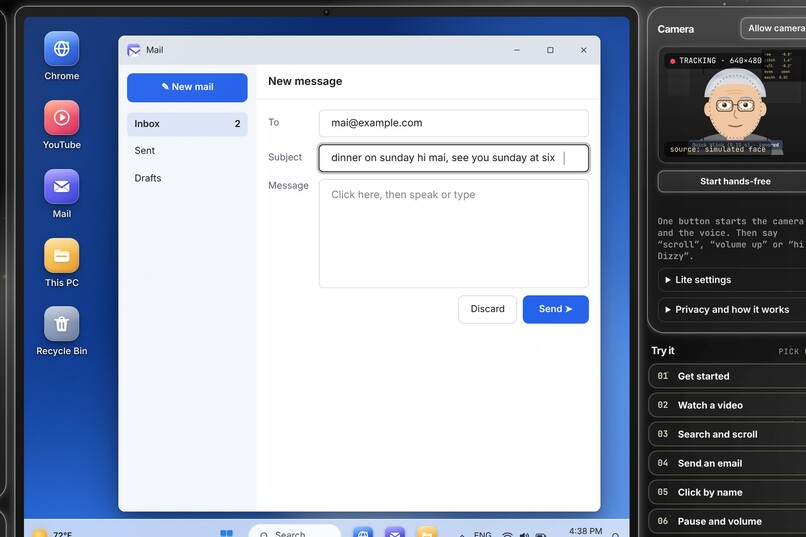
eyeable-11-closeup-dictating-an-email: Close-up: dictating an email, with a live preview before anything is sent.
-
-
Inspiration
So much of everyday life happens through a computer: catching up with a friend, finishing an assignment, or watching one more video when we probably should be finishing that assignment. We click, type, and move between these moments without thinking about what makes them possible.
When someone can't use a mouse or keyboard, those same moments become harder to reach. Having something to say is one thing. Being able to open the conversation, type it, and press Send yourself is another.
We built [eye]able for that gap, and for the people who live with it: people with motor disabilities, conditions like ALS or cerebral palsy, spinal cord injuries, or tremor, and older adults whose hands no longer cooperate. Many of them already rely on someone else for small, personal choices, like what to watch or when to reply. Dedicated assistive hardware exists, but it is often expensive and hard to get. We wanted to start with equipment almost everyone already has, a laptop webcam and microphone, and make it do something new.
For our team, the reason always comes back to the person using it. If the work we put into moving a cursor or recognizing a word makes an everyday task a little easier, more of the choices stay with them.
What it does
[eye]able lets someone control a Windows computer completely hands-free, through head movement, deliberate blinks, and voice.
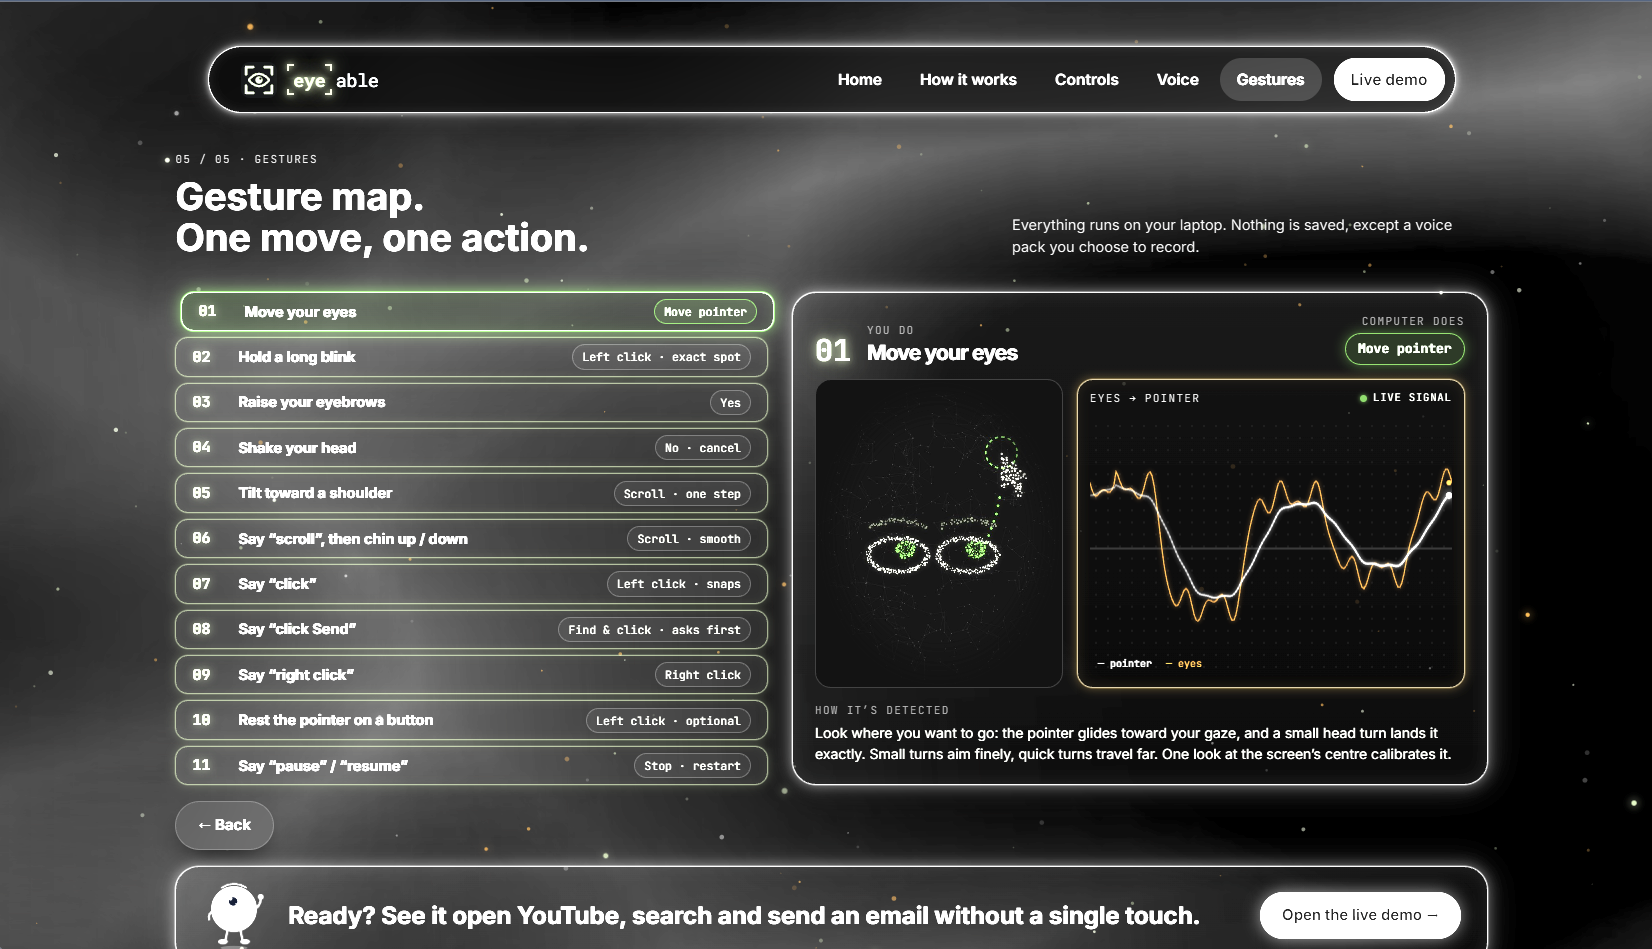
| You do | The computer does |
|---|---|
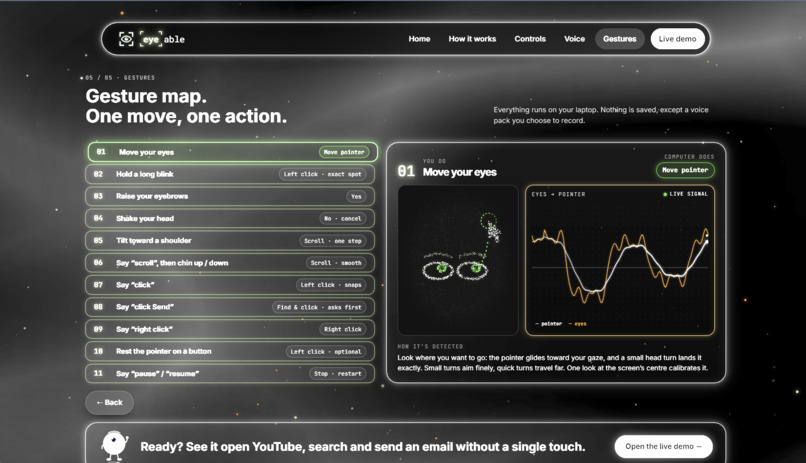
| Turn your head | Moves the cursor: small turns aim precisely, quick turns go far. An optional eye "pull" nudges it toward where you look. |
| Hold a long blink (≈0.4–1.6 s) | Left click on the exact spot. Normal blinks never click. |
| Say a command | "open Chrome", "volume up", "right click", "pause", and more |
| Say "click Send" | An AI model finds the Send button on screen and asks before clicking |
| Say "scroll", then tilt your chin | Smooth scrolling: tilt further to scroll faster, say "stop" to end |
| Say "hi Dizzy", then speak | Dictation with a live preview: "yes" types it, "no" discards it |
Safety is built in. Risky or irreversible actions always ask for a yes or no first. If nobody answers within 12 seconds, nothing happens.
We shipped two ways to use it:
| Version | What it does | Requirements |
|---|---|---|
| Windows app | Controls the real computer | One-click installer picks a setup for your graphics card: full features on a 16 GB NVIDIA GPU, a lighter version on ordinary laptops |
| Live demo (website) | Guided tasks on a simulated Windows desktop: watch YouTube, search and scroll, send an email, click a button by name | Nothing to install; runs in the browser and only controls the demo page |
How we built it
Our five-person team built [eye]able in 48 hours at Gator Hack V (UF AI Days 2026).
Engine (Python). Independent modules for vision, speech, and actions talk through an event bus, so each part could be built and improved on its own during the hackathon.
- Vision: MediaPipe Face Landmarker tracks 478 facial points per frame. A One Euro filter smooths pointer movement without adding lag, nose assist helps reach screen edges, and a one-look calibration sets your neutral position in seconds.
- Speech: Whisper (via faster-whisper) transcribes with a live preview. UI-Venus 1.5 reads the screen to find buttons by name. Optional Qwen2.5 cleanup tidies dictation, and you can always keep your original words.
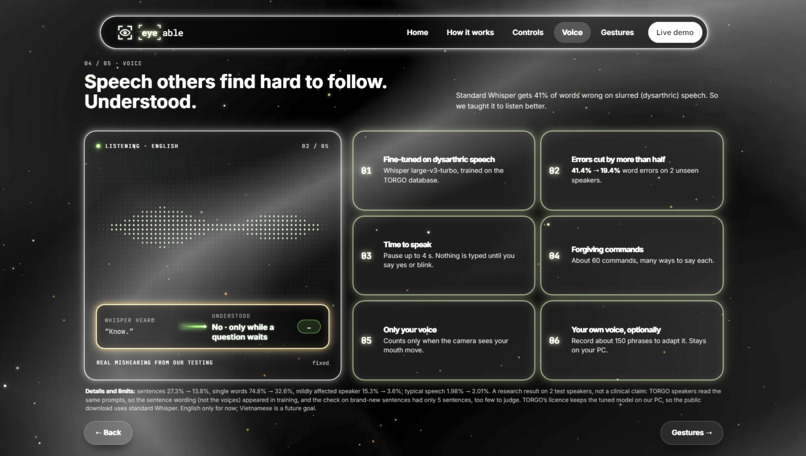
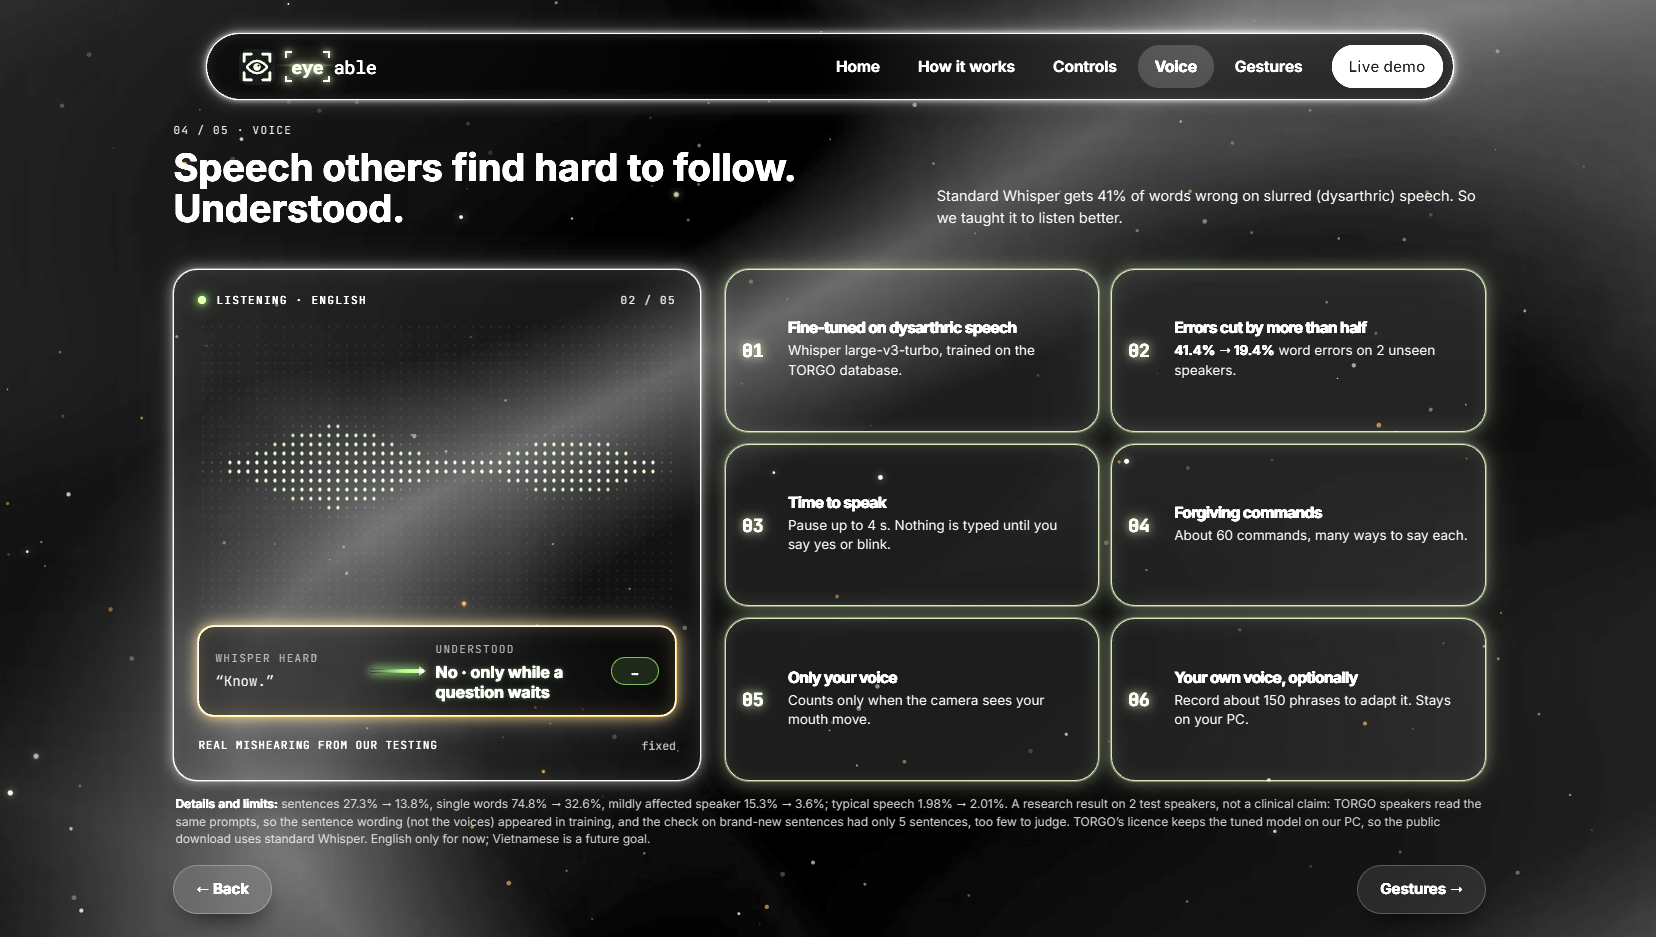
- Fine-tuning for dysarthric speech: standard speech recognition struggles with slurred speech, so we fine-tuned Whisper on TORGO, a research dataset of dysarthric speech, and mixed in typical speech so ordinary voices stay accurate.
- Privacy: in the Windows app every model runs locally. Camera frames, audio, and screenshots stay in memory and are never saved or uploaded.
Website (HTML/CSS/JavaScript). A five-page explainer plus the Live demo, which runs face tracking and speech recognition right in the browser, with animated visuals that show what each gesture's signal looks like as it crosses its threshold.
Built with
| Layer | Technology | What we used it for |
|---|---|---|
| Core engine | Python | Main app logic; vision, speech, and action modules talk through an event bus |
| Face and head tracking | MediaPipe Face Landmarker | Tracks 478 facial points per frame to read head movement, blinks, brows, and mouth |
| Face and head tracking | OpenCV | Captures and processes webcam frames |
| Face and head tracking | One Euro filter | Smooths the cursor so it stays steady without feeling laggy |
| Speech recognition | Whisper (via faster-whisper) | Fast, local speech-to-text with a live preview |
| Speech recognition | TORGO dataset | Dysarthric speech used to fine-tune Whisper for people whose speech is affected |
| Speech recognition | LibriSpeech dataset | Typical speech mixed into training so ordinary voices stay accurate |
| AI helpers | UI-Venus 1.5 | Reads the screen to find a button by name, e.g. "click Send" |
| AI helpers | Qwen2.5 | Optional cleanup of dictated text; you can always keep your original words |
| Website and Live demo | HTML · CSS · JavaScript | Five-page site plus a simulated Windows desktop you can try with no install |
| Website and Live demo | Canvas | Animated dot-art visuals and live signal charts for each gesture |
| Website and Live demo | MediaPipe (browser) + Web Speech API | Face tracking and voice commands inside the browser demo |
| Collaboration | Git / GitHub | Version control and teamwork across 5 people in 48 hours |
Designing for the people who use it
Accessibility was the core requirement, not a feature we added at the end.
| Principle | How [eye]able does it |
|---|---|
| Clicks must be intentional | Long blinks instead of normal ones, a pointer that freezes while your eyes are closed, and confirmations on anything risky |
| You can always see and undo | Dictation is previewed before typing; "no" discards it and "use original" restores your exact words |
| Several ways to do each thing | Head, blink, and voice overlap, so people can use whatever their body allows |
| No special hardware | Works with a normal laptop webcam and microphone |
| Try before installing | The Live demo teaches every control in the browser before anyone downloads the app |
Challenges we ran into
| Challenge | What we did |
|---|---|
| Webcam gaze alone was too imprecise to aim a cursor | Redesigned around head movement and deliberate blinks, keeping the eyes as an optional helper |
| Telling intentional blinks from natural ones, with thresholds tuned to one teammate's face | Learned that per-user calibration is essential and made it a top priority |
| Standard speech recognition broke on dysarthric speech | Fine-tuned Whisper on the TORGO dataset |
| Fitting several AI models on one laptop GPU | Built an installer that picks a full or a light configuration |
| Building a convincing browser version | Created a simulated Windows desktop with guided tasks |
| Preventing accidental actions | Yes-or-no confirmations on risky actions, with a 12-second timeout that does nothing |
Accomplishments that we're proud of
- A working Windows app and a browser demo, both built in 48 hours.
- Our Whisper fine-tune halved errors on dysarthric speech for speakers it never saw in training, without hurting typical speech.
- A safety model where nothing irreversible happens without a yes.
| Word error rate (lower is better) | Standard Whisper | Our fine-tune |
|---|---|---|
| Dysarthric speech, sentences (unseen speakers) | 27.3% | 13.8% |
| Mildly affected speaker | 15.3% | 3.6% |
| Typical speech | 1.98% | 2.01% |
Honest caveat: this is a research result on a small dataset (two test speakers, with sentence prompts repeated across speakers), not a clinical claim. TORGO's licence keeps the tuned model on our own PC, so the public download uses standard Whisper.
What we learned
Making a control respond is only part of making it usable. We also have to know when someone didn't mean a command, let them review the result, and give them an easy way to say no.
We also learned to be honest about what we can't yet claim. Our development experience and speech benchmarks can't prove the whole system works well for the people it's meant for. Only those people can tell us that.
What's next for [eye]able
| Next step | Why it matters |
|---|---|
| Test with the people we built it for | We have not yet tested with people who cannot use their hands. Working with them and occupational therapists is our most important next step. |
| Per-user blink and head calibration | So clicks and pointing fit each person's face and movement |
| Measure tracking accuracy | To back our design with real numbers |
| More languages, including Vietnamese | The current app supports English only |
| macOS support and a signed installer | The current app supports Windows only |
We want more everyday computer tasks to become things people can choose to do for themselves.


Log in or sign up for Devpost to join the conversation.