Inspiration
Every beauty marketplace says its sellers are "trusted," "curated," or "expert." None of them say what was measured.
That word does a lot of work and carries no information. A seller with good photography and a returns policy gets the same badge as one who actually understands skin. The buyer has no way to tell them apart, so the signal collapses — and the person selling snake oil ranks alongside the person who knows what a compromised barrier looks like.
When we looked at the YouCam Skin Analysis API, the obvious build was a consumer scanner: point a camera at your face, get eight scores, see some products. That is a fine feature and roughly what we expected most entries to be.
The more interesting question was: the API measures skin objectively — so why only point it at buyers? If a machine can grade a face, it can grade whether a seller can grade a face. That turns "trusted seller" from a claim into a test result. It is checkable, it is comparable, and it is very hard to fake. That inversion is the product.
What it does
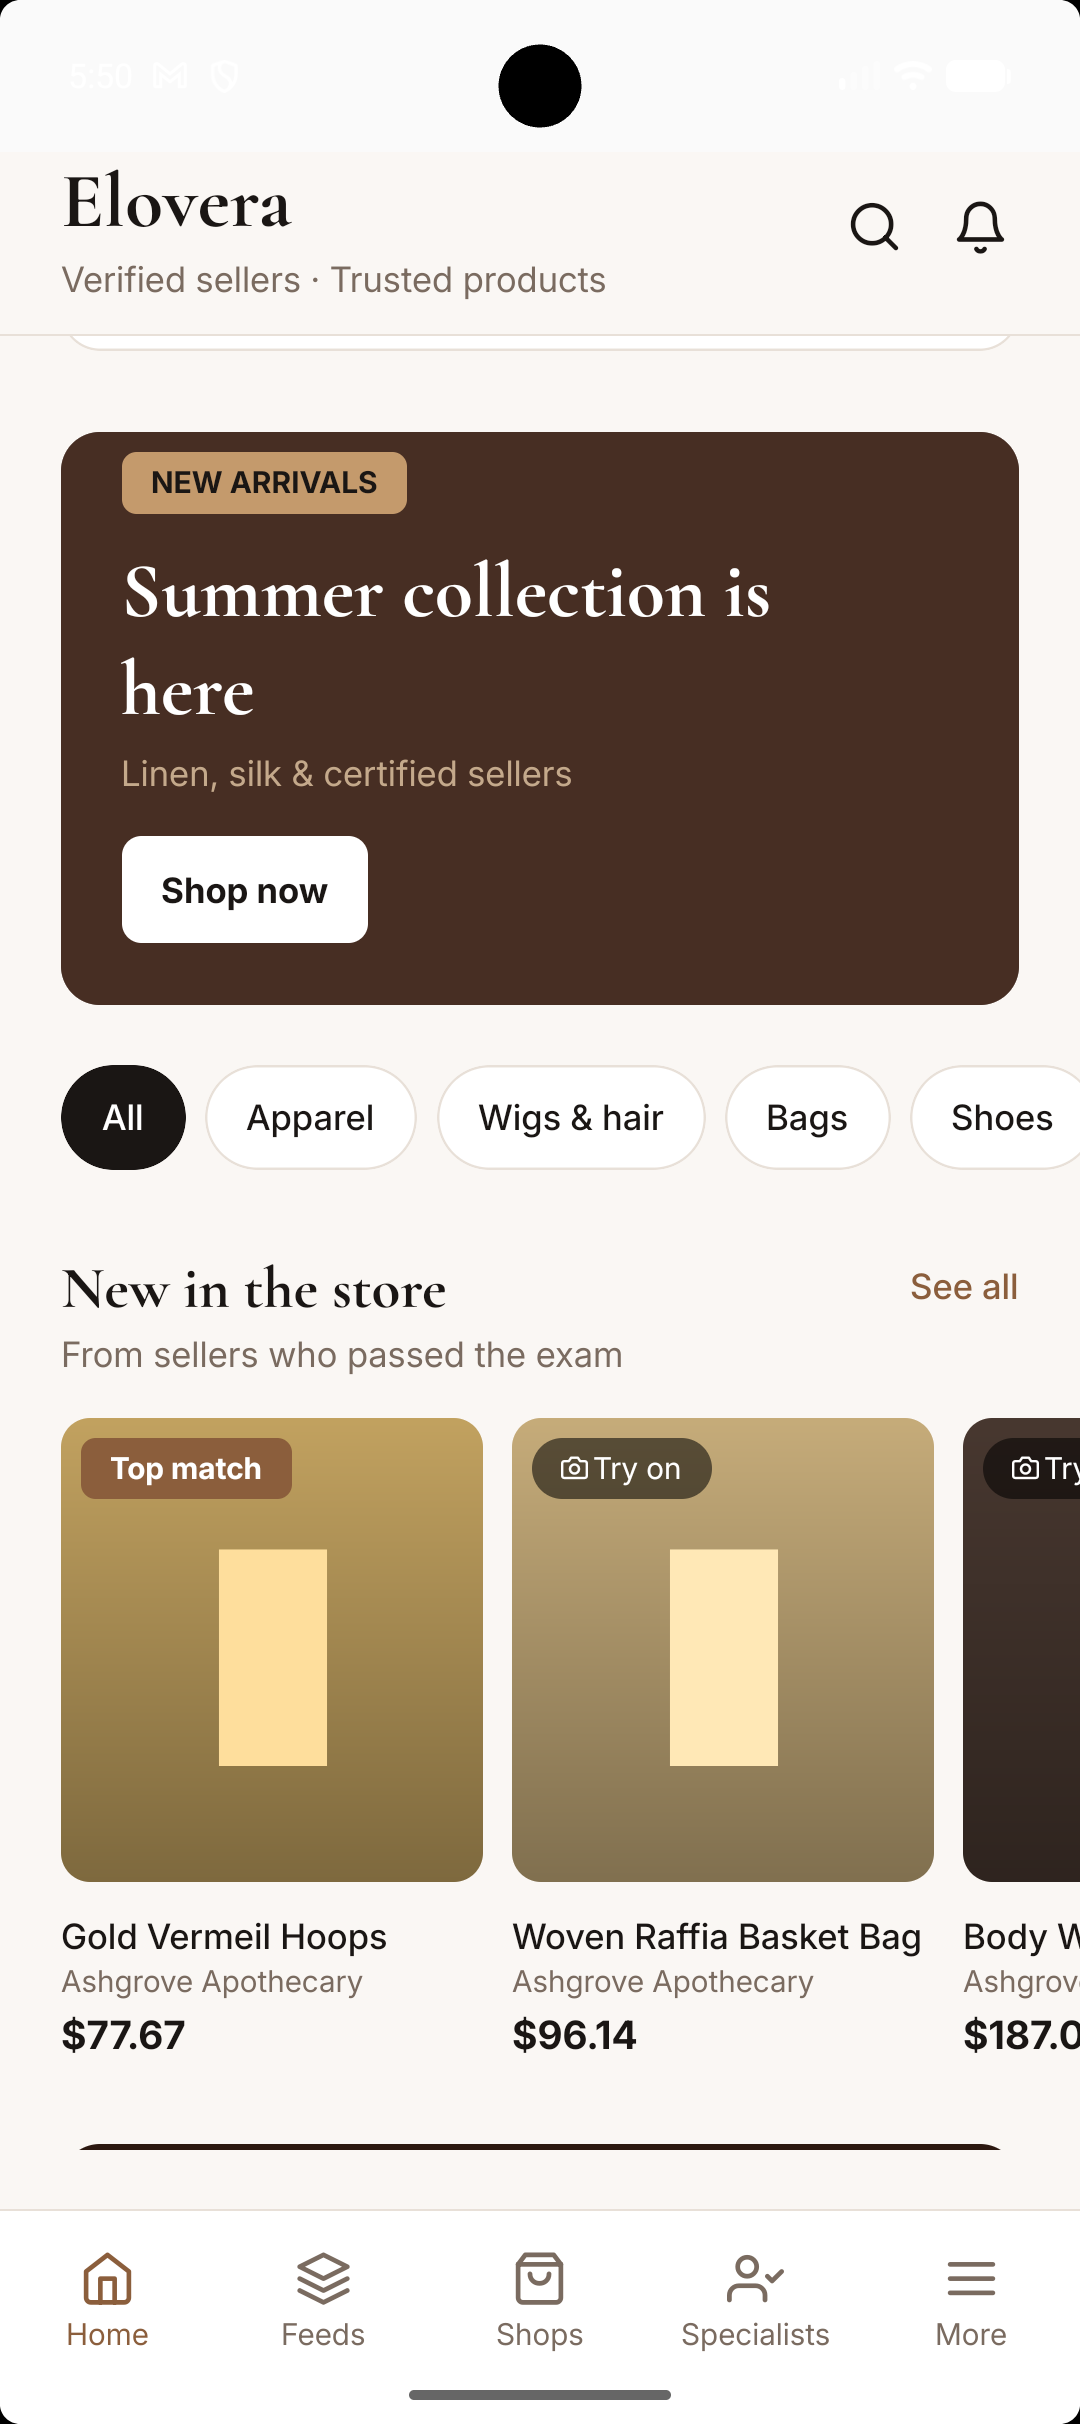
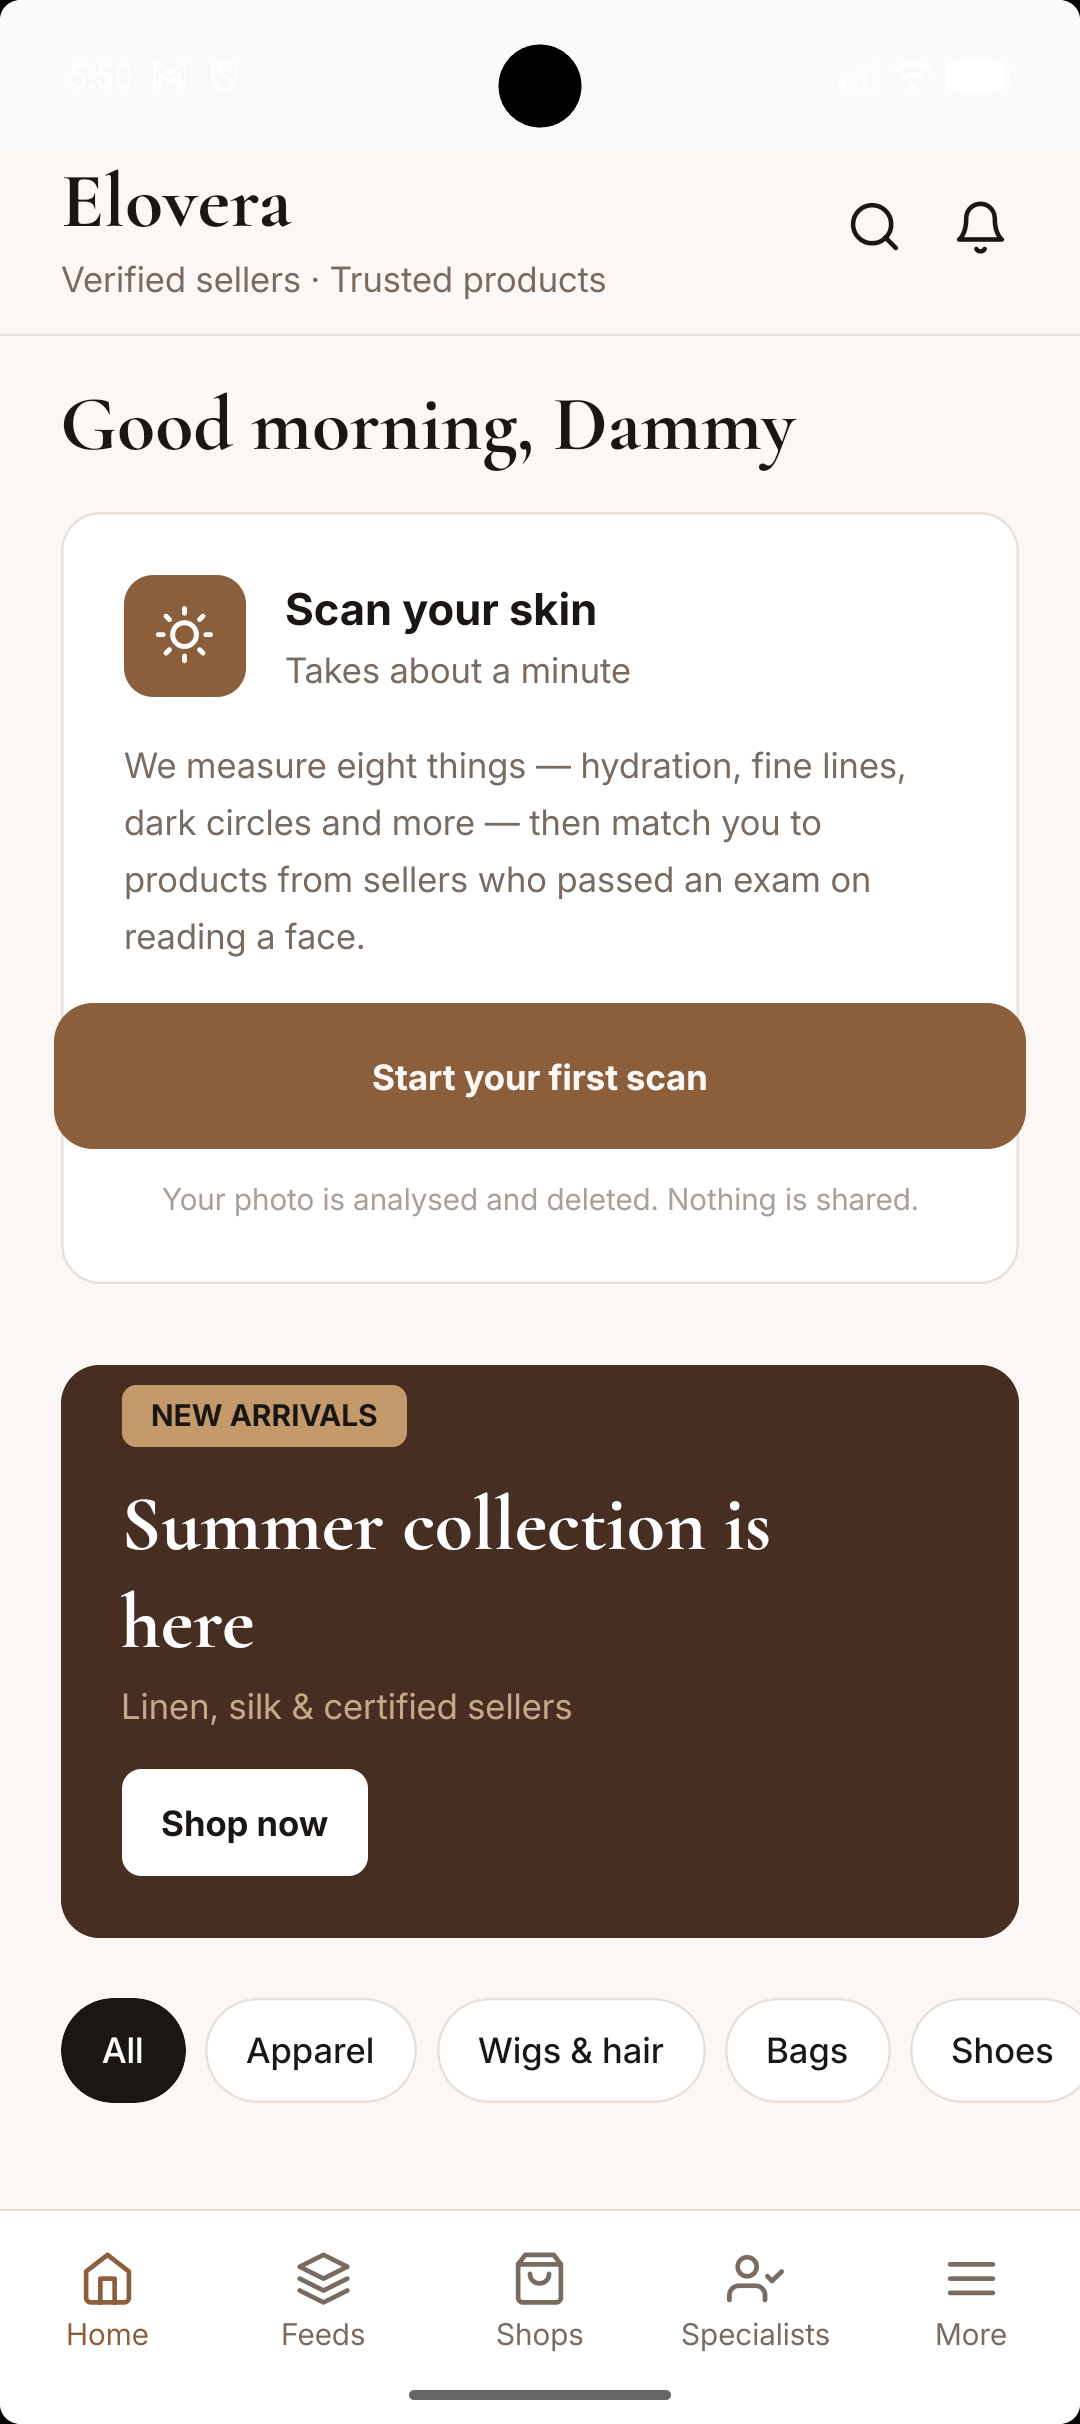
Elovera is a two-sided marketplace where the right to sell is earned by examination. Shoppers use the mobile app — scanning a face and trying clothes on belong to a camera in your hand. Sellers and our review staff use the web app, because managing a catalogue and reading a medical licence belong to a keyboard. For shoppers. Scan your face. The API measures eight concerns — hydration, fine lines, pores, redness, oiliness, blemishes, even tone, dark circles — and the app routes you to products matched to what it found. Then shop the rest of the store. Apparel, wigs, bags, shoes and accessories sit alongside skincare, stocked by the same certified sellers under the same gate. Try any of the first four on against a photo of yourself — four different YouCam engines behind one button — and from the result, walk straight into the store that sells it. Every listing carries its seller's exam score. Every try-on ends at their storefront. For sellers. Before listing anything, you sit an exam. You are shown ten faces and asked to assess eight concerns on each. Your answers are graded against the analysis engine's own measurements of those same faces. Score well and you can sell — in any department — with your score printed on your storefront.
For specialists. Dermatologists and estheticians upload a professional licence. A human checks it against the issuing register before the profile goes live. This one deliberately is not automated — more on that below.
How we built it
Backend: Go 1.25, PostgreSQL 16, pgx with hand-written SQL. Modular monolith plus a separate worker binary. Docker Compose, Cloudflare R2 for object storage.
Mobile app: React Native for iOS and Android — TanStack Query, Zustand, MMKV, Restyle, vision-camera. This is the surface the whole product was designed for: scanning your face and trying clothes on are things you do with a camera in your hand, not at a desk.
Web app: in build, for the two jobs a phone is genuinely worse at. Sellers manage a catalogue, upload product photography and sit the ten-item exam; our staff work the specialist licence review queue, comparing a document against a medical board's register. Both are keyboard-and-large-screen work, and both already have their endpoints — /v1/seller/* and /v1/staff/* were built server-first, so the web client is a client rather than a second backend.
Contract: a hand-maintained OpenAPI document in the backend repo generates the clients' TypeScript types. Neither app hand-writes a request or response shape, so a server change a client has not caught up with becomes a compile error rather than a runtime surprise — and the web app inherits every type, every error code and every capability rule the mobile app already relies on, rather than reimplementing them and drifting.
Three properties of the upstream API shaped everything
Most backend designs assume the upstream is synchronous, free at the margin, and durable. None of those hold here, and the architecture is a direct consequence.
| Property | Consequence |
|---|---|
Asynchronous — returns a task_id, results arrive later |
No AI work on a request goroutine. Durable job queue with workers. |
| Metered and prepaid — 1,000 units total, 12 per scan, 2 per try-on | Quota governance as a first-class subsystem: pre-flight checks, per-user rationing, a result cache, a usage ledger, a circuit breaker. |
| Ephemeral — every asset deleted after 24 hours | Every result is copied into our own storage inside the success path, before the job is marked complete. |
The job queue is Postgres, not Redis, and the deciding argument was transactional consistency. When a scan completes we must atomically write the concern scores, record unit consumption in the ledger, and mark the job done. With a separate broker those are two systems, and a partial failure leaves the ledger wrong — which, against a finite prepaid balance, is a correctness bug rather than an inconvenience.
-- The whole queue, essentially.
SELECT id, kind, payload FROM jobs
WHERE status = 'queued' AND run_at <= now()
ORDER BY id
FOR UPDATE SKIP LOCKED
LIMIT 1
The exam mechanic
The first design was: show sellers a face, ask what they would recommend, grade the recommendation.
That is circular. The API returns concern scores, not product recommendations — so "correct" would have meant "whatever our own routing table would have said," and the exam would have tested agreement with our code rather than competence.
The redesign grades detection instead. Precompute ground truth by running real faces through the API. Show a seller a face. Ask them to band each of eight concerns. Compare against what the engine measured.
$$\text{score} = \sum_{i=1}^{80} w(a_i, t_i), \qquad w = \begin{cases} +2 & \text{exact band} \ +1 & \text{adjacent band} \ -1 & \text{claimed a problem that isn't there} \ 0 & \text{otherwise} \end{cases}$$
Ten items, eight concerns each, 160 points available, 70% to pass.
The false-positive penalty is the load-bearing part. Without it, the optimal strategy is to mark everything "severe" — a seller who says every customer has every problem scores well and sells more product. Making that cost points is what stops the exam rewarding exactly the behaviour the product exists to prevent.
We grade on raw_score, never ui_score. Perfect Corp's documentation describes ui_score as "primarily a psychological motivator," adjusted upward because "consumers generally prefer positive evaluations regarding their skin health." That is entirely appropriate in a consumer report and disqualifying in an exam, where it would systematically reward sellers who under-diagnose. We store both and display the flattered one.
Try-on is not one API. It is a family of them.
We started by assuming "apparel VTO" was one endpoint. It is not. YouCam serves each product category from its own endpoint under /s2s/v2.0/task/{engine}, and the payloads genuinely differ:
| Department | Engine | What it takes |
|---|---|---|
| Apparel | cloth |
Customer photo, garment photo, garment_category |
| Wigs | hair-style |
Customer photo, style_id — no item photo |
| Bags | bag |
Customer photo, item photo, gender |
| Shoes | shoes |
Customer photo, item photo, gender |
So product_categories.try_on does not hold a flag. It holds the upstream endpoint slug, and that one name carries end to end — database, Go dispatch, JSON contract, client copy table. A key that needs translating between layers is a lookup table waiting to disagree with itself. Adding a department is a row and a registry entry, not a new concept threaded through five files.
The hair engine forced a decision we could have fudged. It will not accept a photograph of a wig — it applies one of Perfect Corp's catalogued styles by style_id. So a wig try-on previews the style, not that specific unit. The convenient move is to render it and say nothing. Instead, sellers nominate a style when they list, and both the product page and the result screen say plainly that this is a guide to the style rather than a photograph of the piece arriving in the post. On a marketplace whose entire proposition is that its claims are checkable, a quiet misrepresentation on the highest-intent screen in the app is the one thing we cannot ship.
Different engines also want different photographs, which is a UI problem before it is an API one. Clothes and bags need a standing torso shot; hair needs a headshot; shoes need both feet in frame — and shoes are the only one that must use the rear camera, because nobody can frame their own feet in a selfie. The capture screen reads the engine and changes the guide, the instruction and the camera accordingly. Framing for the wrong engine is a rejection the shopper cannot diagnose and a round trip we already paid for.
Whether an item can be tried on at all is computed server-side, in SQL, and sent as try_on_kind.
CASE
  WHEN pc.try_on = 'cloth' AND p.garment_cat IS NOT NULL AND (
         (p.garment_cat =  'upper_body' AND (p.on_model_image_key IS NOT NULL
                                             OR array_length(p.image_keys, 1) > 0))
      OR (p.garment_cat <> 'upper_body' AND p.on_model_image_key IS NOT NULL)
  ) THEN 'cloth'
  WHEN pc.try_on = 'hair-style' AND p.hair_style_id IS NOT NULL THEN 'hair-style'
  WHEN pc.try_on IN ('bag', 'shoes') AND (
         p.on_model_image_key IS NOT NULL
      OR array_length(p.image_keys, 1) > 0
  ) THEN pc.try_on
  ELSE 'none'
END
The client shows a try-on affordance if and only if this is not none, and it is never allowed to infer it from the category name. That single rule prevents a family of failures: trousers listed without the on-model photograph Perfect Corp require for lower-body garments ("only actual worn outfits are supported, not standalone product images"); a wig with no style mapping; an accessory in a department we have not wired an engine for. Each would have been a button that spends metered units to produce a failure we could have predicted before the customer tapped it.
It also survived being wrong. We first modelled this as a three-way flag on the assumption that clothes and wigs were the only things that could go on a person — then found the bag and shoe endpoints. Because the decision lived in one SQL expression and one registry rather than in switch statements across the app, correcting it was a migration and two cases, and no screen needed touching.
Try-on is deliberately unrationed. At 2 units against a scan's 12 it costs roughly a sixth, which makes it cheap enough to be the free, shareable surface while scanning stays quota-limited. The expensive thing is the one people do once; the cheap thing is the one they do for fun. Results are cached on a hash of the inputs, so a judge retrying the same combination costs nothing after the first call.
Challenges we ran into
The exam bank is a security control, and we could prove it
Beauty stock photography is overwhelmingly of clear skin. Seed an exam bank from it and the band distribution skews badly — so we simulated what that does.
Monte Carlo, 400 trials per strategy, against the real scoring function:
| Bank composition | "Clear to everything" scores | Pass rate |
|---|---|---|
| Balanced (25/25/25/25) | 37.8% | 0.0% |
| Clear-skewed (5/15/30/50) | 65.2% | 13.5% |
A candidate who answers "Clear" to every question lands within five points of the pass mark on a skewed bank and gets through roughly one sitting in seven — while genuinely competent candidates drop from an 88% pass rate to 56%.
A skewed bank is simultaneously gameable and unfair. So ValidateBank refuses any bank where a severity band holds under 15% or over 40% of cells, and it runs before the bank goes live — a composition check treated as a security control rather than a nicety.
Building a bank that passes it was the hardest sourcing problem in the project. Beauty photography selects hard for clear skin, so the faces that make the Severe and Moderate bands are exactly the ones stock libraries do not have. Every candidate costs 12 units to evaluate, which makes trial and error expensive. We built a free pre-flight check — format sniffing, dimension validation, duplicate detection by SHA-256 — so that a candidate the engine would reject is caught before it costs anything.
The bugs only running it could find
Running the thing found what reading it could not:
- Metadata graded as skin concerns. The API returns
all,skin_ageandresize_imagealongside the eight real concerns. We were banding all of them — three fabricated "severe" readings per face, and an overall score of 65.55 where the truth was 90.13. That would have silently corrupted exam ground truth. - Retries on unfixable photos.
error_src_face_too_smallwas retried five times because task-level failures came back as plain errors, soerrors.Asnever matched the typed one. A user's badly framed selfie became five round trips. - An undocumented error code.
error_large_face_angleappears nowhere in the documentation. We found it by running real photographs. - Presigned URLs signed for the wrong host. Signed against
minio:9000, which is unreachable outside the Docker network. Later, the same class of bug again: signed forlocalhost, which inside an Android emulator means the emulator, not the development machine. - A dead job orphaning its scan. When a job exhausted its retries, the queue closed the job but nothing closed the
scansrow — so the app polled a status that would never change. An endless spinner, which is worse than an error, because an error at least tells you to try again. The fix generalised: the queue now hands dead jobs to a per-kind handler, and try-on registers one too, because it had the identical latent bug.
Windows, and a 260-character path
The Android build failed on a filename longer than 260 characters. Enabling long paths did not help — the ninja shipped with the Android SDK's CMake predates long-path support.
We worked out the arithmetic, established that relocating the project would still not fit, and traced the offending path to react-native-gesture-handler, pulled in by @react-navigation/stack. Nothing in the app imported it. Switching to the native stack removed the dependency and the problem.
Consent that is actually consent
A photograph of a face processed for analysis is plausibly Article 9 special-category data under GDPR, and is covered by Illinois BIPA and Texas CUBI. Those require consent that is specific to the purpose, separate from other terms, and as easy to withdraw as to give.
A checkbox in the signup flow satisfies none of that. So biometric consent is its own screen before the camera opens, stating what happens to the photo, how long it is kept, who can see it, and how to withdraw. Consent records are versioned and revocable per purpose — the three signup agreements are three separate rows, because revising the community standards must not silently re-consent someone to a privacy policy they never read.
The same reasoning governs try-on results. They are pictures of the customer, so they are served from short-lived signed URLs rather than any stable address, and an unsaved look is transient and swept. Keeping one is an explicit act.
Accomplishments that we're proud of
We pointed the API at the seller. Every entry in this hackathon will scan a buyer's face. We think we are the only one grading whether the seller can read one — and that single inversion turns the oldest unfalsifiable claim in e-commerce into a number a shopper can see on a storefront.
We proved the exam is fair rather than asserting it. 400 Monte Carlo trials per strategy, run against the real scoring function, showing that a lazy candidate goes from a 0% pass rate on a balanced bank to 13.5% on a skewed one. That number is why ValidateBank exists and why the 15–40% band thresholds are what they are. The design decision has evidence behind it, not intuition.
Four try-on engines, one button, and no way to press it wrongly. Clothes, hair, bags and shoes each have a different endpoint, a different payload and a different framing requirement — and the app never guesses which applies. Capability is computed in SQL from what each engine actually needs, so a listing that cannot succeed simply has no button. On a prepaid balance, that is the difference between a demo and a bill.
We refused the convenient lie. The hair engine previews a catalogued style rather than the seller's actual wig. We could have rendered it silently and nobody would have known. Instead it says so, on the product page and on the result screen — the two places where saying it costs us conversions. A verification product that misrepresents anything has no product left.
The backend is not hackathon scaffolding. A transactional Postgres job queue with SKIP LOCKED, dead-letter handlers per job kind, a usage ledger with a circuit breaker, argon2id, rotating refresh tokens with family-wide reuse detection, RFC 7807 errors with stable codes, and an OpenAPI contract that generates the clients' types so a drift becomes a compile error.
A shipped mobile app, and a web app that costs a fraction of it. The React Native app carries the full shopper journey — signup, email verification, biometric consent, scan, report, recommendations, catalogue, four try-on engines, saved looks — across three role-scoped navigation stacks with capabilities recomputed server-side on every request rather than carried in a token. The seller and staff web app is the second client, and it is cheap precisely because the first one was built against a contract instead of against a memory of the server: same generated types, same error codes, same authorisation rules, no reimplementation.
Consent that would survive being asked about. Biometric consent is its own screen with its own record, revocable per purpose, versioned so a change to one policy cannot silently re-consent anyone to another. Try-on results are pictures of the customer, so they are served from short-lived signed URLs and swept unless explicitly saved. We built it this way before anyone asked us to.
We were honest about what is not built. Checkout is not wired. Jewellery has no engine. Those are stated plainly here and shown plainly in the app — an empty department reads as "nobody has listed here yet," never as a broken screen.
What we learned
Verification is only worth something if you can say what was measured. "Trusted" is unfalsifiable. "Scored 91 out of 100 on a test of reading a face" is checkable, and the difference is the whole product.
Some things must not be automated. A seller's competence can be graded by machine because there is ground truth. A dermatologist's licence cannot — it is a document issued by a medical board, and the only honest check is a person comparing it against that board's register. On a product whose entire proposition is verification, claiming a verification we did not perform is the one failure that would actually matter. So specialist credentials go to a human review queue, and every read of a licence document is audited.
Capability belongs on the server, even when the client could guess. try_on_kind could plausibly have been a switch on the category name in the app. Putting it in SQL, derived from what each engine actually requires, is what made it impossible to ship a button that spends money to fail — and it is why going from two engines to four cost a migration rather than a refactor.
Name your keys after the thing they identify. Our engine key is Perfect Corp's endpoint slug, unmodified, from the product_categories row through the Go dispatch to the JSON the app reads. We briefly had our own vocabulary — garment for cloth — and every layer boundary became a place to get the translation wrong.
A metered upstream changes how you write code. When a retry costs real money, idempotency stops being hygiene. When a user's photo is rejected, telling them why — "hold the camera closer, your face needs to fill more of the frame" — is worth more than any amount of error handling, because it is the difference between a second attempt that works and a user who gives up.
Guess about a library and you will write code that compiles and does nothing. vision-camera v5 has a completely different API from v4 — no photo boolean, no takePhoto on a ref, but composed outputs and capturePhotoToFile. Reading the type definitions took two minutes. Writing v4 from memory would have cost an evening.
What's next
- The seller and staff web app, finished. Catalogue management, product photography upload, the exam sitting, and the specialist licence review queue — the work that wants a keyboard and a large screen. The endpoints exist and are enforced today; what remains is the client.
- Checkout and orders. The catalogue, the storefronts and the try-on funnel all land on a seller; the payment rail is the remaining piece.
- Grow the exam bank so item selection can draw from a larger pool without repeating faces across sittings.
- Live specialist consultations. Designed and gated —
CapAdviseCustomerexists and is enforced — but video needs signalling, a media provider and scheduling, which is not a three-day feature. - Hats, scarves and jewellery. YouCam serves all of them; the earring endpoint alone wants per-item placement data (
object_infos) that a seller cannot supply from an upload form, so the department exists and the engine is deliberately left unwired rather than shipped as a button that fails. - The seller and specialist feed, where certified sellers publish technique videos and specialists publish articles.
- Sign in with Google and Apple. Apple requires Sign in with Apple on any app offering third-party social login, so the two ship together.
- Seller analytics — which concerns their catalogue actually serves, which pieces get tried on and never bought, and where the gaps are.
Built With
- ai
- amazon-web-services
- android
- argon2
- cloudflare-r2
- computer-vision
- docker
- docker-compose
- e-commerce
- go
- ios
- jwt
- minio
- openapi
- perfect-corp
- postgresql
- react
- react-native
- resend
- rest-api
- sql
- tanstack-query
- typescript
- youcam-api
- zustand


Log in or sign up for Devpost to join the conversation.