Inspiration
Being in college, education is constantly at the forefront of our minds. The social sciences dataset was of particular interest to our team because it encompasses a variety of factors including health and housing, which are deeply intertwined with each other and speak to our common interests in public health and service. After visualizing each of the composite scores for each state, we noticed that California had the highest average percent of population with less than a high school education across its school districts. This question of why California has the highest average percent of population with less than a high school education across its school districts and investigating how each of the other factors are intertwined with it interested us.
What it does
Our slideshow helps visualize the specific geographic and issues that are most impactful on education in California, providing insight for organizations on what root causes to focus on to improve education in California.
How we built it
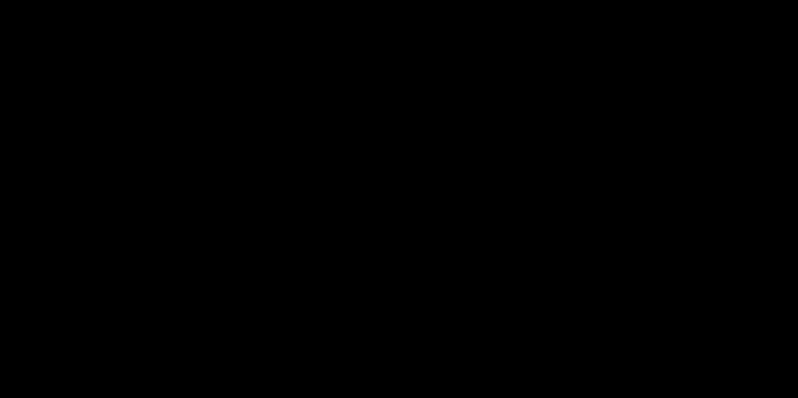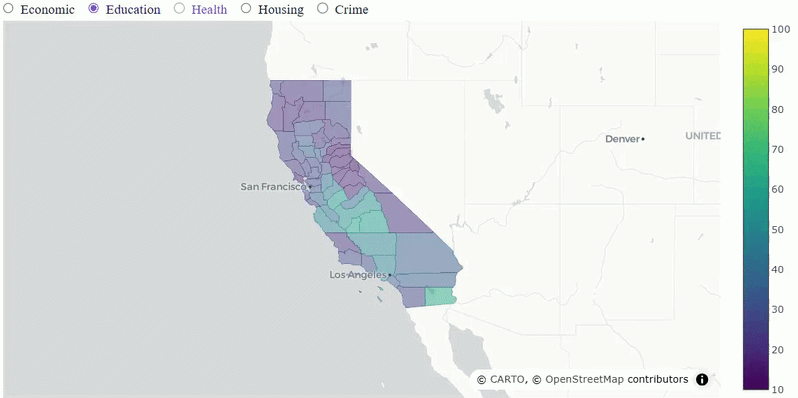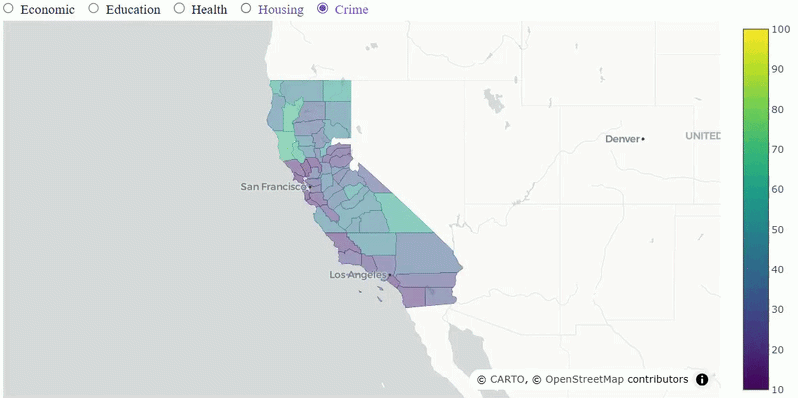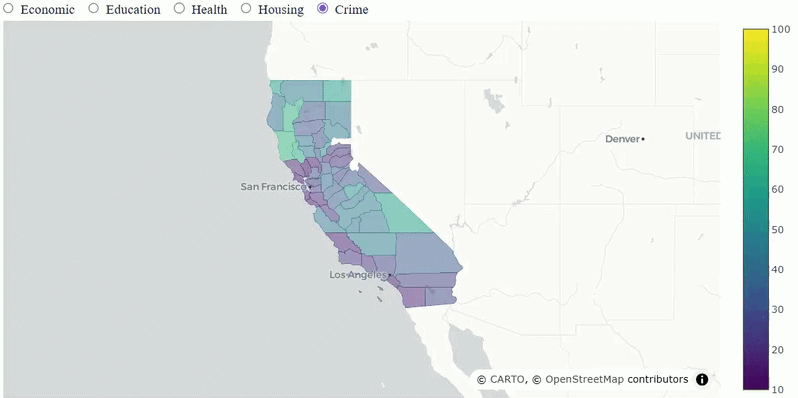
We used plotly to generate the dynamic map that shows each of the composite scores across all California districts. To understand the relationship between the composite scores on education and the specific economic factors on education, we used random forest models (ranger) in R. For the county bar graphs, we used matplotlib. The presentation slide deck was created on Google Slides.
Challenges we ran into
Our initial ideas were ambitious but were unable to be carried out because of the lack of external data. After searching through public datasets for some time, we decided that the scope of our attempted analysis introduced too many confounding variables, as we were unable to standardize external data to be comparable to the primary dataset. We then consulted with the mentors to narrow down the scope of our project to create a more focused analysis.
Accomplishments that we're proud of
We are very proud of our web app made using plotly because it shows the distribution of the different composite scores across California well. It highlights which factor is the most prevalent in California and how the counties affected most by one composite score are the same for another composite score but very different for another. We chose good visualizations to further highlight this and effectively build a case to support further efforts and real-life impacts.
What we learned
Through this project, we honed our data analysis skills by utilizing more complex software and statistical models. From the initial planning stage, we learned to ideate when it came to crunching large datasets and narrowing our focus. Once some ideas were unable to be fully realized due to the lack of data or other constraints, we learned to pivot and reformulate our analysis to concentrate on a different topic.
What's next?
Further analyses on the topic of education would include targeting poverty and/or underrepresented populations. Poverty itself is a complex topic to cover and address, so future research would identify data-driven solutions for specific regions. This would require time, funding, and opportunities to directly consult with the people affected to ensure their needs are addressed in a manner that is respectable, effective, and sustainable. Qualitative coding would be highly useful for such an analysis. Addressing educational attainment for minorities, specifically Hispanic/Latino communities, would follow a similar path in order to synthesize a comprehensive plan to tackle these challenges.
Our team will continue to tackle pressing public issues as we continue our academic journeys and collaborate in the data analysis club where we met. Our common interests in public health, education, and community service will bring us together again in the future as we work with each other on data analyses.


Log in or sign up for Devpost to join the conversation.