Inspiration
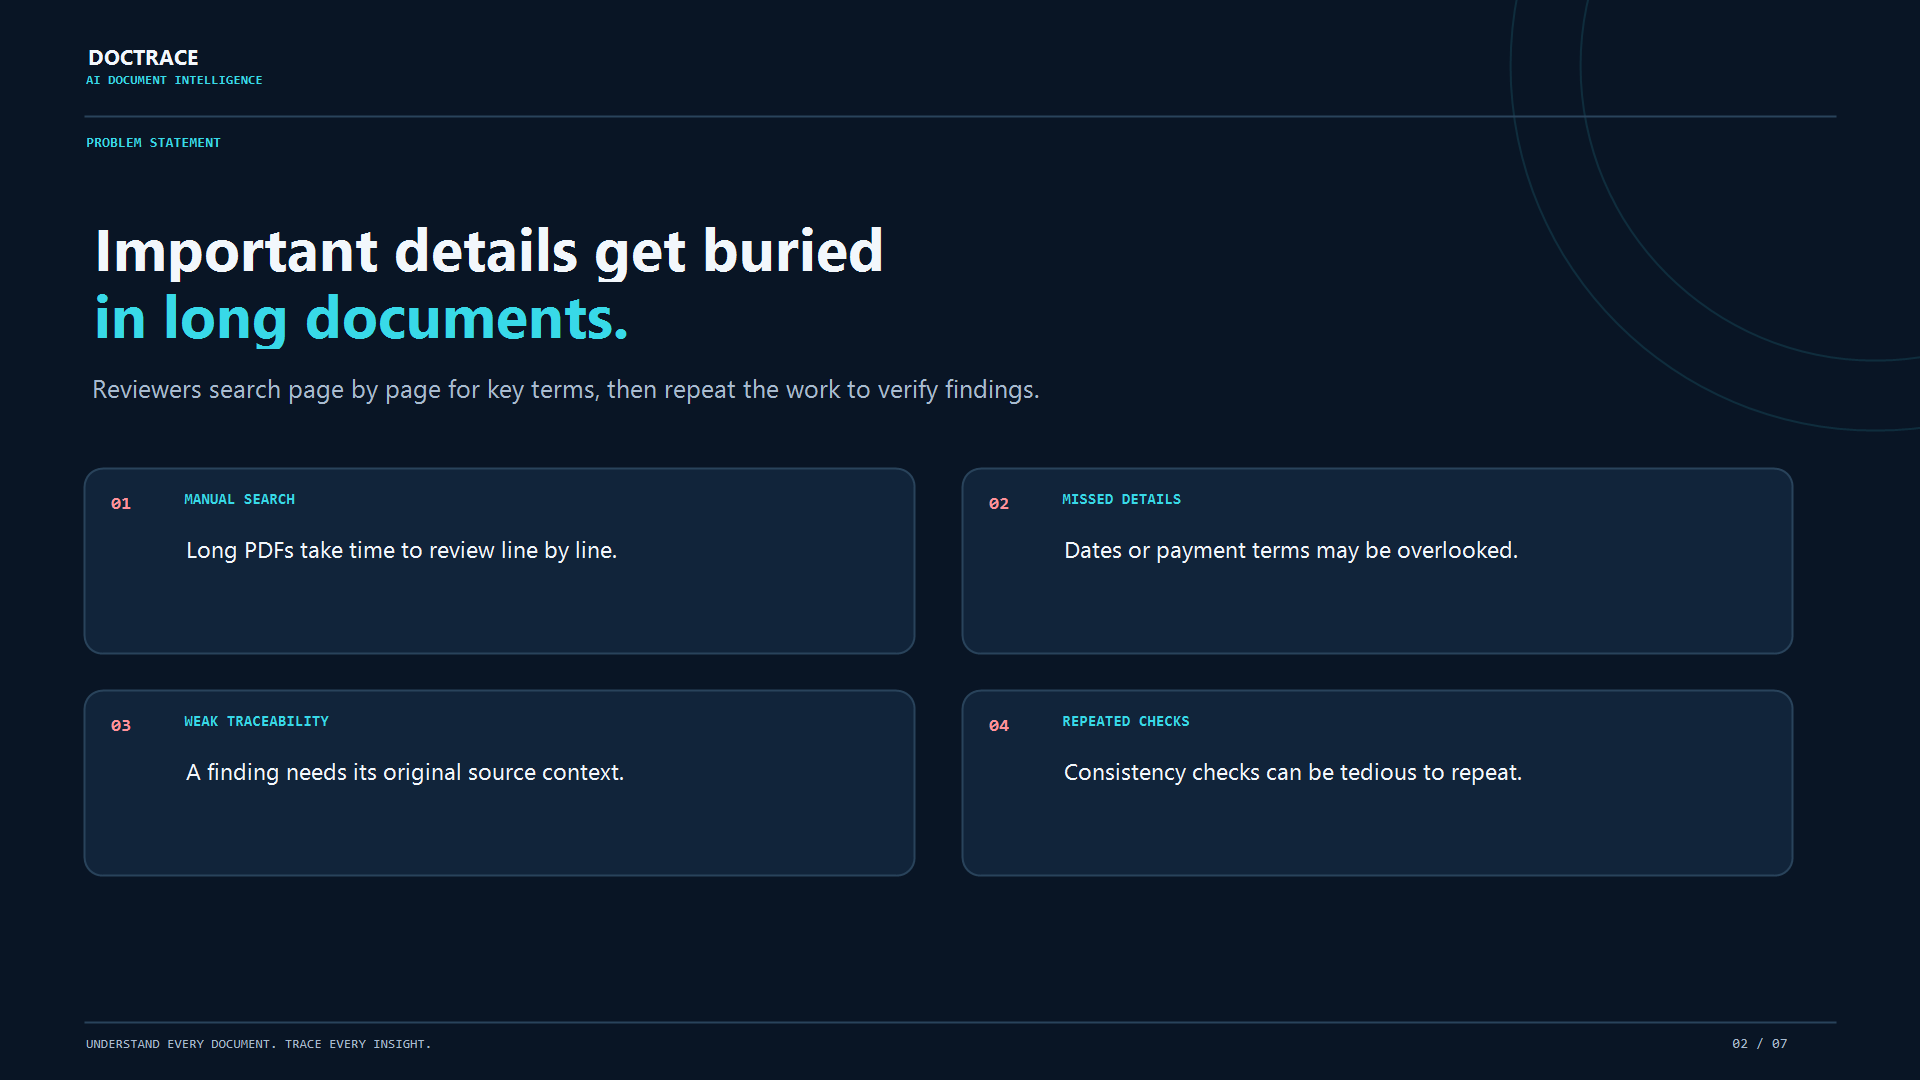
Contracts and other important documents can be long and difficult to review. We wanted to make it easier to find key details and verify them against the original document. DocTrace is built around one idea: every extracted insight should lead back to its source.
What it does
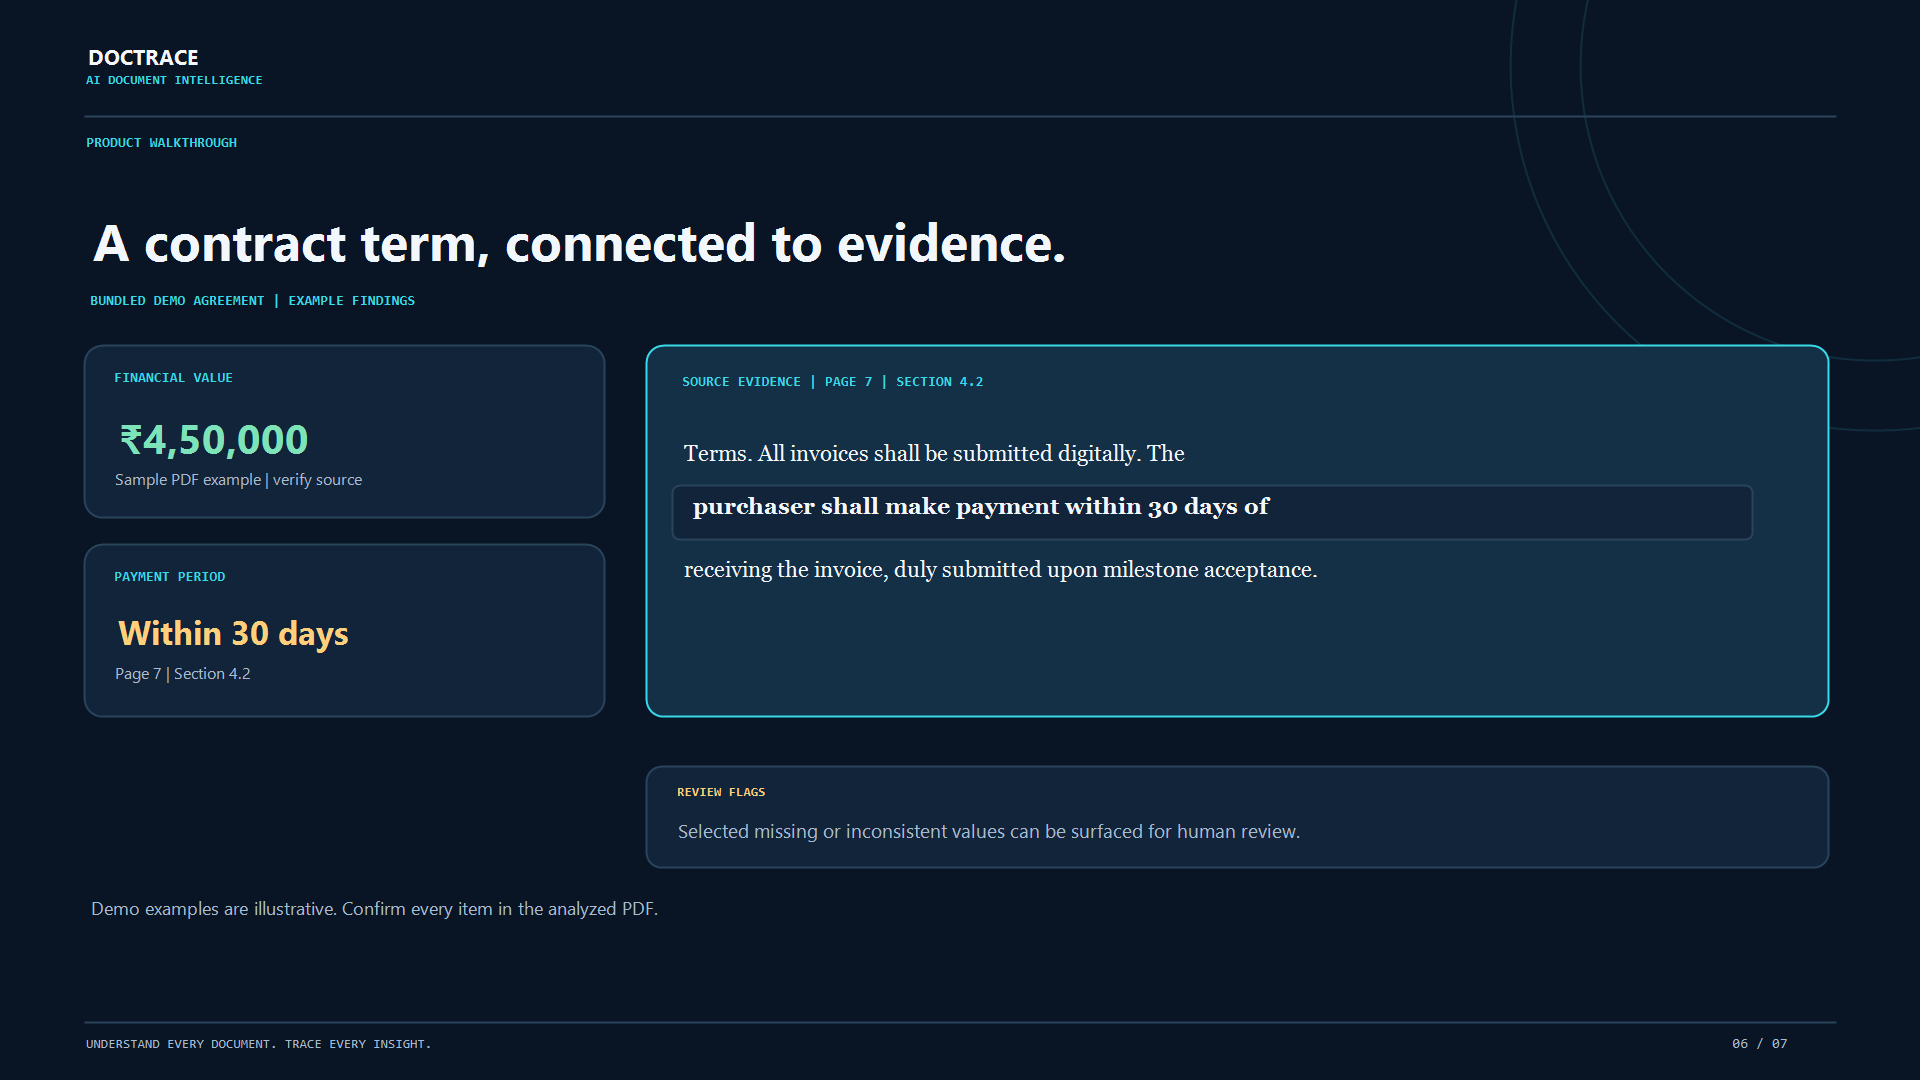
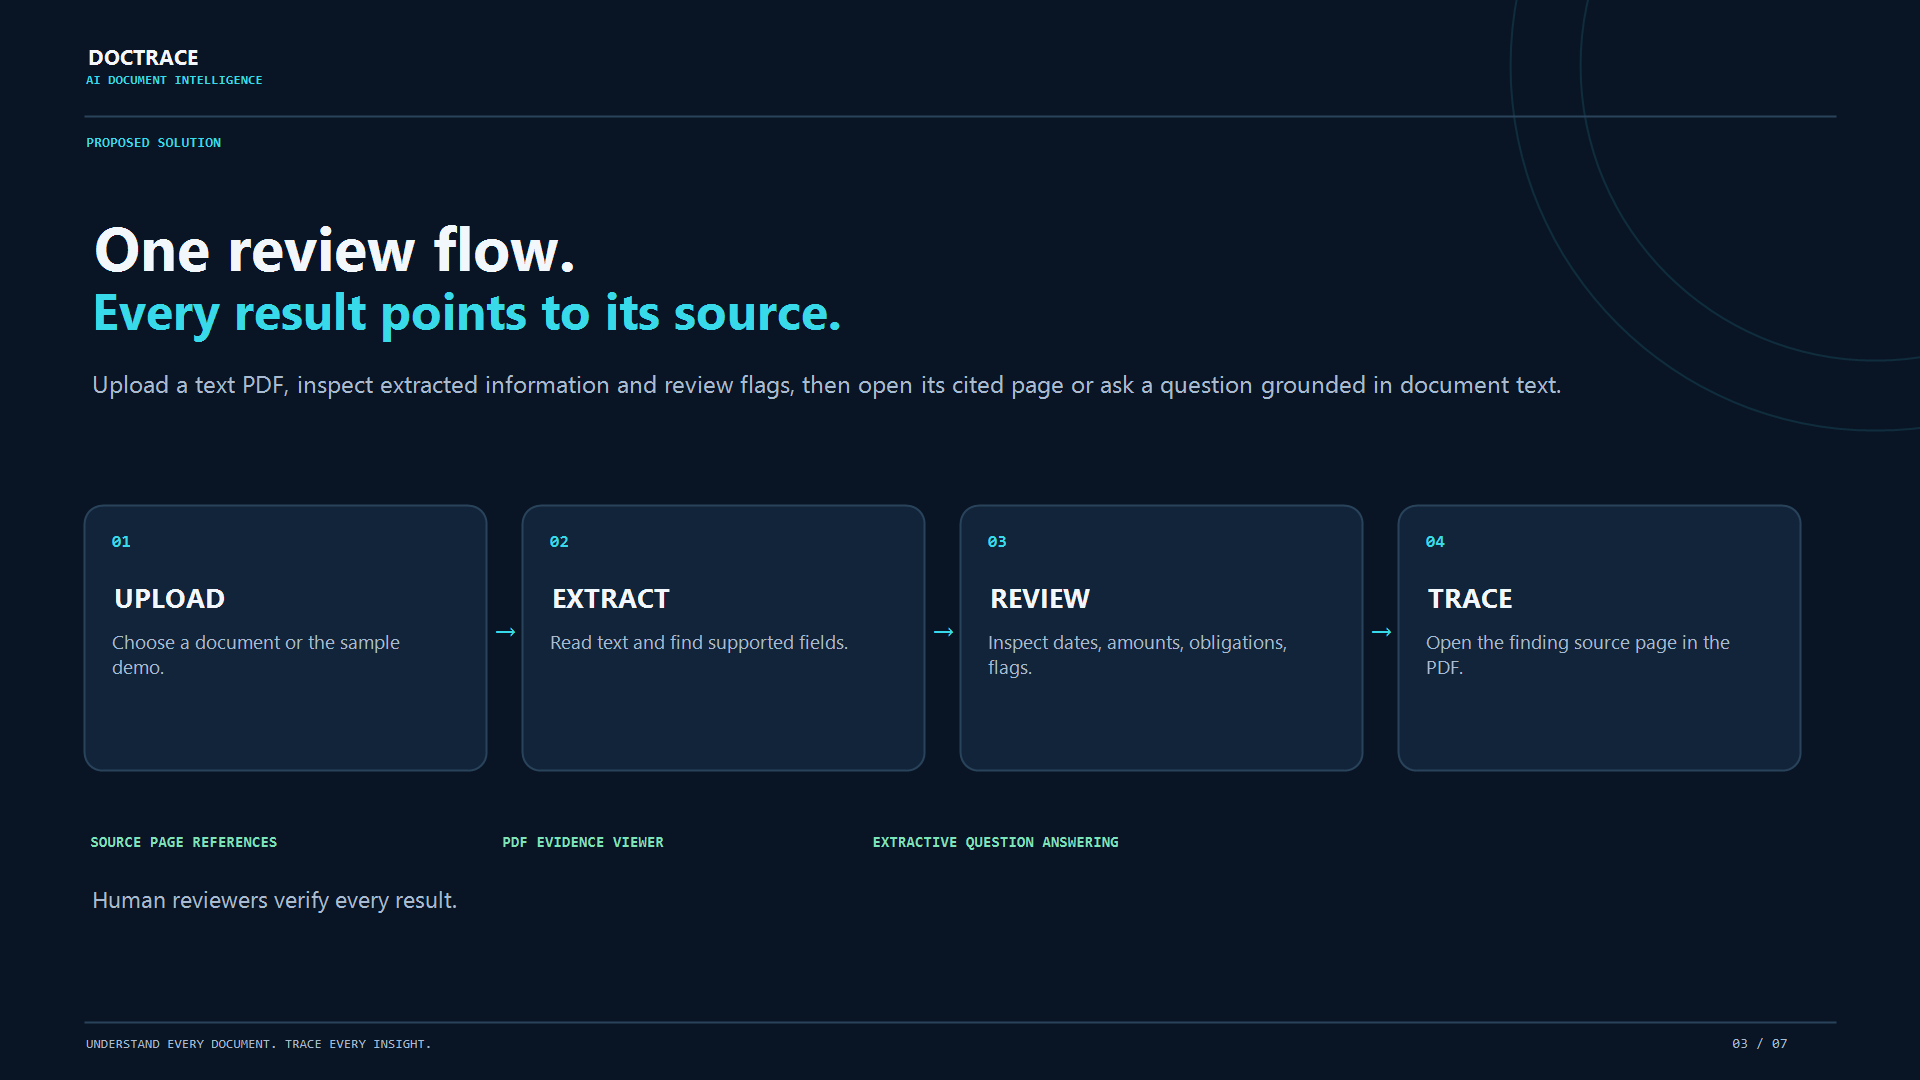
DocTrace lets users upload a PDF and review extracted dates, payment periods, financial values, obligations, and potential inconsistencies in a dashboard. Each result includes source text and a page reference, alongside the original PDF. Users can also ask questions and get answers by searching the document text for relevant passages.
The project uses a bundled service agreement in demo mode so people can explore the workflow without uploading a document. Its rule-based results support human review; they are not legal advice.
How we built it
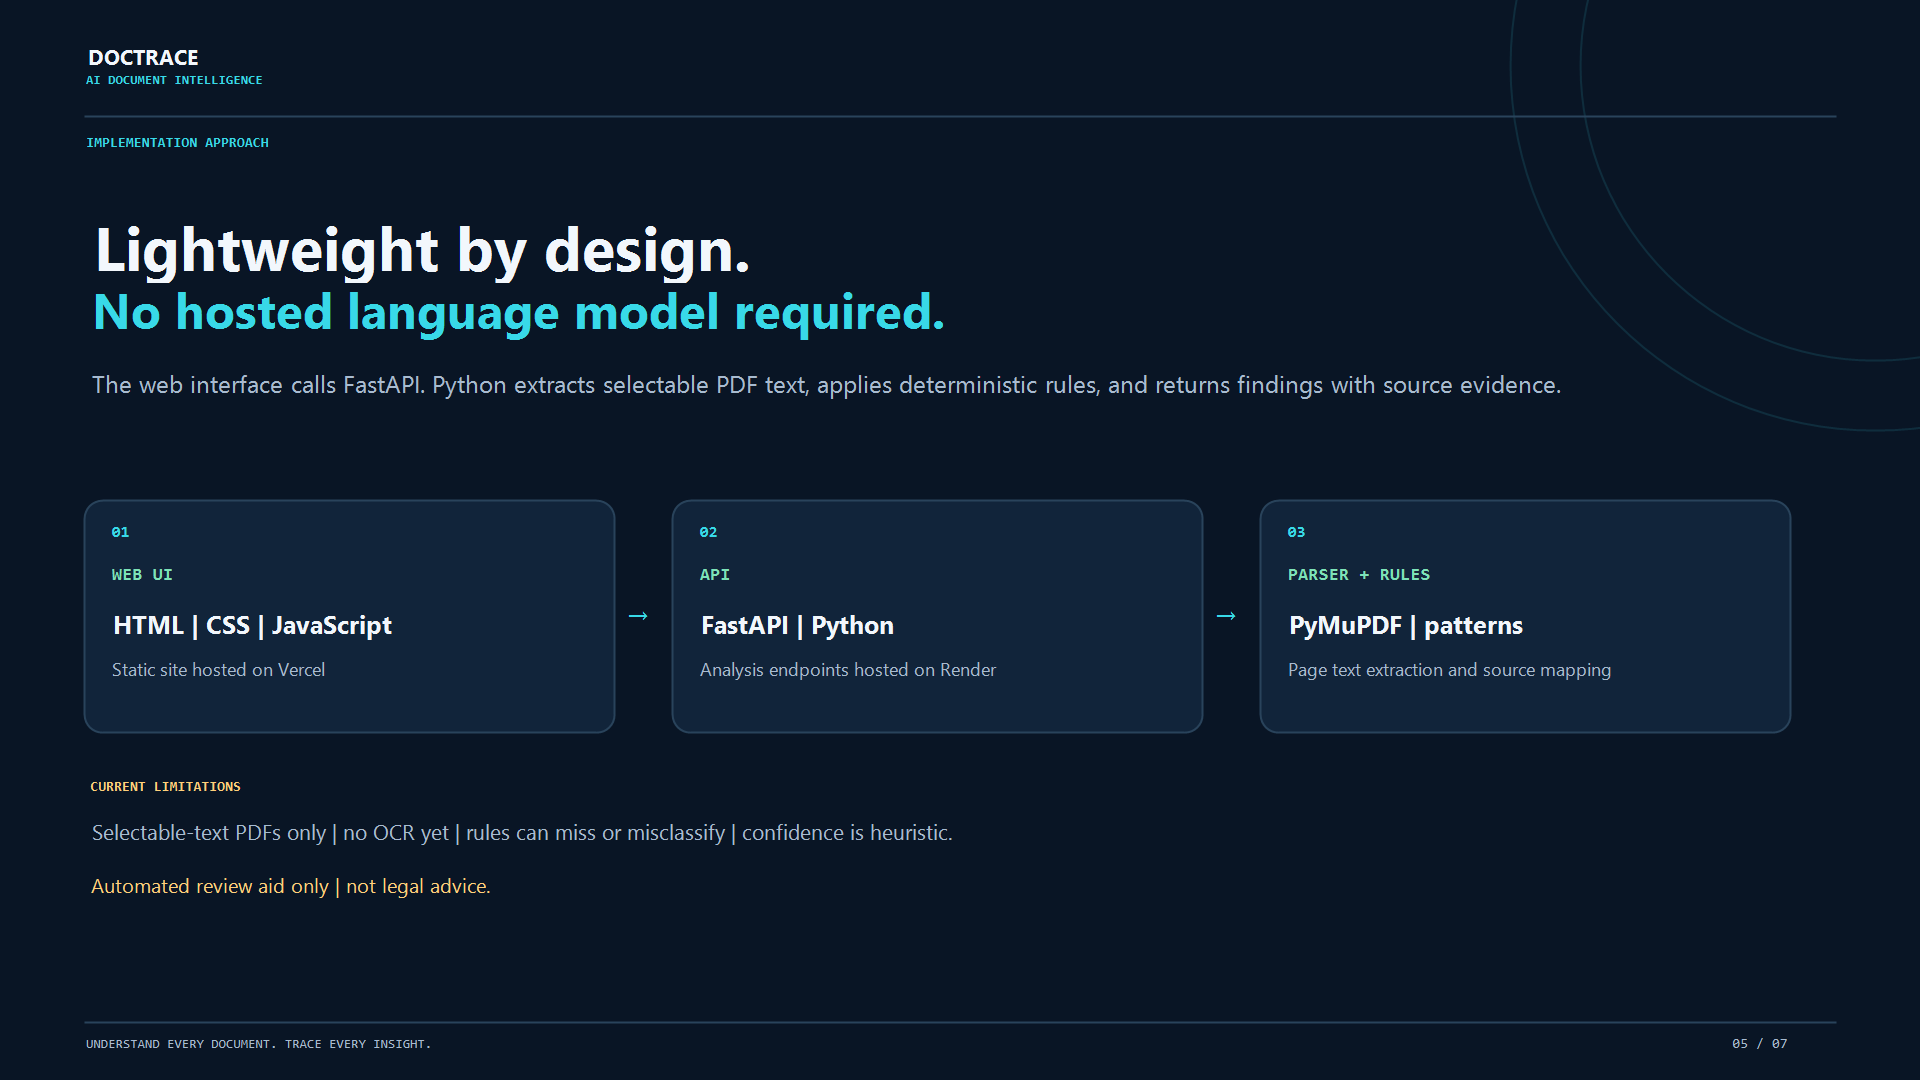
We built the frontend with HTML, CSS, and JavaScript, and the backend with FastAPI and Python. The backend uses PyMuPDF to extract text and page information from PDFs. Pattern matching identifies selected fields and review items, and consistency checks flag selected conflicting values or arithmetic mismatches.
The frontend sends PDFs to the API and displays structured results alongside the source document. Question answering searches extracted text and returns a relevant passage with its page reference. We deployed the frontend on Vercel and the backend on Render.
Challenges we ran into
One challenge was making the PDF visible and keeping it aligned with the extracted results, especially when users move between evidence pages. We also had to configure the frontend and backend separately for deployment, including their project roots and API connection. Render’s free service can sleep when inactive, which may delay its first response.
Accomplishments that we're proud of
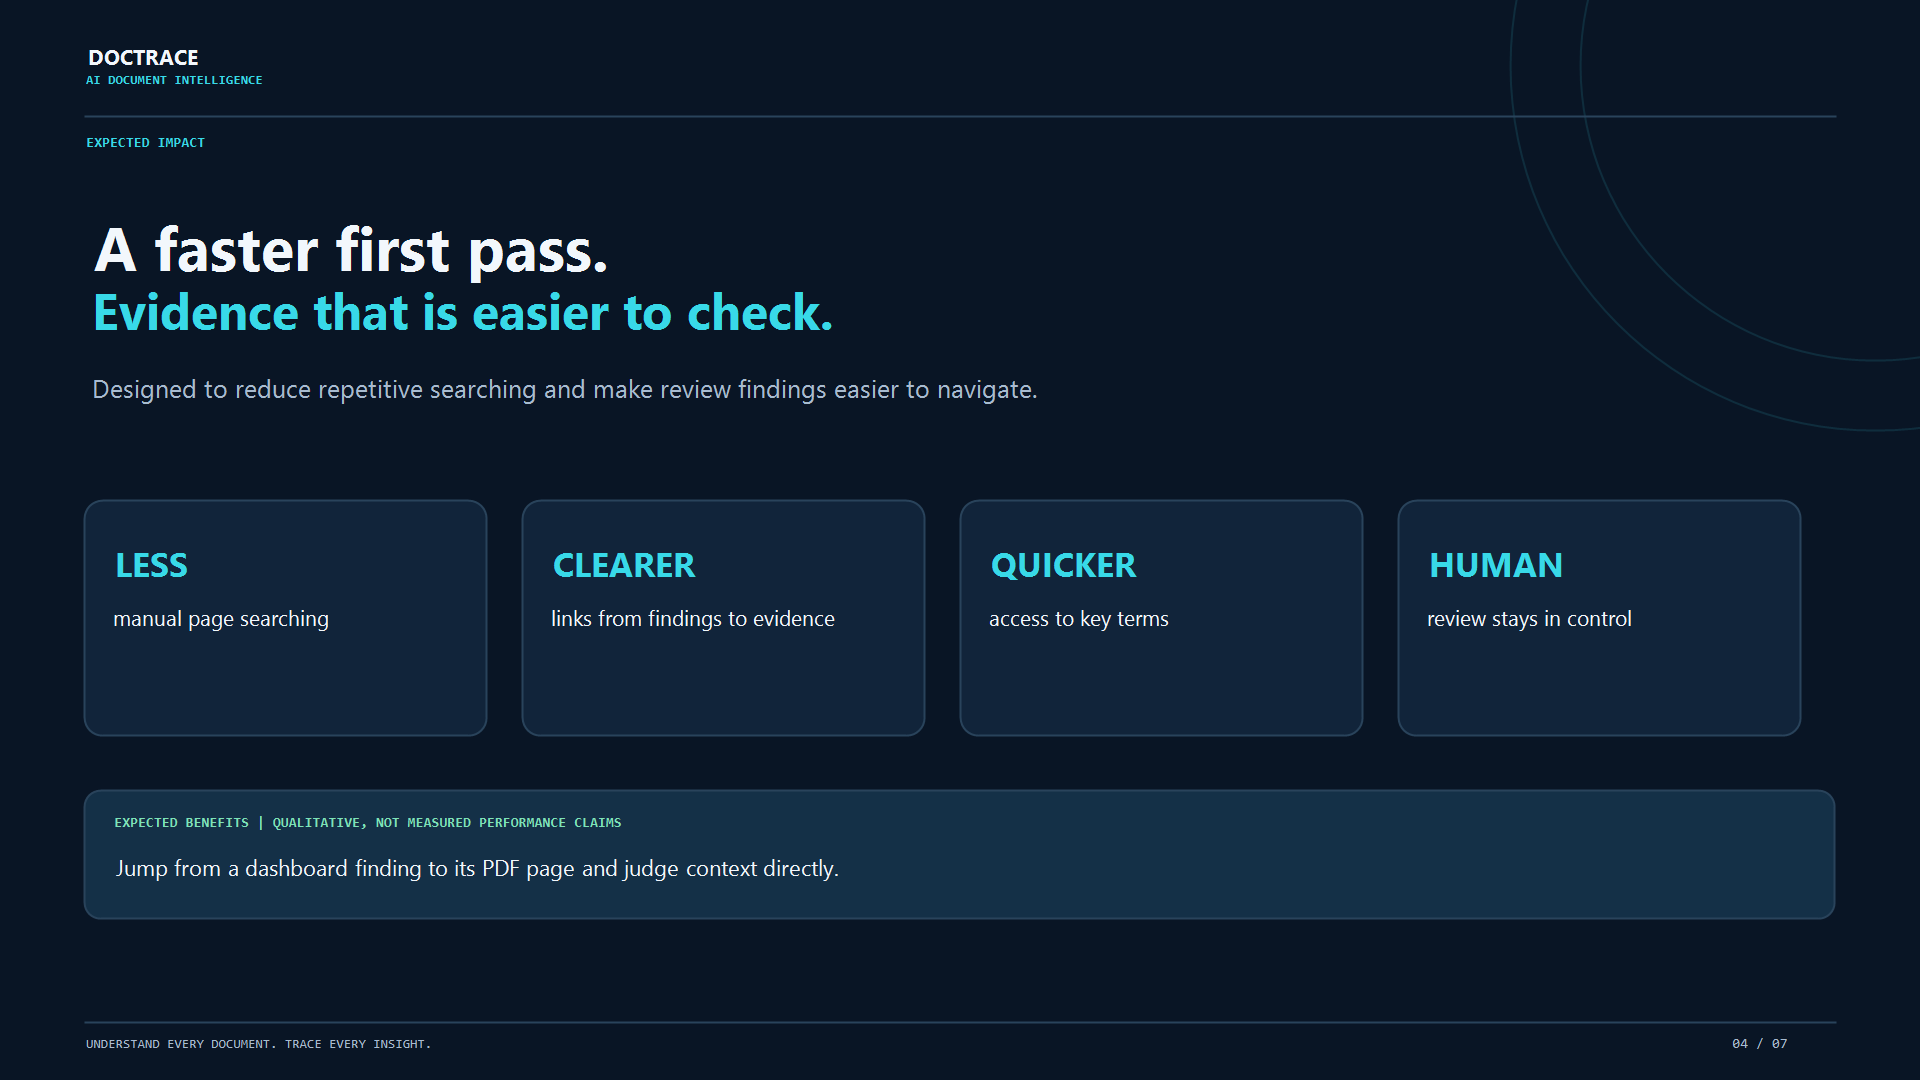
We built a complete flow from PDF upload to review dashboard, with page-linked evidence and a demo document that showcases the experience. We’re proud that users can inspect the original page behind an extracted result instead of relying on an unexplained summary.
What we learned
We learned how to connect a static frontend to a FastAPI backend, extract text and page information from PDFs, and deploy a multi-service application. We also learned to communicate the limits of rule-based extraction and keep document review results traceable to their sources.
What's next for DocTrace – AI Document Intelligence
Next, we’d like to improve extraction accuracy across more document types, add OCR for scanned PDFs, make confidence estimates more meaningful, and improve document storage and privacy controls. We’d also like to expand the evidence checks while keeping every result verifiable against the source document.
Built With
- css
- fastapi
- html
- javascript
- pymupdf
- python
- render
- vercel
Log in or sign up for Devpost to join the conversation.