-
-
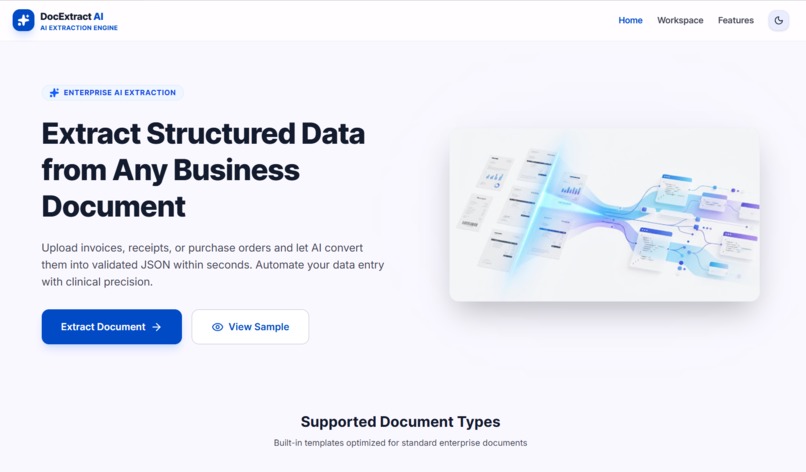
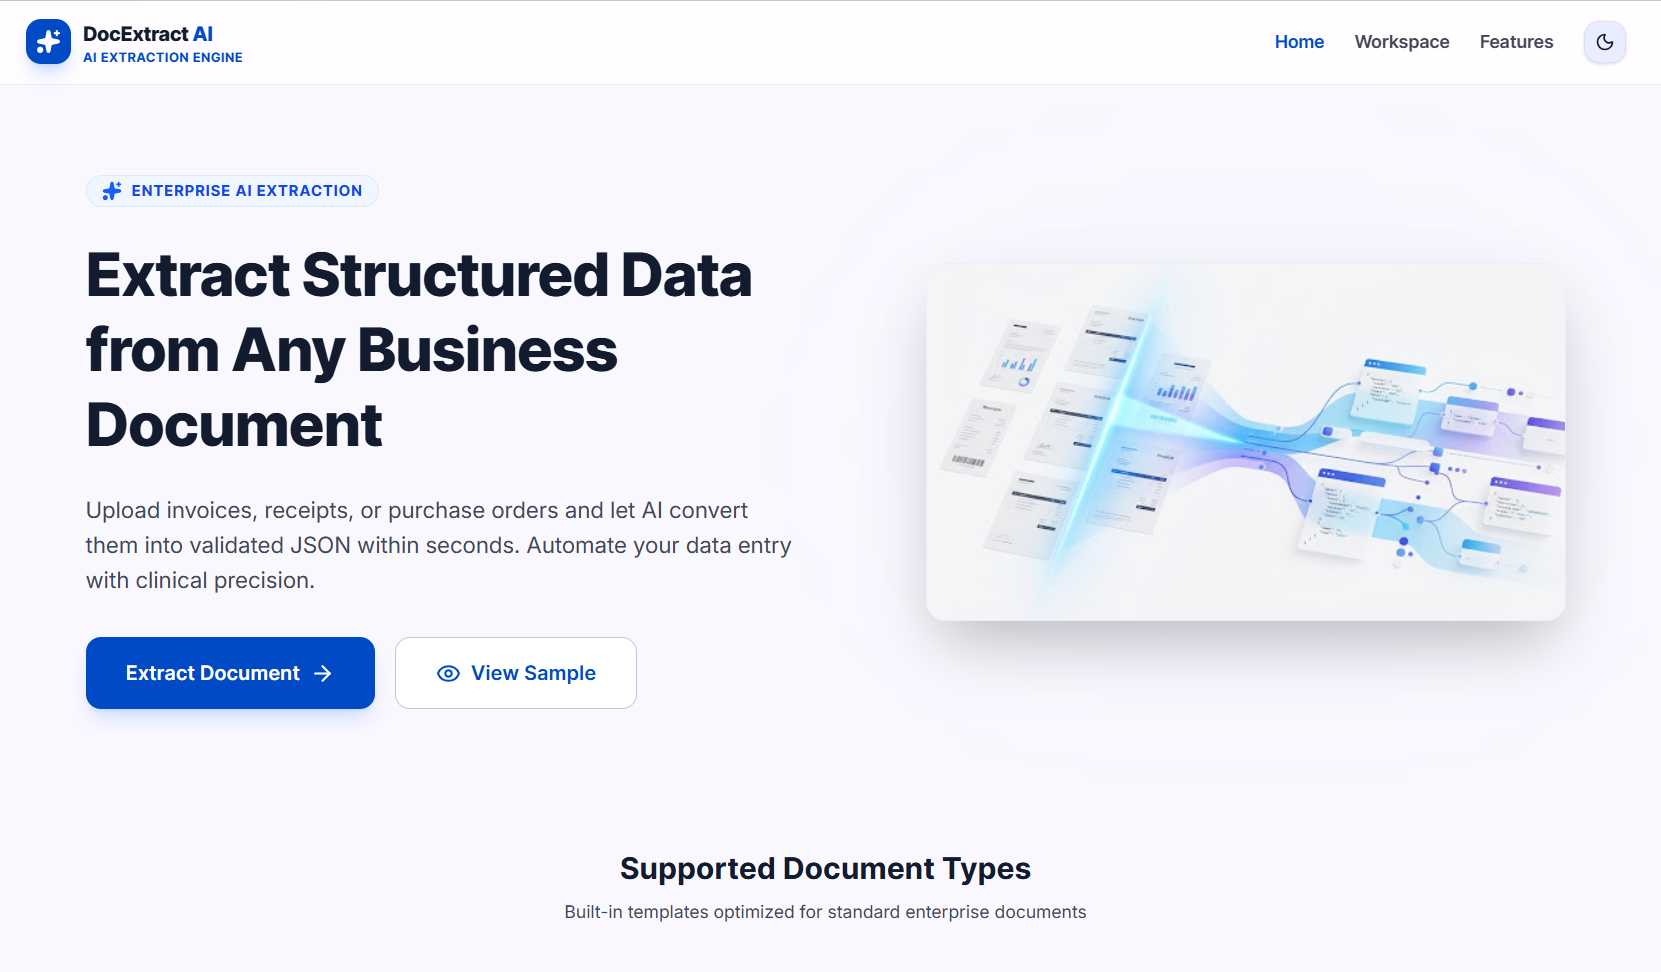
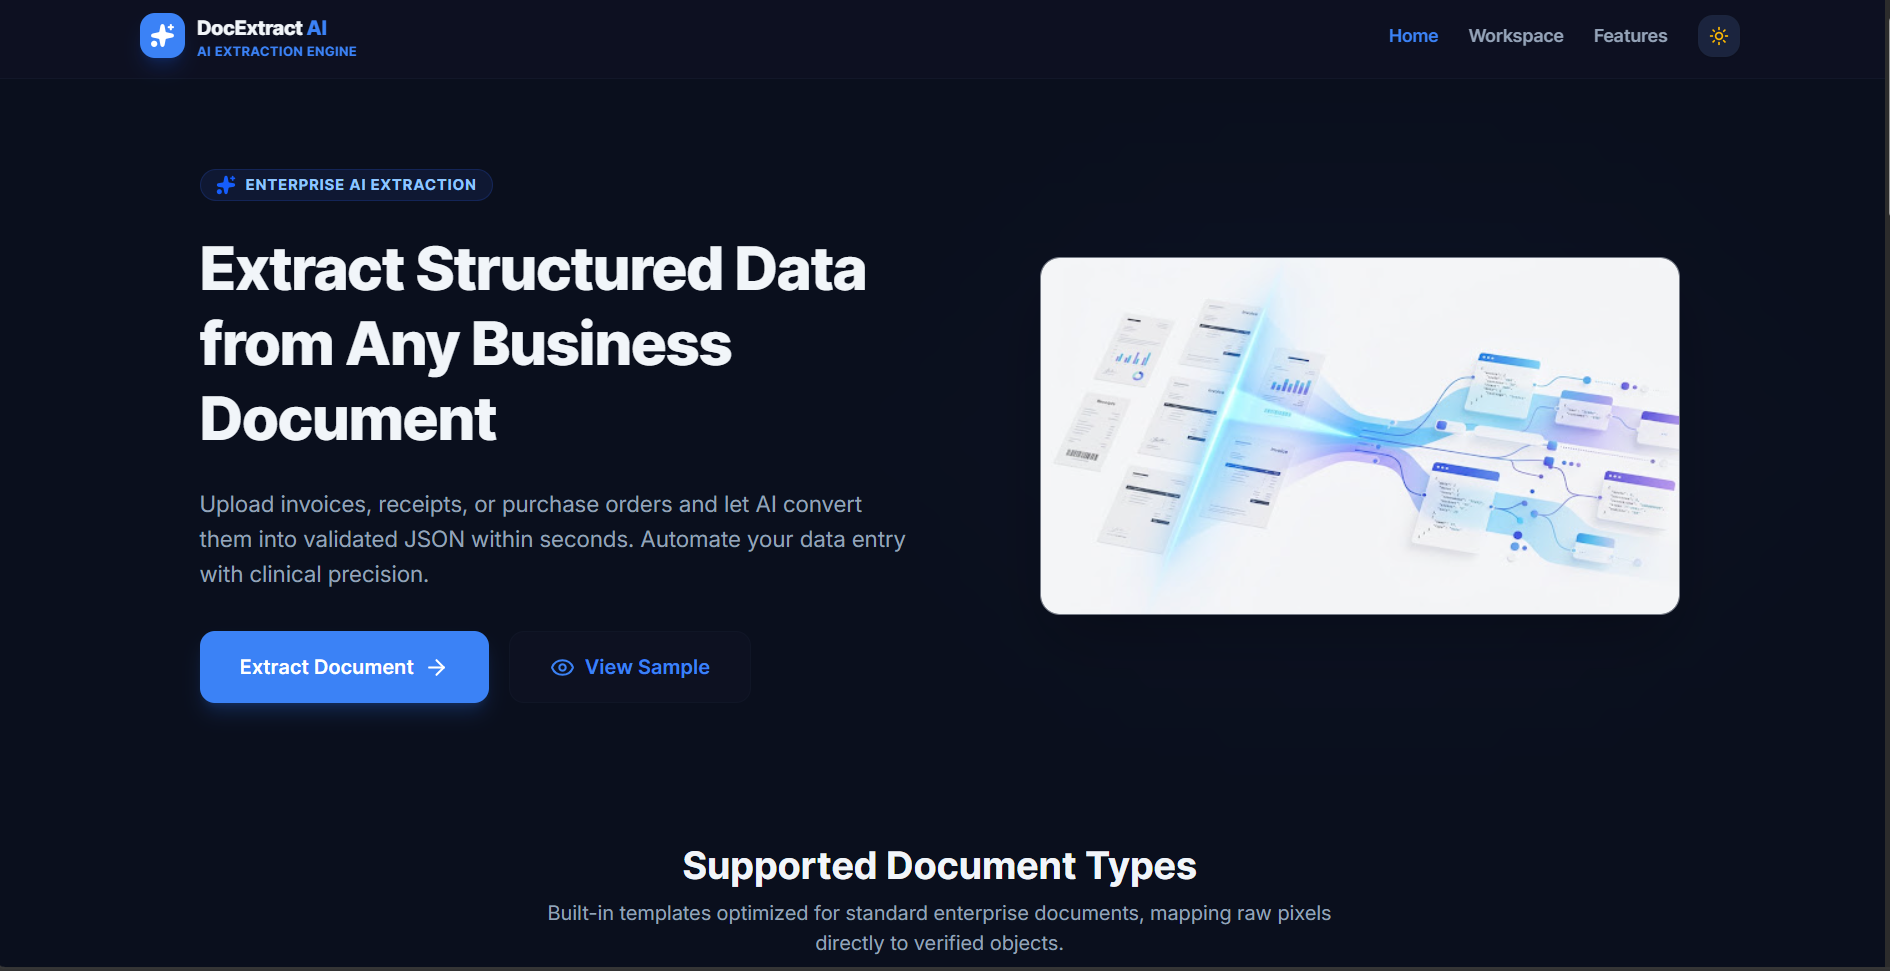
Home Page
-
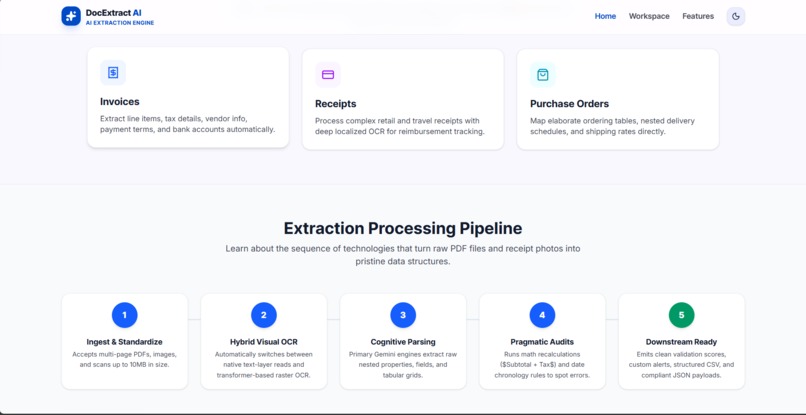
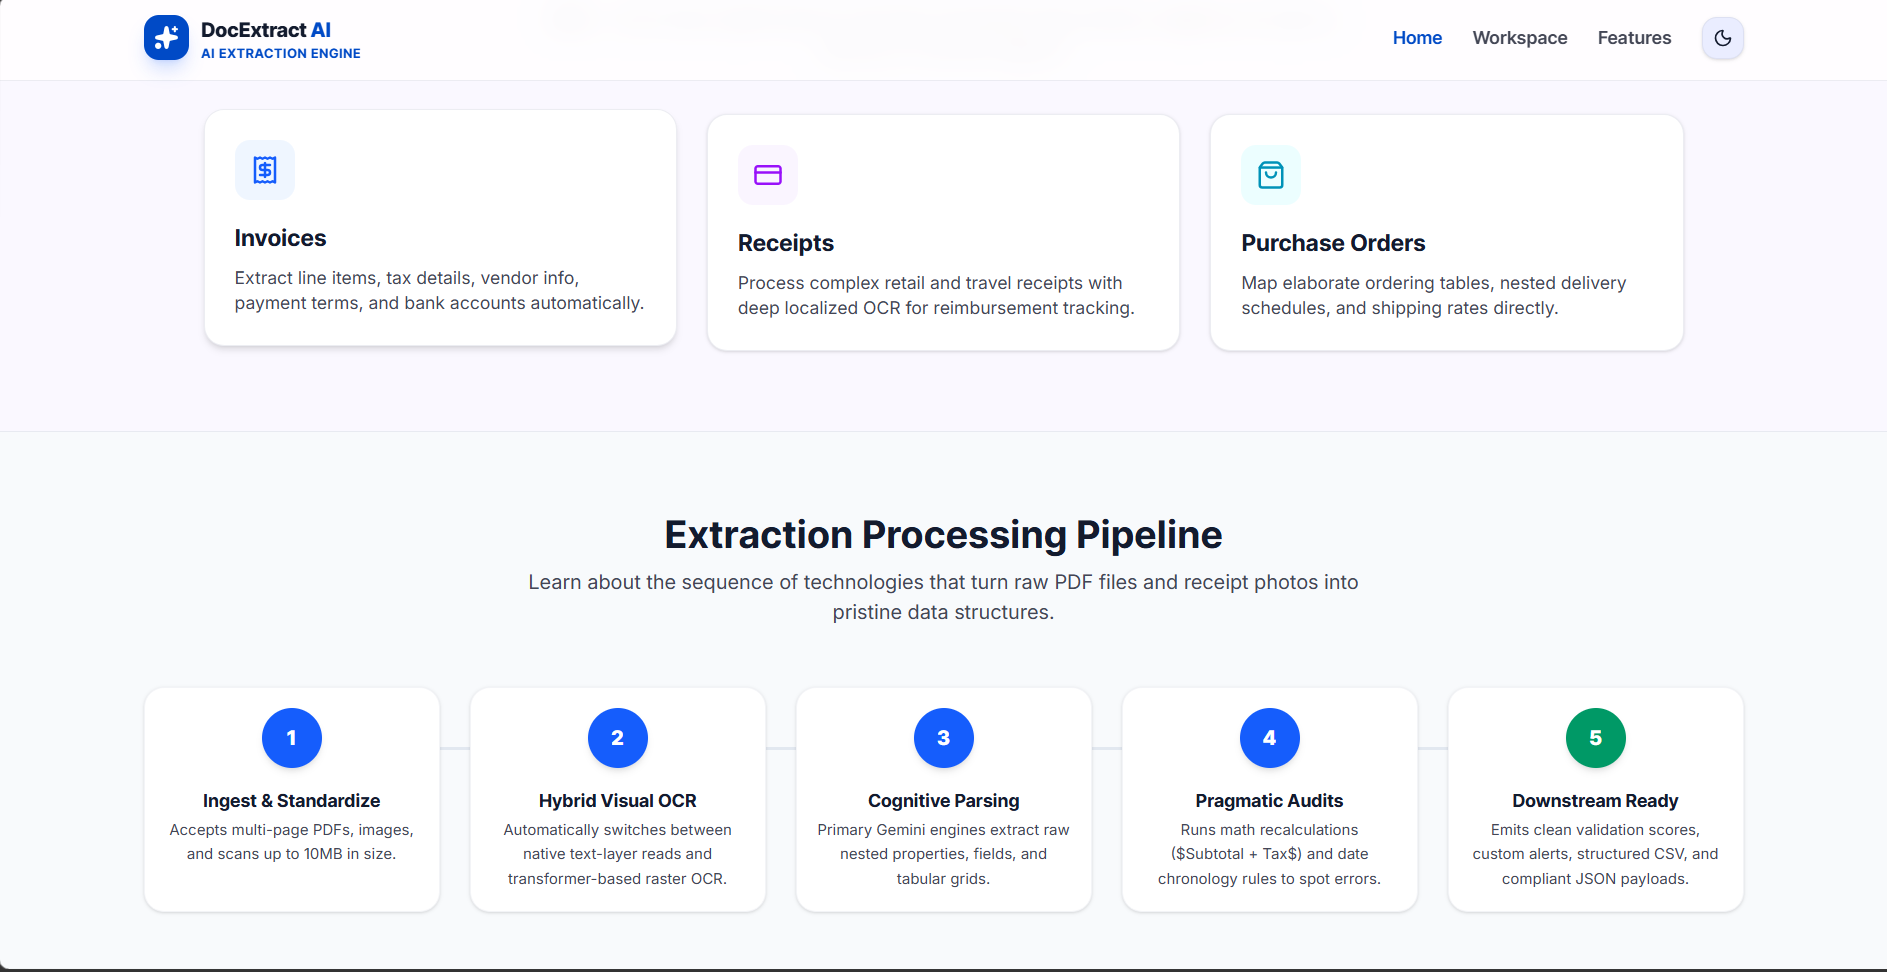
Features
-
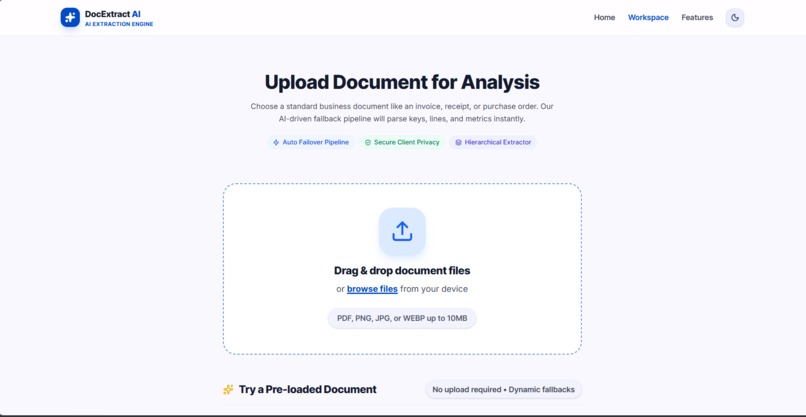
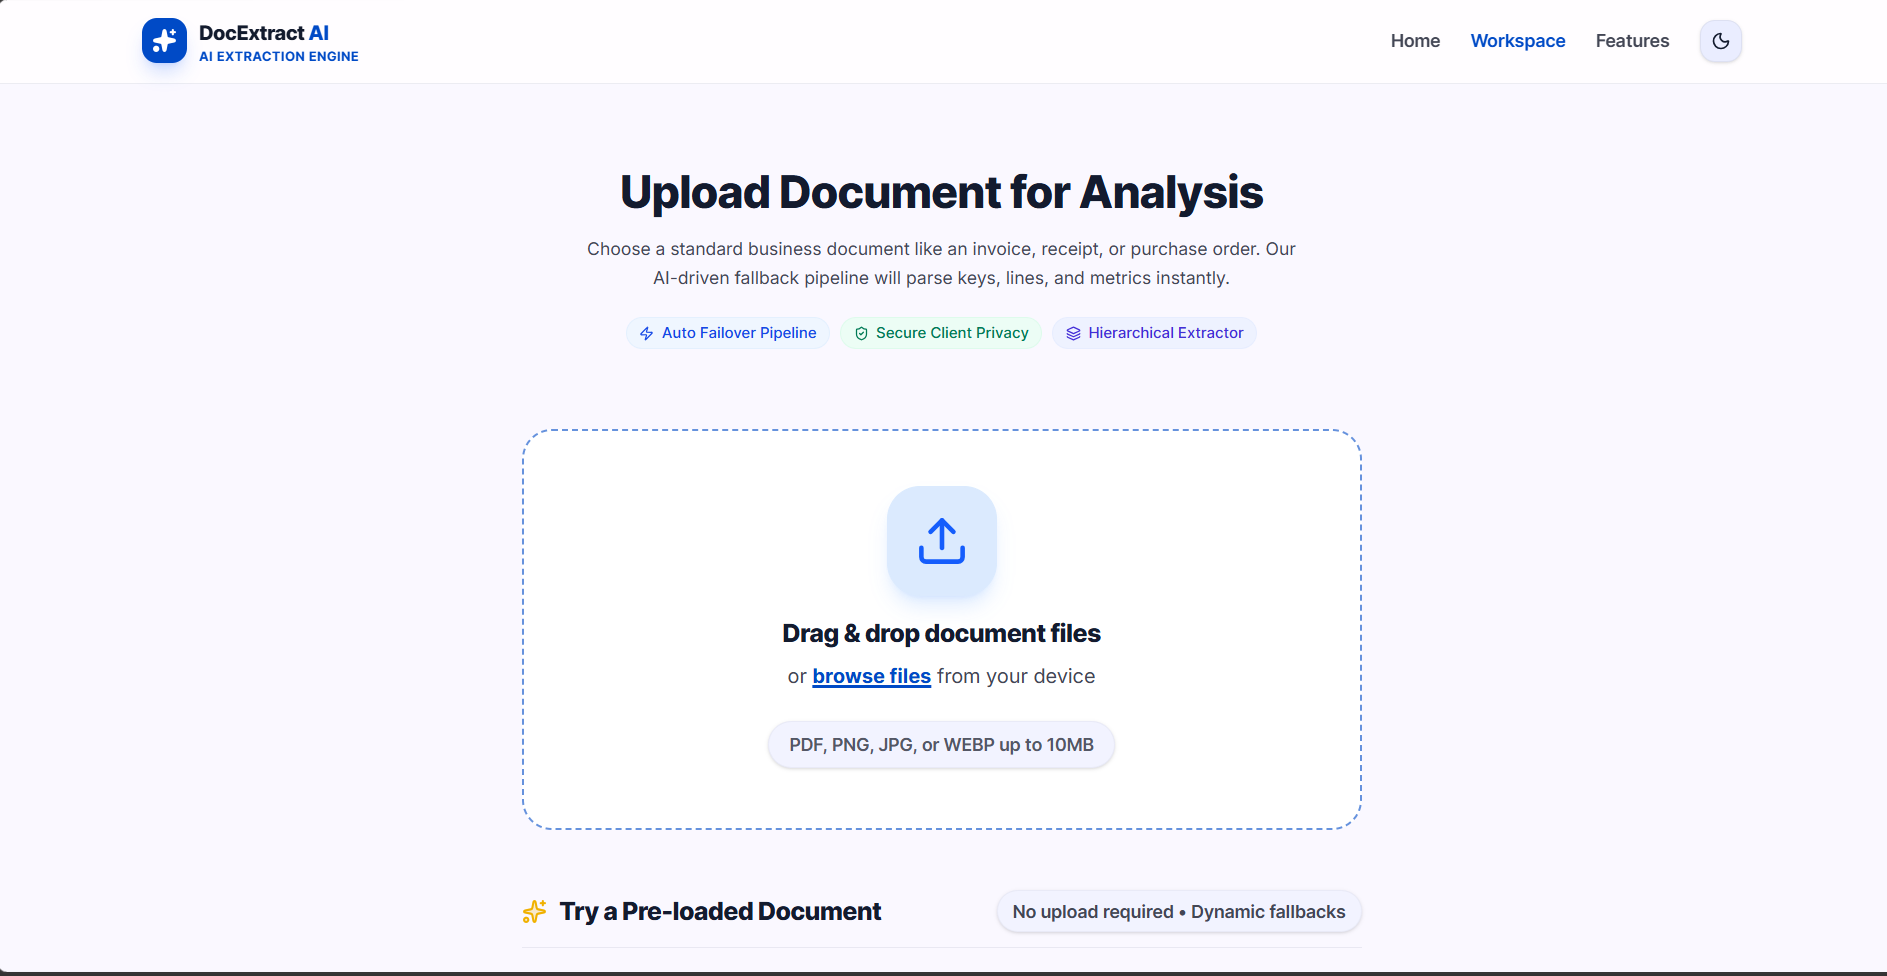
Upload Document Page
-
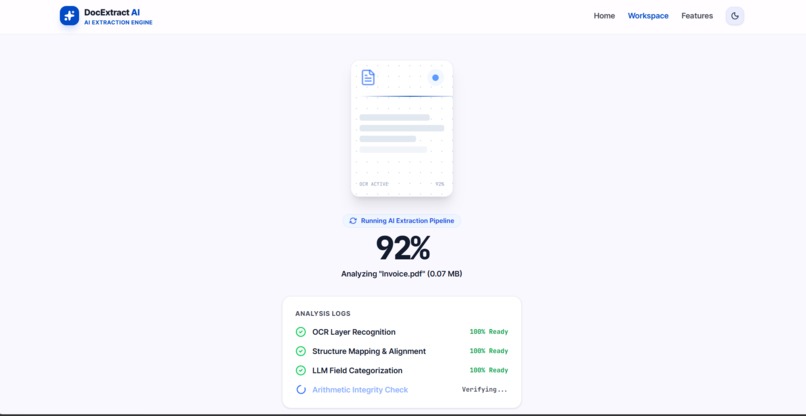
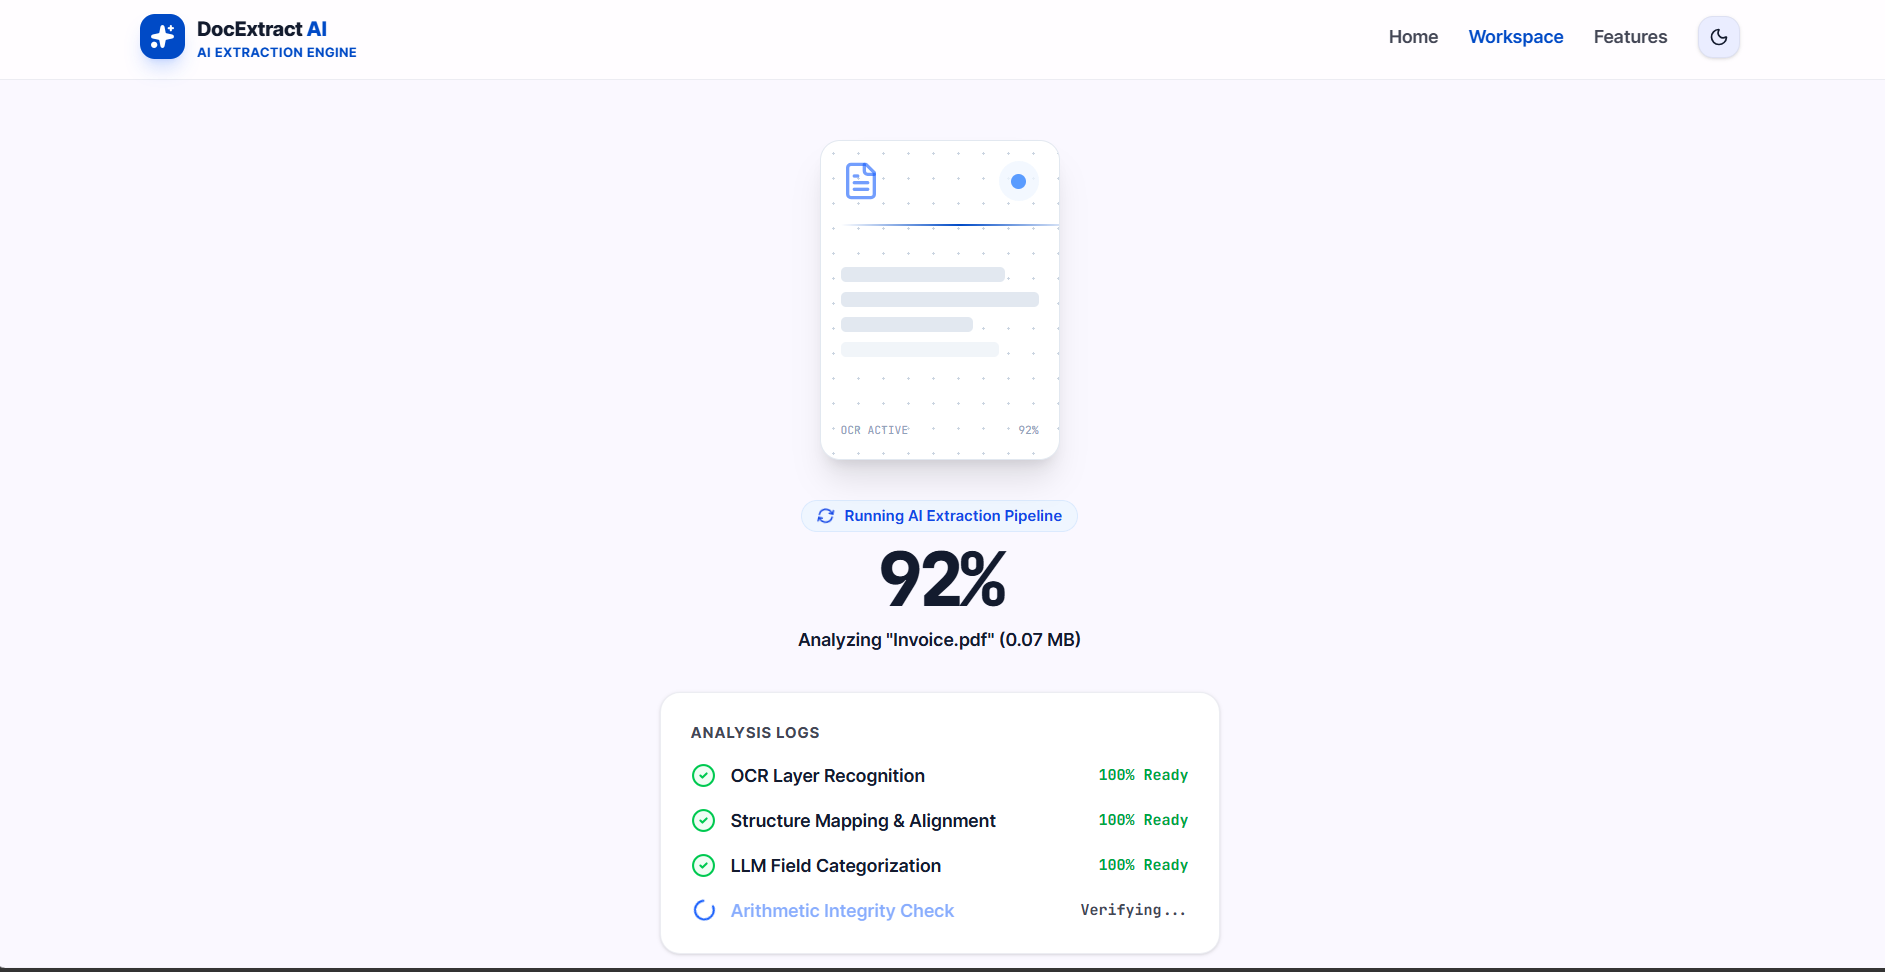
AI Processing Screen
-
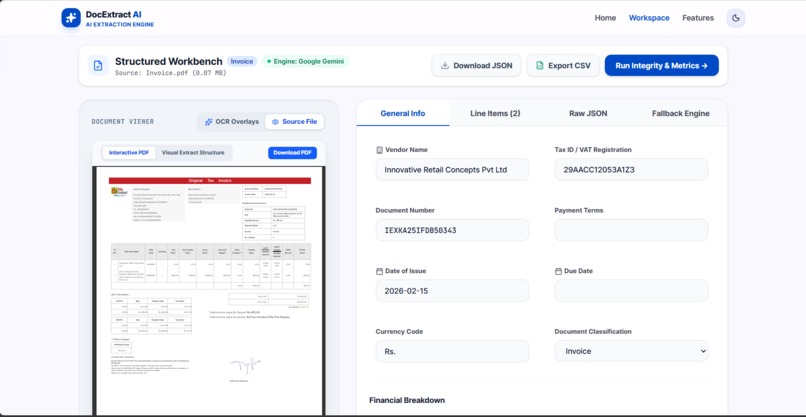
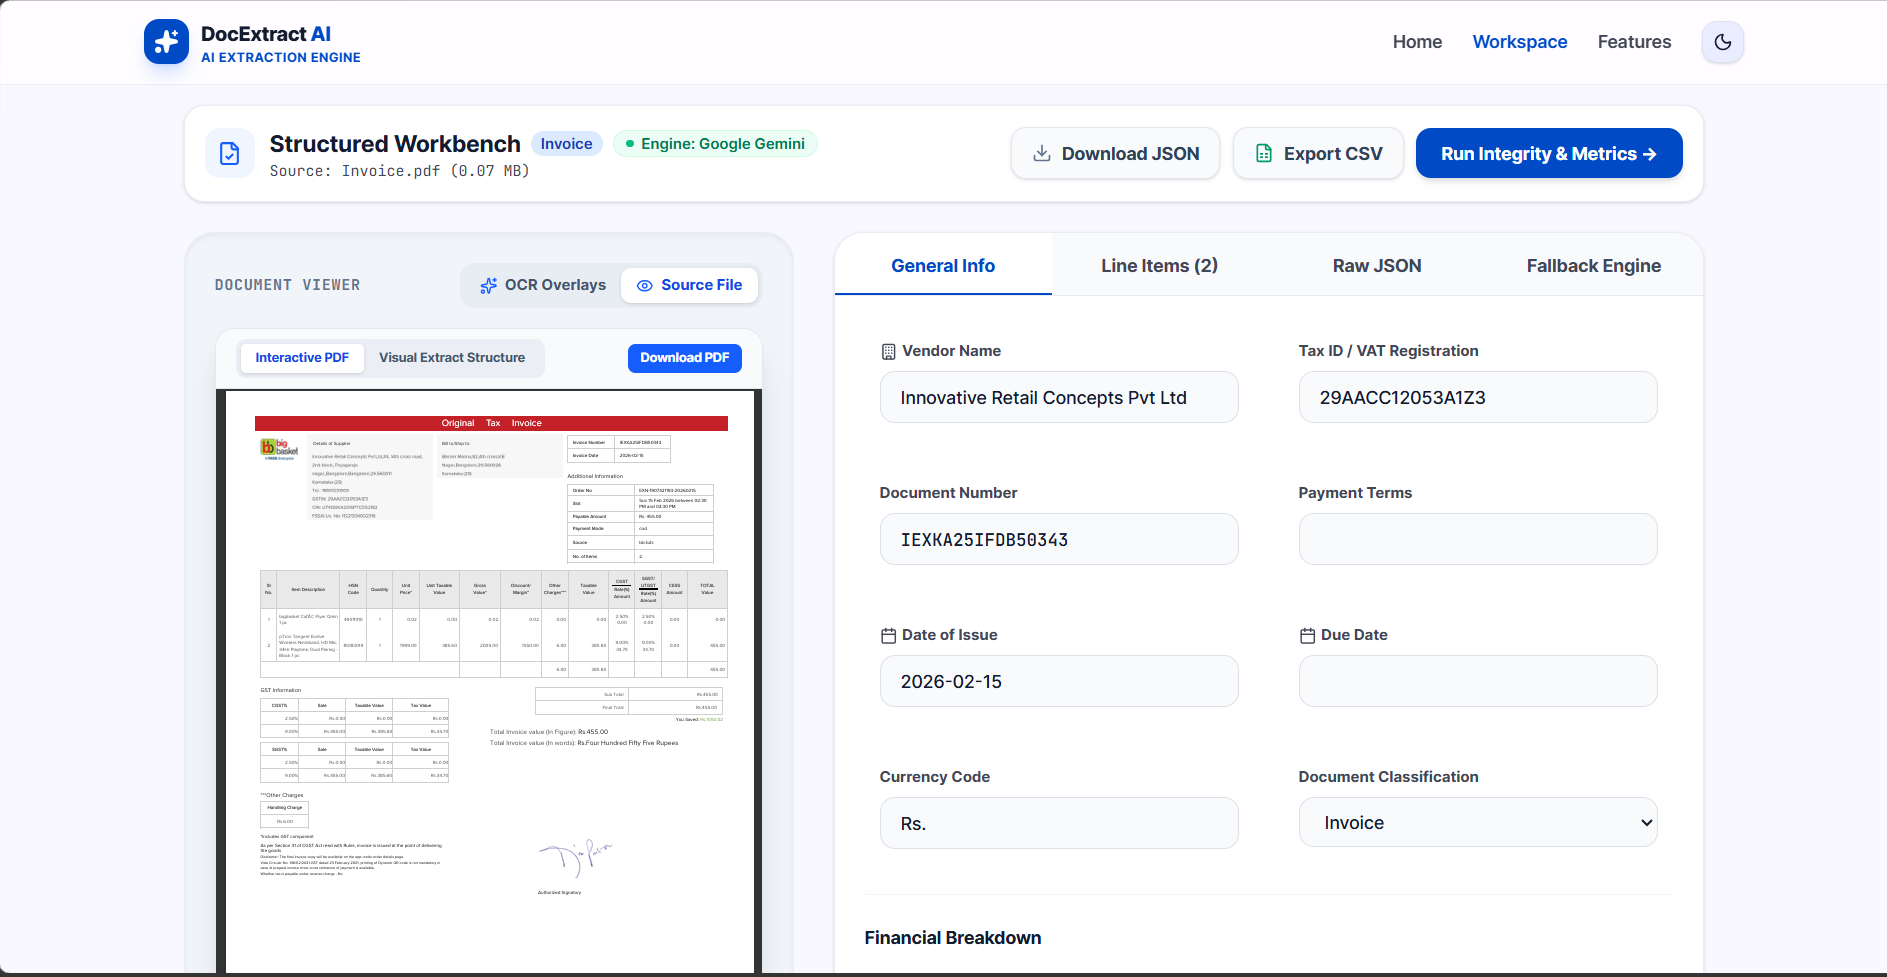
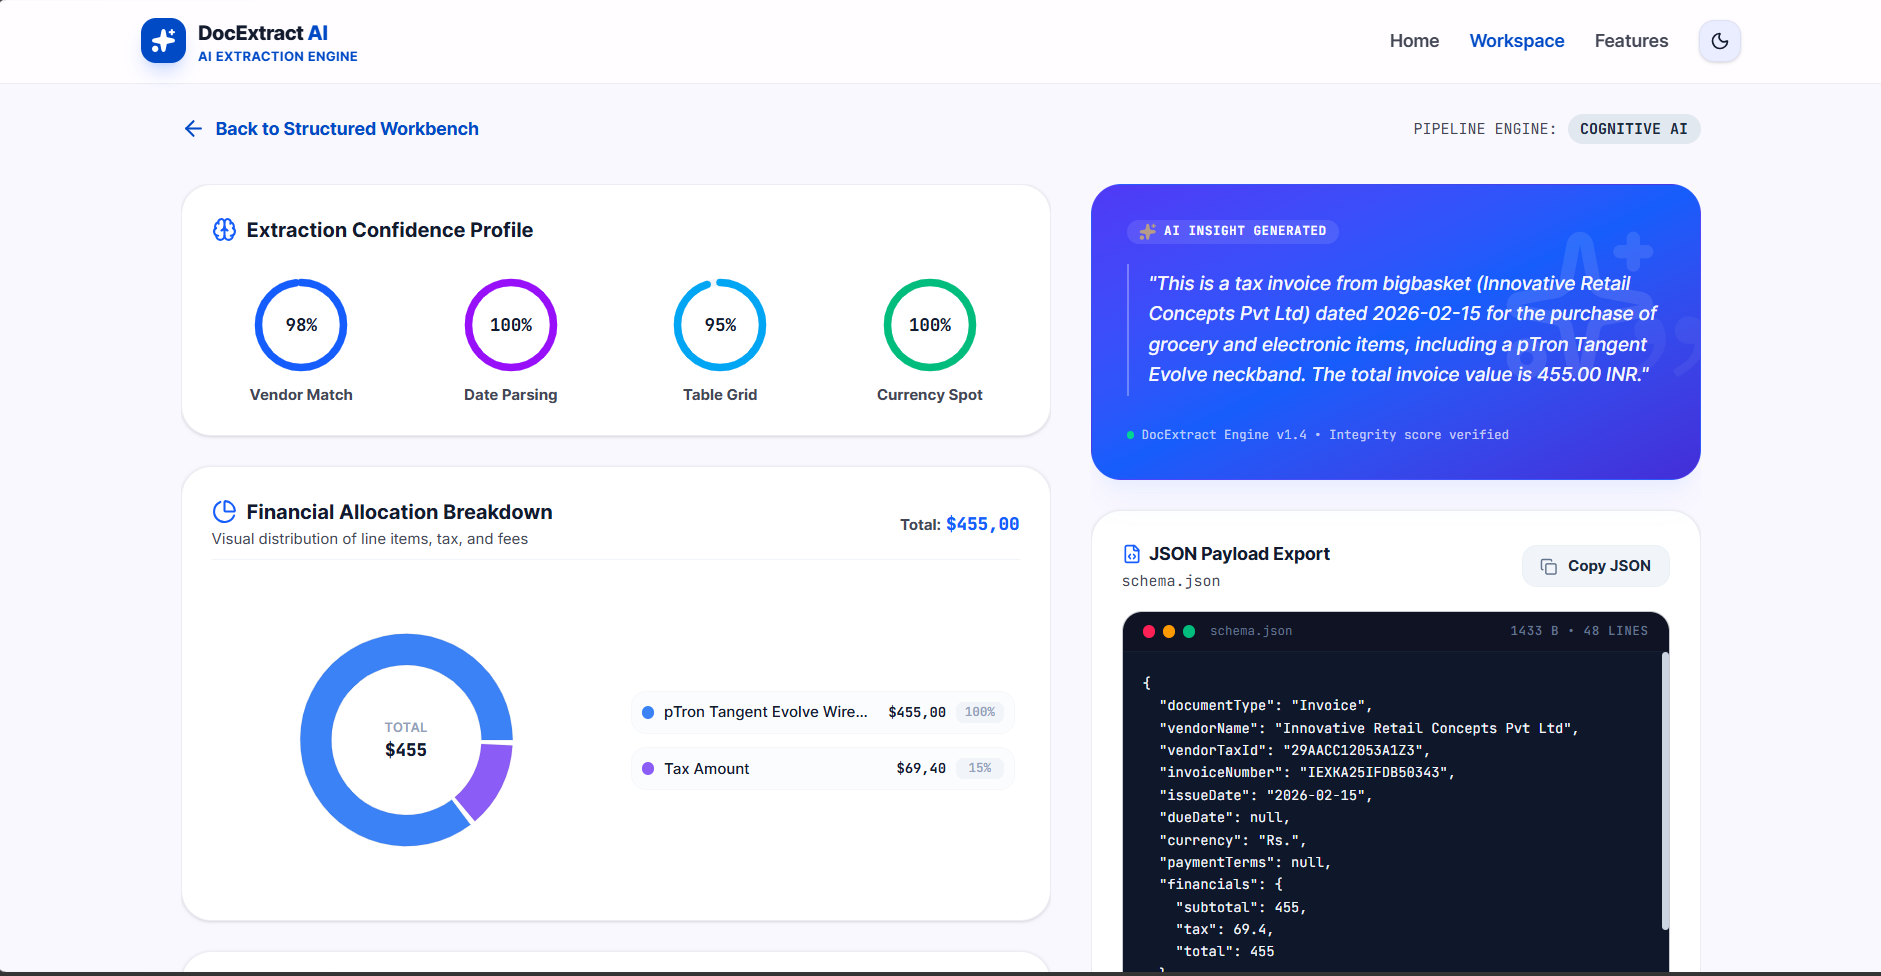
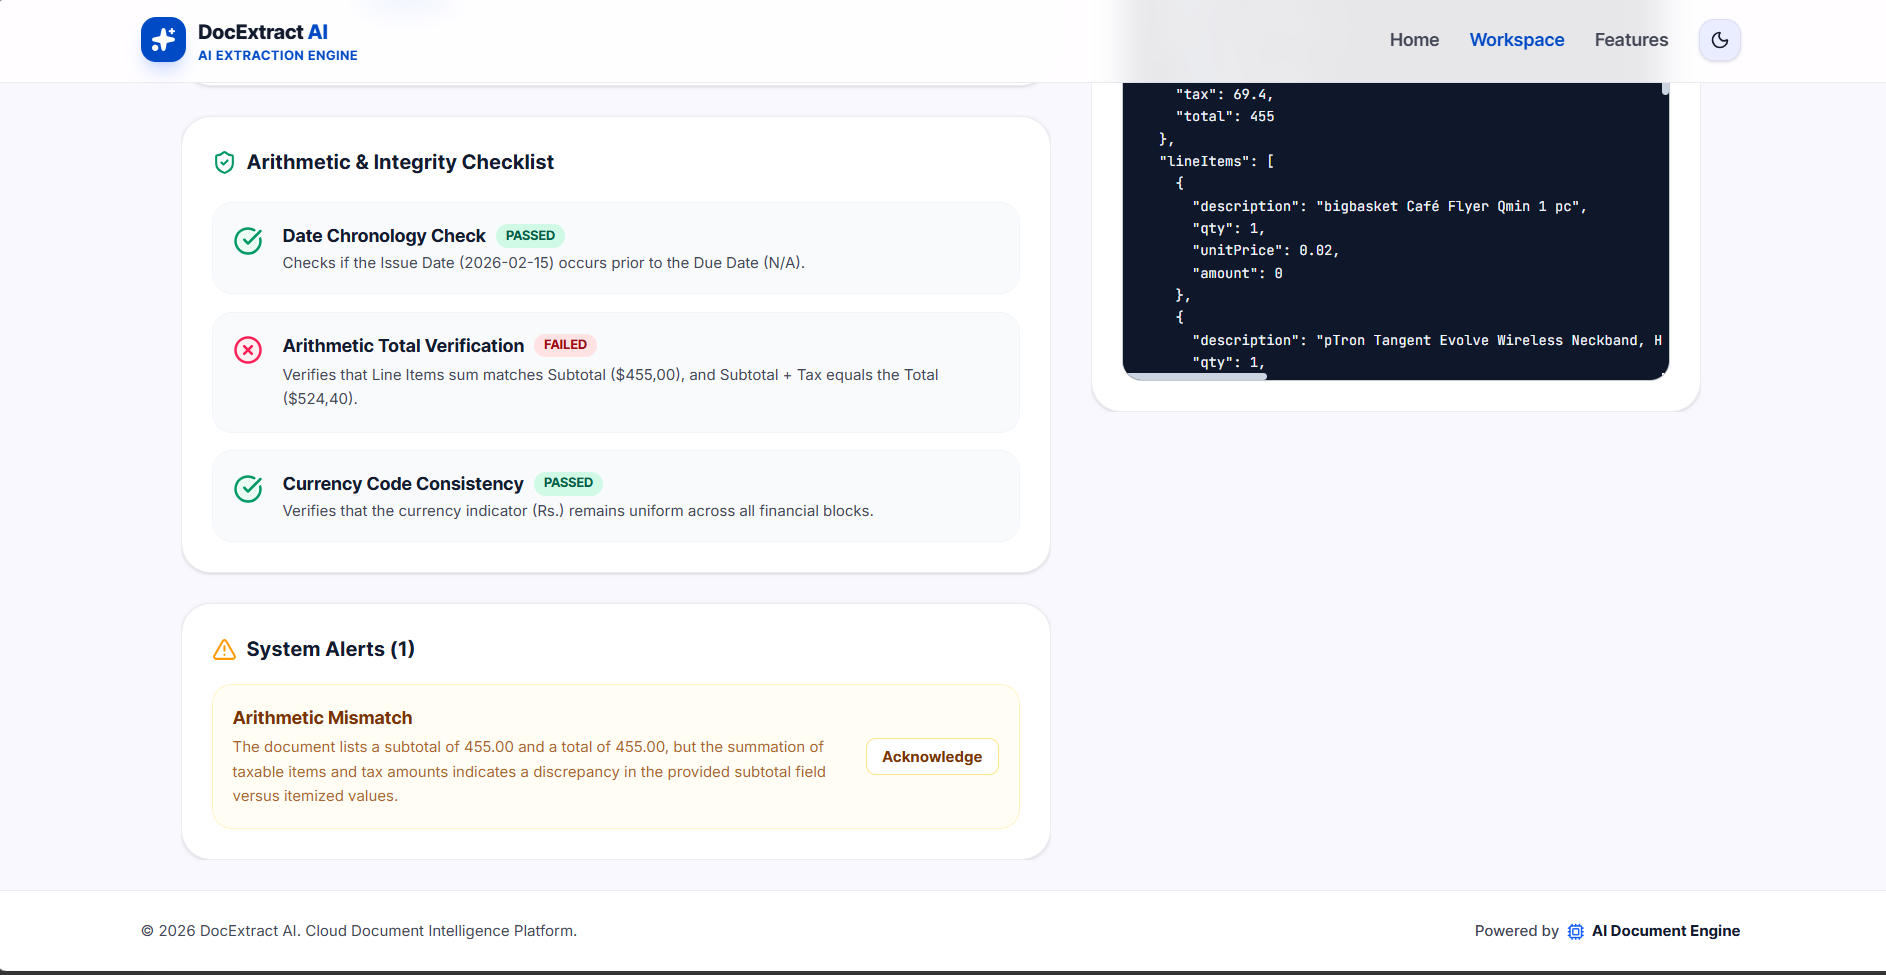
Extraction General Results
-
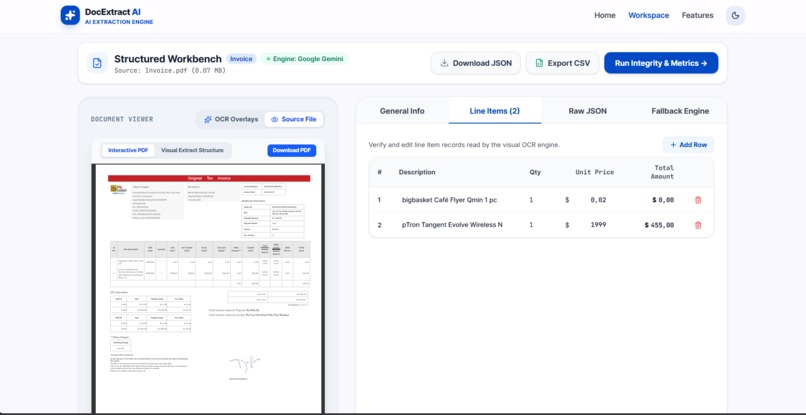
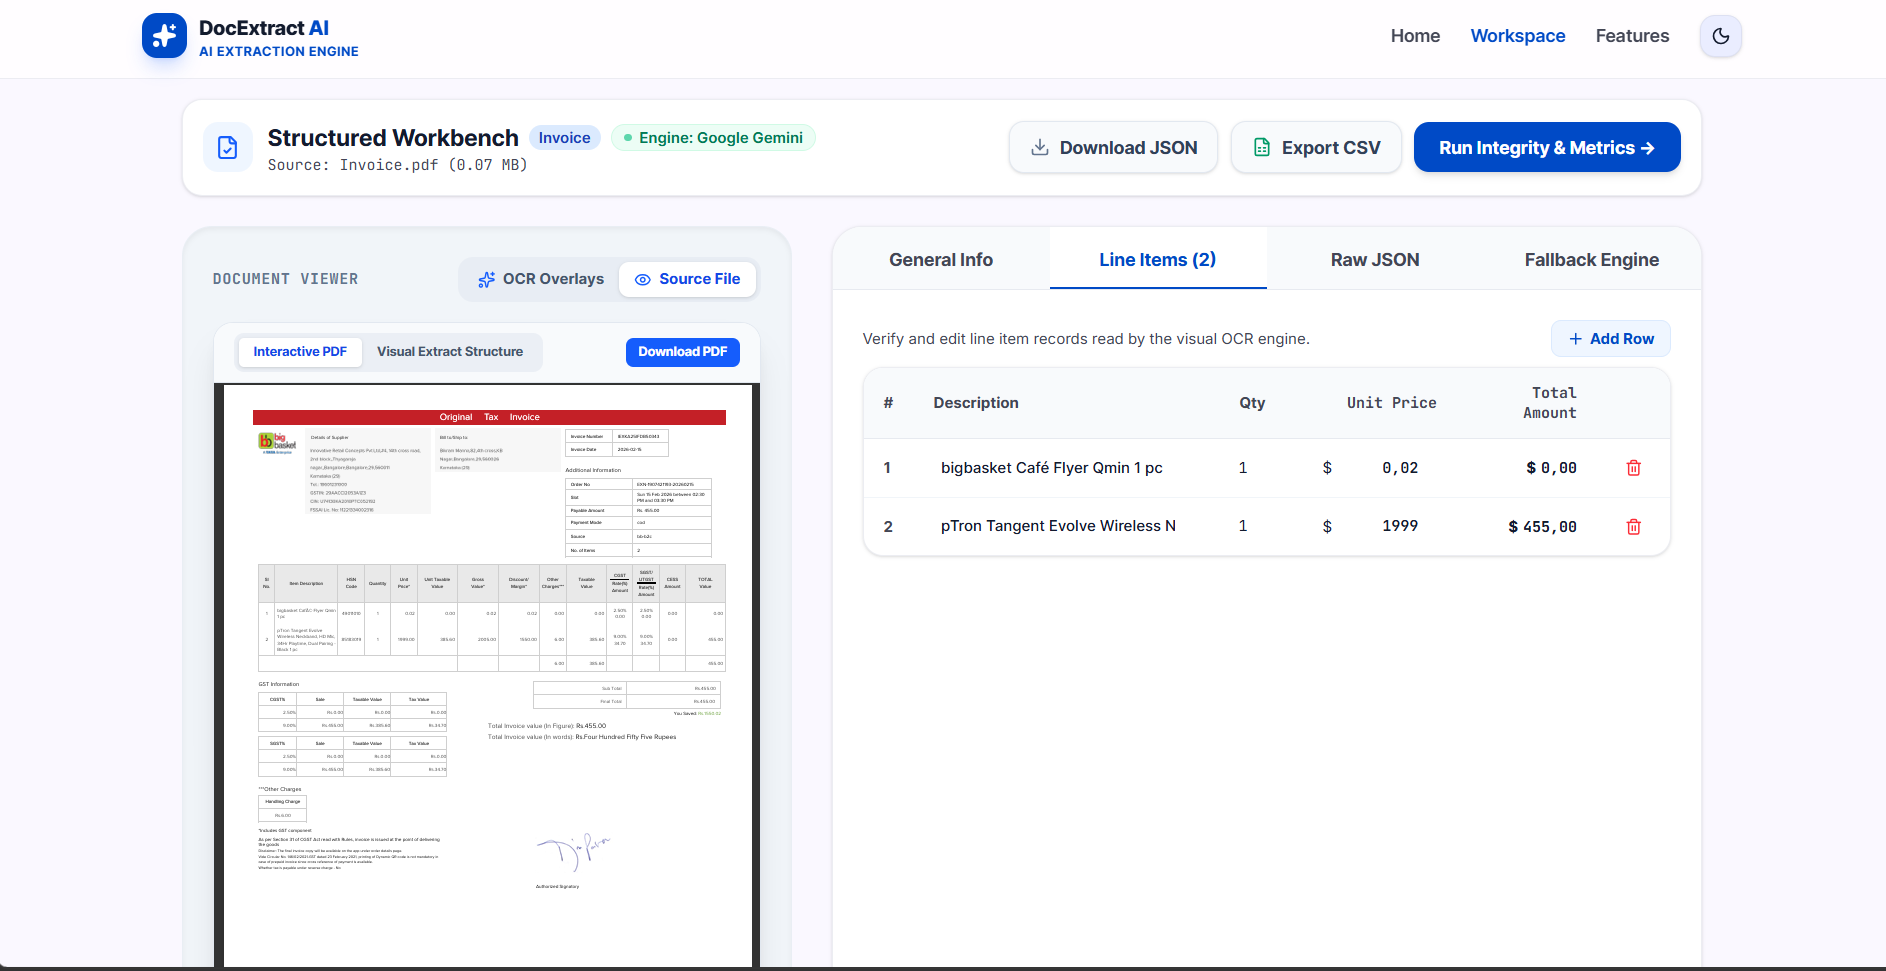
Extraction Line Item Results
-
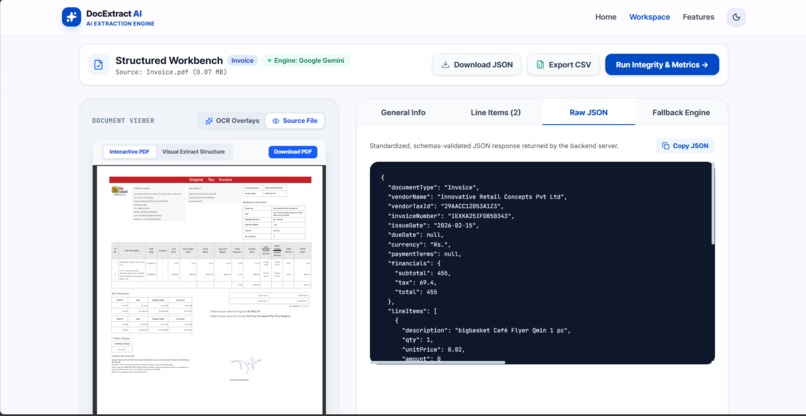
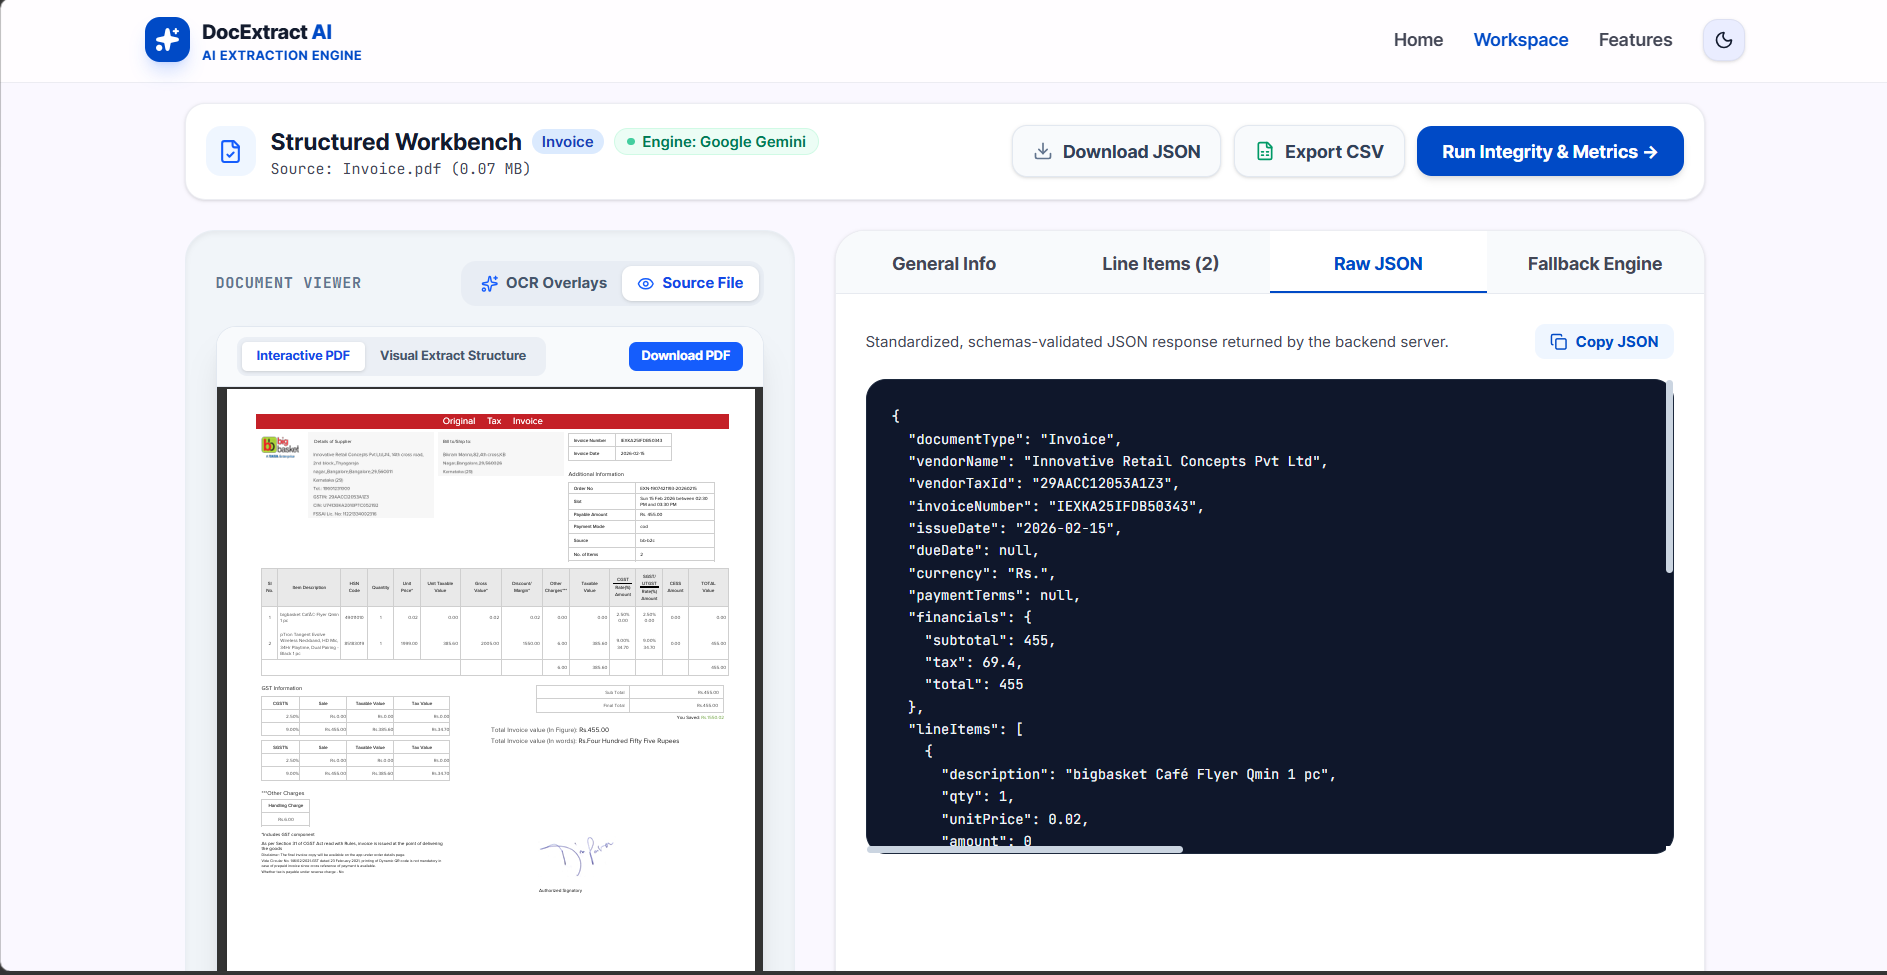
Extraction Json Results
-
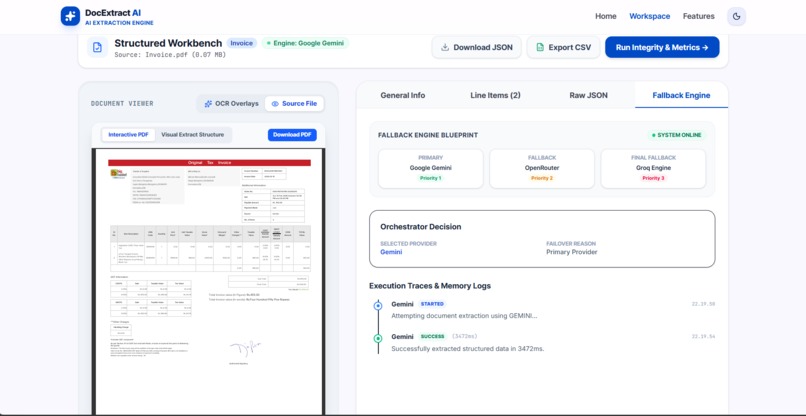
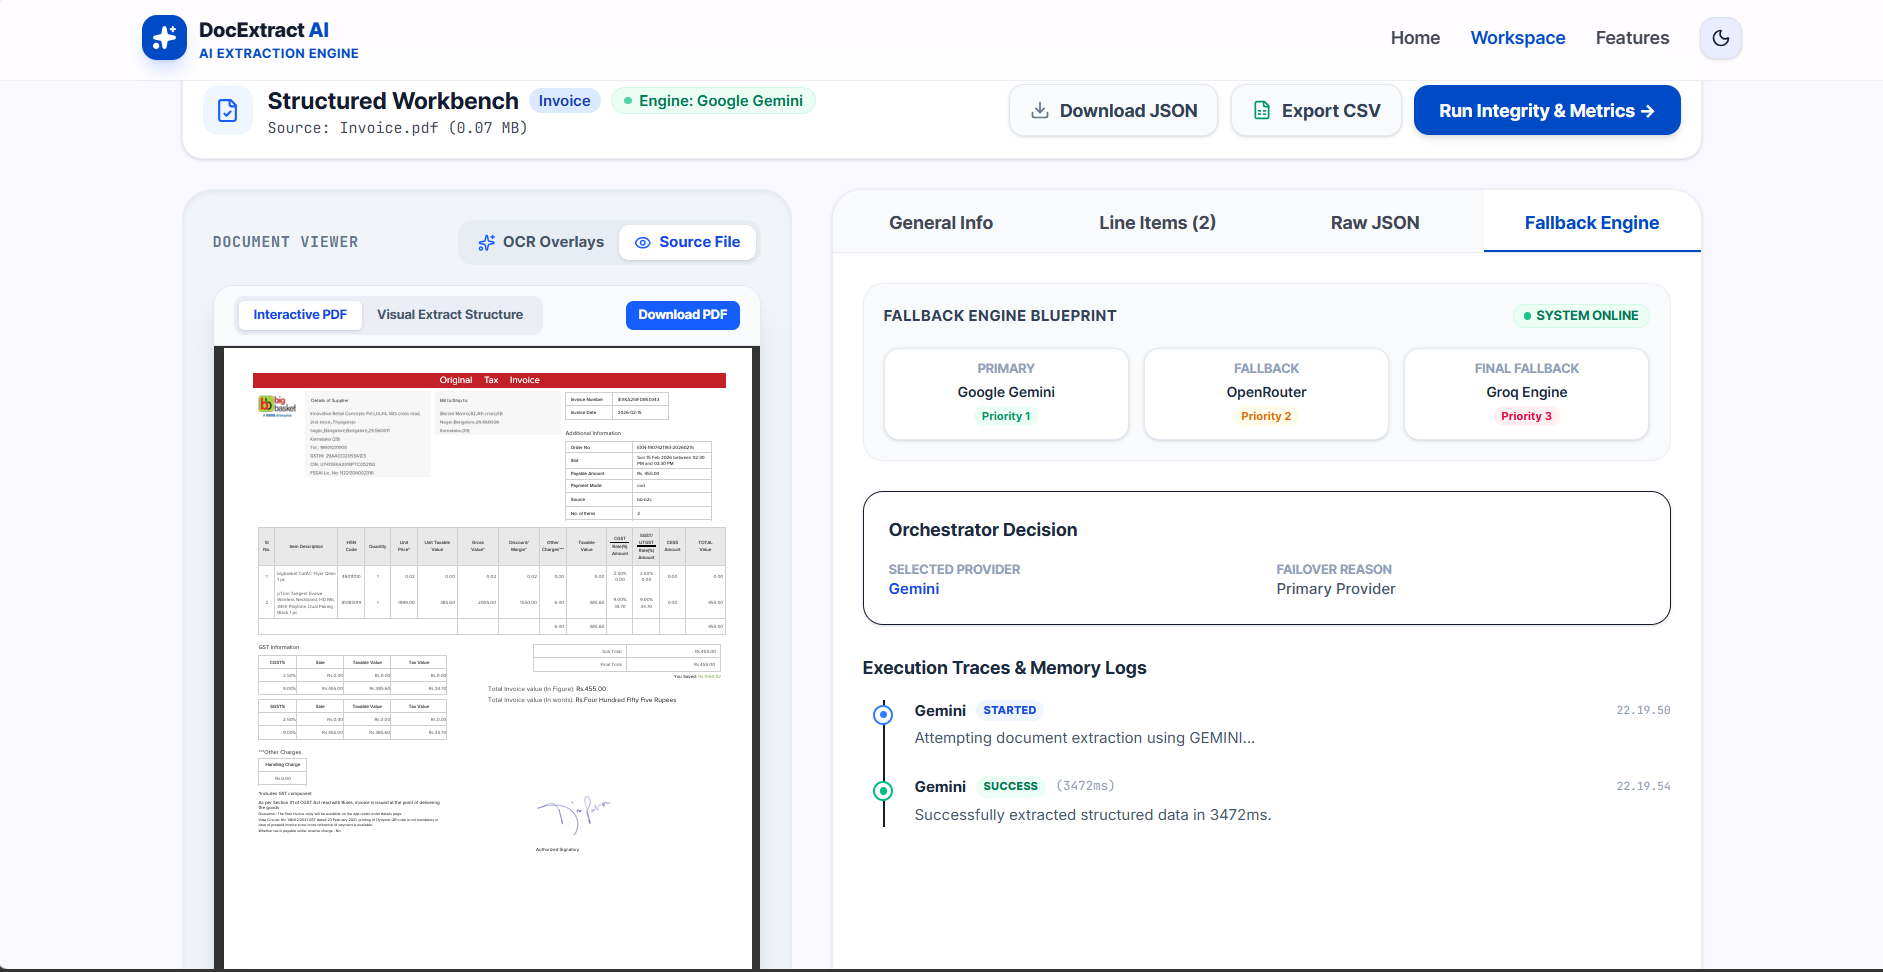
Fallback Engine
-
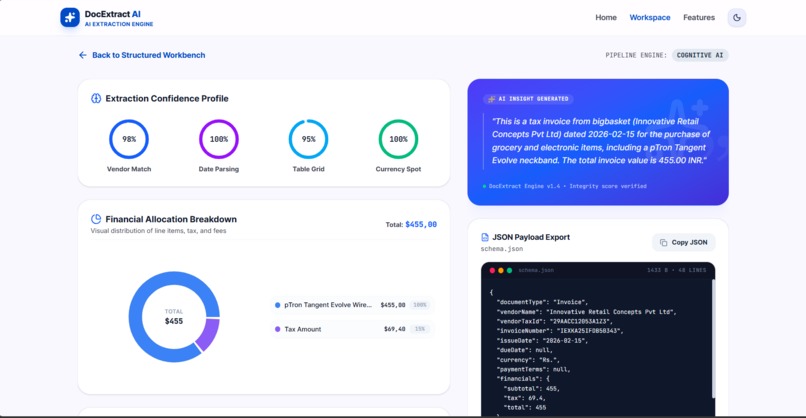
Analytics Dashboard 1
-
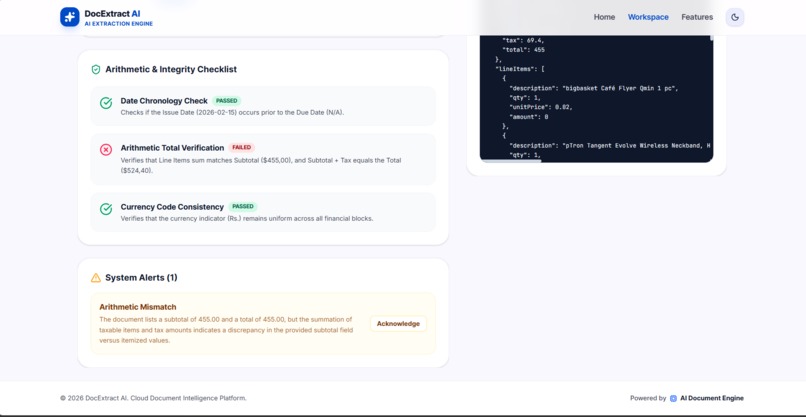
Analytics Dashboard 2
-
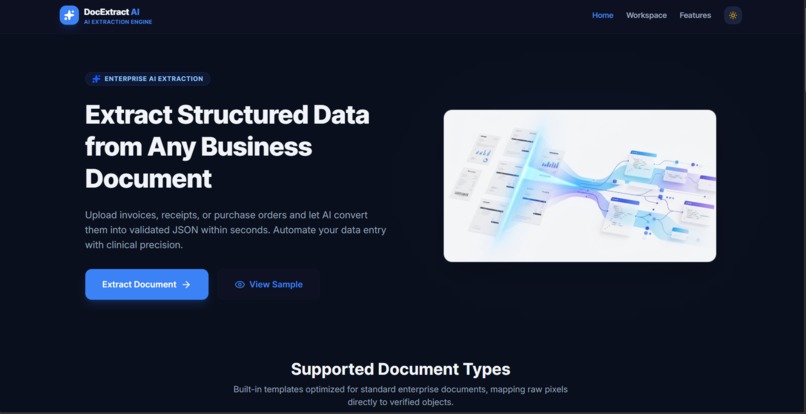
Dark Mode
-
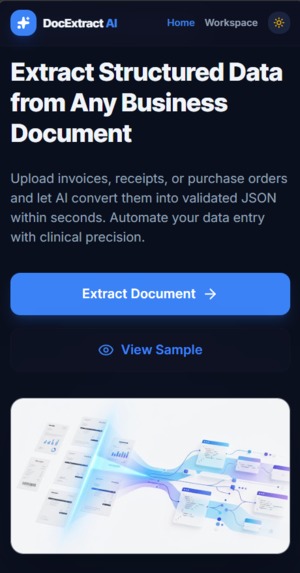
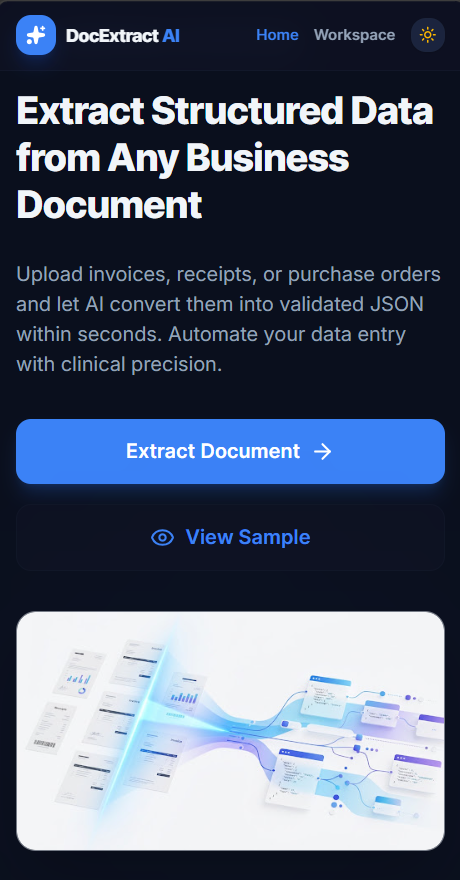
Responsive Mobile View
📄 About the Project
Inspiration
Businesses process thousands of invoices, receipts, and purchase orders every day. Manually extracting information from these documents is time-consuming, error-prone, and expensive. Small businesses often rely on manual data entry, while larger organizations invest in costly enterprise solutions.
We wanted to build an intelligent, AI-powered platform that automates document understanding and transforms unstructured business documents into structured, validated data. Our goal was to simplify document processing, reduce manual effort, and improve operational efficiency.
What it does
DocExtract AI is an intelligent document extraction platform that converts invoices, receipts, and purchase orders into structured JSON data.
The application automatically:
- Uploads and processes PDF and image documents
- Detects whether OCR is required
- Extracts important business information using AI
- Validates financial calculations and extracted fields
- Generates structured JSON for downstream systems
- Allows users to edit extracted data before export
- Exports results in JSON and CSV formats
The platform helps businesses digitize paperwork and accelerate document processing with minimal manual intervention.
How we built it
We built DocExtract AI using a modern full-stack architecture.
Frontend
- React 18
- TypeScript
- Vite
- Tailwind CSS
Backend
- Node.js
- Express
Artificial Intelligence
- Google Gemini API
- OCR using Tesseract.js
- PDF text extraction using pdf.js
The system first determines whether a document contains selectable text or requires OCR. The extracted content is then processed by Google Gemini, which identifies key business entities and converts them into structured JSON. Additional validation checks verify totals, dates, currencies, and document consistency before presenting the final results.
Challenges we ran into
One of the biggest challenges was handling different document layouts. Every invoice or receipt follows a different structure, making consistent extraction difficult.
We also worked on improving extraction reliability by validating numerical calculations, checking date consistency, and handling incomplete or noisy OCR results. Designing prompts that produced accurate, structured JSON while minimizing hallucinations was another significant challenge.
Accomplishments that we're proud of
- Successfully built a complete AI-powered document extraction platform.
- Integrated Google Gemini for intelligent document understanding.
- Automated extraction of invoices, receipts, and purchase orders.
- Implemented validation checks for dates, totals, taxes, and currency consistency.
- Designed a clean, modern, and responsive user interface.
- Enabled structured JSON export for seamless business integration.
What we learned
Throughout this project, we gained practical experience in:
- Building AI-powered document intelligence systems
- Prompt engineering with Google Gemini
- OCR and PDF processing workflows
- Designing scalable full-stack applications
- Data validation and structured information extraction
- Creating intuitive user interfaces for AI applications
What's next for DocExtract AI
We plan to extend the platform with:
- AI-powered document chat
- Multi-language document understanding
- Automatic expense categorization
- ERP and accounting software integrations
- Batch document processing
- Enterprise workflow automation
- Advanced analytics dashboard
- Mobile application support
Our vision is to make DocExtract AI a comprehensive document intelligence platform that enables organizations to automate document processing efficiently and accurately.
Built With
- ai
- api
- artificial
- css
- data-extraction
- document
- express.js
- gemini
- github
- intelligence
- javascript
- json
- learning
- machine
- netlify
- node.js
- ocr
- pdf.js
- react
- rest
- tailwind
- tesseract.js
- typescript
- vite
