Tested, not just demoed: 96.2% exact verdicts on 3,000 test cases, with 0.3% false alarms. A keyword script gets 55.8%, with 17.7% false alarms.
Inspiration
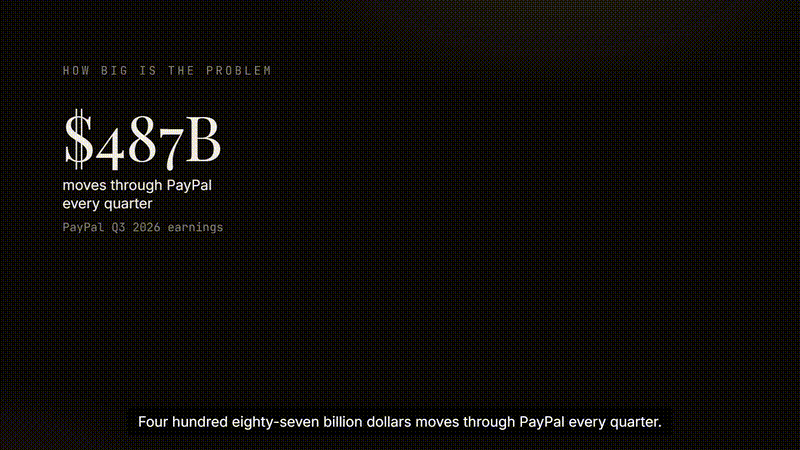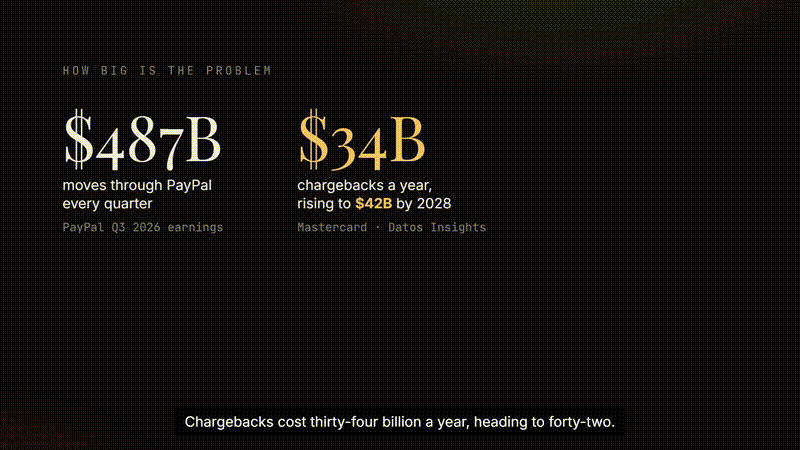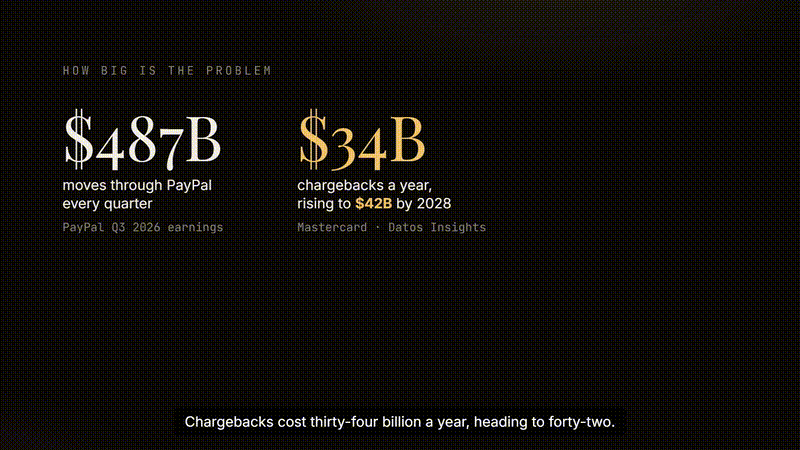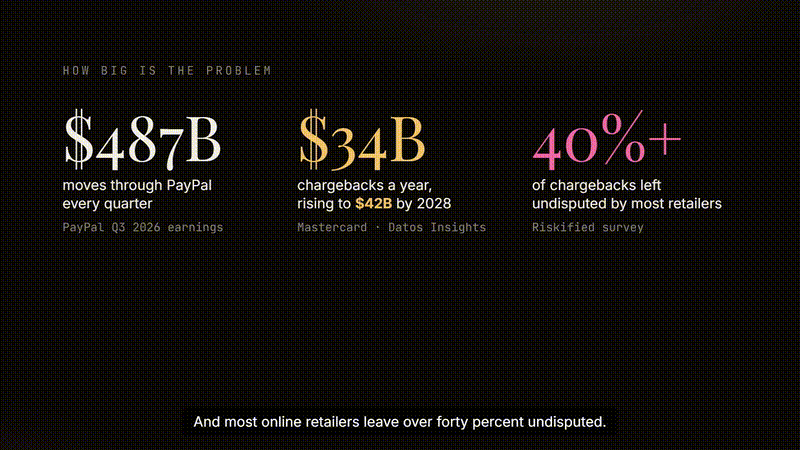
- Chargebacks cost merchants $34B a year (Mastercard / Datos Insights).
- Most online retailers leave over 40% of chargebacks undisputed (Riskified).
They usually weren't wrong. The proof was spread across invoices, emails and carrier pages, and the deadline came first. We wanted a tool that collects the proof, says exactly what's missing, and never makes a number up.
What it does
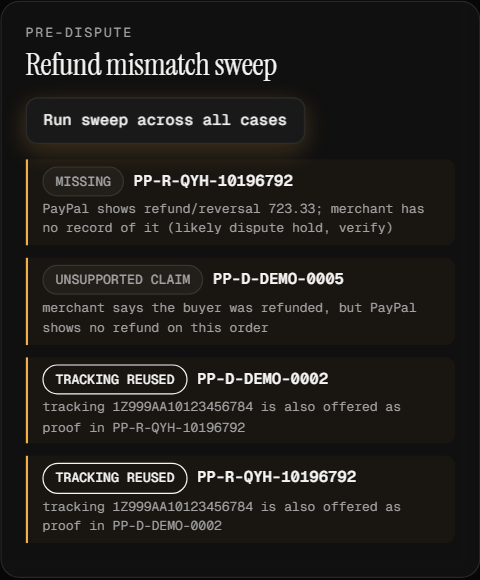
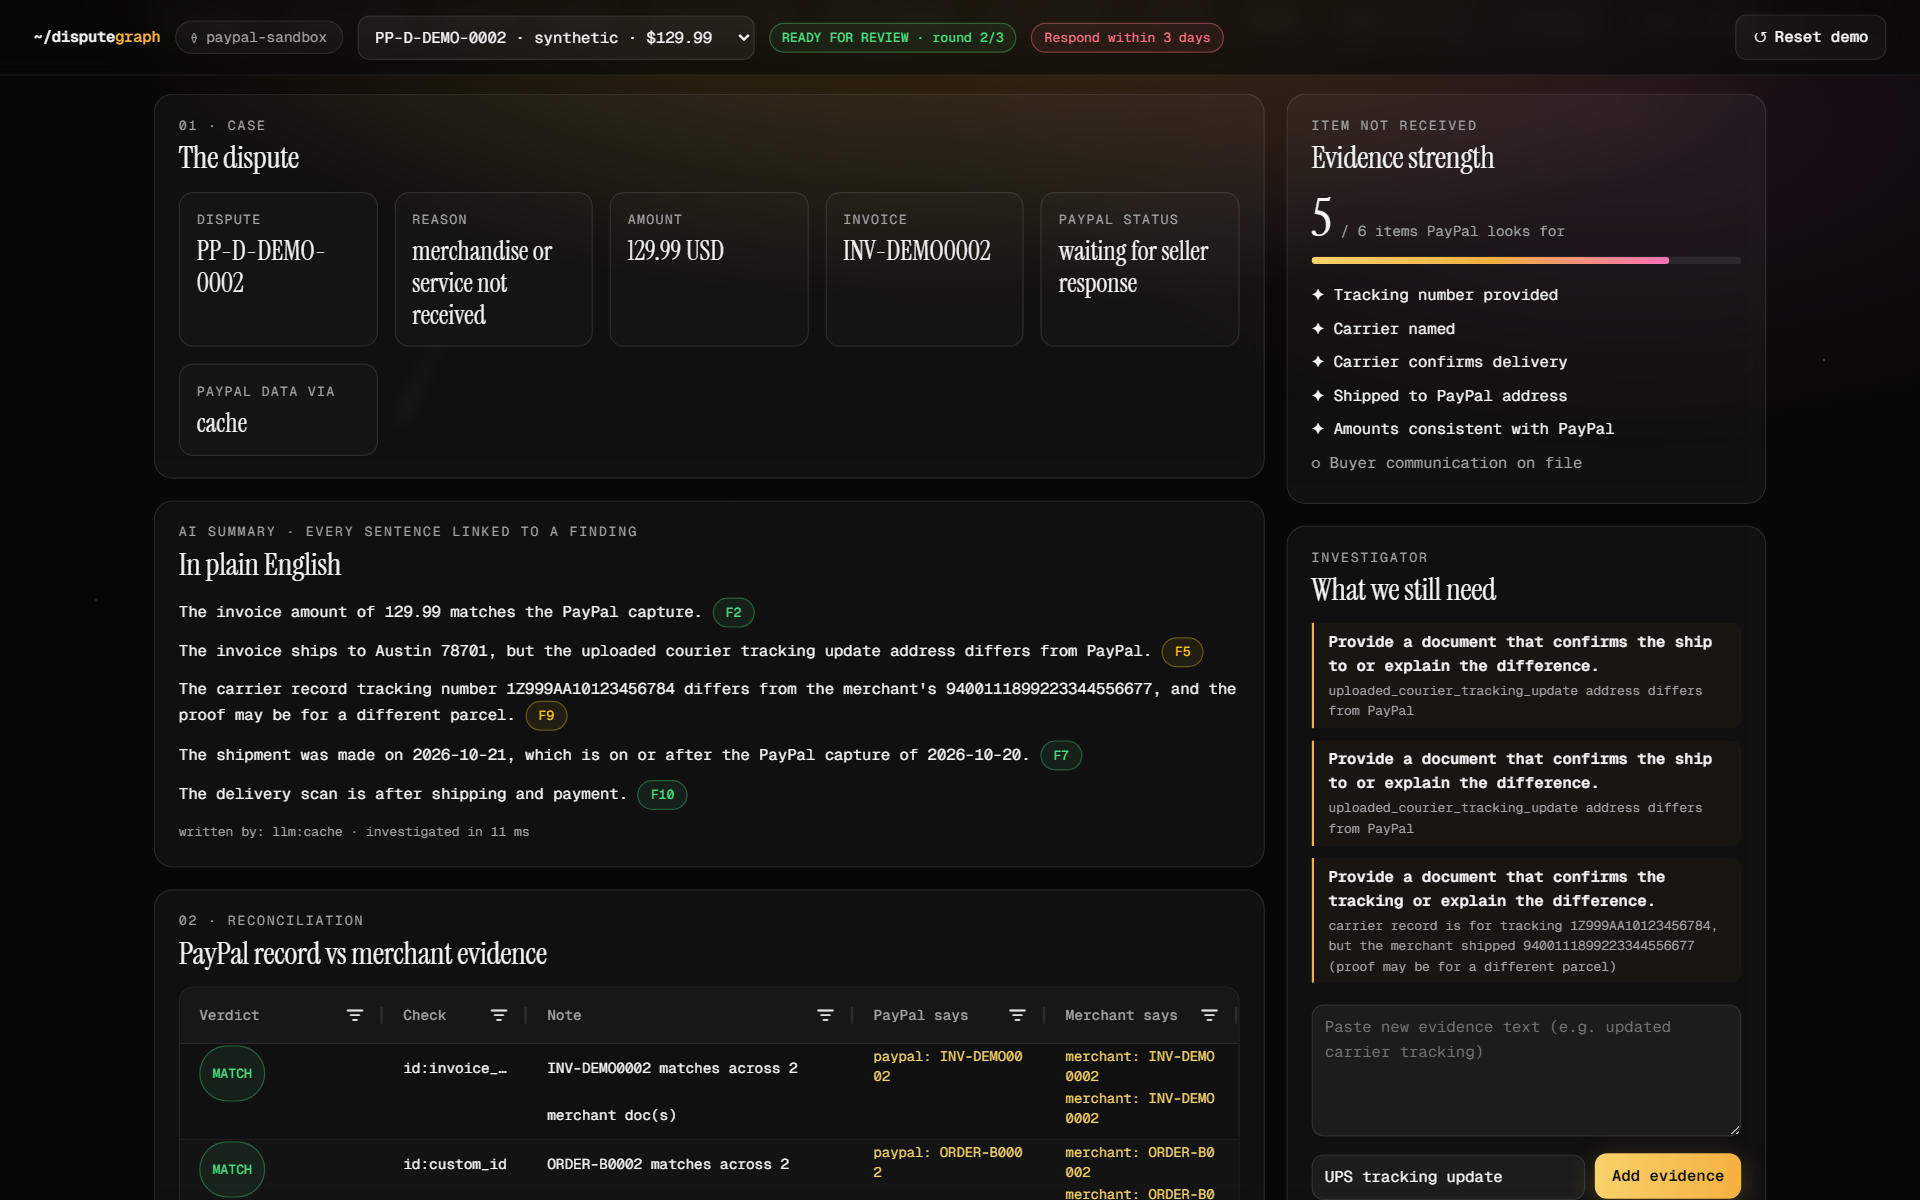
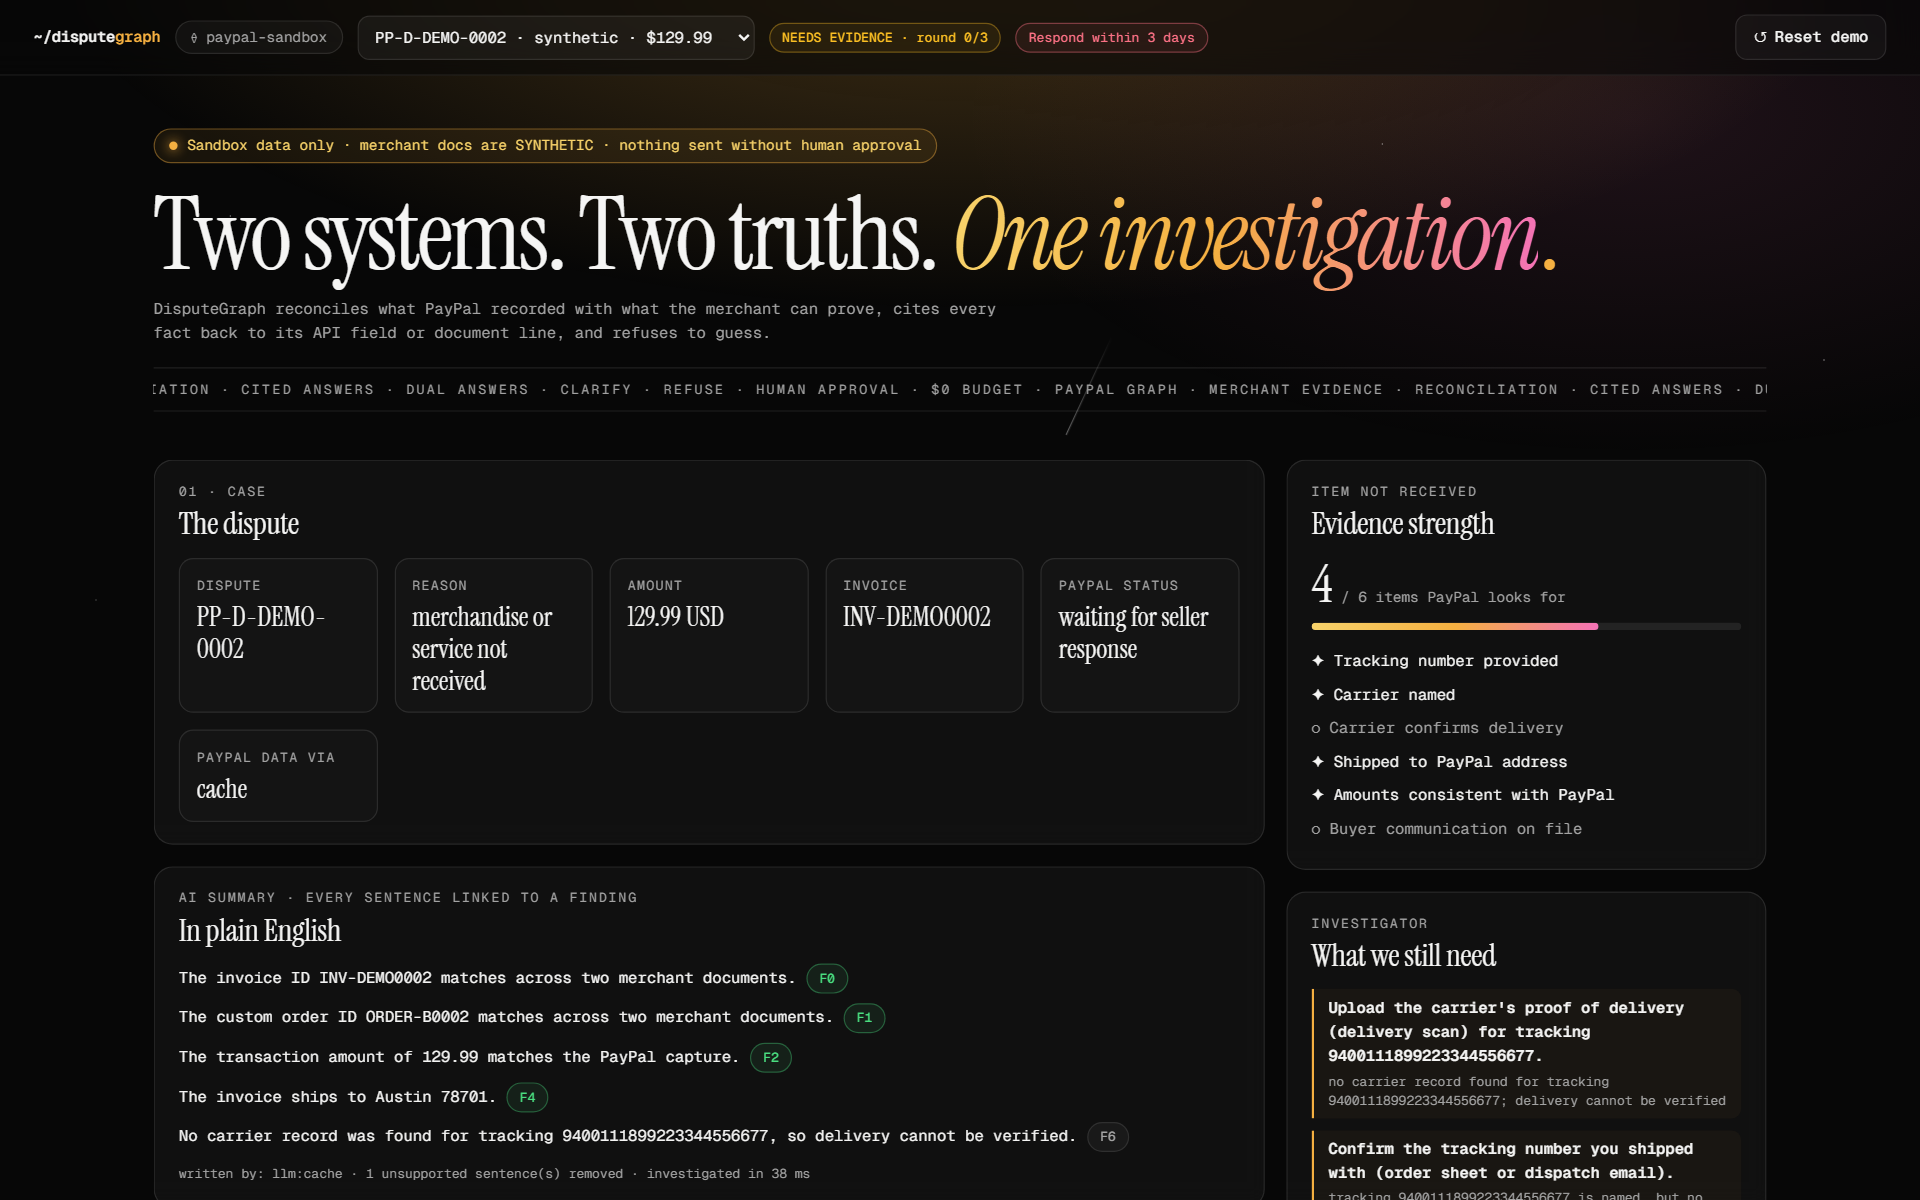
DisputeGraph puts two truths side by side: what PayPal recorded and what the merchant can prove.
- Pulls the dispute: the PayPal MCP server and REST APIs (Disputes, Payments, Orders) in the sandbox.
- Reads the merchant's evidence: text, PDFs, scanned receipts (OCR) and non-English documents. A translated line is kept only if every number in it matches the original.
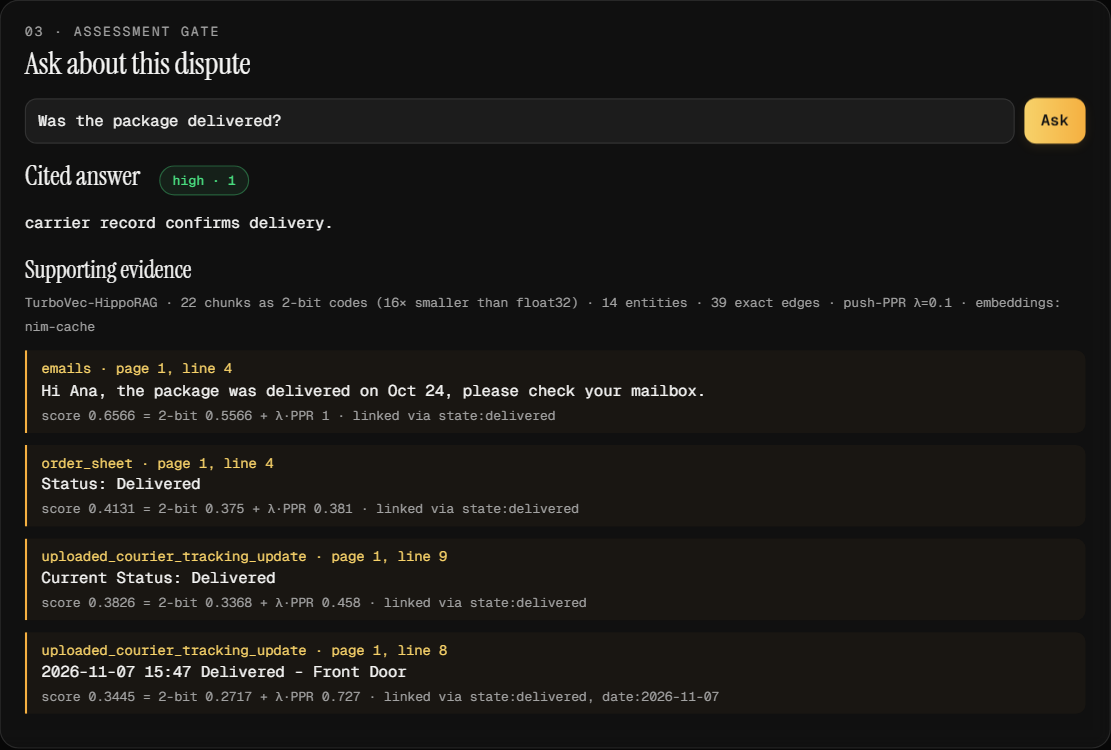
- Turns every line into a cited fact (file / page / line, or API path).
- Runs checks in code: amount, IDs, address, timeline, tracking, delivery and refund. Each check gets a verdict: MATCH, MISMATCH, CONTRADICTION, UNSUPPORTED CLAIM or MISSING.
- Checks PayPal's own tracking record with the Shipment Tracking API: is the merchant's tracking number actually on the transaction? Seller Protection depends on this.
- Flags forged or AI-made evidence:
- C2PA Content Credentials
- AI-tool and editor metadata
- PDF edit history
- photo noise analysis
- an optional pixel-based AI-image model
- Turns gaps into a to-do list, for example "No carrier record for tracking 1Z…, so delivery can't be verified."
- A human approves before anything is sent to PayPal.
How we built it
- Stack: Python, FastAPI and NetworkX (a graph linking the dispute, capture, order and documents), with NVIDIA NIM Nemotron as the LLM.
- Design rule: the AI never decides a verdict, amount, ID or date.
| AI job | What code still checks |
|---|---|
| Map an unseen label ("AWB no.") to a field | Code reads and compares the value |
| Read fuzzy claims ("money is on its way back") | A claim ranks below a carrier record |
| Propose a value no rule could read | The value is kept only if it appears word for word in the source line |
| Translate | The translation is dropped if any number changes |
| Write the summary | A sentence without a valid finding citation is removed |
- Hosting: Render.
- Demo video: made with HyperFrames.
Challenges we ran into
- Messy input.
- On cases written outside our code, the first try scored only 64%, then 70%.
- Almost every failure was a reading error (odd labels, OCR damage, amounts written in words), not a reasoning error.
- A fix that made things worse. An address rule we added caused 47 false alarms, so we removed it. We value a low false-alarm rate over a high catch rate.
- Rate limits. NVIDIA's free tier rate-limited us, so part of one benchmark row (the 98.7% "extraction fallback" figure) used a Claude Haiku stand-in. We say so everywhere, and the headline 96.2% uses Nemotron only.
- Fake evidence. No single test proves an image is AI-made, so we combine signals. A flag sends the case to a person; it never rejects a file automatically.
Accomplishments that we're proud of
| Test | Result |
|---|---|
| 3,000-case benchmark, Nemotron | 96.2% exact, 0.3% false alarms |
| Keyword baseline, same cases | 55.8% exact, 17.7% false alarms |
| 159 manually collected cases written outside our code, after fixing each failure type | 157 / 159 |
| Stress test (3,000 HTTP requests, including 328 attacks) | 0 server errors, 0 attacks got through |
| ChatGPT-made "parcel on the doorstep" photo, metadata stripped | Flagged at 99% AI |
- Seven PayPal integrations, working in the sandbox: the MCP server, Disputes, Payments, Orders, Shipment Tracking, provide-evidence and webhooks.
- We publish our failures, not just our wins.
What we learned
- Most AI errors here are reading errors. Checking each value against its source line fixes more than a bigger model would.
- Fix the failure type, never the single case, or you are only memorizing the test.
- Publishing your failures builds more trust than a perfect demo.
What's next for DisputeGraph
- A pilot on real merchant disputes, with consent. All testing so far used synthetic data and the PayPal sandbox.
- More dispute types beyond Item Not Received.
- Shopify and Gmail connectors, so evidence is gathered automatically.

