TattvaSwarm — a sovereign personal AI swarm Sovereign personal AI: local-first memory, tiered Nemotron routing, and a logical swarm engine.
Inspiration
Personal AI in 2026 means rent-a-brain: your notes, your memory, your thinking, all in someone else's cloud. We wanted the opposite starting point — an assistant whose default is local, whose outbound calls are an explicit, auditable allowlist, and whose brain is open models (NVIDIA Nemotron) served through Nebius Token Factory. Sovereignty should be an architectural property, not a privacy toggle.
What it does
- Tiered router (deterministic classification):
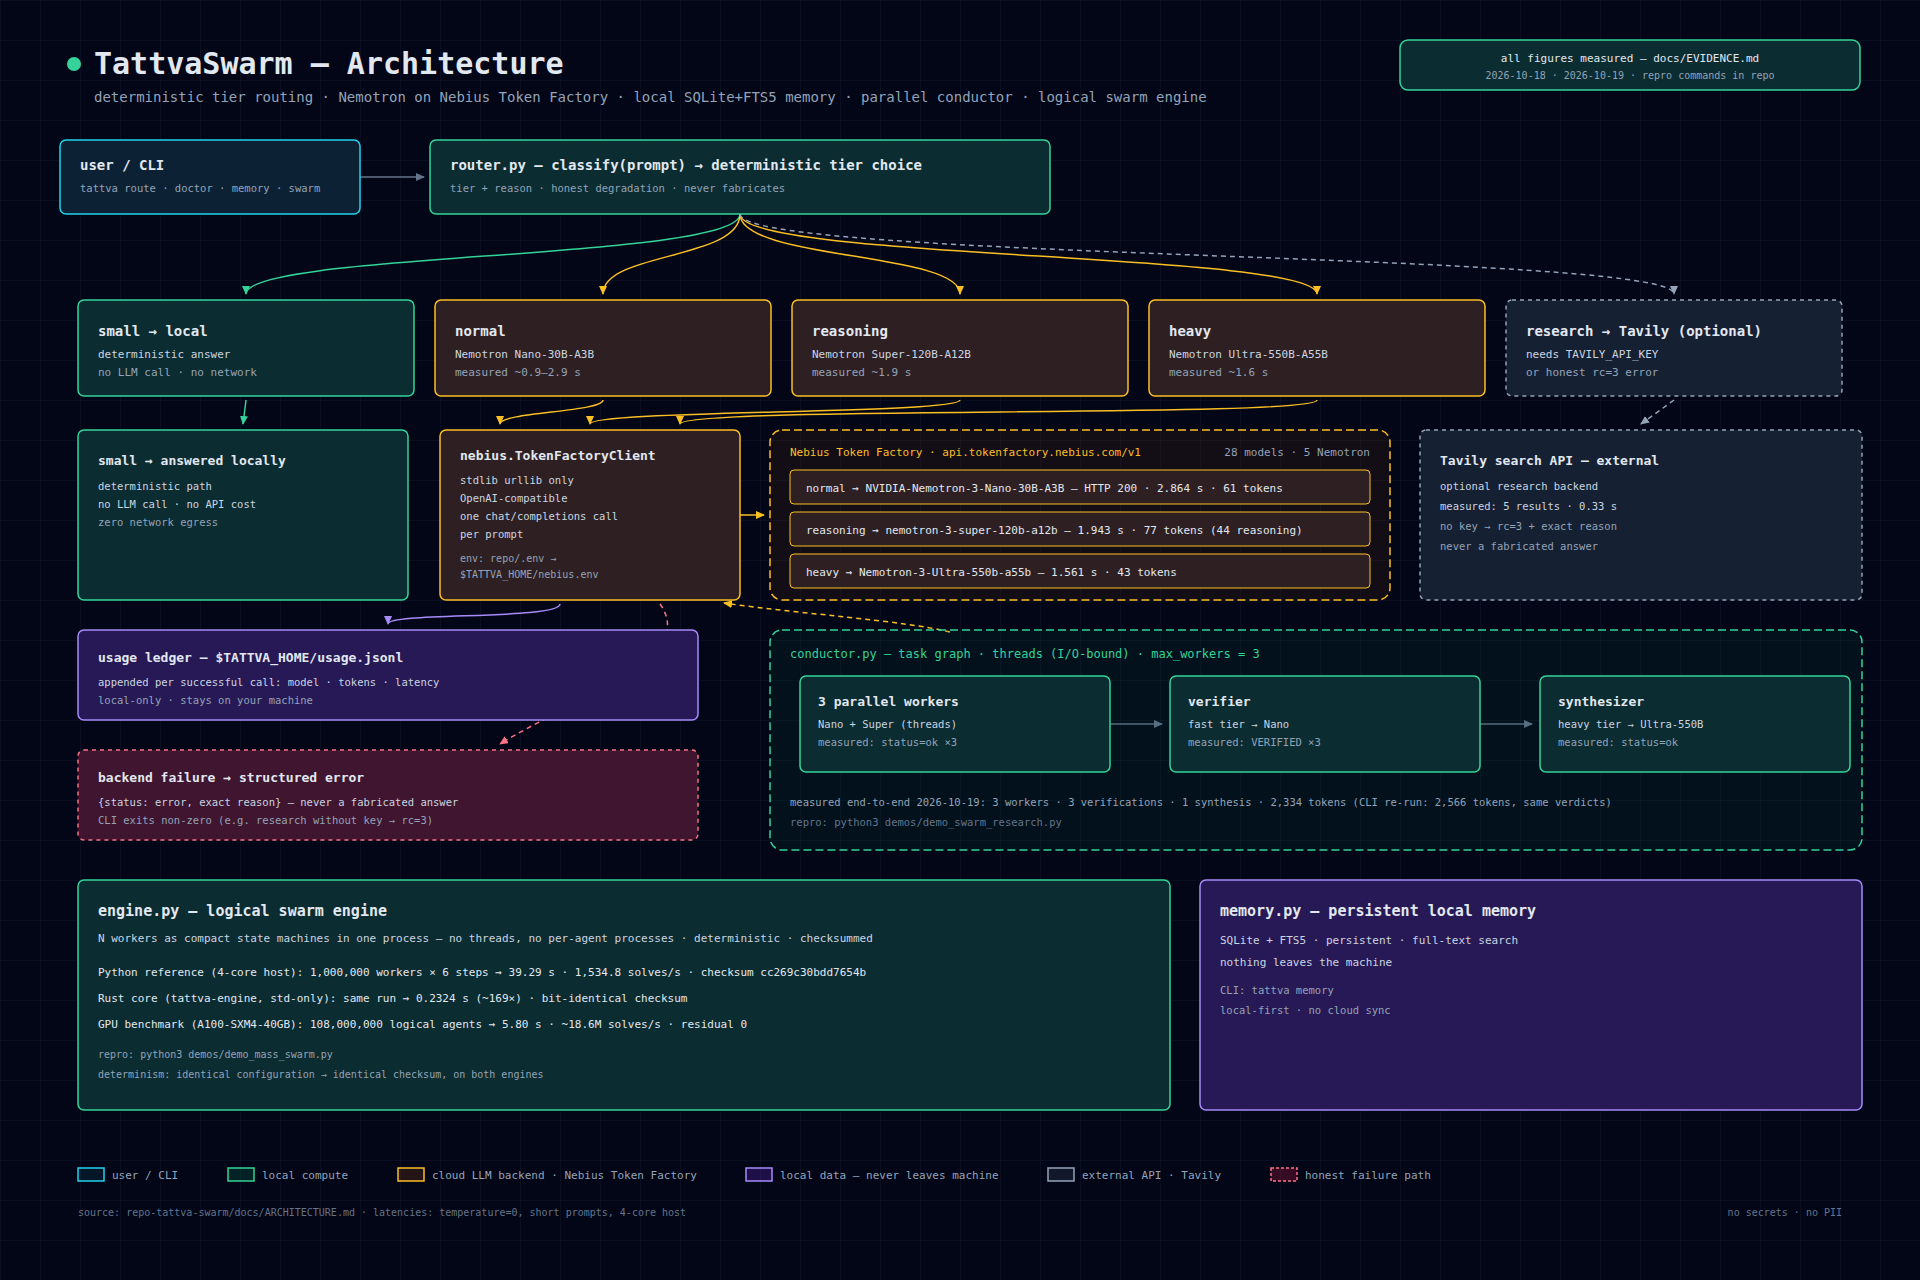
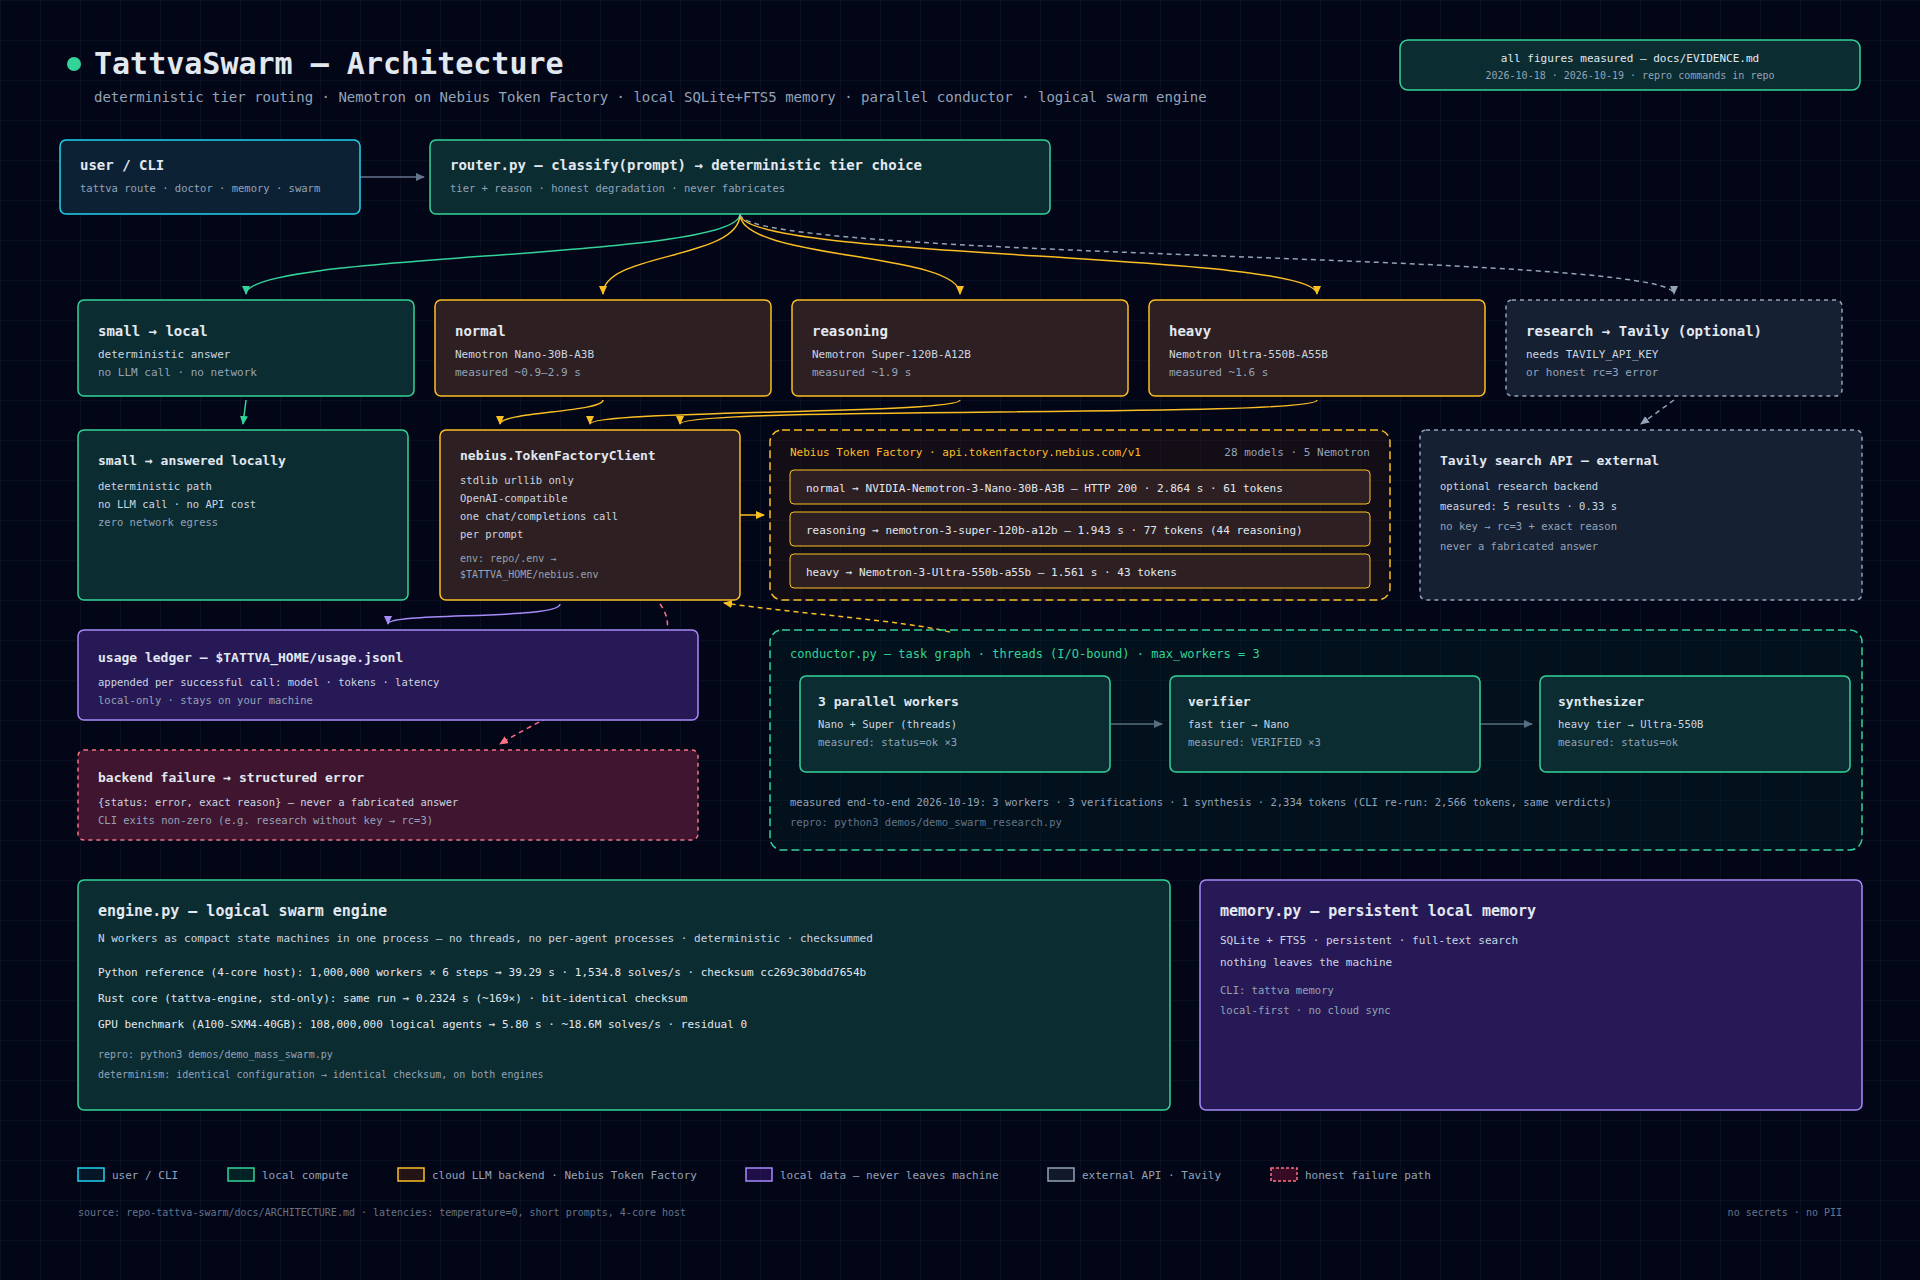
smallruns locally and never touches the network;normal,reasoningandheavyroute to Nemotron Nano / Super / Ultra on Token Factory;researchis a live Tavily search (verified 2026-10-19: 5 results in 0.33 s). No key → exact-reason errors, never fabricated answers. - Local memory: SQLite + FTS5 — persistent, searchable, and it physically has nowhere to sync to.
- Swarm conductor: a task graph executed as parallel workers → verifier pass → synthesis by the heavy model, with a per-run token total.
- Logical swarm engine: millions of logical workers as compact state machines (deterministic, checksummed). The reference implementation runs in pure Python in this repo; the scaled engine was measured at 108M workers in 5.8 s on an A100 (numbers + conditions in
docs/EVIDENCE.md). - Sovereignty by policy: an explicit allowlist of what may leave the machine, a local usage ledger for every outbound call, and a pre-push sanitization scanner.
How we built it
Python 3.12 standard library only — zero runtime dependencies (urllib for the OpenAI-compatible Token Factory API). The CLI (tattva doctor/route/memory/swarm) drives the same code path as the live demo. Everything is measured: model smoke tests (HTTP 200, latencies, token usage), the conductor run (~2.3–2.6k tokens end-to-end), and the swarm engine with verifiable checksums. The public repository was created during the submission window; docs/HACKATHON.md lists exactly what was updated.
Challenges we ran into
- Thinking models eat
max_tokensbefore emitting visible content — we learned to budget headroom (and documented it, because it will bite every Nemotron newcomer the same way). - FTS5 treats user input as query syntax (
-, quotes,NEAR); we neutralise it by quoting every token, so searching arbitrary text is always safe. - Honest degradation is harder than it looks: every failure path had to return the exact reason without ever inventing an answer.
Accomplishments we're proud of
- Verified live tier map on Token Factory: Nano / Super / Ultra, with smoke evidence checked into the repo.
- A conductor run where all workers verified and Ultra synthesised the final answer for under 3k tokens.
- Deterministic engine checksums, so anyone can verify the reference run.
- A sanitization gate we actually ran before publishing (report included).
- Bonus eligibility verified: the same router executed a live Tavily research call (5 results, 0.33 s) with the key kept out of the repository.
What we learned
Sovereignty is a routing problem before it is a cryptography problem. Once every outbound call is classified, allowlisted and ledgered, "local-first" stops being a slogan and becomes a property you can test. Also: open Nemotron models on Token Factory were fast enough (sub-2 s for reasoning-class calls) that the tiered design pays for itself immediately.
What's next
- Optional vision tier (Nemotron Super-VL) for screen understanding.
- Signed memory exports (content-addressed) for portable sovereignty.
- A CUDA build of the logical engine with the measured scale benchmarks.
Nebius feedback
- What worked: the OpenAI-compatible surface made integration a single-
urllibjob; catalog clarity was good (28 models listed, 5 Nemotron); latencies from a low-power host were excellent (Nano ~0.9–2.9 s, Super ~1.9 s, Ultra ~1.6 s on short prompts). - What would make it better: per-model
max_tokensguidance for thinking models in the model list metadata (or areasoning: trueflag); usage/billing visibility by key; a first-class "from-this-repo" deploy path.

Log in or sign up for Devpost to join the conversation.