-
-
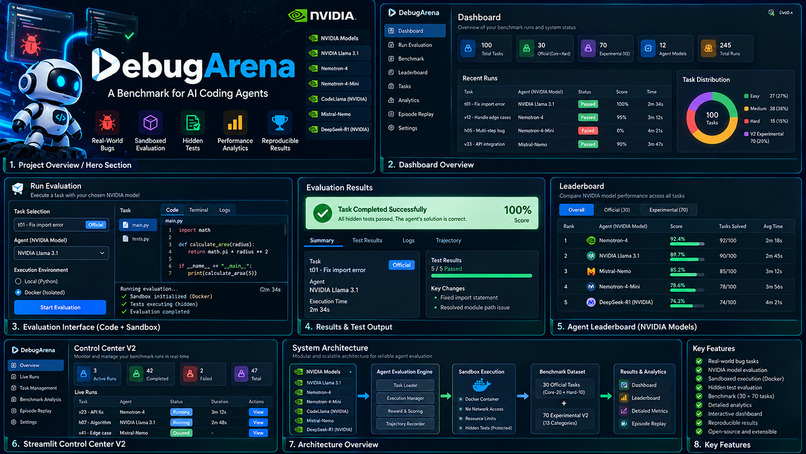
DebugArena project overview
Inspiration
AI coding agents are becoming increasingly capable, but how do we know whether they can reliably fix real software bugs rather than simply generate plausible code? Existing demonstrations often focus on successful examples without providing reproducible, controlled evaluation. We built DebugArena to make coding-agent performance measurable, testable, and transparent.
What it does
DebugArena is an evaluation platform for AI coding agents. Agents receive buggy Python tasks, inspect the code, attempt fixes, execute commands in a controlled environment, and have their solutions evaluated using hidden tests. The platform records trajectories, calculates rewards and performance metrics, and presents results through an interactive Streamlit dashboard.
The project maintains a 30-task canonical benchmark and a separate 70-task experimental V2 suite. This separation helps preserve the integrity of official evaluations while allowing new task categories to be explored.
How we built it
We built DebugArena with Python, a custom agent evaluation environment, configurable model providers, local and Docker-based sandboxes, hidden-test evaluation, reward calculation, and a Streamlit Control Center. The system includes episode tracking, run management, benchmark analysis, leaderboard views, and trajectory replay.
Docker execution applies isolation controls such as disabled networking, resource limits, dropped Linux capabilities, and protected hidden-test files. Automated tests and clean-clone reproducibility checks help validate the system.
Challenges we faced
A major challenge was building an evaluation pipeline that remains reproducible while supporting multiple agents, task types, and execution environments. We also addressed sandbox security, path traversal protection, concurrent run management, failure classification, and the separation of official results from experimental tasks.
What we learned
We learned that a useful AI benchmark requires more than a collection of coding problems. It needs reliable execution, hidden-test integrity, reproducible results, clear failure reporting, and transparent evaluation methodology.
What's next
Future work includes broader model comparisons, repeated evaluation protocols, expanded language support, and additional benchmark tasks. Our goal is to make DebugArena a practical foundation for evaluating the reliability and engineering capabilities of AI coding agents.


Log in or sign up for Devpost to join the conversation.