Inspiration
People pay for day-trading courses: rules, daily calls, live trading sessions. Course sellers show their wins, never a full record. When the FTC looked at one day-trading course (Warrior Trading, 2022), it found "the vast majority of customer accounts actually lost money." Studies agree: 97% of people who day traded for 300+ days in Brazil lost money (Chague, De-Losso & Giovannetti), and US retail options traders lost an estimated $2.1B in 20 months (Bryzgalova, Pavlova & Sikorskaya, Journal of Finance, 2023). Luis paid for three courses (Learn Plan Profit, ZipTrader, Crypto Wizard) and never knew if following them would have made money.
What it does
Day Trader AI answers one question per course: if you had copied every trade it posted, verbatim, would it have beaten just holding the market?
- It copies every posted trade with $10,000 of fake money, after trading costs.
- It compares the result with just holding the S&P 500 (stocks) or Bitcoin (crypto).
- It gives one word: Yes, Barely, No, or Not enough trades.
- A slider sets how late you got in after each post (1 to 60 minutes), because people reading Discord are not bots.
- Each kind of trade (day, swing, options, crypto) is its own portfolio, so you learn which part worked.
- Every verdict opens its proof: the course rules it used, the failures PRISM found, and the evaluator's score.
Results today (5-minute delay):
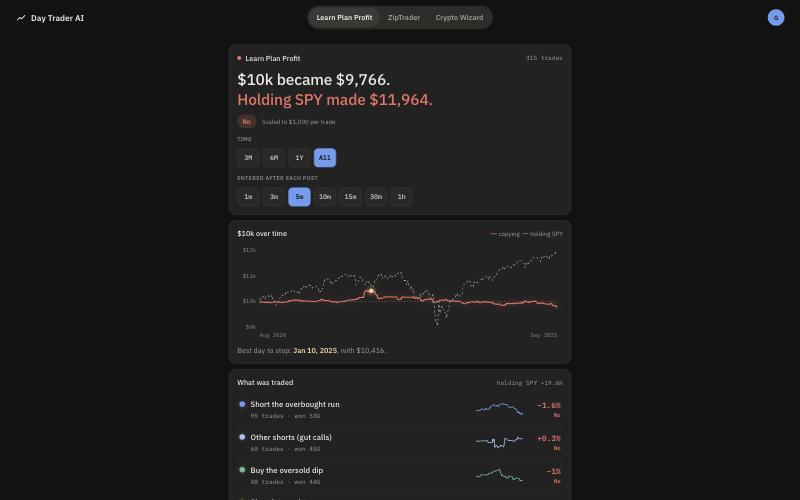
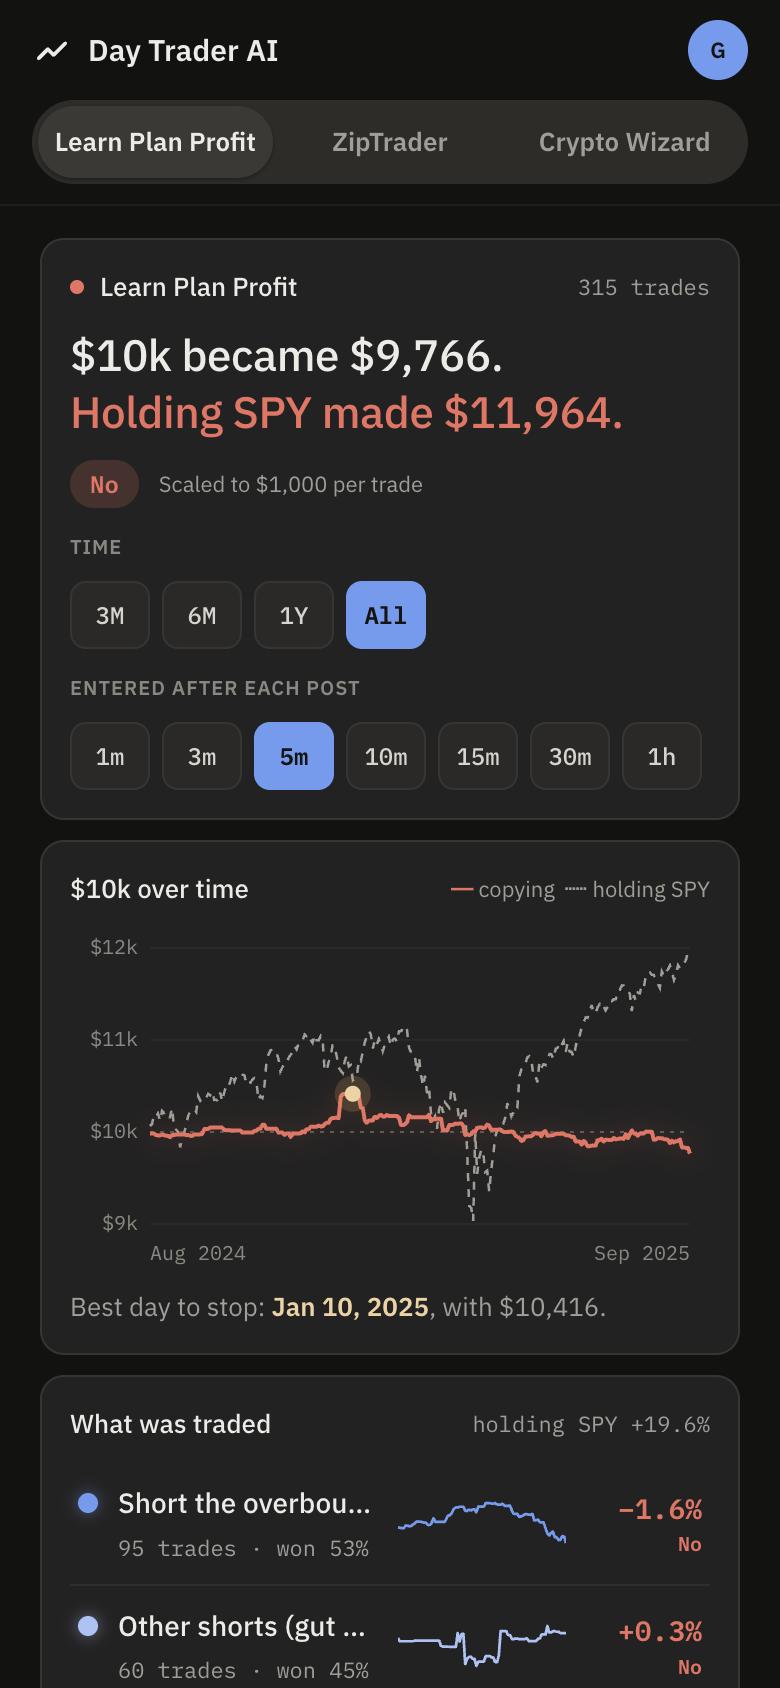
- Learn Plan Profit: No. 315 trades from a year of live sessions. $10,000 became $9,766; just holding the S&P 500 made $11,964.
- Crypto Wizard: Yes, with a catch: $10,000 became $9,221 while just holding Bitcoin made $7,543. It lost money, just less. In the newest three months, reported on their own, it was behind (-0.8% vs Bitcoin +26.0%).
- ZipTrader: Not enough trades. 12 briefings, mostly watch-lists; one trade could be copied. It says so instead of guessing.
How we built it
- Collect (read-only): a year of Learn Plan Profit live-session videos (246 with captions), Crypto Wizard's 126 Discord calls, ZipTrader's 12 morning briefings. Raw content stays on Luis's laptop, never in git or the app.
- Extract: one streamed model call per whole session or post, through the Nicrron API (
anthropic/claude-sonnet-5-5), writes down each trade: ticker, side, price, stop, target, time, and a quote of 12 words or fewer. - Check: code tests every event. The quote must be in the source, every number must be in the quote, the ticker must be real, the price must fit the market that minute. Any failure is marked
needs_review, never kept silently. - Backtest: code, not the model, prices every trade on 1-minute bars (Alpaca for Learn Plan Profit, Yahoo for ZipTrader's recent days, Binance for crypto) at post time + your delay, with costs (5 bps per side, 20 under $10, 25 for crypto).
- Prove: every extraction and verdict run is traced to PRISM, with one stable agent id per version (
extract-lpp-v1,extract-lpp-v2,daytrader-verdict-v1, ...). - Show: a static web app (Vite, Clerk Google sign-in, TradingView Lightweight Charts) that reads only the committed result files. No backend, no per-user data.
The PRISM proofs (failure → fix → score)
- The failure (Root Cause):
extract-lpp-v1failed at least one code check in 28 of 30 proof-set runs (final_status="error", naming the check). PRISM's Root Cause put 25 of them in one cluster, "failures in LPP session extractor v1"; the failed-tool-call detector fired in 25 of 25 runs and the unsupported-answer detector in 20 of 25. Our sentence: the v1 prompt let the model quote long caption stretches and lose track of open positions, so most v1 runs failed a code check. - The fix: v2 makes each quote carry the numbers it backs, code trims the quote to the 12 words that hold them, and the position ledger carries trades across sessions. Failed runs fell from 28 to 18 of the same 30 sessions. Part of that gain is code, not only the prompt.
- The score (Evaluator): our evaluator "Numbers grounded" (every price, level and quantity appears in the quote it cites) scored v1 and v2 on the same sessions. Our code, reading each run in full: 52% → 66% of runs pass. PRISM's LLM judge with the same rubric: 50% → 47%, but it saw a cut-off run output in 24 of 30 runs for each version, so its score can't separate them; we report both. The money barely moved ($10,291 vs $10,303 on the same 30 sessions): the fix made the evidence cleaner, not the answer rosier.
- Knowledge Base: paraphrased strategy cards per course are uploaded to PRISM's Knowledge Base and assigned to
daytrader-verdict-v1and-v2; each verdict run starts with akb_searchstep and cites the card it used. In our Learn Plan Profit run it found the course's own rule that you don't have to take every trade, so the verdict says copying every post isn't how the course tells you to trade.
Challenges we ran into
- Long model calls timed out until we streamed them (hidden thinking ate the first 20-60 seconds).
- The course hosts trade $40k+ positions; we scaled each trade to $1,000 so $10,000 can copy them, and say so.
- Three courses, three formats: videos, Discord calls, briefing images. One event shape covers all three.
Accomplishments that we're proud of
- A real answer for three paid courses, with every number read from result files the code wrote, not the model.
- The full PRISM loop: a Root Cause cluster of failed runs, a fix, and an evaluator score on the same 30 sessions (28 → 18 failed runs).
- "Not enough trades" is an answer: ZipTrader gets exactly that instead of a guess.
What we learned
- The code decides, not the model. The model only extracts events and writes plain text; code prices every trade on real bars.
- Show the caveats. Exits we had to assume, trades we couldn't copy, options counted but not priced, and an LLM judge that saw cut-off outputs: we report them rather than hide them.
- Newest months on their own. A result that only held in the past shows it (Crypto Wizard does).
What's next for Day Trader AI
The improving agent (daytrader-improver-v1) already runs: it proposed "skip short-breakdown entries from 10:00 ET" for Learn Plan Profit. That helped on older months (-1.3% → +0.5%) but not on the newest ones (-0.1% both), so code didn't keep it. Next: let it try more changes, still kept only if months it never saw agree.
Fake money, not financial advice.
Built With
- alpaca
- binance
- blockconvey
- nicrron
- prism
- python
- surrealdb
- vercel
- vite

Log in or sign up for Devpost to join the conversation.