Inspiration
I set out to build something small: an agent that reads corporate filings so I don't have to. A few days in I hit the problem that became the project. I could not tell when the agent was wrong.
A weak model rarely writes a wrong number. It drops a filing entirely. The answer that comes back is fluent, well-formatted, correctly sourced — and missing the buyback that mattered. Reading the answer tells you nothing. You would have to go read the filings yourself, which is the whole thing you were trying to avoid.
That gap matters here more than in most places. Korea's DART and the U.S. SEC publish every corporate disclosure within minutes, free and machine-readable, and almost nobody reads them. The information is already public. What is missing is somebody to read it every fifteen minutes, forever. An agent can do that. An agent you cannot check should not be left alone to do it.
So the agent had to grade itself against something that isn't a model.
What it does
dart-agent watches DART and SEC filings and turns them into structured Event objects
— what happened, who did it, how much, when, and a link to the original document.
It is running right now on Cloud Run, watching three companies: SK hynix and Samsung Electronics through DART, Micron through SEC EDGAR. Forty-five filings read so far, every stored verdict clean — and that count is higher by the time you read this, because nothing stops it. Nobody asked for any of it. This is the service's own log, pulled from Cloud Logging:
[dart:00164779] 12 new filings, taking 5
[fallback] gemini-3.7-flash key 1 rate-limited -> next model
[answered] gemini-3.6-flash / key 1
[dart:00164779] audited against the source: clean
[dart:00126380] 7 new filings, taking 5
[fallback] gemini-3.7-flash key 1 rate-limited -> next model
[answered] gemini-3.6-flash / key 1
[dart:00126380] audited against the source: clean
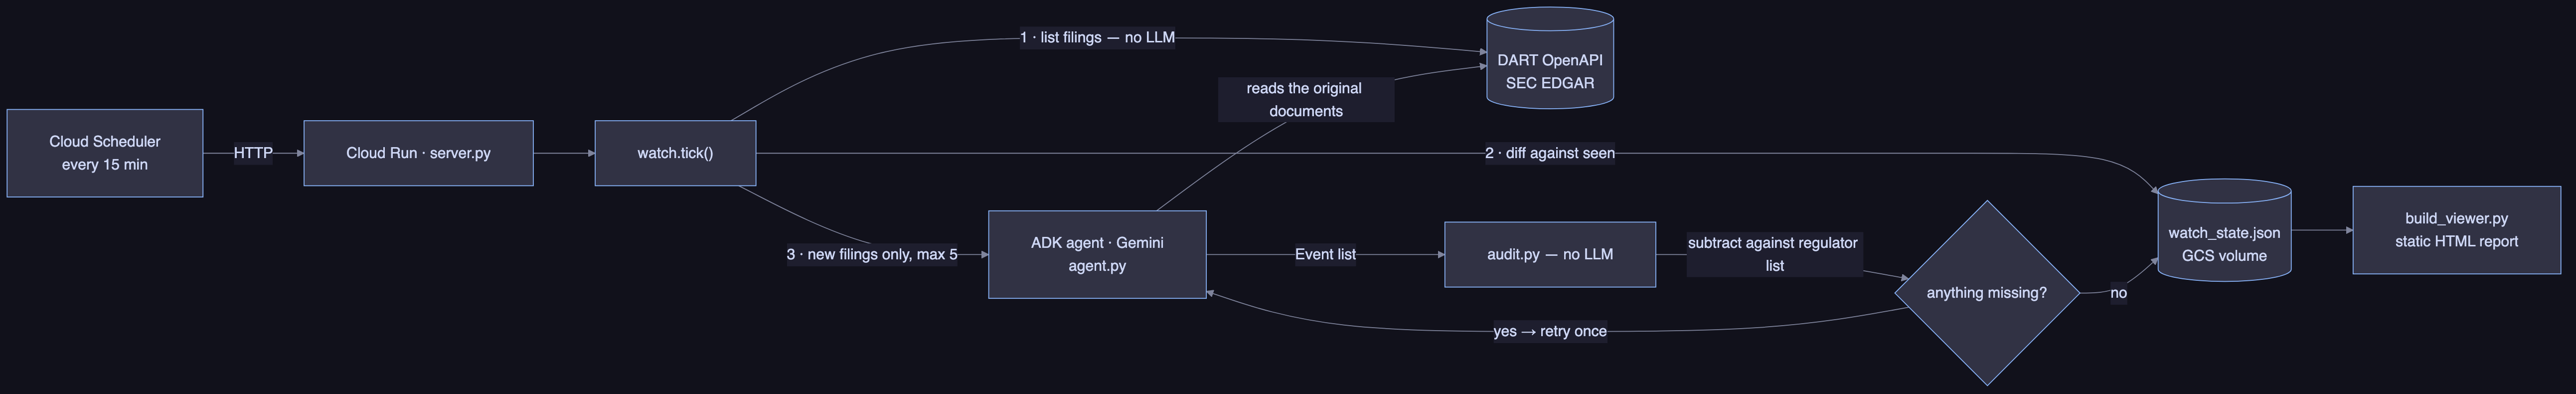
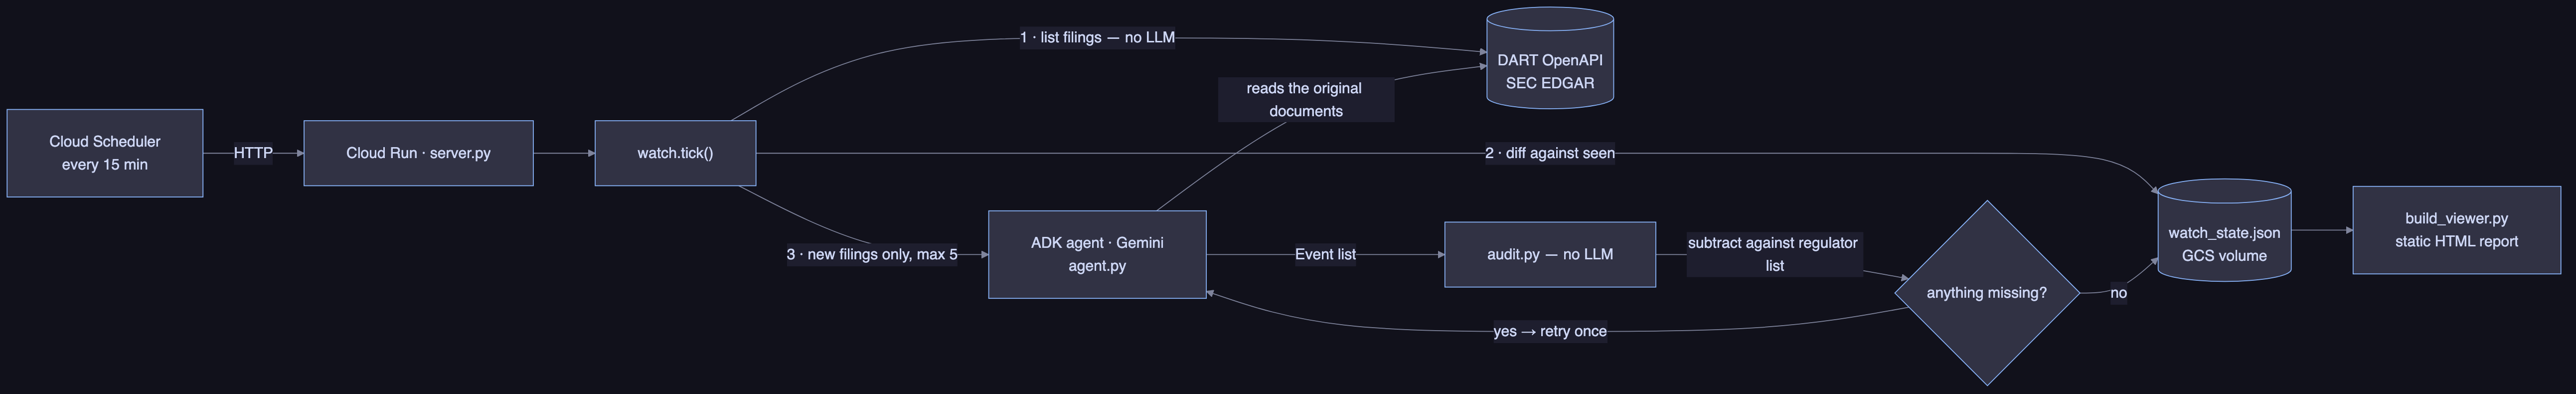
Nobody prompts it. Cloud Scheduler pokes it every 15 minutes; it lists filings with no LLM at all, diffs against what it has already seen, and calls Gemini only when there is something new. On a quiet day it costs nothing.
The part I actually care about is audit.py, and it contains no LLM:
- It pulls the official filing list straight from the regulator's own API.
- It subtracts that against the filings the agent cited.
- Two failure modes fall out of that subtraction for free — filings the agent dropped, and accession numbers the agent invented that don't exist in the list.
If anything is missing, the agent gets sent back once. Pass or fail, the verdict is stored next to the answer, so a bad answer cannot be quietly presented as a good one. And because the check is pure arithmetic against a public list, it never hits a rate limit and never lies about itself.
That same audit acts as a gate on writes: a newer answer that scores worse than the stored one does not overwrite it. This is not theoretical — a higher-tier model in my ladder once dropped two capital-expenditure filings and cited a 2024 accession number, while the cheaper model one rung below got it exactly right. Without the audit I would have shipped the worse answer and never known.
Every extracted field links back to its source document, so any single claim is one click from being checked.
How I built it
Google ADK + Gemini. The agent has four tools — list and read, for each of DART and
SEC. Both regulators are normalized onto one Disclosure schema, so the SEC connector
drops into the Korean pipeline without a second code path: CIK goes where corp_code goes,
the accession number where rcept_no goes.
Cloud Run + Cloud Scheduler. server.py is one endpoint on plain http.server — one
route does not need a web framework. Buildpacks deploy it, so there is no Dockerfile.
Cloud Run's disk dies with the instance, so state lives in a mounted GCS bucket.
Two safeguards that are load-bearing and easy to get backwards:
- Max 5 filings per tick. Reading one original costs roughly one request, so a 15-filing
batch blows through the free tier's 5-requests-per-minute limit mid-run — and a mid-run
failure restarts the whole conversation, wasting everything already spent. The backlog
drains over the following ticks instead. That is the
taking 5in the log above. - Write the result first, mark the filing as seen second. Reversed, a crash between the two writes silently loses a filing — the exact failure this project exists to catch.
Both are pinned by watch.py --selfcheck, which runs the logic with no network and no
model, so the invariants are enforced in CI rather than in my memory.
A model ladder instead of a retry-with-backoff. Gemini's free tier caps at 20 requests per day per model, so when one model 429s, waiting is the wrong move — the next model down has its own untouched quota. Four rungs, plus key rotation across projects. Falling down a rung costs thoroughness, which is exactly what the audit is there to measure.
Challenges, and what's next
The hard part was not the agent. It was learning that "the answer looks right" is not evidence, and that any check made of the same material as the thing being checked will agree with it. The audit only works because it is dumb, deterministic, and sourced from the regulator rather than from the model.
The second lesson was that a better model is not reliably a better answer. I had assumed the ladder was strictly ordered by quality. The audit proved it isn't, which is why score beats rank and rank only breaks ties.
Next: more regulators — adding one is a single line in audit.py's SOURCES, which
was the design goal. Then event-type coverage beyond the current set, and a diff view that
shows how a company's disclosures changed across quarters rather than treating each filing
as an isolated fact.
