Inspiration
Machine learning research is mostly not the modelling. It is the loop around it: form a hypothesis, run it, read the metric, decide what the number means, and choose the next move. That loop is where the days go, and almost none of it is the part that requires taste.
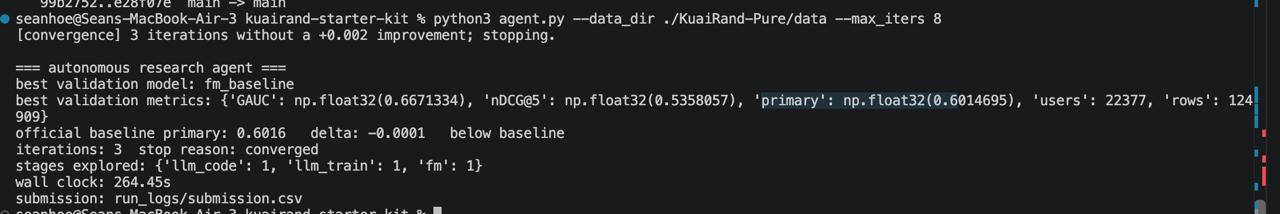
We wanted to know whether an agent could hold that loop on its own — not autocomplete a model class, but actually run the research: propose an experiment, train it, read its own validation feedback, and decide what to try next. The KuaiRand-Pure benchmark is a good place to ask, because it is honest about difficulty. The official FM baseline sits at 0.6016 validation primary, the theoretical ceiling is 0.8484, and 27.1% of users are all-negative and score zero nDCG no matter what you build. There is nowhere to hide.
What it does
Da AI AI tuner runs an autonomous research loop against KuaiRand-Pure:
- Reproduces the official baseline as a gate. Every run starts by training the official FM and refusing to continue unless it lands within tolerance of the published score. If the pipeline is wrong, the run stops before it can generate confident nonsense on top of a broken foundation.
- Chooses a pipeline stage to attack. Each iteration the planner picks one of four moves based on its own history: rewrite the model architecture, write a new feature transform, change the training recipe (loss function, class weighting, LR schedule, capacity), or retune a registered experiment.
- Validates before it spends. Generated code is compiled in a restricted sandbox and put through a dry-run forward pass before any real training starts. Rejected candidates are retried immediately with the compile error fed back into the prompt, rather than burning a full iteration.
- Trains, evaluates, and records. Every iteration writes its hypothesis,
generated code, parameters, validation GAUC / nDCG@5, and any error to
iterations.jsonl. Every provider call, including its raw response, goes tollm_calls.jsonl. - Stops when it should. The convergence rule (ε = 0.002, N = 3) normally fires first, with a 50-iteration cap and a 6-hour wall-clock backstop behind it. The stop reason is recorded, not inferred.
- Submits only what validation chose. The final submission is generated from the winning configuration's actual parameters, and the hidden test set is touched exactly once.
Development uses the training split and public validation feedback only. The agent never reads hidden test labels.
How we built it
The architecture separates research decisions from benchmark correctness, and that line is the whole design.
Fixed and never agent-writable: data loading, the causal feature construction
(which advances user state only for training rows, so validation is read-only
against final training state), the train/eval loop, and the GAUC / nDCG@5
definitions from the organizers' evaluate.py.
Agent-writable, inside a sandbox: the model architecture, the feature
transform, and the training recipe. Generated source is executed with
restricted builtins and a denylist covering file, network, process and
environment access. A guarded importer lets libraries resolve their own lazily
imported submodules while refusing os, subprocess, socket and
importlib outright.
Feature-stage and training-stage proposals are scored against a fixed reference architecture. If the model changed at the same time as the features, the resulting delta would be unattributable and the iteration would produce no usable evidence.
The feature sandbox additionally proves that a transform is row-wise, using two independent invariants — subset consistency and permutation equivariance. This is not a style check. A transform that normalises by a batch mean would inflate validation and collapse on the hidden test set, and no metric would warn us.
Stack: Python, PyTorch, NumPy, an OpenAI-compatible Chat Completions API for the planner (provider and model configurable), CPU-only, no GPU required.
Challenges we ran into
A silent fallback that manufactured a fake success. For several runs the
agent printed best validation model: fm_baseline and exited cleanly. Nothing
looked broken. In fact the LLM planner was failing on every call, returning
None, and the controller was quietly falling through to its hardcoded
schedule. A run that did zero autonomous research was indistinguishable from a
successful one. This was by far the most expensive bug we hit, and it was
expensive precisely because it never announced itself.
Debugging blind. The first real error was Expecting ',' delimiter: line 44
column 6 — an unhelpful JSON parse failure. The raw provider response was
being discarded, so we were guessing. Once we logged finish_reason and the
raw text, the cause was obvious in one line: finish_reason: "length". The
response was truncated at a 300-token cap mid-string. We had spent an entire
debugging cycle on a hypothesis about the planner's mode-selection logic that
was never the problem.
Correct code, rejected. With truncation fixed, the model produced genuinely
valid architectures — right constructor, right forward signature, right output
shape — that were rejected three times running because they opened with
import torch. The sandbox forbids the token. The contract said not to. The
model wrote it anyway, out of habit, even after seeing the error in its
history. Fighting the habit was less effective than deterministically stripping
the pre-injected imports.
A leakage guard that did not guard. Our first row-independence check tested permutation equivariance, and mean-centering passed it — the batch mean does not change when you shuffle the batch. The check was well-intentioned and completely ineffective against the exact class of leak it existed to catch. A unit test caught it, not a run. It now takes a subset check as well.
A crash that was good news. After all of the above, a run died with
TypeError: Object of type float32 is not JSON serializable. It was a latent
bug in the history summariser, unreachable until an iteration produced real
metrics — which meant a generated candidate had finally trained end to end.
Accomplishments that we're proud of
- The agent iterates across the full stack, not just the model. Feature engineering and training recipe are first-class moves, scored in isolation so their effects are attributable.
- The leakage guard. Proving a feature transform is row-wise before it can touch training data is the single most valuable safety property in the system, because it defends against a failure that would otherwise look like success right up until the hidden test score came back.
- Failures are legible. Every planner failure writes a
planner_failedrow with the raw response. Deterministic errors are blocklisted after one attempt instead of reproducing the same traceback three times. The run reports why it stopped rather than leaving us to infer it. - Honest reporting by construction.
run_metadata.jsonrecords the delta against the official baseline and abeat_official_baselineboolean. The submission cannot quietly become "whatever looked best". - 46 tests, most of which exist because they caught a real bug in this system — including two that found defects in code we had already written and believed was correct.
What we learned
A silent fallback is worse than a crash. Our agent's most dangerous behaviour was not failing; it was failing and then printing a plausible result. Every recovery path now leaves a record, and the smoke-test mode refuses to fall back at all.
Log the raw artifact, not your interpretation of it. One line of
finish_reason would have saved an entire misdiagnosis. We were storing a
parsed error message and discarding the evidence that explained it.
Validate at proposal time, not at execution time. Moving compile and dry-run checks into the planner turned a wasted iteration into a same-turn retry with the error fed back.
Invariants need adversarial tests. Permutation invariance felt like it meant row independence. It does not, and only writing the leaky transform we were afraid of revealed the gap.
The scaffolding is not the bottleneck. With the loop finally working, our candidates land at 0.6043 against a 0.6016 baseline. Getting the agent to run correctly and getting it to win are different problems, and we should not confuse solving the first for progress on the second.
What's next for Da AI AI tuner
- A stronger planner. Cost is not the constraint here — a full 50-iteration run costs well under a dollar in planner tokens, next to hours of training. The quality of the proposals is the constraint.
- Autonomous ensembling. Let the agent blend any two scored candidates from its own run history with weights it chooses. On this benchmark, blends are historically where the wins are.
- Temporal robustness. Our completed experiments suggest distribution shift between validation and test: candidates that win on validation have not held their margin. The agent should optimise for temporal robustness rather than validation score alone.
- Information-gain scheduling. Allocate iterations by expected information gain instead of running them sequentially — cheap, informative experiments first.
- Cross-benchmark transfer. Run the same loop on KuaiRand-1k and 27k and see whether research strategies learned on one transfer to another.
Built With
- openrouter
- python


Log in or sign up for Devpost to join the conversation.