-
-
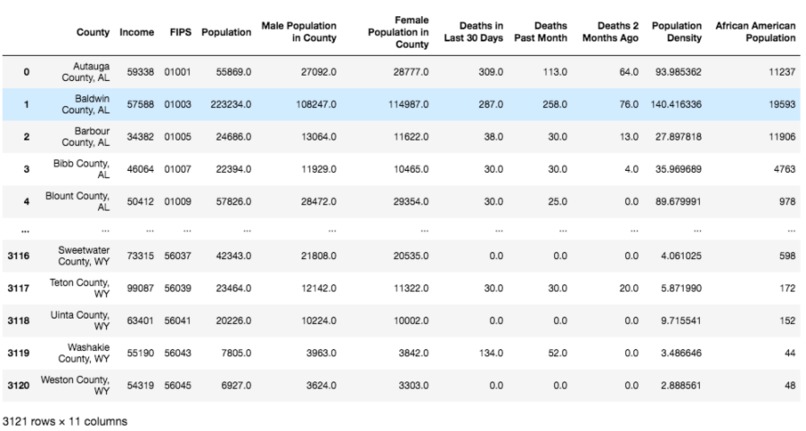
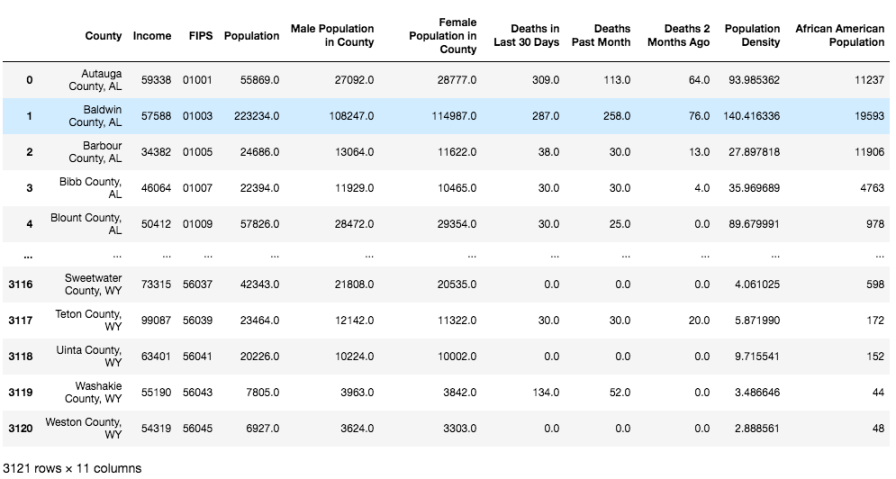
Dataset for counties in the United States
-
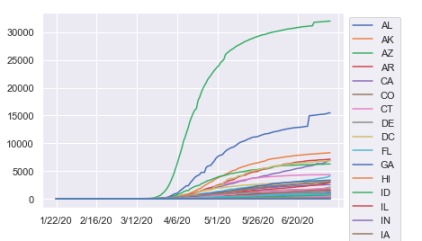
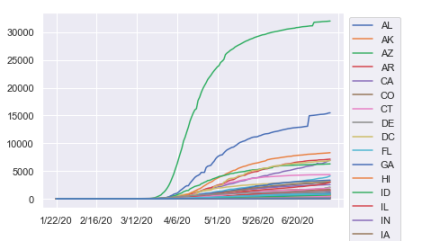
Total cases past 6 months
-
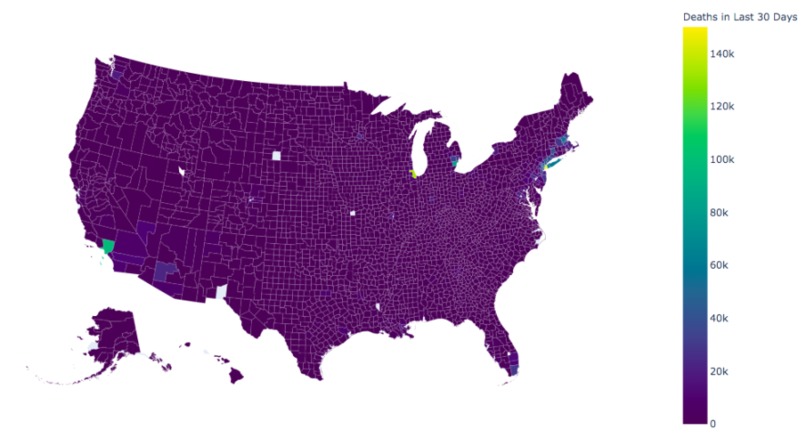
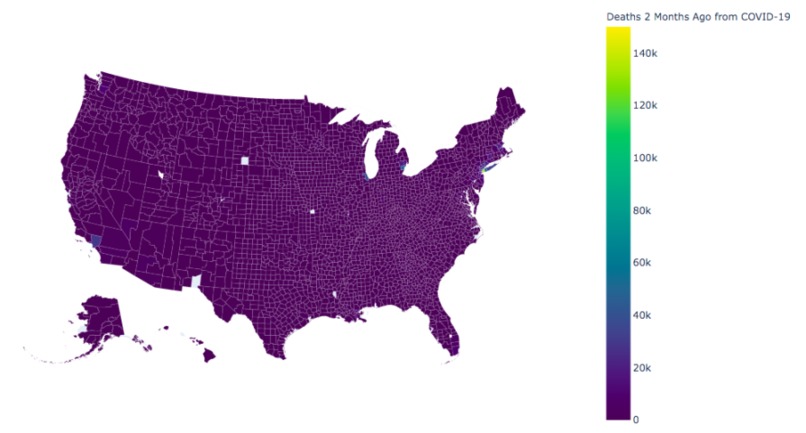
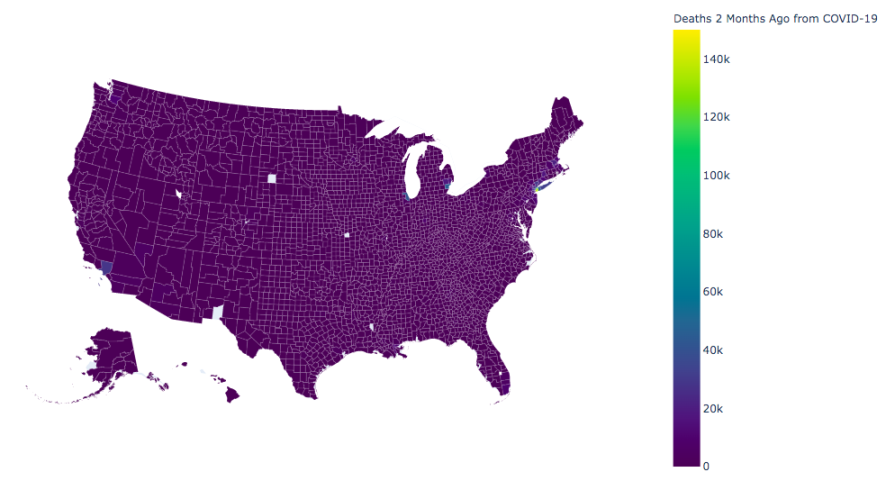
Deaths 2 months ago
-
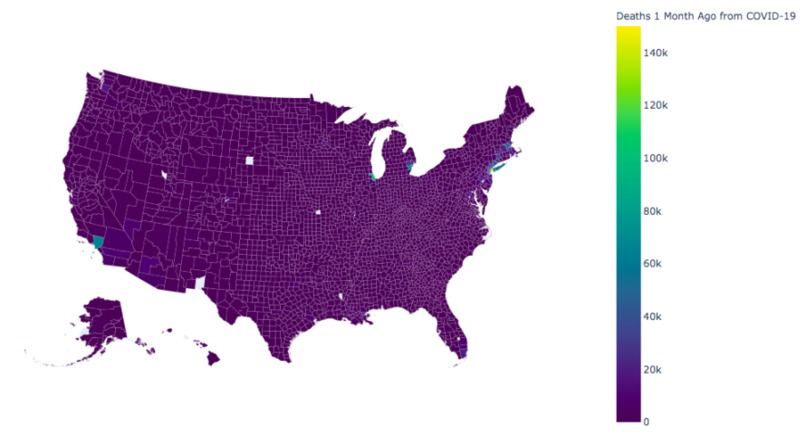
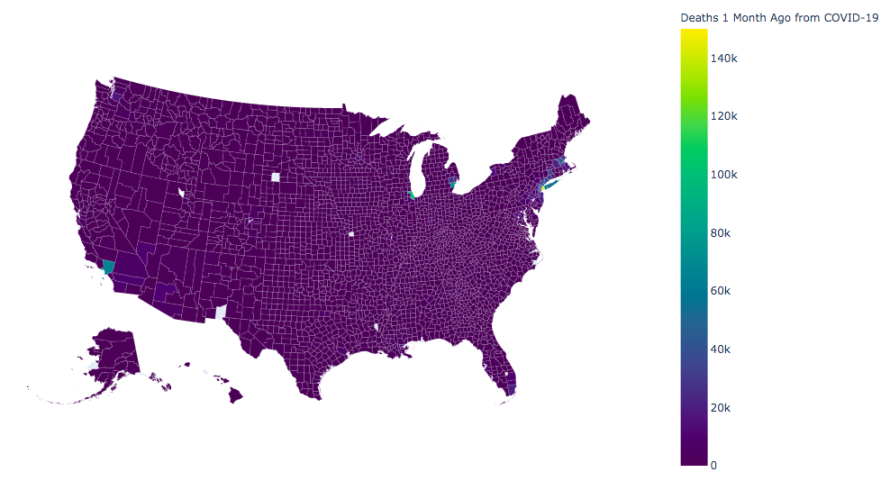
Death 1 month ago
-
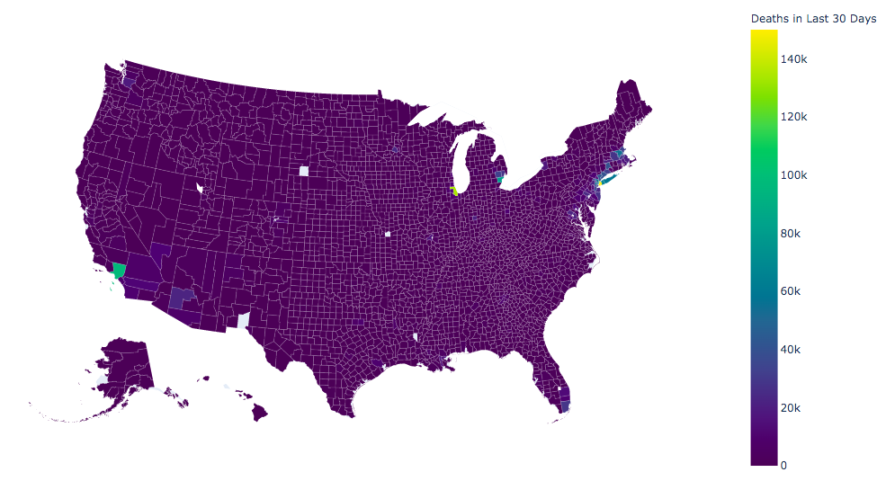
Deaths this past month
Inspiration
It’s a known fact that certain groups are being impacted excessively by the pandemic.While many know this, there was no easy way for people to find out which groups need help the most and when they may need help in the future. So, we sought out to compile important stats about nationwide counties relating to COVID-19, with which a predictive model could be build to help those in need now and in the future.
What it does
By examining our data and looking at different traits such as gender,age,socioeconomic background, and population density, our group is able to determine which counties are going to/are already affected by the virus. Our group finds that counties with less general income, a higher population density, and high African-American populations are being hit the hardest by COVID-19. While we did not have time to make a functioning model, with our data, the model we were planning to create would shed light on communities that are being disproportionately affected and would thus need more funding: something that no one is doing right now.
How I built it
We compiled data from over 10 public datasets and engineered it to run smoothly.
Challenges I ran into
Concatenation was difficult as well as finding important features to analyze. Time was also a huge challenge as we could not start the model, which we planning to build using TensorFlow, Keras, and Scikitlearn, because finding the data was very time-consuming.
Accomplishments that I'm proud of
Successfully creating a dataset that includes a plethora of information relevant to Covid-19.
What I learned
A lot of information about different counties and demographics as well as how to better navigate through and engineer datasets.
What's next for CovAid
Use the dataset to create a deep-learning model (neural network) to analyze the situation of a given county based on the features in our dataset.


Log in or sign up for Devpost to join the conversation.