Inspiration
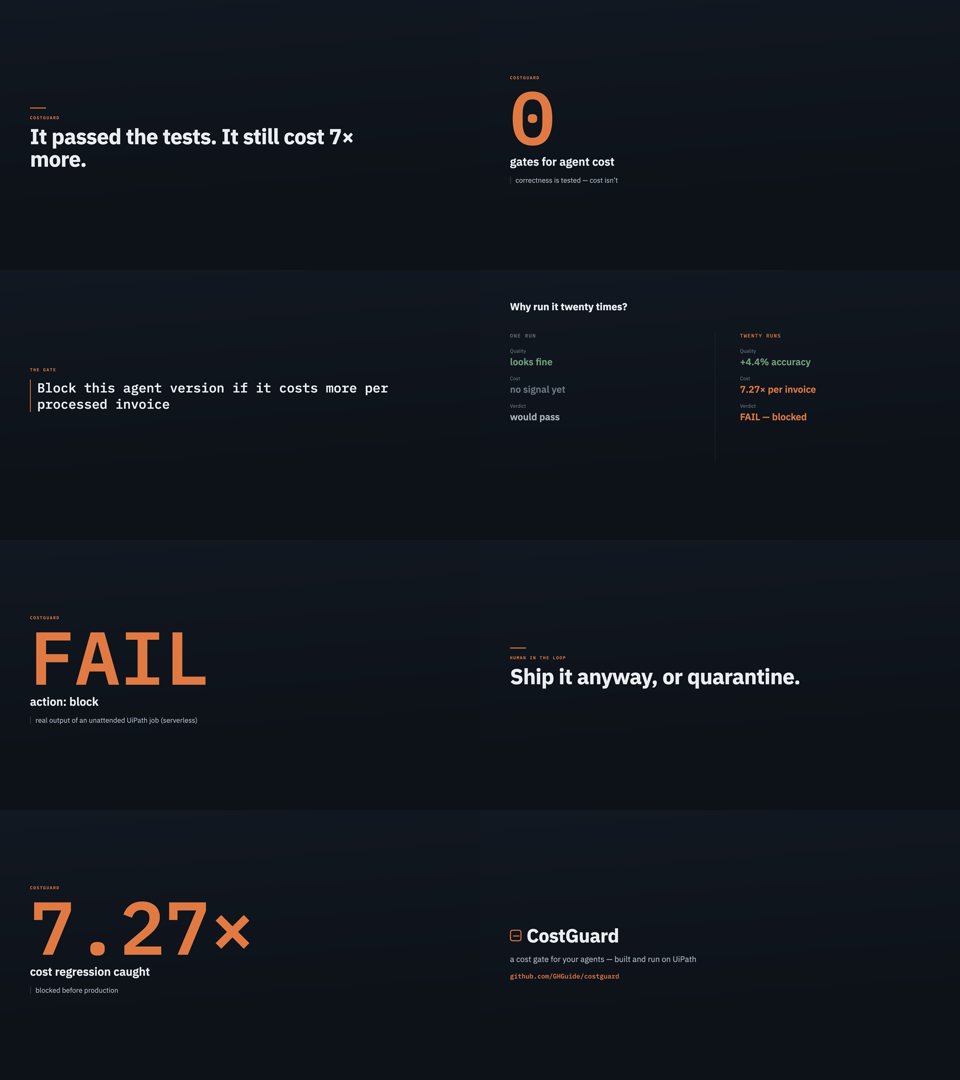
Teams ship AI agents fast. A "harmless" prompt or model tweak can quietly triple token spend while passing every correctness test. FinOps X 2026 called it the Great Token Panic; one 4-agent loop burned ~$47K in 11 days. There's a correctness gate before production. There's no cost gate. So I built one.
What it does
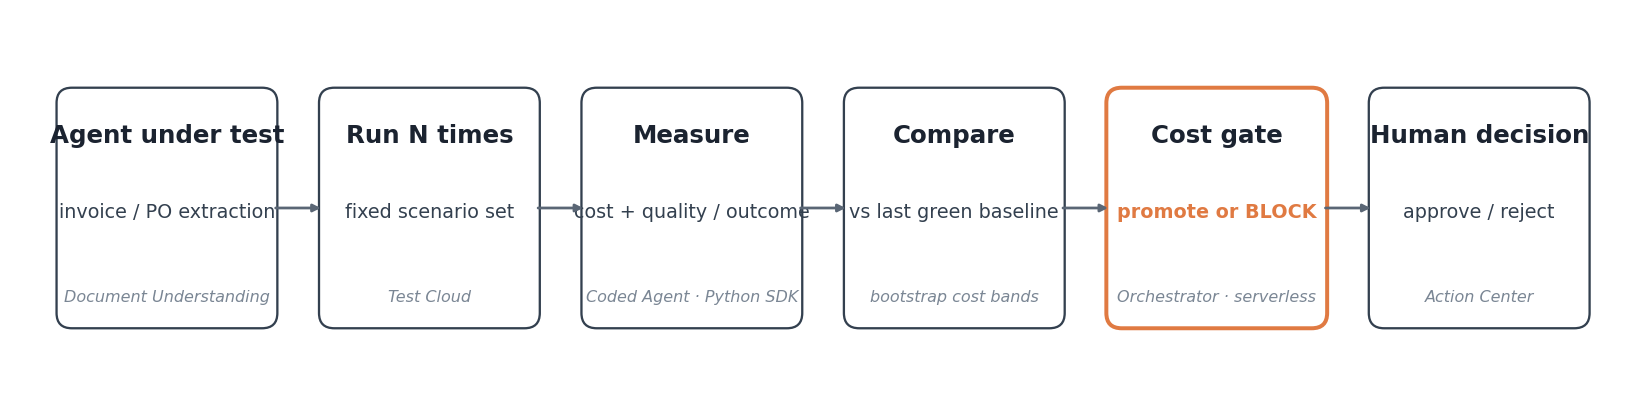
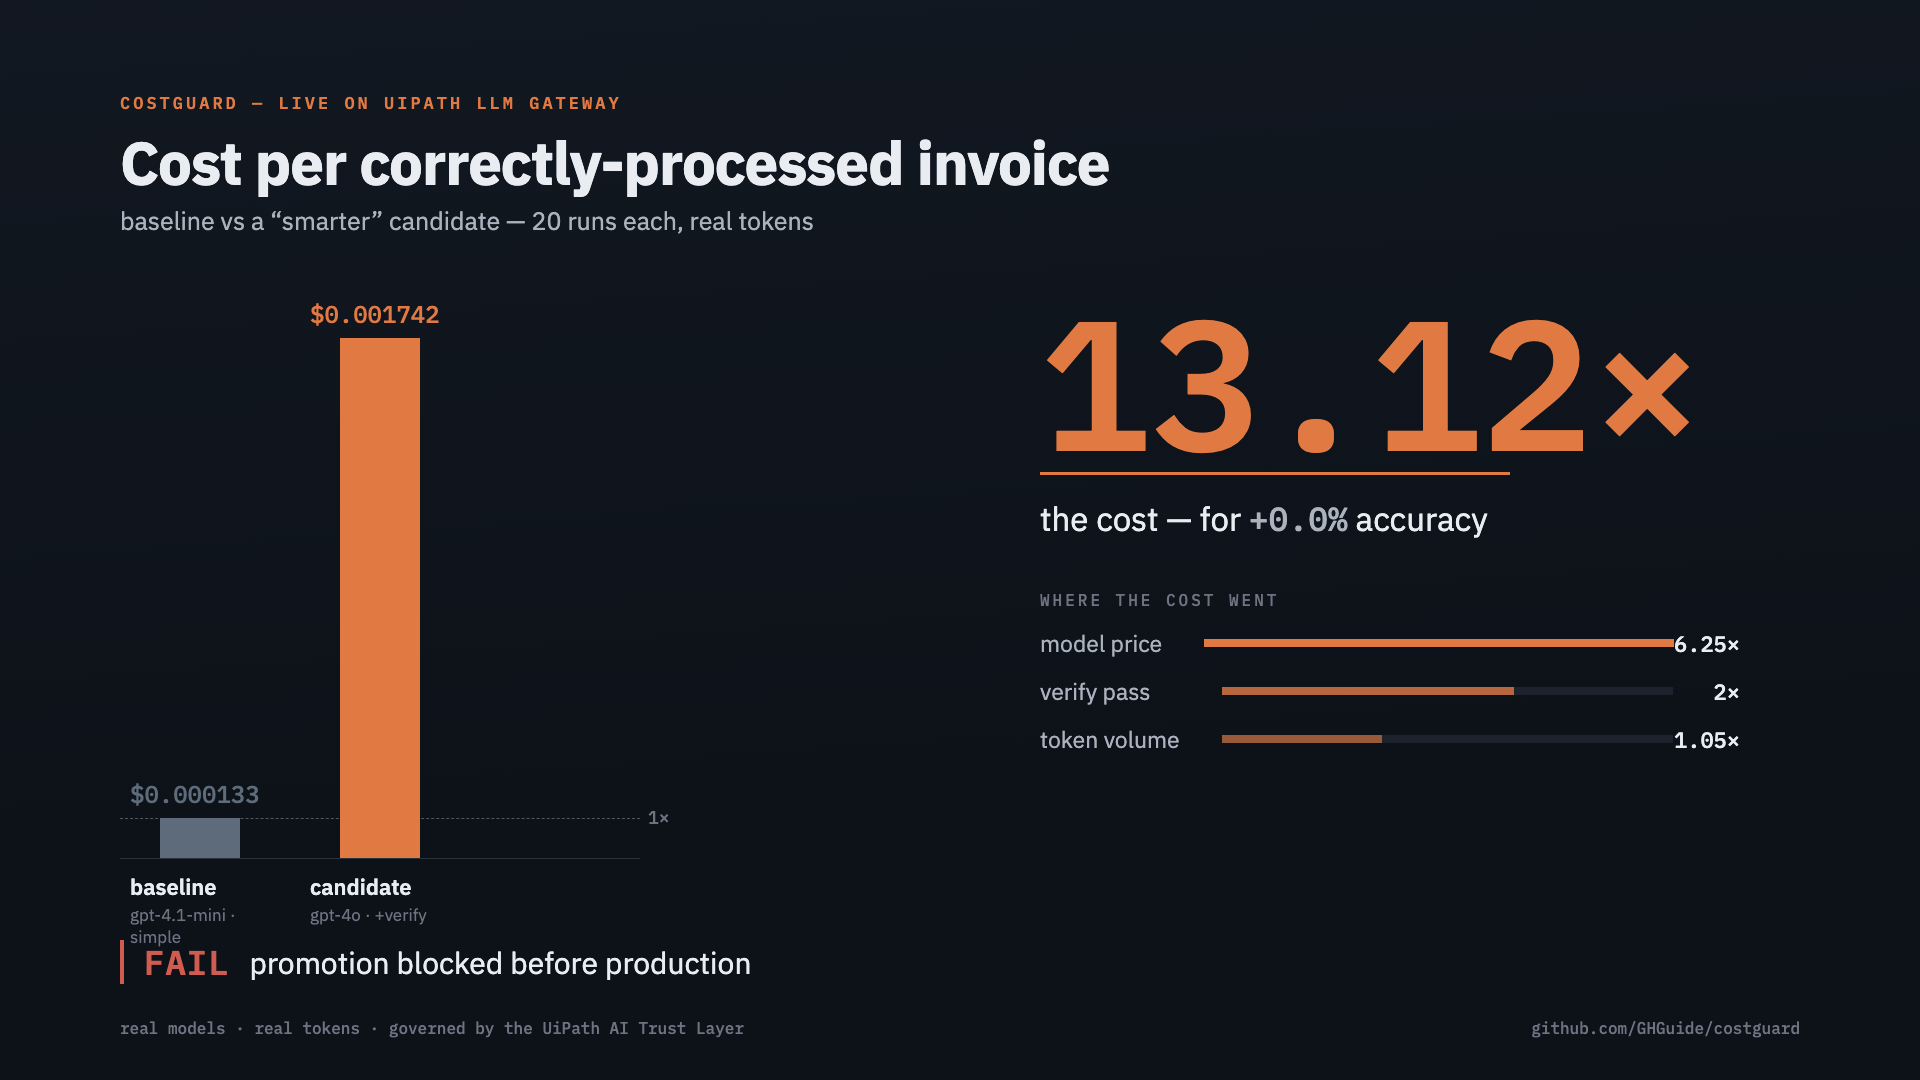
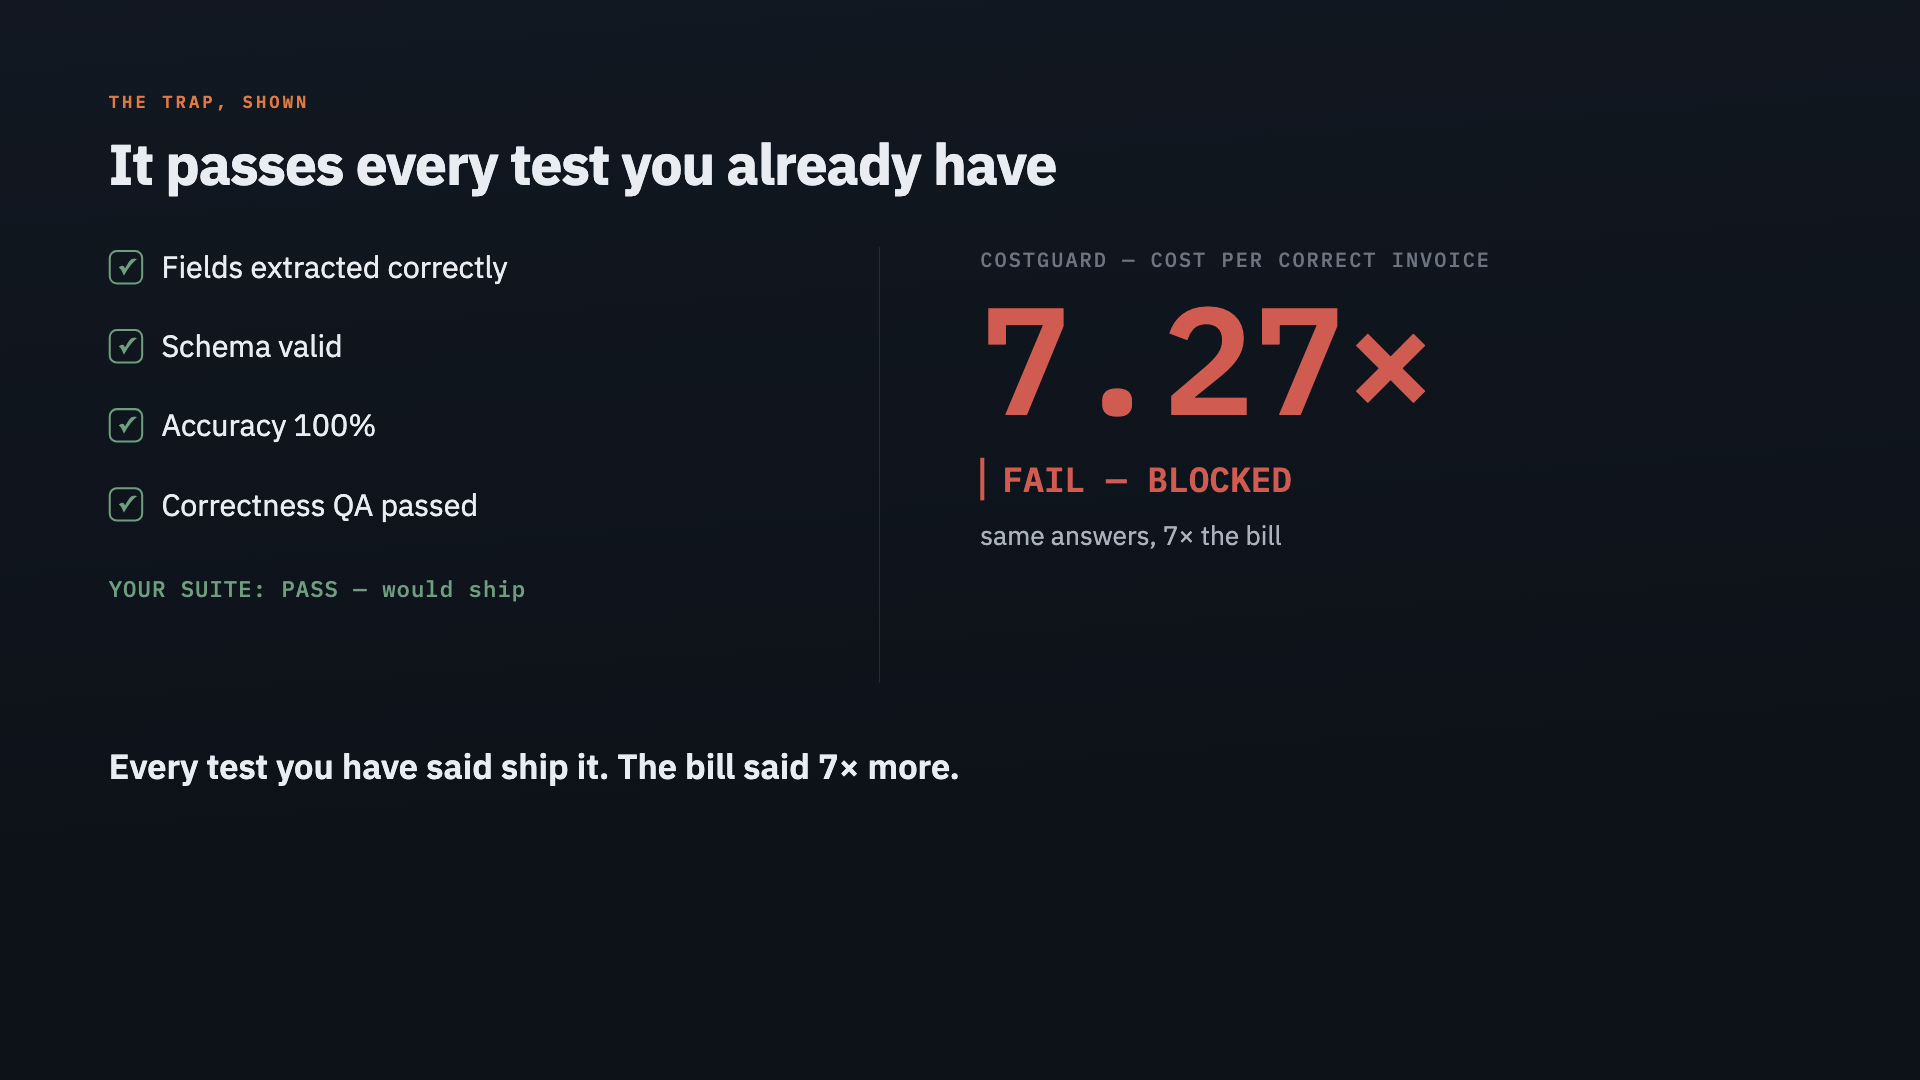
CostGuard adds a new, first-class test type to UiPath Test Cloud: cost & efficiency regression testing for AI agents. Before a changed agent is promoted, it runs the agent N times on a fixed scenario set, measures cost per *correctly-processed outcome* (cost per correct invoice — not per token), compares statistically (bootstrap CI) to the last approved baseline, and returns PASS → promote / FAIL → block / NEEDS_REVIEW → human in Action Center. Cost is paired with a quality score, so "cheaper-but-dumber" can't sneak through. When it blocks, a second agent — the Cost Explainer — root-causes why in plain language.
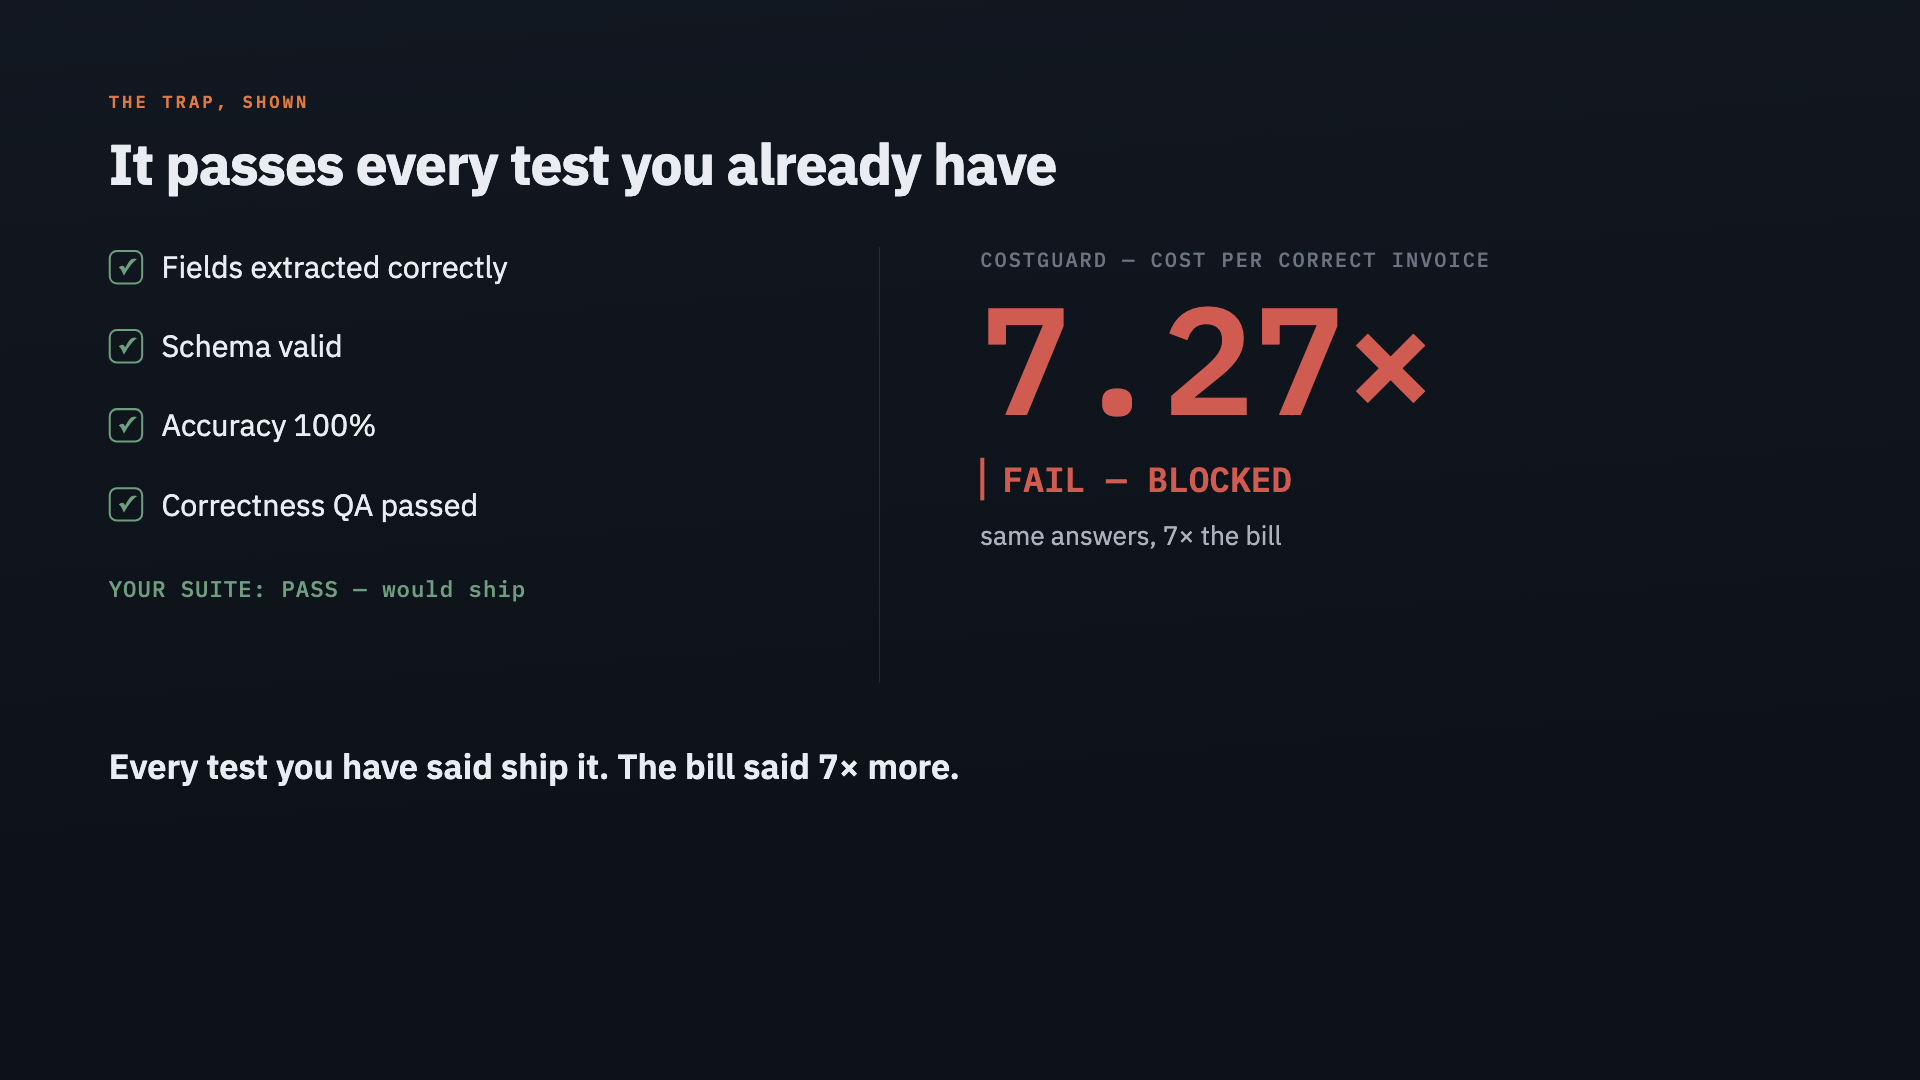
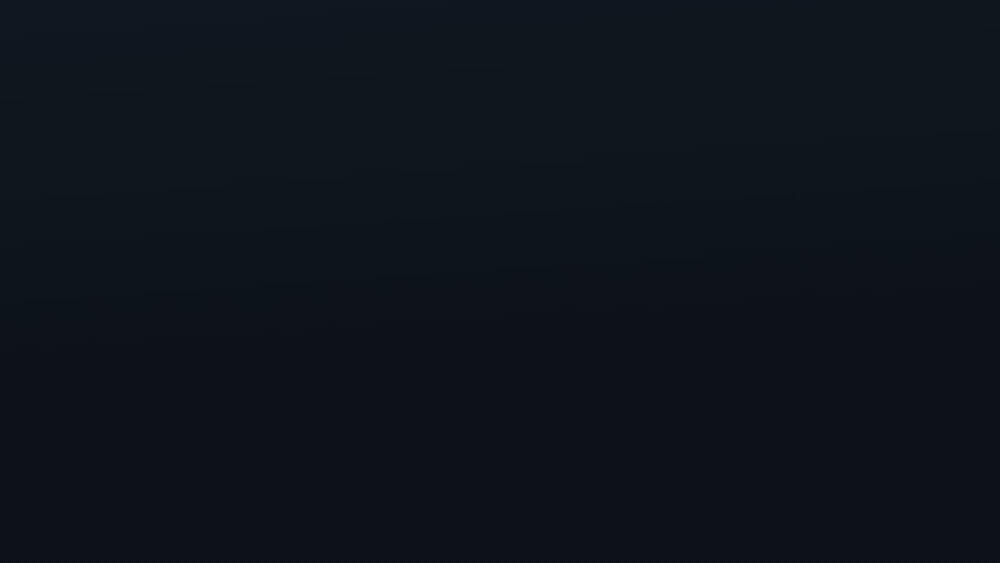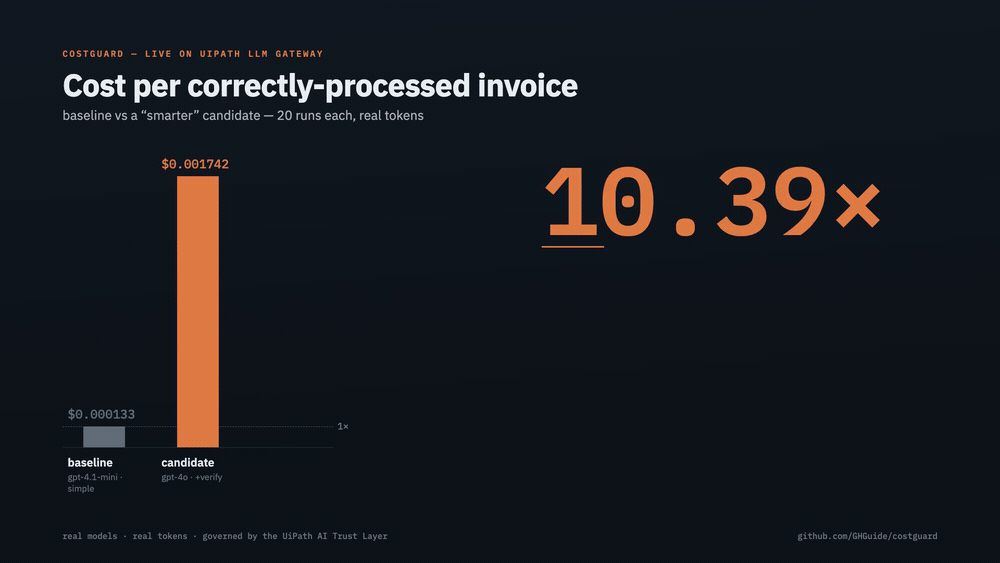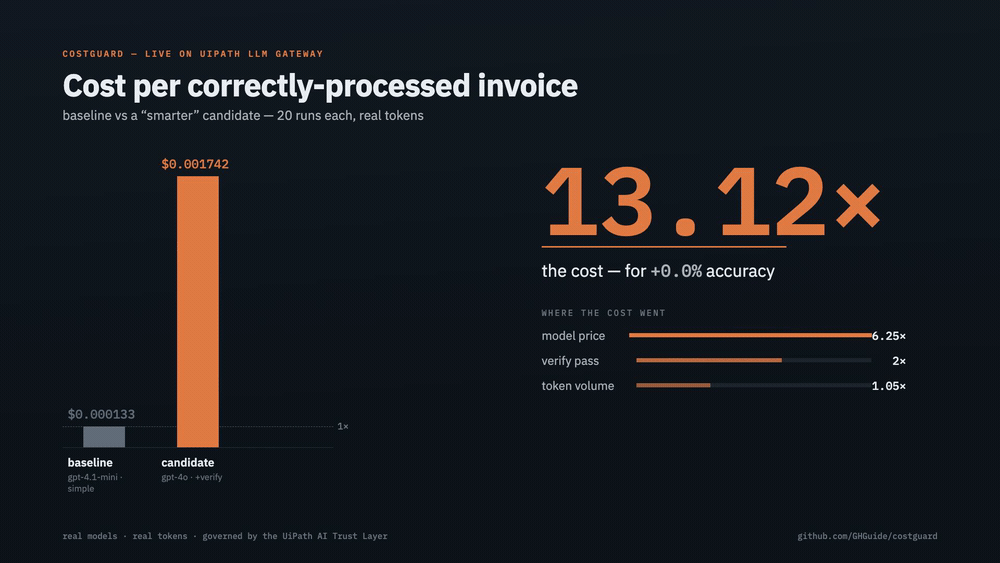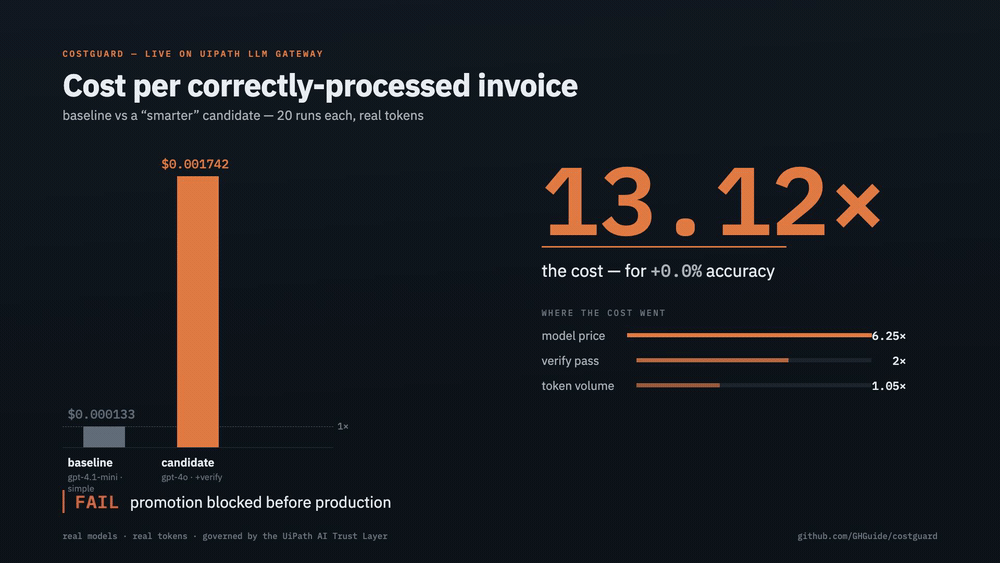
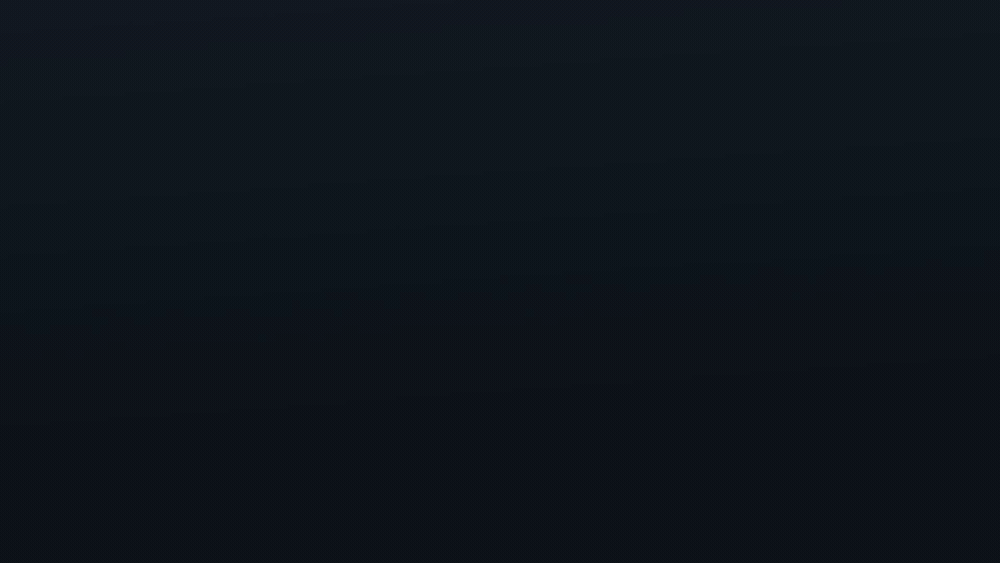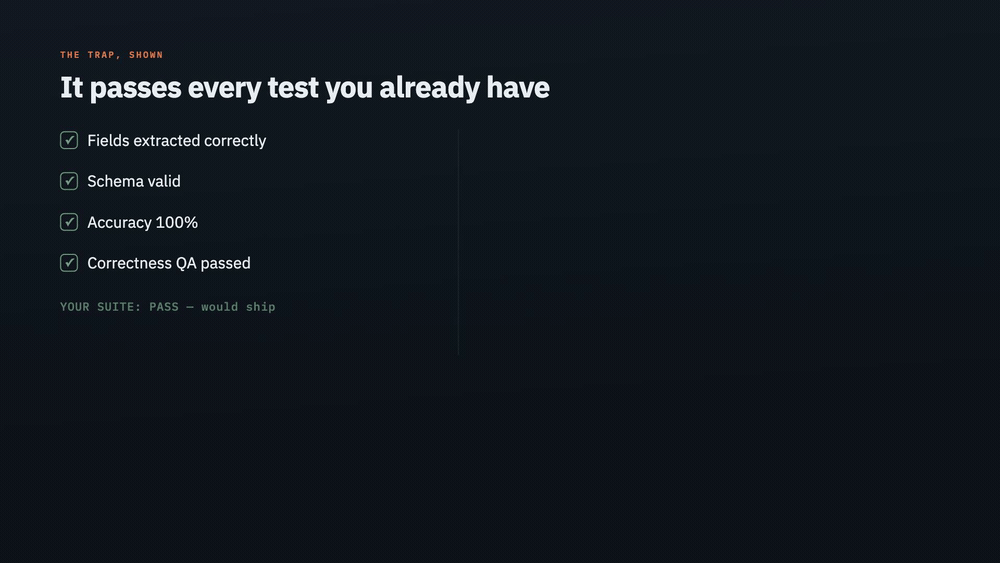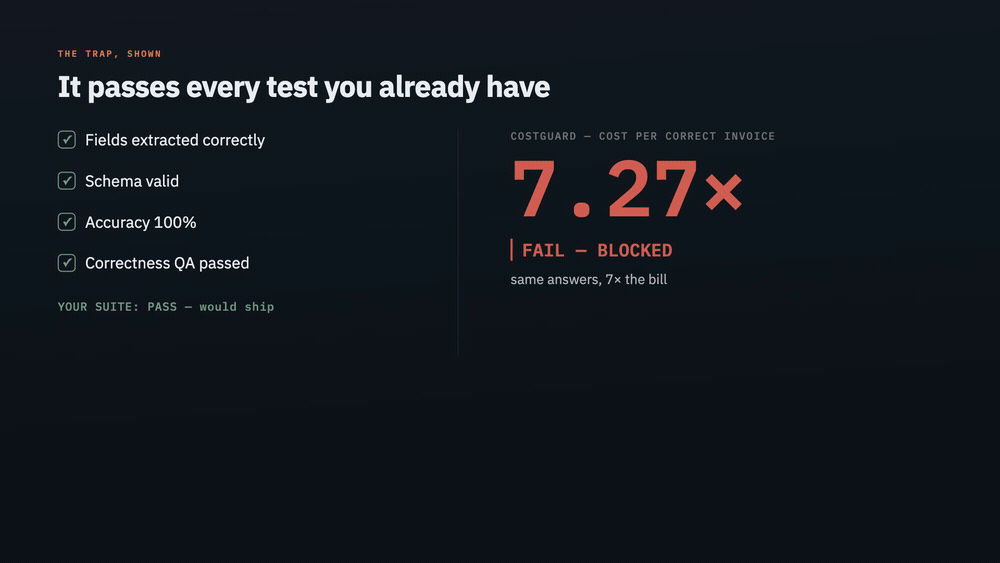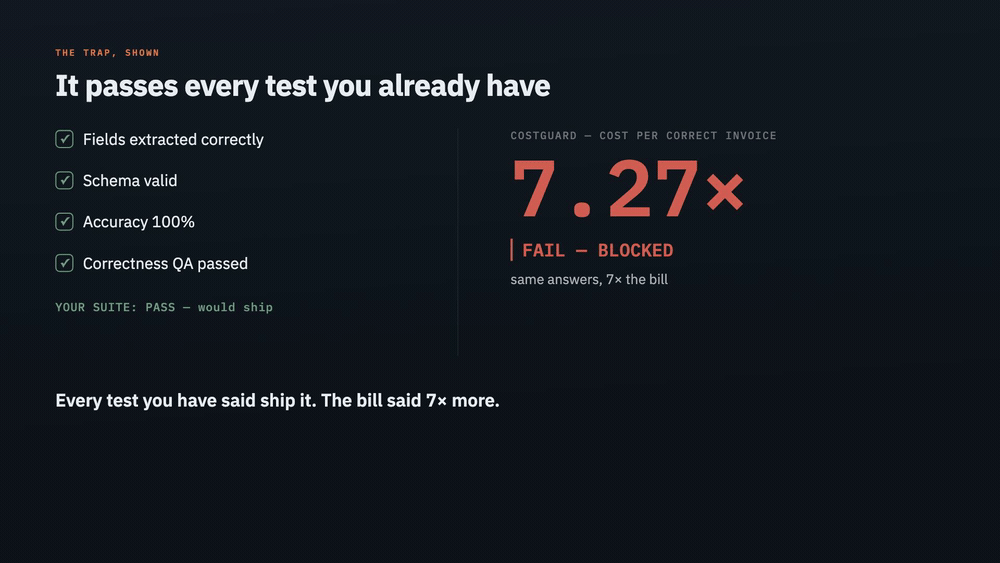
The whole idea in one line: a candidate that passes every correctness test is 7× more expensive per correct invoice — CostGuard blocks it before it ships.
How I built it
A coded agent (UiPath Python SDK), packaged and run as a serverless Orchestrator job. The agent-under-test runs on the UiPath AI Trust Layer LLM Gateway (real models, real tokens, no external key). On a 12-invoice realistic corpus, the baseline measured 98.3% field accuracy (a real extraction error), the candidate 100% — but 15.6× the cost → blocked. The verdict is registered as a first-class Test Cloud result (test case CG:1 → Failed). An external LangChain agent is gated the same way (12.76× → blocked), proving it tests any framework.
Built with a coding agent (bonus)
The entire solution — engine, statistics, the 2nd agent, the 30-scenario regression suite, and the full UiPath integration — was designed, built, tested (27 passing tests, CI-green), packaged, deployed, and run by Claude Code via UiPath for Coding Agents. It also solved real platform problems (granular Test Manager scopes, the release-key job-start, the async LLM-gateway call). Evidence: docs/claude-code-log.md + the git history.
Challenges
Cost is gameable (cheaper-but-dumber passes a single run), so I gate on cost-per-outcome with bootstrap confidence intervals over N runs, never a single run. Registering the verdict as a real Test Cloud result took the right Test Manager execution scope; the HITL task endpoint isn't provisioned on the sandbox, so the gate degrades gracefully.
What's next
Cost-per-outcome trends as a continuous Maestro-orchestrated control tower; Document Understanding on real scanned PDFs; deeper Action Center forms.
Built With
- ai-trust-layer
- claude-code
- langchain
- llm-gateway
- opentelemetry
- python
- uipath-action-center
- uipath-coded-agents
- uipath-document-understanding
- uipath-orchestrator
- uipath-python-sdk
- uipath-test-cloud

Log in or sign up for Devpost to join the conversation.