-
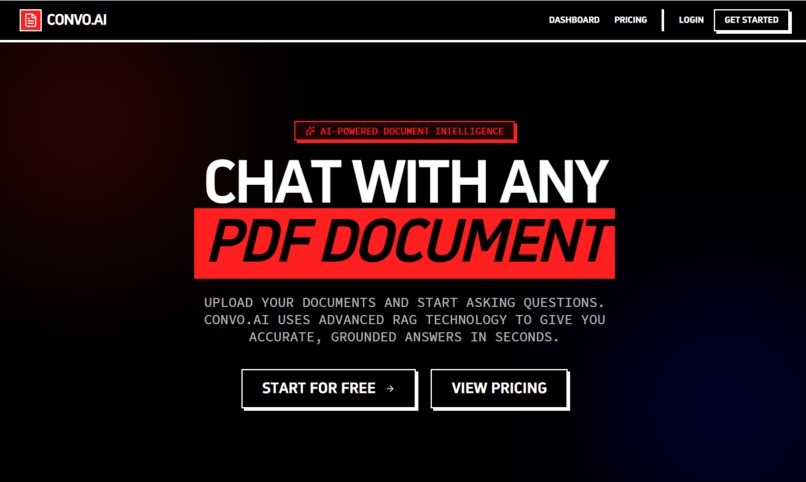
Homepage
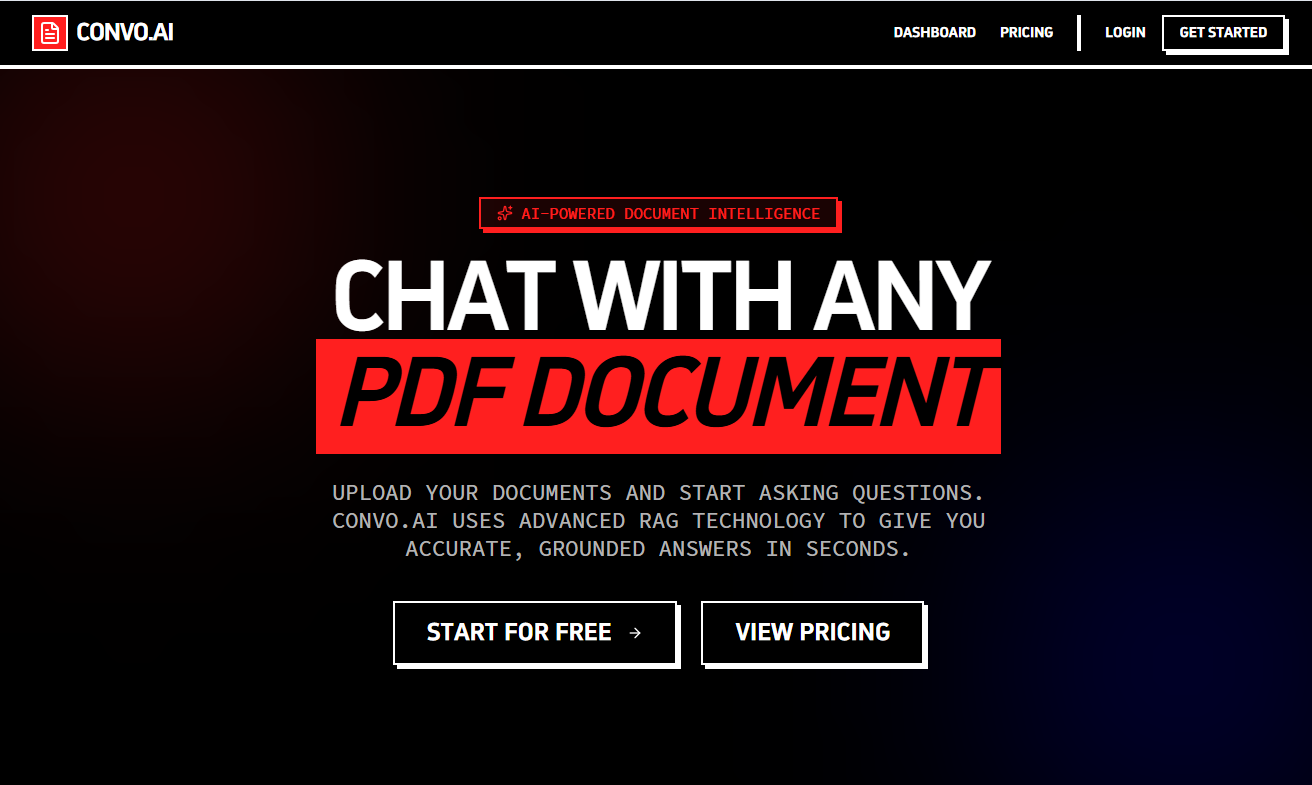
Convo.ai (Chat with Your Documents)
💡 Inspiration
In today’s world, we are overloaded with PDFs, research papers, notes, reports, documentation — but extracting useful information from them is still slow and manual.
While tools like ChatGPT revolutionized conversations, they lack deep, structured understanding of your personal documents.
This inspired me to build Convo.ai, A platform where documents are no longer static, but interactive. Instead of reading PDFs, you talk to them.
🧠 What I Learned
Building Convo.ai was a deep dive into modern AI systems and full-stack engineering:
How Retrieval-Augmented Generation (RAG) works Generating and using embeddings with OpenAI APIs Efficient vector search using Pinecone Designing scalable backend APIs with tRPC Managing relational data using Prisma Building clean, responsive UI with modern design systems
I also learned that UX matters as much as AI — even a powerful model feels weak without a smooth interface.
🏗️ How I Built It
Convo.ai is built as a full-stack AI SaaS application using a modern tech stack:
⚙️ Tech Stack Frontend: Next.js + TypeScript + Tailwind CSS Backend: tRPC (type-safe APIs) Database: PostgreSQL + Prisma Authentication: Kinde Auth File Uploads: UploadThing AI Engine: OpenAI Vector Database: Pinecone Payments: Stripe 🔄 System Architecture
At its core, Convo.ai uses a RAG pipeline:
Answer=f(User Query,Relevant Document Context) Flow: User uploads a PDF Text is extracted and split into chunks Each chunk is converted into embeddings Embeddings are stored in Pinecone User asks a question Relevant chunks are retrieved via similarity search Context + query is sent to the LLM AI generates a grounded response 🧩 Key Features 📄 PDF upload & processing 💬 Chat interface (like ChatGPT) 🔍 Context-aware answers ⚡ Fast vector search 🔐 Authentication system 💳 Subscription-ready (Stripe integration) ⚔️ Challenges I Faced
- 📚 Handling Large PDFs
Splitting documents into optimal chunk sizes was tricky:
Too small → loss of context Too large → poor retrieval accuracy
- 🎯 Improving Answer Quality
Early responses were generic. Fix:
Added context injection Tuned prompt structure Retrieved top-k relevant chunks
- ⚡ Performance Optimization
Embedding generation and search can be slow:
Used batching Cached embeddings Optimized database queries
- 🔗 Integrating Multiple Systems
Coordinating between:
UploadThing (files) Pinecone (vectors) OpenAI (AI) Prisma (DB)
was complex and required careful system design.
🎯 What’s Next 📑 Support for multiple file types (DOCX, TXT) 🧠 Memory across conversations 📊 Document summarization dashboards 🌍 Team collaboration features
Built With
- authentication:
- file
- kinde
- languages:-typescript
- node.js-database:-postgresql
- pinecone
- prisma-ai-&-vector-db:-openai
- shadcn-ui-backend:-trpc
- sql-frontend:-next.js
- tailwind-css
- uploads:
- uploadthing


Log in or sign up for Devpost to join the conversation.