-
-
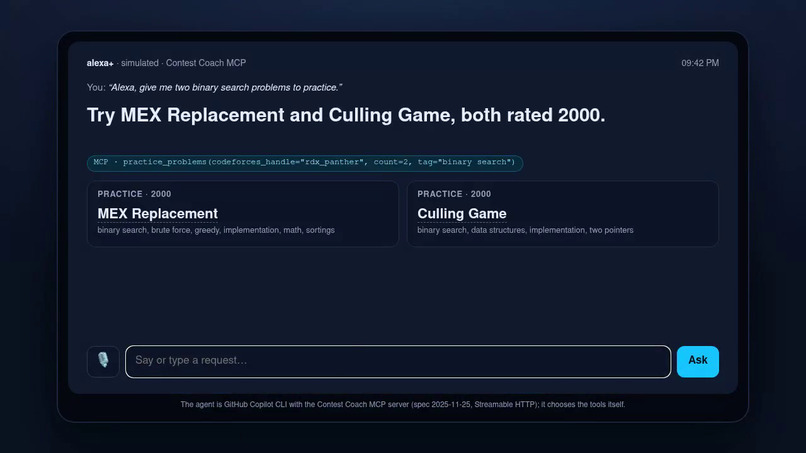
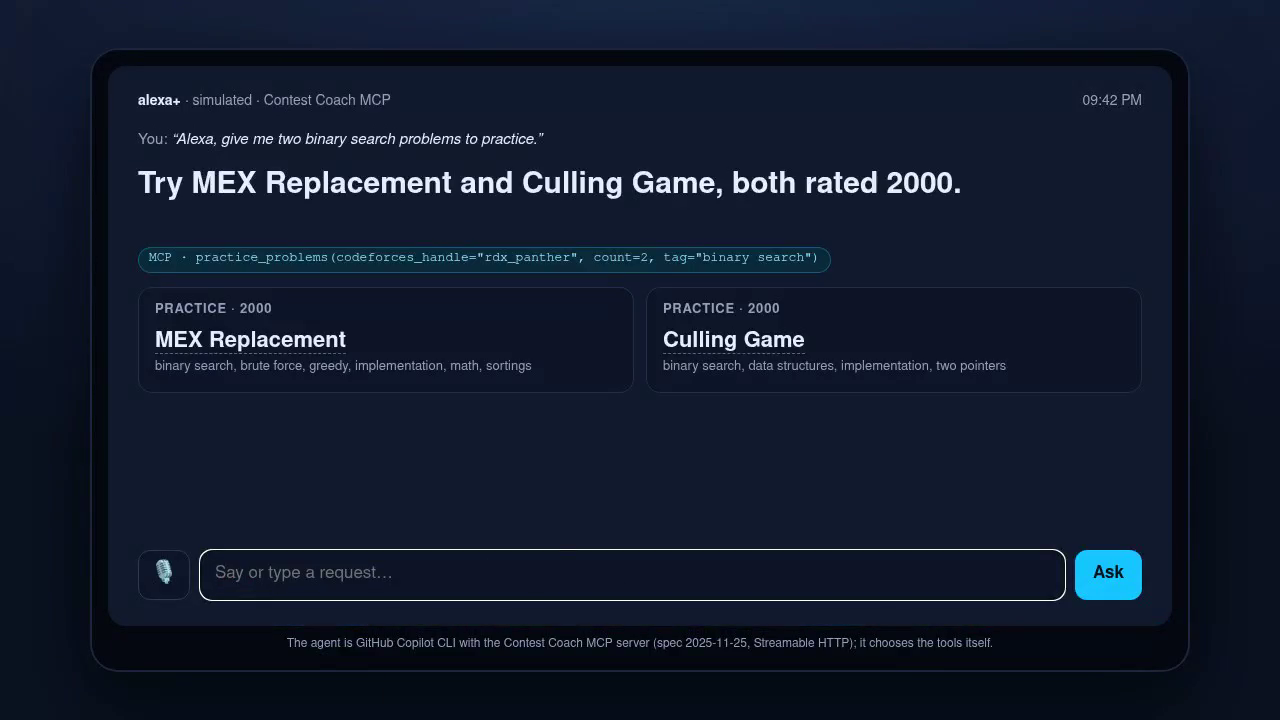
Simulated Alexa+ screen: the agent called practice_problems(tag="binary search") and reads the answer aloud
-
Contest Coach: an MCP server for Alexa+
Inspiration
I'm a competitive programmer (Codeforces Expert, LeetCode Guardian). The hard part of practice isn't finding problems, it's choosing the right ones. Most people grind what they're already good at. I wanted to ask a voice assistant "what should I practice today?" and get an answer based on my own submission history, not a generic list.
What it does
Contest Coach is a self-hosted MCP server that Alexa+ (or any MCP client) can call. Five read-only tools:
upcoming_contests: Codeforces and LeetCode contests, soonest first.my_ratings: current ratings, rank, and recent rating changes.weak_topics: topics that show up a lot near your rating but that you rarely solve or often fail.practice_problems: unsolved problems 100–300 points above your rating in those topics (or a tag you name).daily_plan: one answer for "what should I practice today?".
Every tool returns a short sentence to say aloud plus structured data (structuredContent with an outputSchema), so a voice-only device can speak and an Echo Show-style screen can show links.
How we built it
- MCP TypeScript SDK 1.32 (protocol
2025-11-25), stateless Streamable HTTP: a fresh server and transport per request, behind Express. - Weak topics: for each tag, combine (a) how often the tag appears in problems near your rating, (b) how many problems with that tag you've solved, and (c) how often you fail it.
- Live public data: the Codeforces API (
user.status,problemset.problems,user.rating,contest.list) and LeetCode's public GraphQL, with a 10-minute cache. - Simulated Alexa+ experience: an Echo Show-style web page. A spoken or typed request goes to an AI agent (GitHub Copilot CLI with Contest Coach configured as an MCP server), which picks the tools itself. The answer is read aloud, and the screen shows the exact tool calls and their structured results, taken from the server's opt-in call log.
In the demo
Three real, unscripted requests, with only the agent's waiting time sped up:
- "When's the next contest, and how did my last one go?" The agent chains
upcoming_contestsandmy_ratings. - "What am I weak at?"
weak_topicsreturns binary search, data structures, implementation. - "Give me two binary search problems to practice."
practice_problemswithtag="binary search".
Challenges we ran into
- Voice answers need to be short and natural, so every tool writes its own spoken sentence instead of leaving the agent to summarise a JSON blob.
- "Weak" is subtle: a topic you've never touched near your rating matters more than one you fail occasionally. The score balances coverage, practice and failure rate.
- To show exactly what the agent did on screen, I added an opt-in call log to the server rather than parsing the agent's output.
What's next for Contest Coach
Account linking so Alexa remembers your handles, AtCoder and CodeChef support, and spaced repetition for topics you got wrong.
Built With
- alexa
- codeforces-api
- express.js
- github-copilot-cli
- leetcode
- mcp
- model-context-protocol
- node.js
- playwright
- typescript
- zod

Log in or sign up for Devpost to join the conversation.