-
-
CompassCart
Inspiration
Conversational shopping often fails because systems treat every turn like a brand-new keyword search, or they stubbornly follow a preference the shopper has already changed. Track 4 rewards real shopping assistance: finding the exact item quickly, asking truly useful clarification questions, and recovering smoothly when the user changes their mind.
What it does
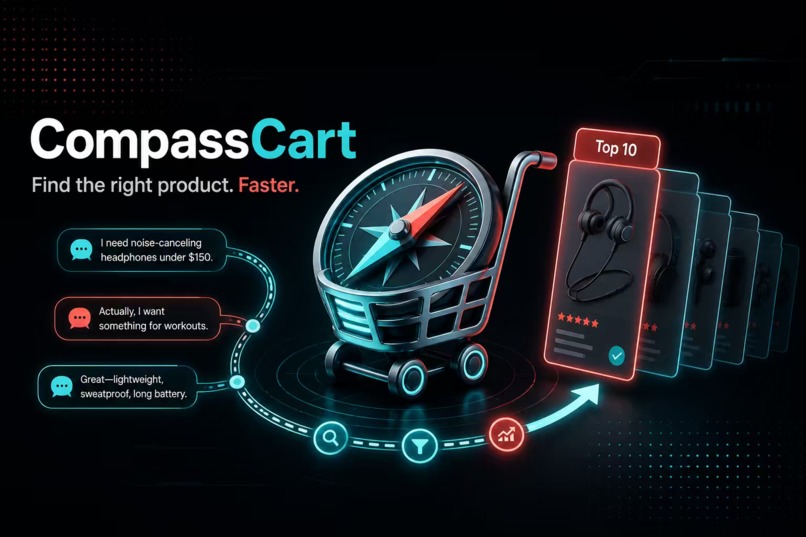
CompassCart turns every shopping conversation into a versioned, step-by-step constraint ledger.
- Smart Intent Routing: Handles precise purchases, broad browsing, and mid-turn intent changes through tailored logic paths.
- Hybrid Search Retrieval: Combines lexical search, catalog attributes, shopper profiles, and local semantic AI models to find candidates.
- Smart Reranking: Filters against hard requirements (like color or category) and prioritizes exact phrase matches where helpful.
- Conversion-Driven Questions: Asks clarification questions only when the answer will significantly narrow down the product list.
- Clean Outputs: Always returns a clean, deduplicated list of exactly ten valid catalog product IDs.
Accomplishments that we're proud of
| Highlight / Category | Key Metric & Achievement | Impact & Details |
|---|---|---|
| Performance Boost | 0.8225 Public Evaluation Score (from 0.1067 baseline) | Achieved a 96.5% HitRate@10 and 0.5810 MRR across public evaluation turns. |
| Air-Gapped Execution | $0.00 Runtime API Cost | 100% offline compliance with zero network socket access, zero credentials, and zero LLM tokens. |
| Speed & Efficiency | < 100 ms Average Turn Latency | Sub-100ms response times while maintaining a total process memory footprint under 410 MiB. |
| System Reliability | 1,047 / 1,047 Passed Test Suites | Verified across 100% automated test suites with consistent cross-fold stability (CV Mean: 0.8122). |
How we built it
- Stack, data, and APIs: Developed in Visual Studio Code on Windows 11 (verified on macOS), in Python 3.12 with NumPy, ONNX Runtime, SQLite FTS5, and pytest. The agent is fully offline — APIs used: none (zero network I/O, zero API calls). It indexes the organizer-provided 50,000-product catalog, and its local semantic encoder is a quantized all-MiniLM-L6-v2 ONNX model with int8 catalog vectors built from the Amazon Reviews 2023 dataset.
- Lexical & Keyword Core: Built using SQLite FTS5 (BM25 search) with catalog attribute normalization and a pure-Python backup engine.
- Local Semantic Search: Powered by a quantized
all-MiniLM-L6-v2ONNX model and int8 catalog vectors, giving semantic understanding with zero external database dependencies. - Candidate Fusion: Blends multiple search strategies together using Weighted Reciprocal-Rank Fusion (RRF).
- State Management: Tracks constraint confidence, history, versioning, and status across turns while keeping the prompt context clean and focused.
- Smart Override Logic: Prioritizes new user intent over old pending questions (e.g., if a user says "Actually, I need leather," it won't misinterpret "leather" as an answer to a previous shoe question).
What makes it different
- 100% Offline-First: Operates with zero API calls, zero token costs, zero cloud credentials, and zero network I/O.
- Real Intent Overrides: When a user changes their mind, obsolete preferences are completely replaced (v1 → v2) rather than just down-weighted.
- Questions That Focus on Conversion: The agent measures expected conversion gain rather than asking questions just to keep talking.
- Learns from User Responses: The agent automatically learns which questions shoppers actually answer. For example, it discovered that asking about specific
featuresworked 97.3% of the time, while asking aboutbudgetproduced zero useful answers across 16 attempts. - Implicit Catalog Understanding: The agent naturally stopped asking about
sizeandbudgetafter realizing users rarely answered them. In reality, size and budget are missing from 91.3% and 77.6% of parent catalog items—a structure the agent deduced entirely on its own. - Route-Aware Reranking: Enables phrase-matching reranking during broad browsing (+0.038 HitRate boost) but automatically disables it during direct purchases to avoid over-complicating exact matches.
- Built-In Fail-Safes: Advanced AI components can fail or be disabled without breaking the core system or returning invalid data.
- Auditable Testing: Validated across four development testing folds, with a sealed fifth fold run strictly once to prevent benchmark overfitting.
Challenges we ran into
- Candidate Latency: Evaluating too many product candidates early on caused broad browsing searches to lag. Restricting diversity calculations to top-ranked candidates reduced turn times to under 100 milliseconds.
- Context Contamination: Mid-conversation intent changes were occasionally misparsed as answers to old questions. We fixed this state transition by evaluating overrides before checking pending questions.
- Reward Calibration: Our initial policy memory scored questions based on whether they expanded the constraint list, which measured our parser rather than user intent. Switching to track simulator refusal markers fixed the signal and gave us a +0.017 score boost.
- Route-Specific Memory: Combining conversation memory across all query types led to poor question choices. Separating memory by route solved this:
use_casequestions get answered 44% of the time when buying, but 0% of the time when browsing.
What we learned
- Catalog Schema Guides Policy: Dialogue systems shouldn't ask users about product attributes that the underlying catalog schema rarely records.
- Smart Logic Outperforms Heavy Models: Custom route-aware logic and state management provided bigger accuracy gains than adding larger, resource-heavy models.
- Fail-Safe Design is Essential: Building pure-Python fallbacks for vector assets ensures the agent remains fully functional regardless of hardware limits.
What's next for CompassCart
- Override-Aware Memory: Fine-tune memory tracking during mid-conversation resets to recover minor accuracy drops during intent switches.
- Multi-Catalog Schema Transfer: Generalize our question policy to adapt to completely new catalog schemas without needing new dense embeddings.
- On-Device Small Language Models: Explore lightweight sub-1B parameter local language models for natural phrasing while keeping our deterministic constraint ledger for state control.


Log in or sign up for Devpost to join the conversation.