Inspiration
AI coding agents are fast, but they usually work alone in a terminal. Teams can't see what they are doing, and nothing stops an agent from shipping code nobody reviewed. We wanted a room where people and agents work together, everyone can watch, and a human always makes the final call.
What it does
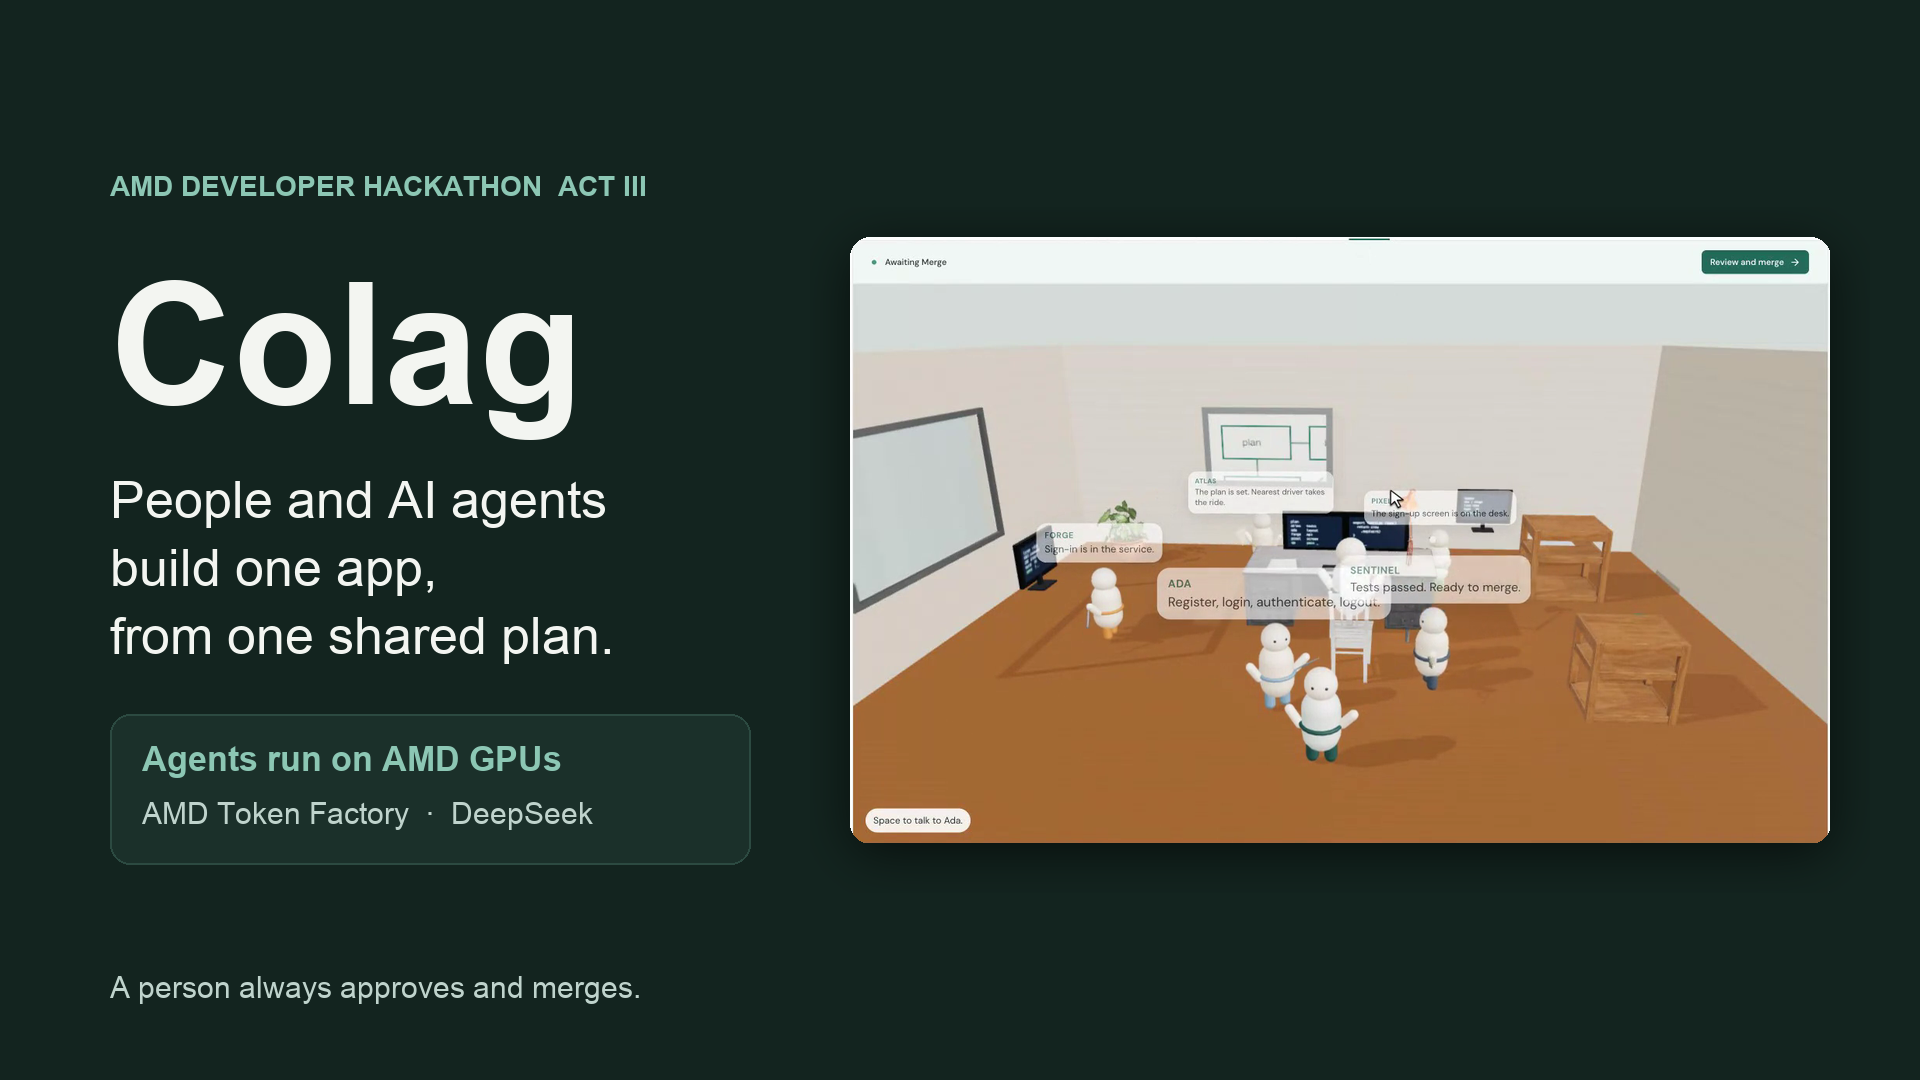
Colag is a shared room for building software with a team of AI agents.
- Atlas is the coordinator. It reads the request and writes a plan.
- A human approves the plan.
- Ada (architecture), Forge (backend) and Pixel (frontend) each build their part in their own Git worktree.
- Sentinel (QA) runs the tests in a sandbox with no network, then reviews the work.
- A human reviews and merges. Approve and merge are not tools, so no model can call them.
The Live tab shows the run as a 3D office. Each agent sits at its desk and says what it is doing, straight from the real run events.
How we built it on Nebius and NVIDIA
Every agent runs on NVIDIA Nemotron 3 Super 120B through Nebius Token Factory. Colag has a model runtime that speaks the OpenAI compatible API, so switching to Nemotron is four settings: provider, base URL, API key and model name. Our full acceptance test (plan, approval, build, sandboxed tests, review, merge) passes on Nemotron in about 40 seconds.
The rest of the stack: Next.js and React Three Fiber for the web app, Fastify for the API, Postgres and Redis for state, Yjs for live collaboration, Docker for the test sandbox, and the Model Context Protocol and A2A so outside agents can join a room.
Challenges
- Structured output. Agents must return plans and reviews as JSON. Some open models echoed the JSON Schema back instead of filling it in. We now check every answer against its schema and ask again, naming exactly what is wrong.
- JSON modes. Not every endpoint supports strict JSON Schema, so the runtime falls back from json_schema to json_object to plain text.
- Rate limits. Five agents share one key, so the runtime waits out 429 and 502 to 504 answers, honors Retry After and backs off.
What we learned
Open models are ready to run a real multi agent workflow when the runtime is strict about checking their output. Nemotron followed our plan format on the first try.
What's next
- Point the agent team at existing repositories to find and fix bugs.
- Dedicated Nebius endpoints for larger teams and longer runs.
- Voice control, so you can ask the room what it is doing.
Built With
- a2a
- docker
- fastify
- git
- model-context-protocol
- nebius
- next.js
- node.js
- nvidia-nemotron
- postgresql
- react
- redis
- three.js
- typescript
- vercel
- yjs

Log in or sign up for Devpost to join the conversation.