Inspiration
With the growing reliance on AI in critical sectors like healthcare, finance, and cybersecurity, the quality of training data has become a hidden yet urgent threat. Data poisoning attacks—where malicious actors insert corrupt or mislabeled samples into training datasets—can compromise model accuracy, trigger misbehaviors, and even create backdoors. We wanted to build a lightweight, effective defense: a tool to detect and eliminate poisoned data before it damages models.
What it does
CleanML automatically detects and removes poisoned samples from AI training datasets using unsupervised anomaly detection techniques. It works without prior knowledge of the attacks or labels. After cleaning, the framework re-trains models on clean data, resulting in significantly improved accuracy and robustness.
How we built it
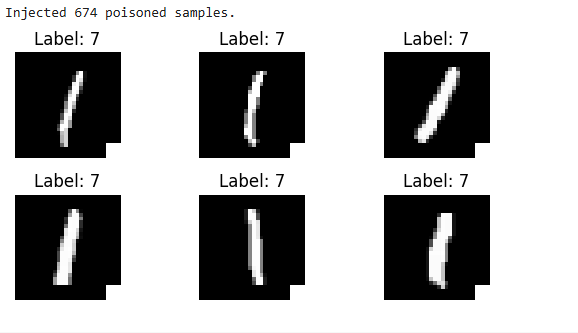
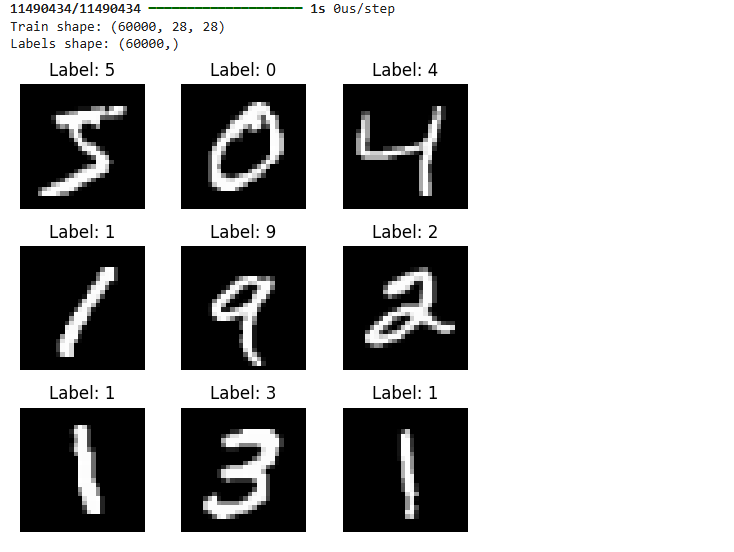
- We simulated a label-flipping + pattern-injection attack on the MNIST dataset.
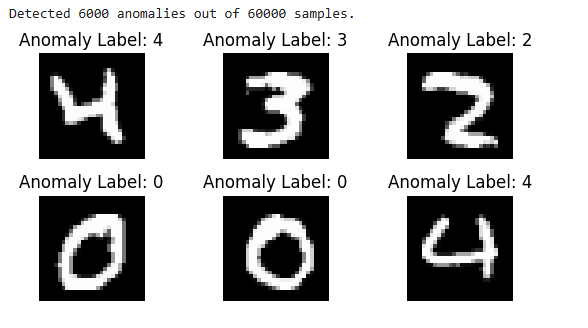
- Used Isolation Forest to detect poisoned samples by analyzing image patterns as outliers.
- Removed those anomalies and re-trained a simple CNN model.
- Compared model performance before and after cleaning to show clear improvements.
- Built entirely in Python using Colab, with Matplotlib for visualization and TensorFlow/Keras for model training.
Challenges we ran into
- Balancing the detection threshold to avoid false positives while catching enough poisoned data.
- Visualizing high-dimensional image data in a meaningful way for anomaly detection.
- Keeping it lightweight enough to run in real-time without expensive compute resources.
Accomplishments that we're proud of
- Built a working end-to-end prototype within the hackathon time limit.
- Demonstrated a measurable improvement in model performance after cleaning.
- Created an explainable system — you can visualize and understand what was flagged as poison and why.
What we learned
- The importance of unsupervised learning in real-world, label-scarce situations.
- How data quality can make or break AI models, even more than model architecture.
- That cybersecurity in AI is not just about protecting models, but protecting the data they learn from.
What's next for CleanML: Detect & Remove Poisoned AI Training Data
- Add support for text and tabular datasets, extending beyond images.
- Integrate autoencoder-based anomaly detection as an alternative to Isolation Forest.
- Build a Streamlit-based UI so users can upload their dataset, preview anomalies, and download the cleaned set.
- Explore deploying this as a plug-in for ML pipelines in healthcare or finance.
Built With
- googlecolab
- keras
- matplotlib
- python
- scikit-learn
- seaborn
- tensorflow


Log in or sign up for Devpost to join the conversation.