-
-
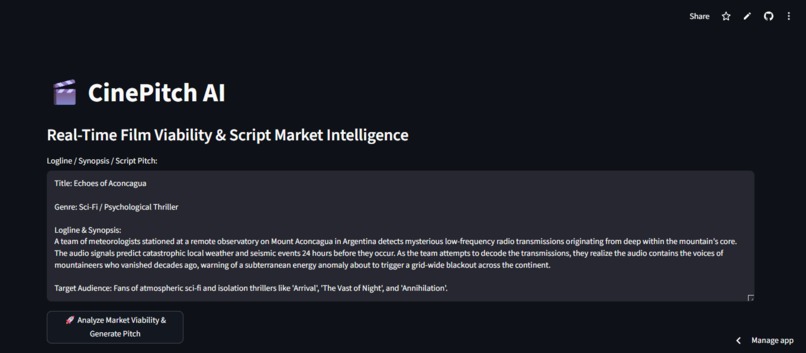
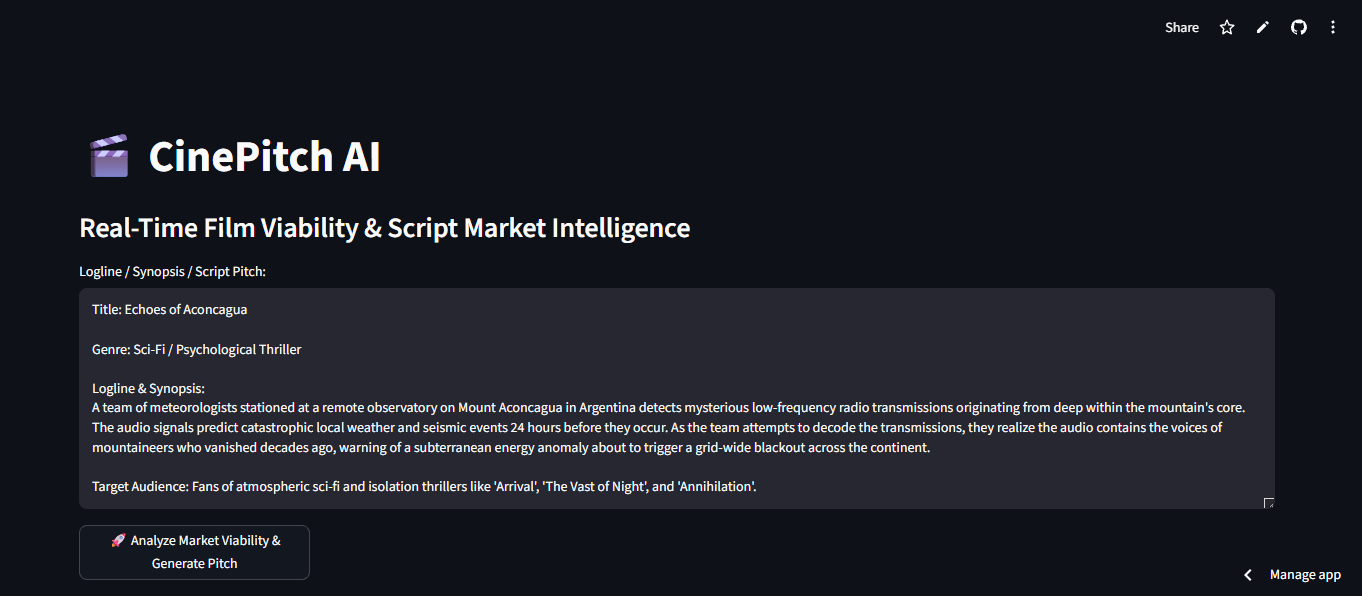
CinePitch AI | Logline / Synopsis / Script Pitch
-
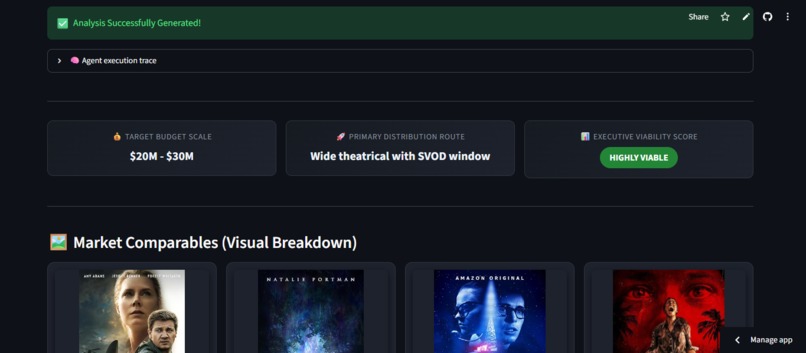
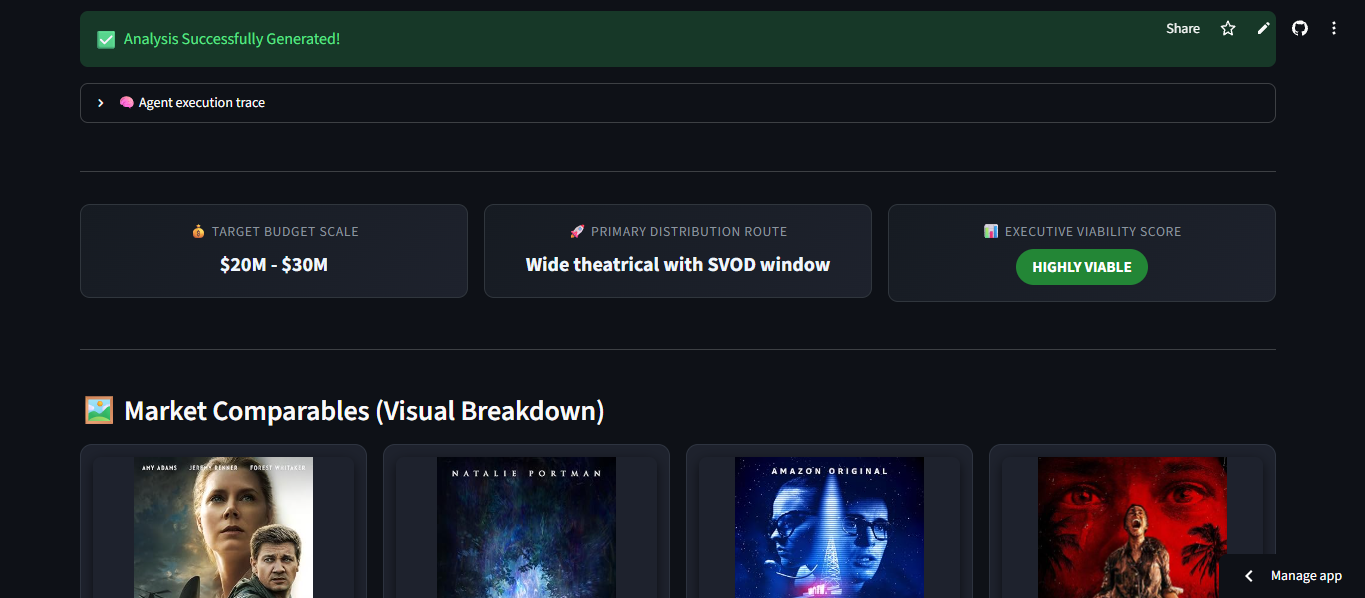
CinePitch AI | KPI cards
-
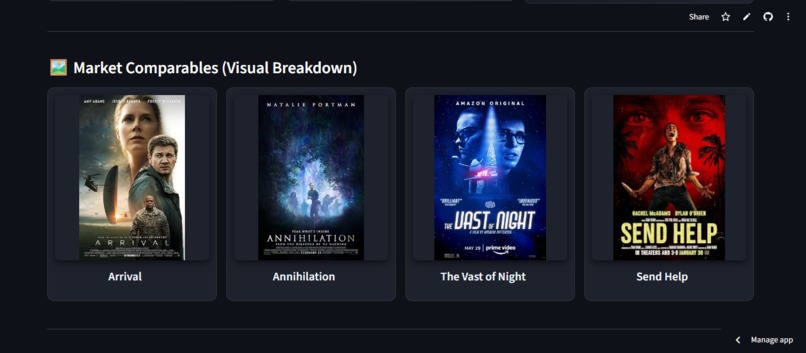
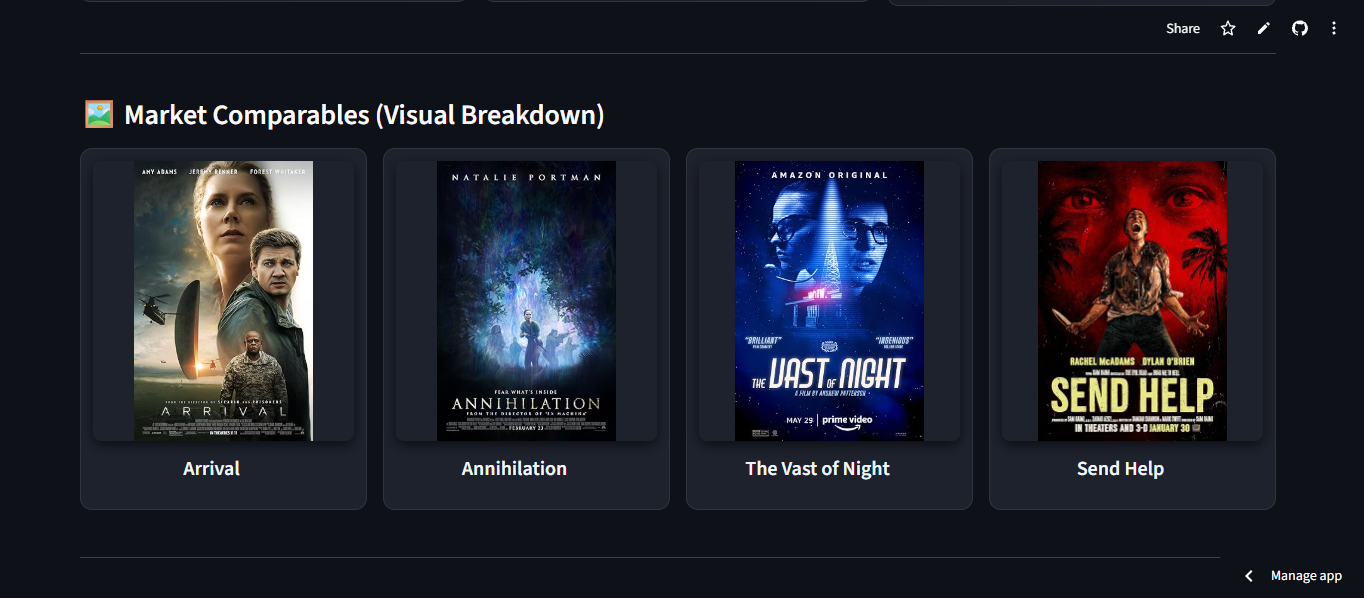
CinePitch AI | Market Comparables (Visual Breakdown)
-
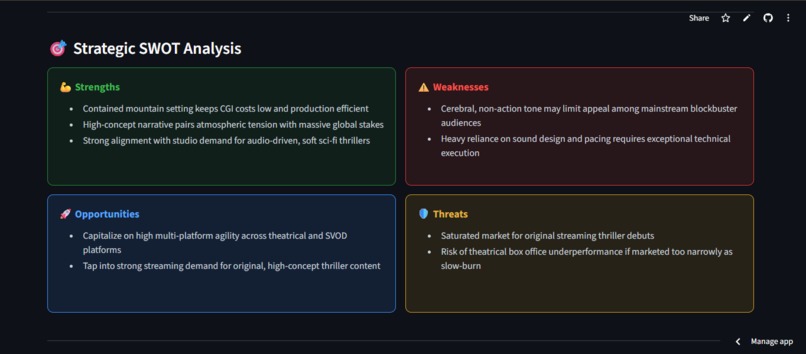
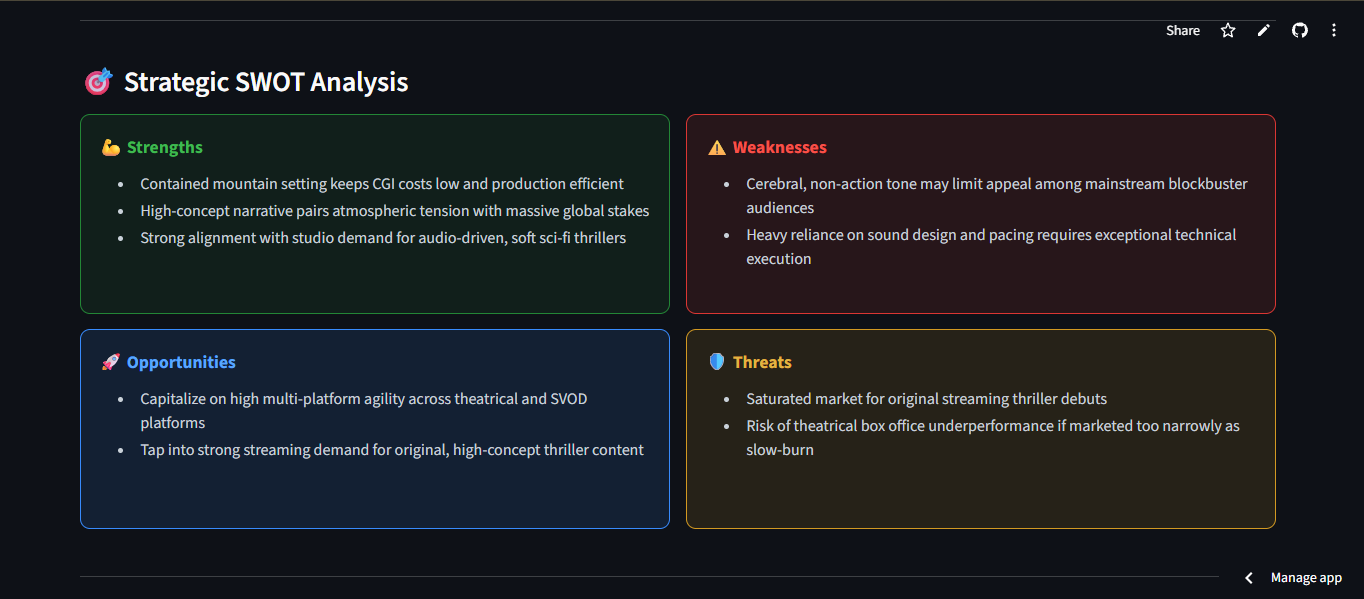
CinePitch AI | SWOT
-
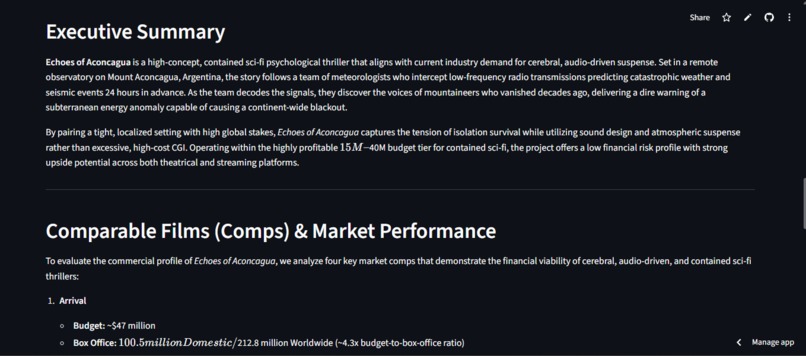
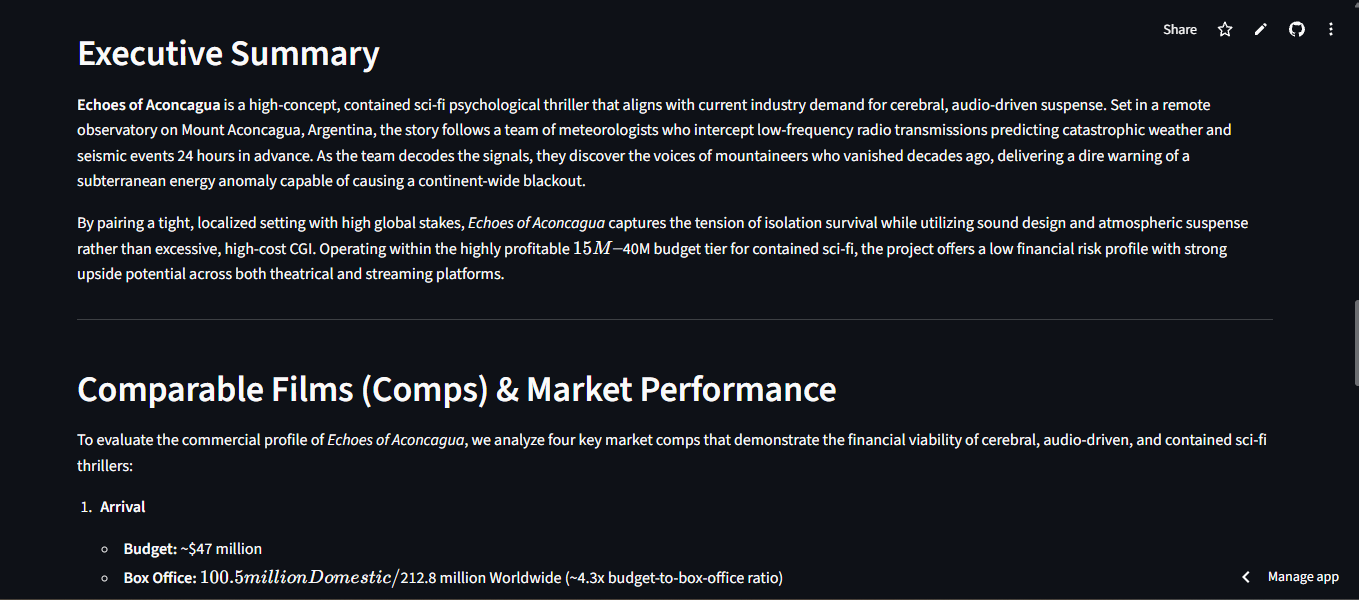
CinePitch AI | Executive Summary 1
-
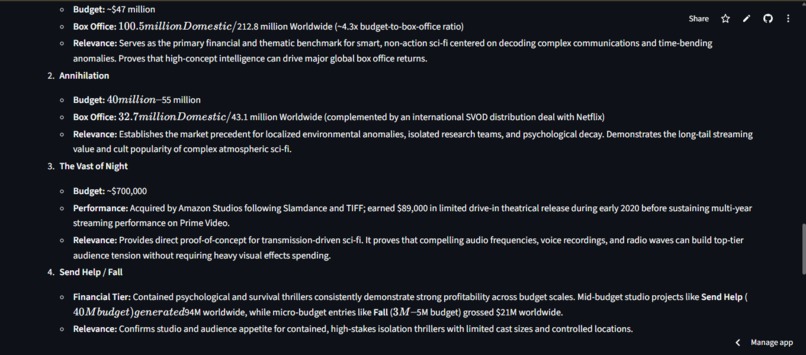
CinePitch AI | Executive Summary 2
-
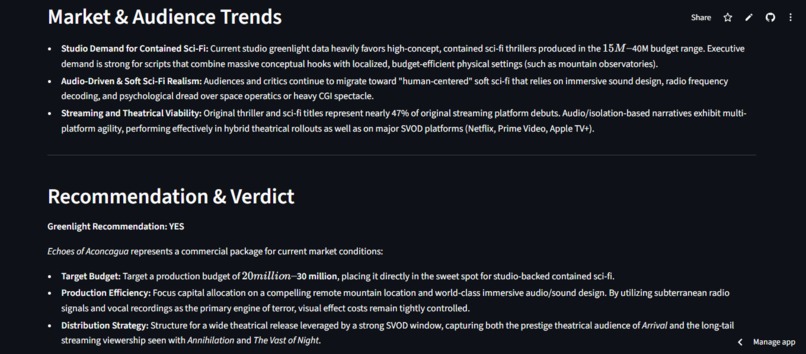
CinePitch AI | Executive Summary 3
Inspiration
Producers and investors greenlight films based on instinct and outdated comps. Validating a pitch against today's real market — budgets, box office performance, current trends — takes analysts days of manual research. I wanted an AI agent that could do that work in seconds, grounded in live data instead of the model's static training knowledge.
What it does
CinePitch AI takes a movie logline or script pitch and returns a full executive breakdown:
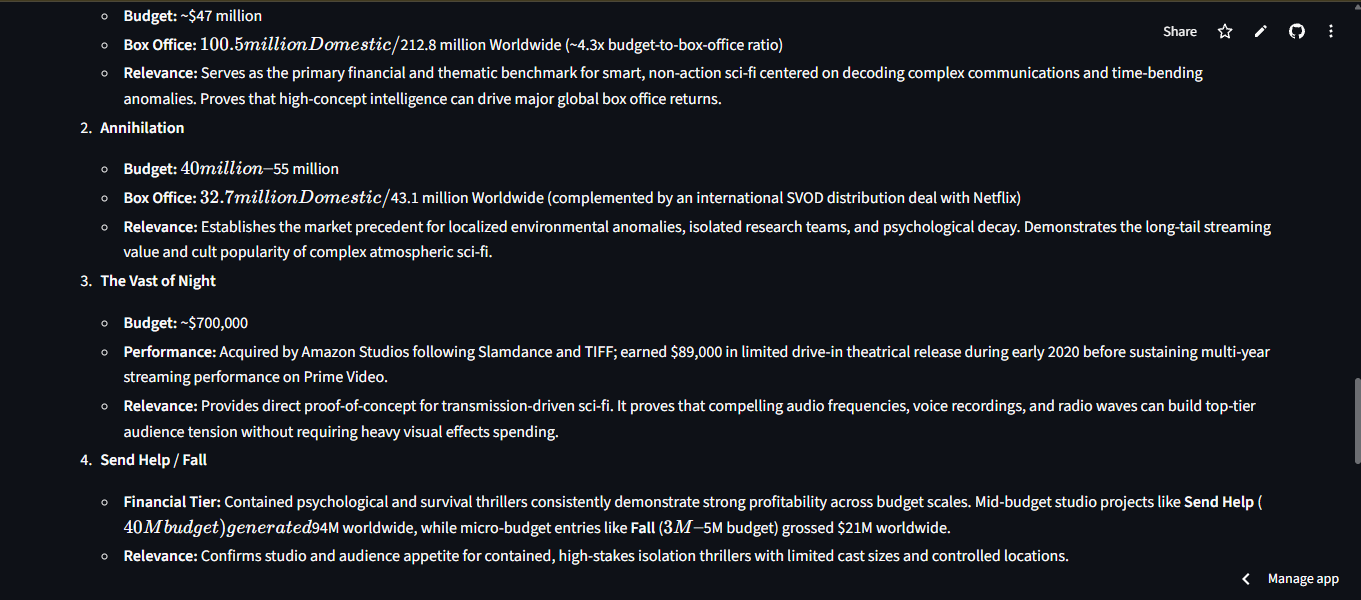
- 3–4 real comparable films with year, budget, and box office/streaming performance
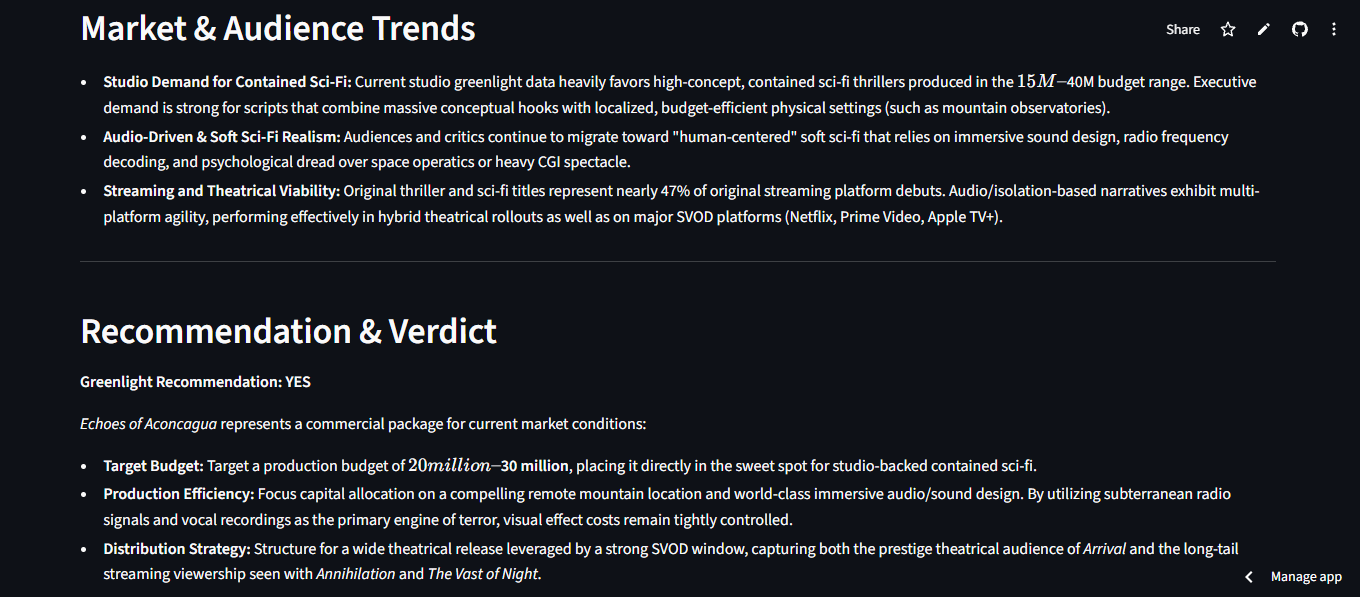
- Current genre and audience trends
- A viability score (Highly Viable / Moderate / High Risk)
- A suggested budget range and distribution route
- A SWOT analysis of the pitch
Everything is grounded in live market research pulled at the moment of analysis — not the language model's static knowledge.
How I built it
CinePitch AI runs on a Google ADK (Agent Development Kit) multi-agent pipeline, not a single LLM call. Three specialized Gemini-powered agents pass state to each other through a SequentialAgent:
- Research Agent — calls the Parallel Search API at runtime to pull live comparable films and market trend data.
- Writer Agent — turns the raw research into a structured executive pitch report.
- Extractor Agent — parses the report into structured JSON that drives the dashboard (KPIs, SWOT, comp titles).
The Streamlit frontend shows the live agent execution trace so users can watch the pipeline run, then renders KPI cards, comparable-film posters, and a SWOT grid from the extracted data.
Stack: Python, Streamlit, Google Gemini, Google Agent Development Kit (ADK), Parallel Search API, OMDb API.
Challenges I ran into
Keeping the agents grounded in real data instead of letting the writer agent hallucinate plausible-sounding comps. I solved this by forcing the research agent to gather and cite raw Parallel results before the writer agent ever runs, and by having the app clearly warn the user — instead of silently falling back to placeholder data — if the metrics-extraction step ever fails to parse.
Accomplishments that I'm proud of
Building a genuine multi-agent orchestration (not a single prompt-and-response) that actively calls a real-time search API mid-reasoning, and pairing it with a polished, production-feeling dashboard rather than a bare proof of concept.
What I learned
How to design agent pipelines where each step has a single clear responsibility and passes clean state forward — and how much more reliable that is than asking one model to research, write, and structure data all in a single call.
What's next for CinePitch AI
Multi-territory distribution modeling, a locations/incentives research sub-agent, and exportable investor-ready PDF decks.

Log in or sign up for Devpost to join the conversation.