-
-
Your own AI phrasebook starts with the words you could not say
-
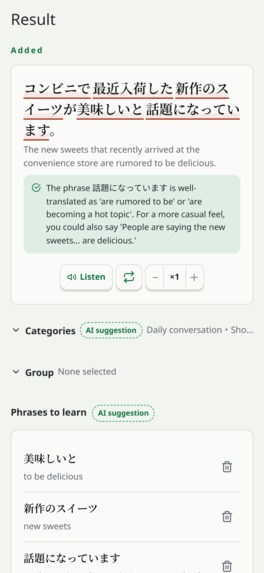
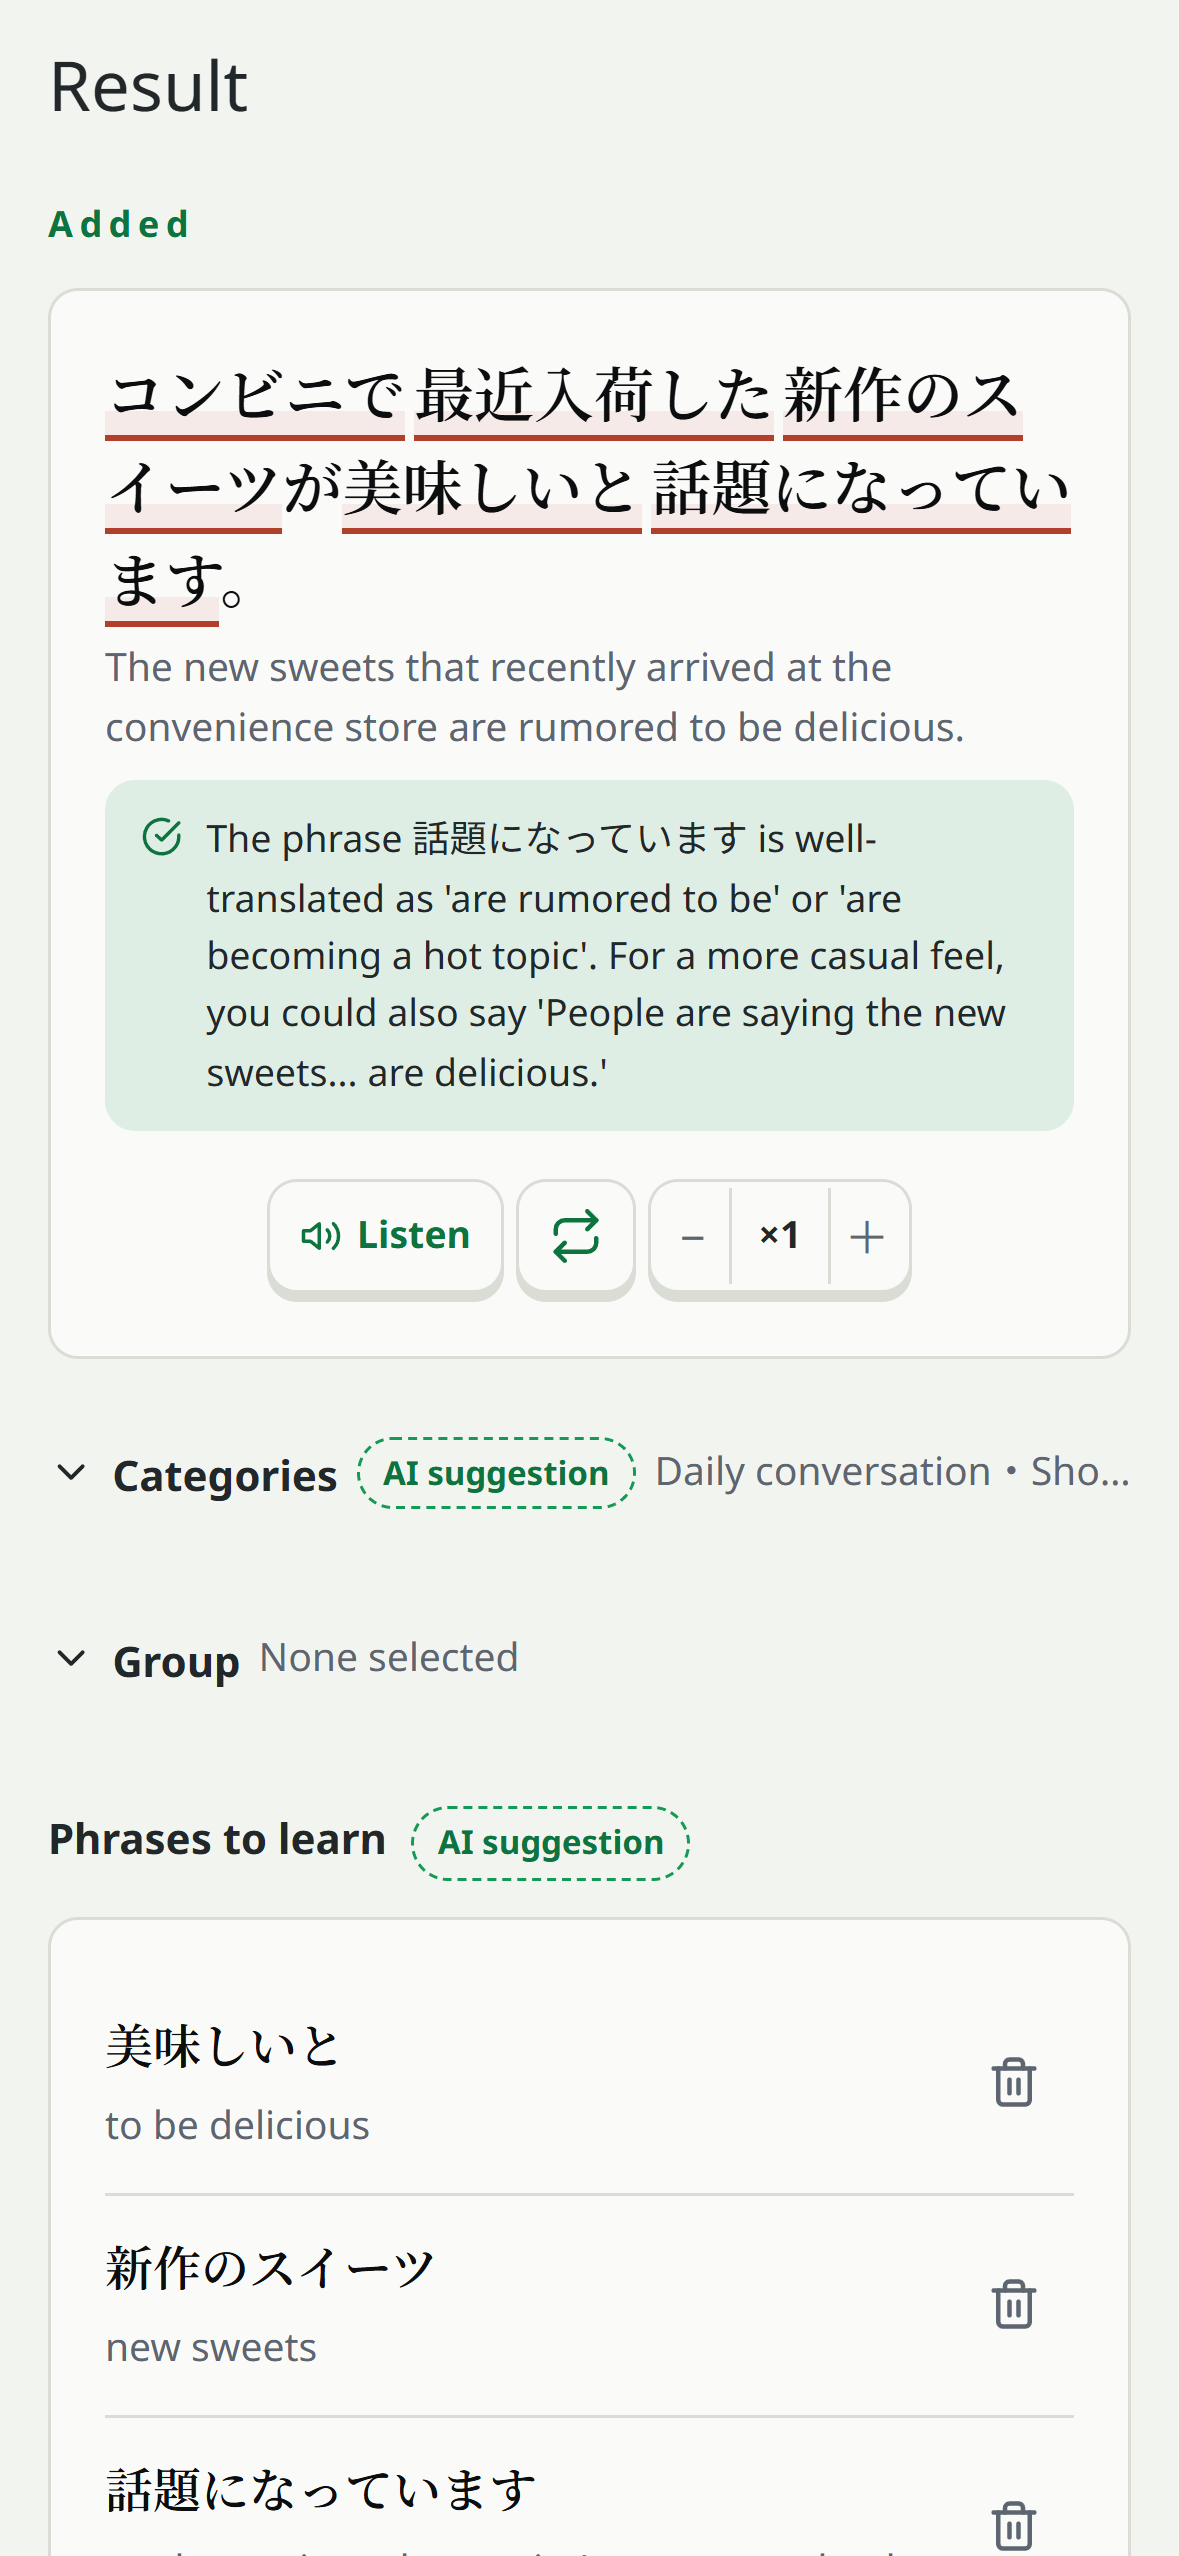
AI turns one pasted line into a natural sentence and reusable chunks
-
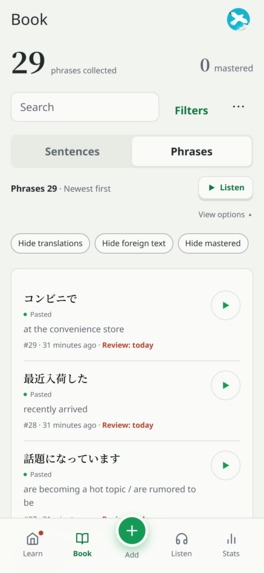
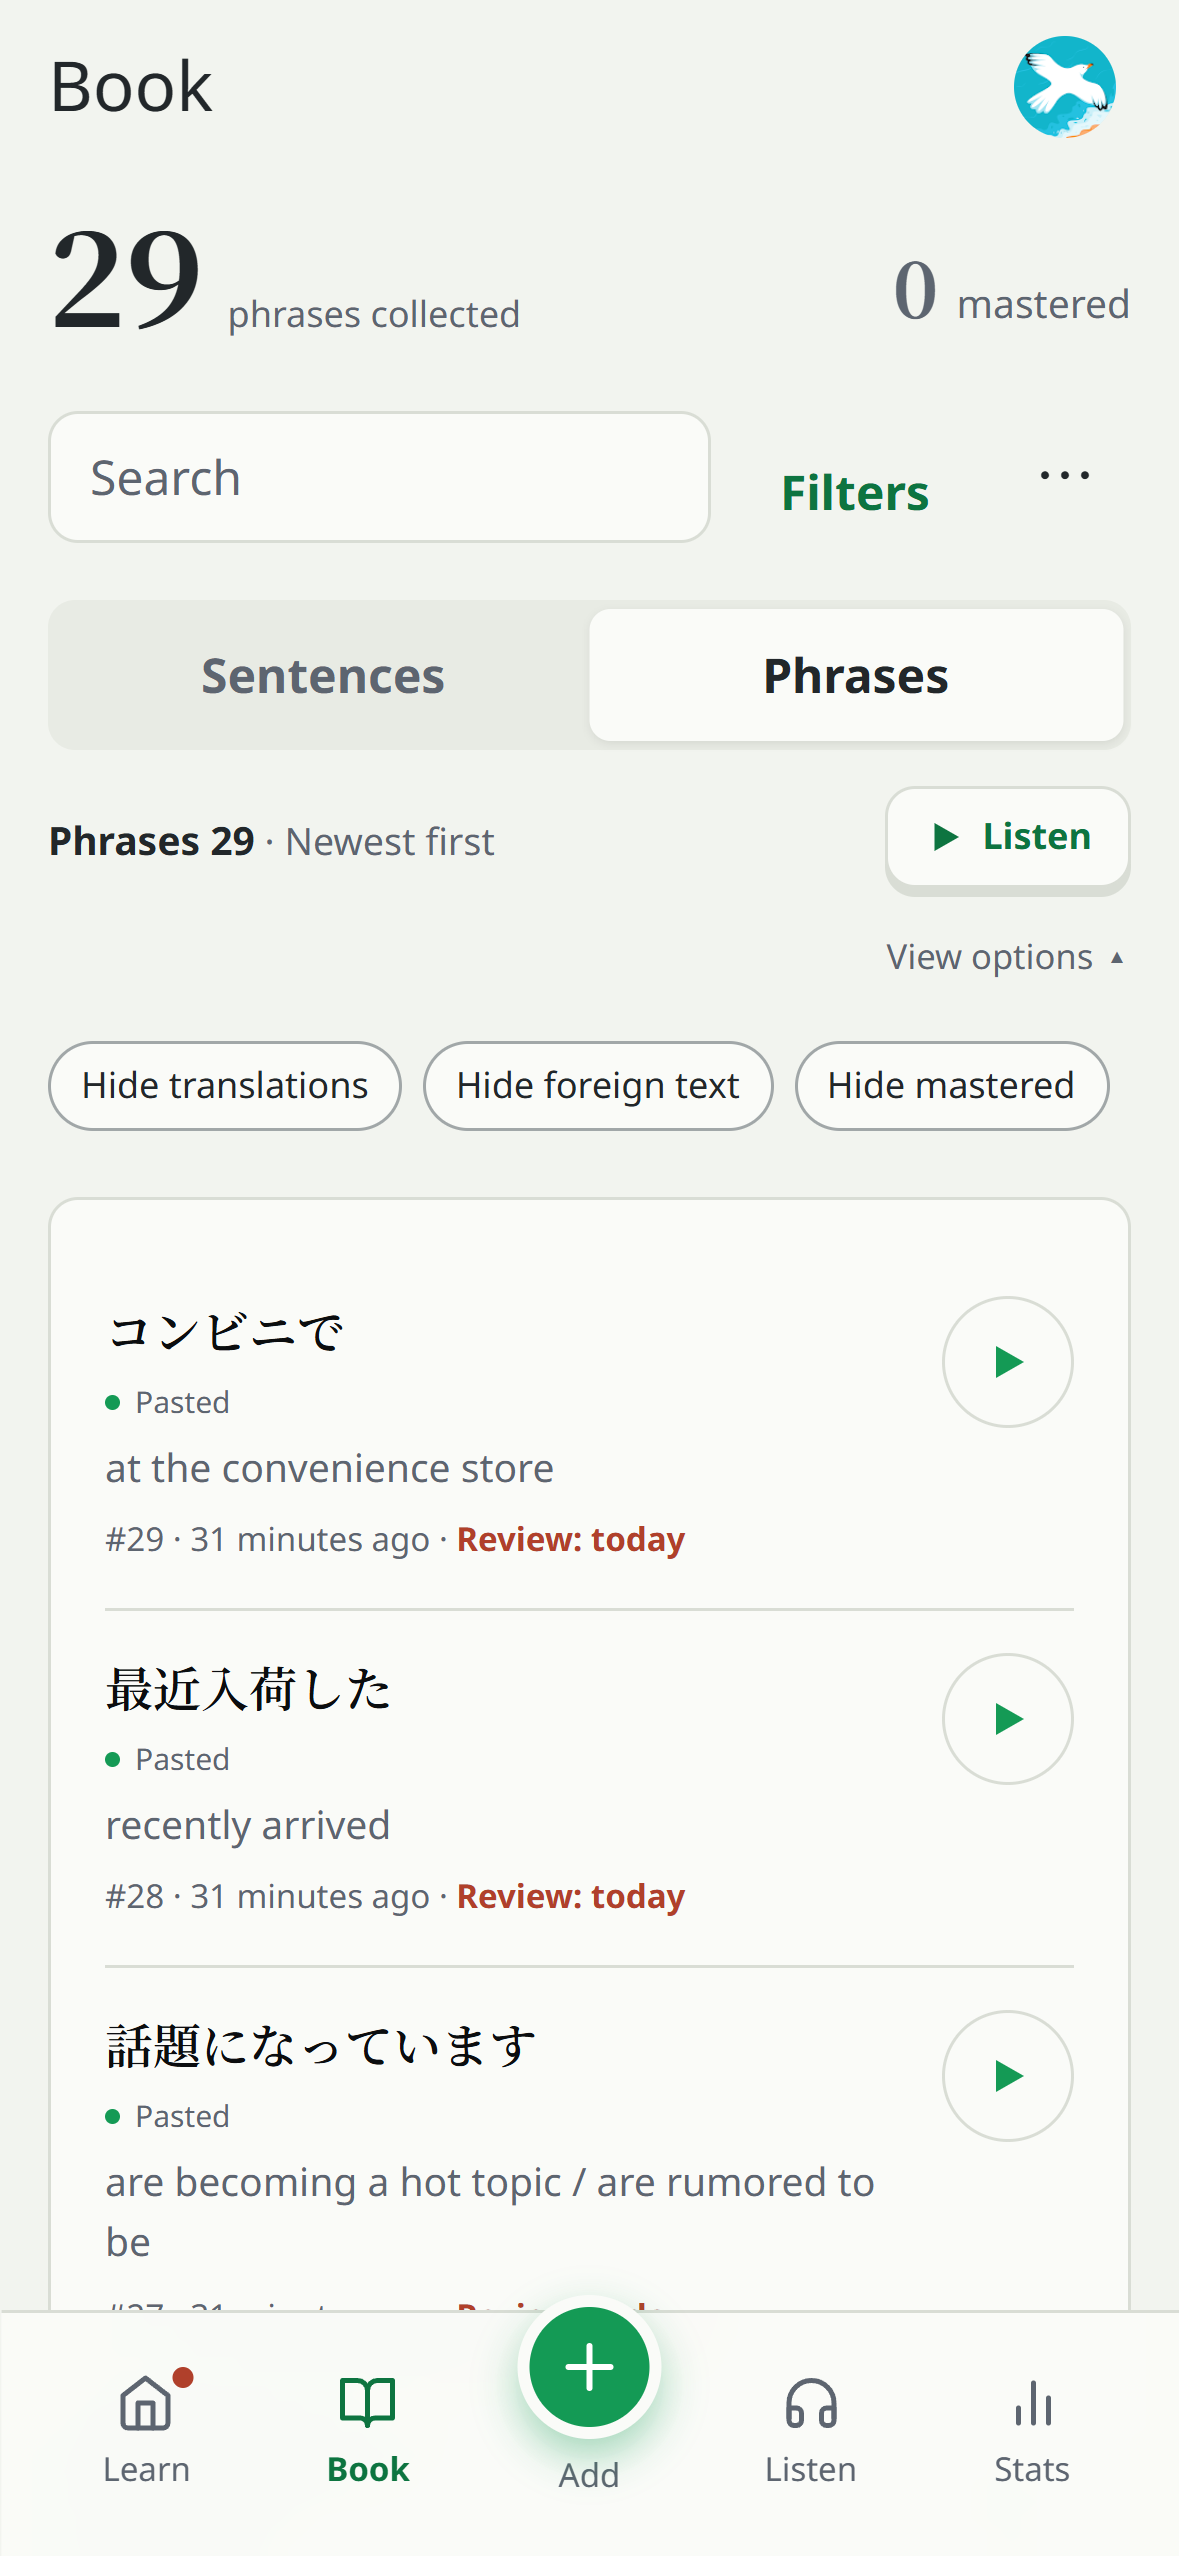
Every saved phrase lands in one book with its own review date
-
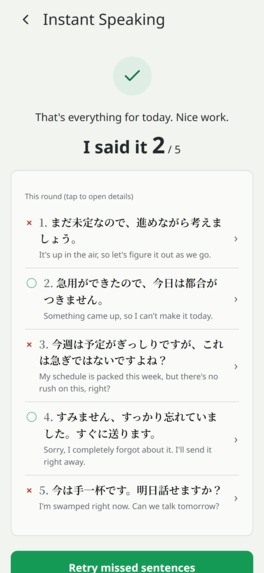
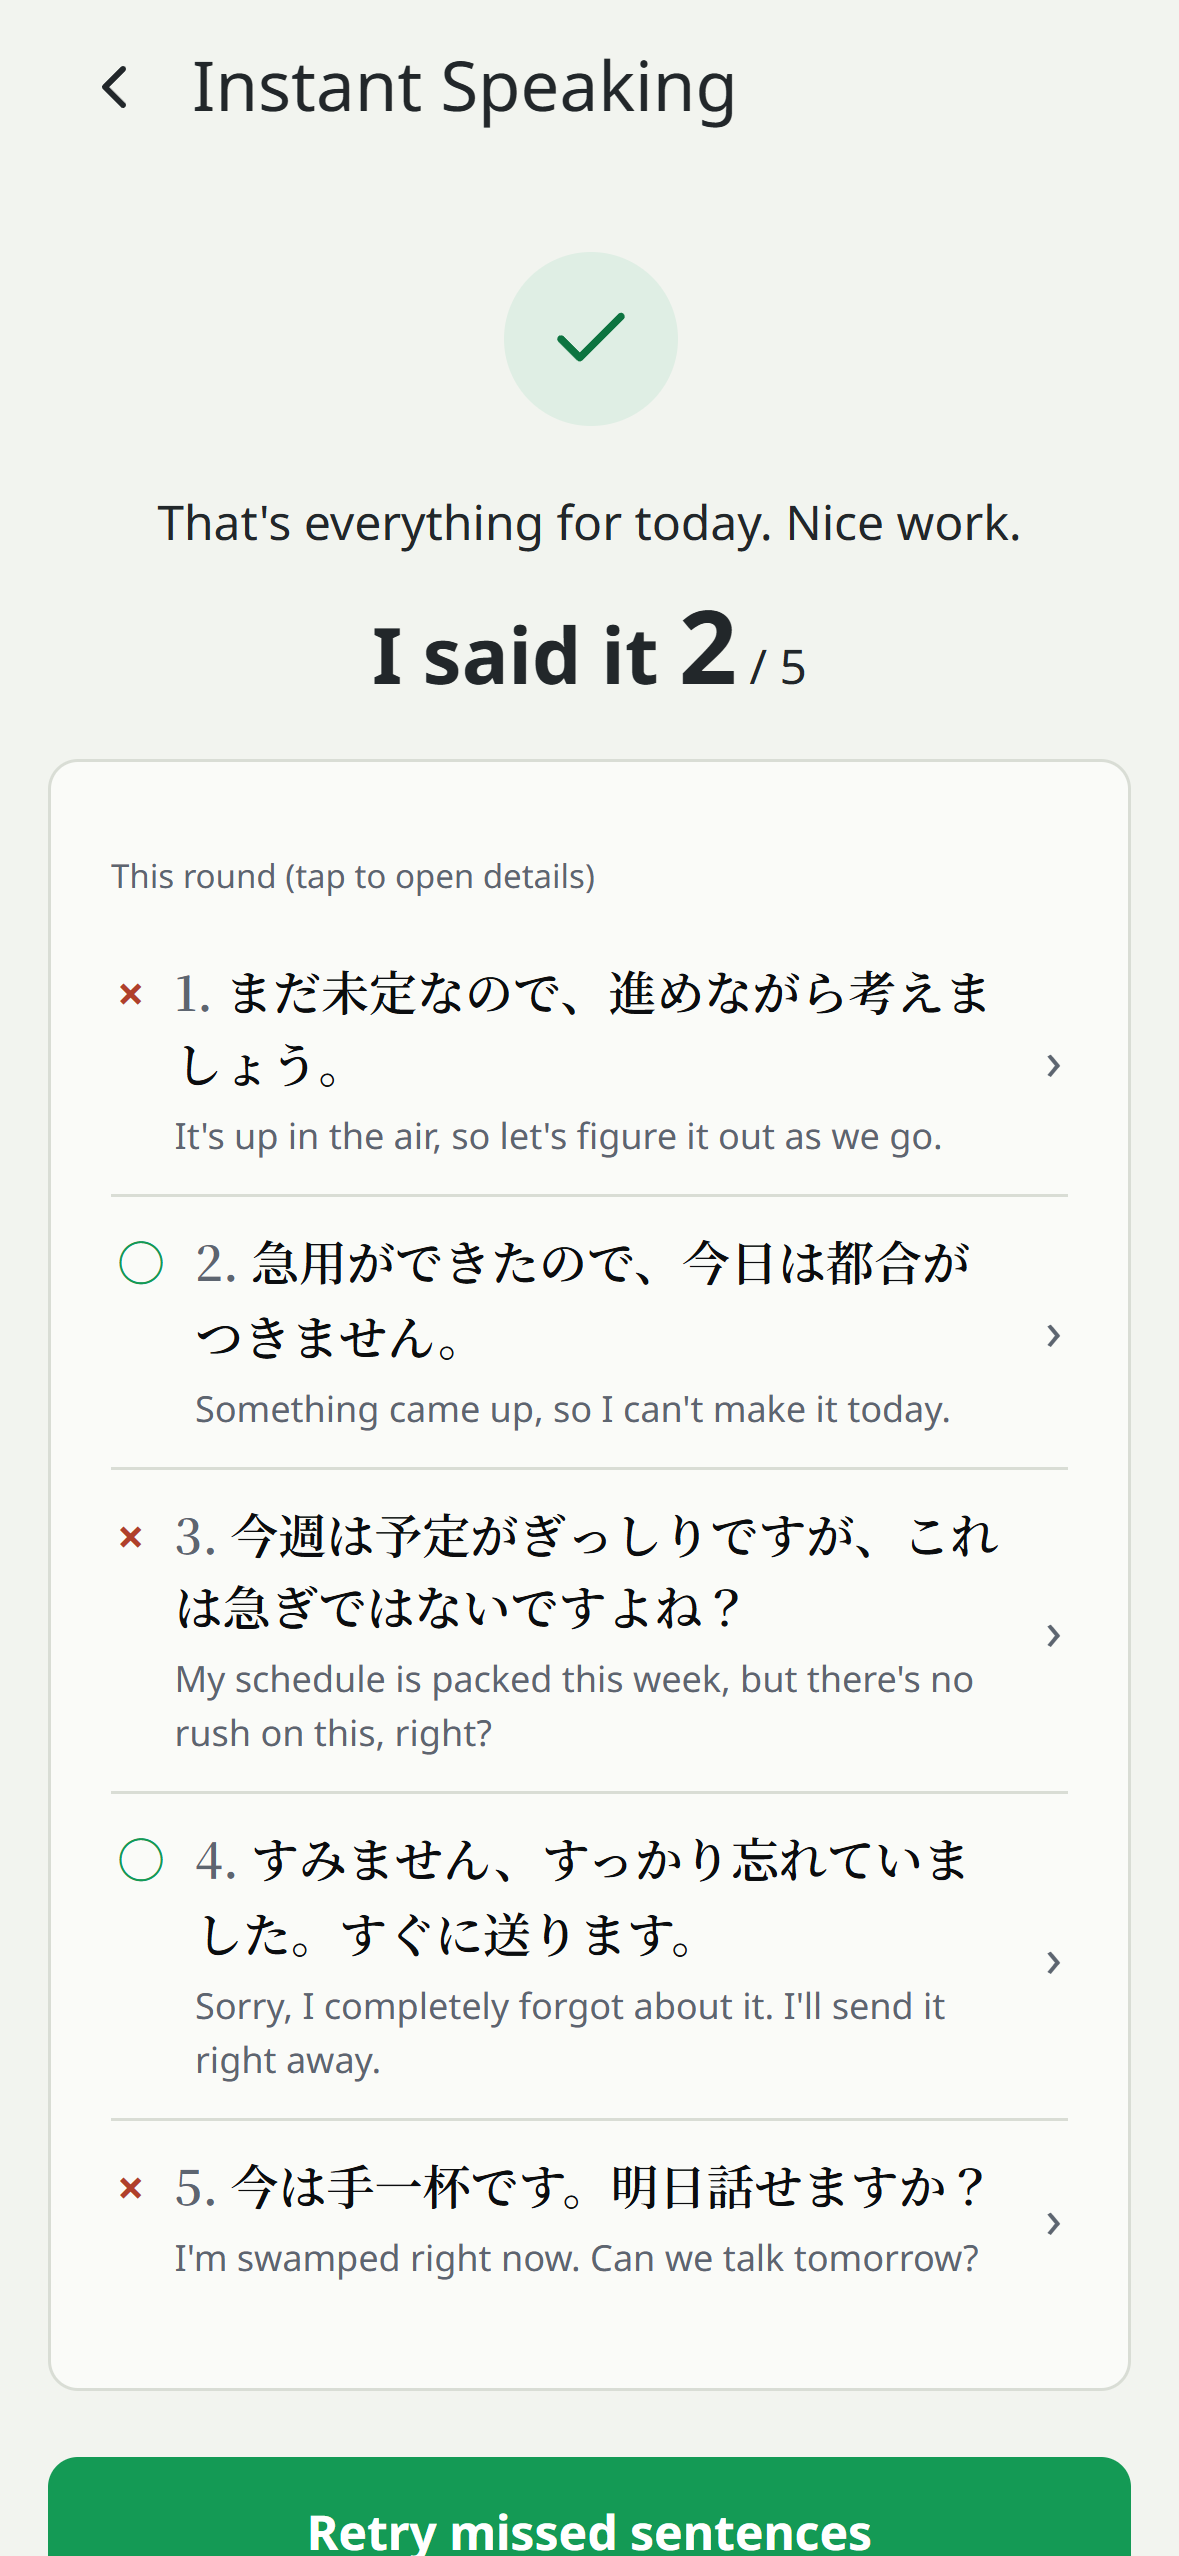
Speak on the clock then retry only the sentences you missed
-
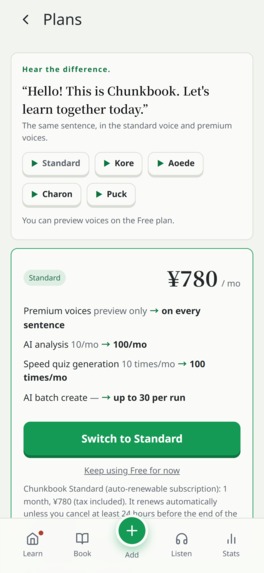
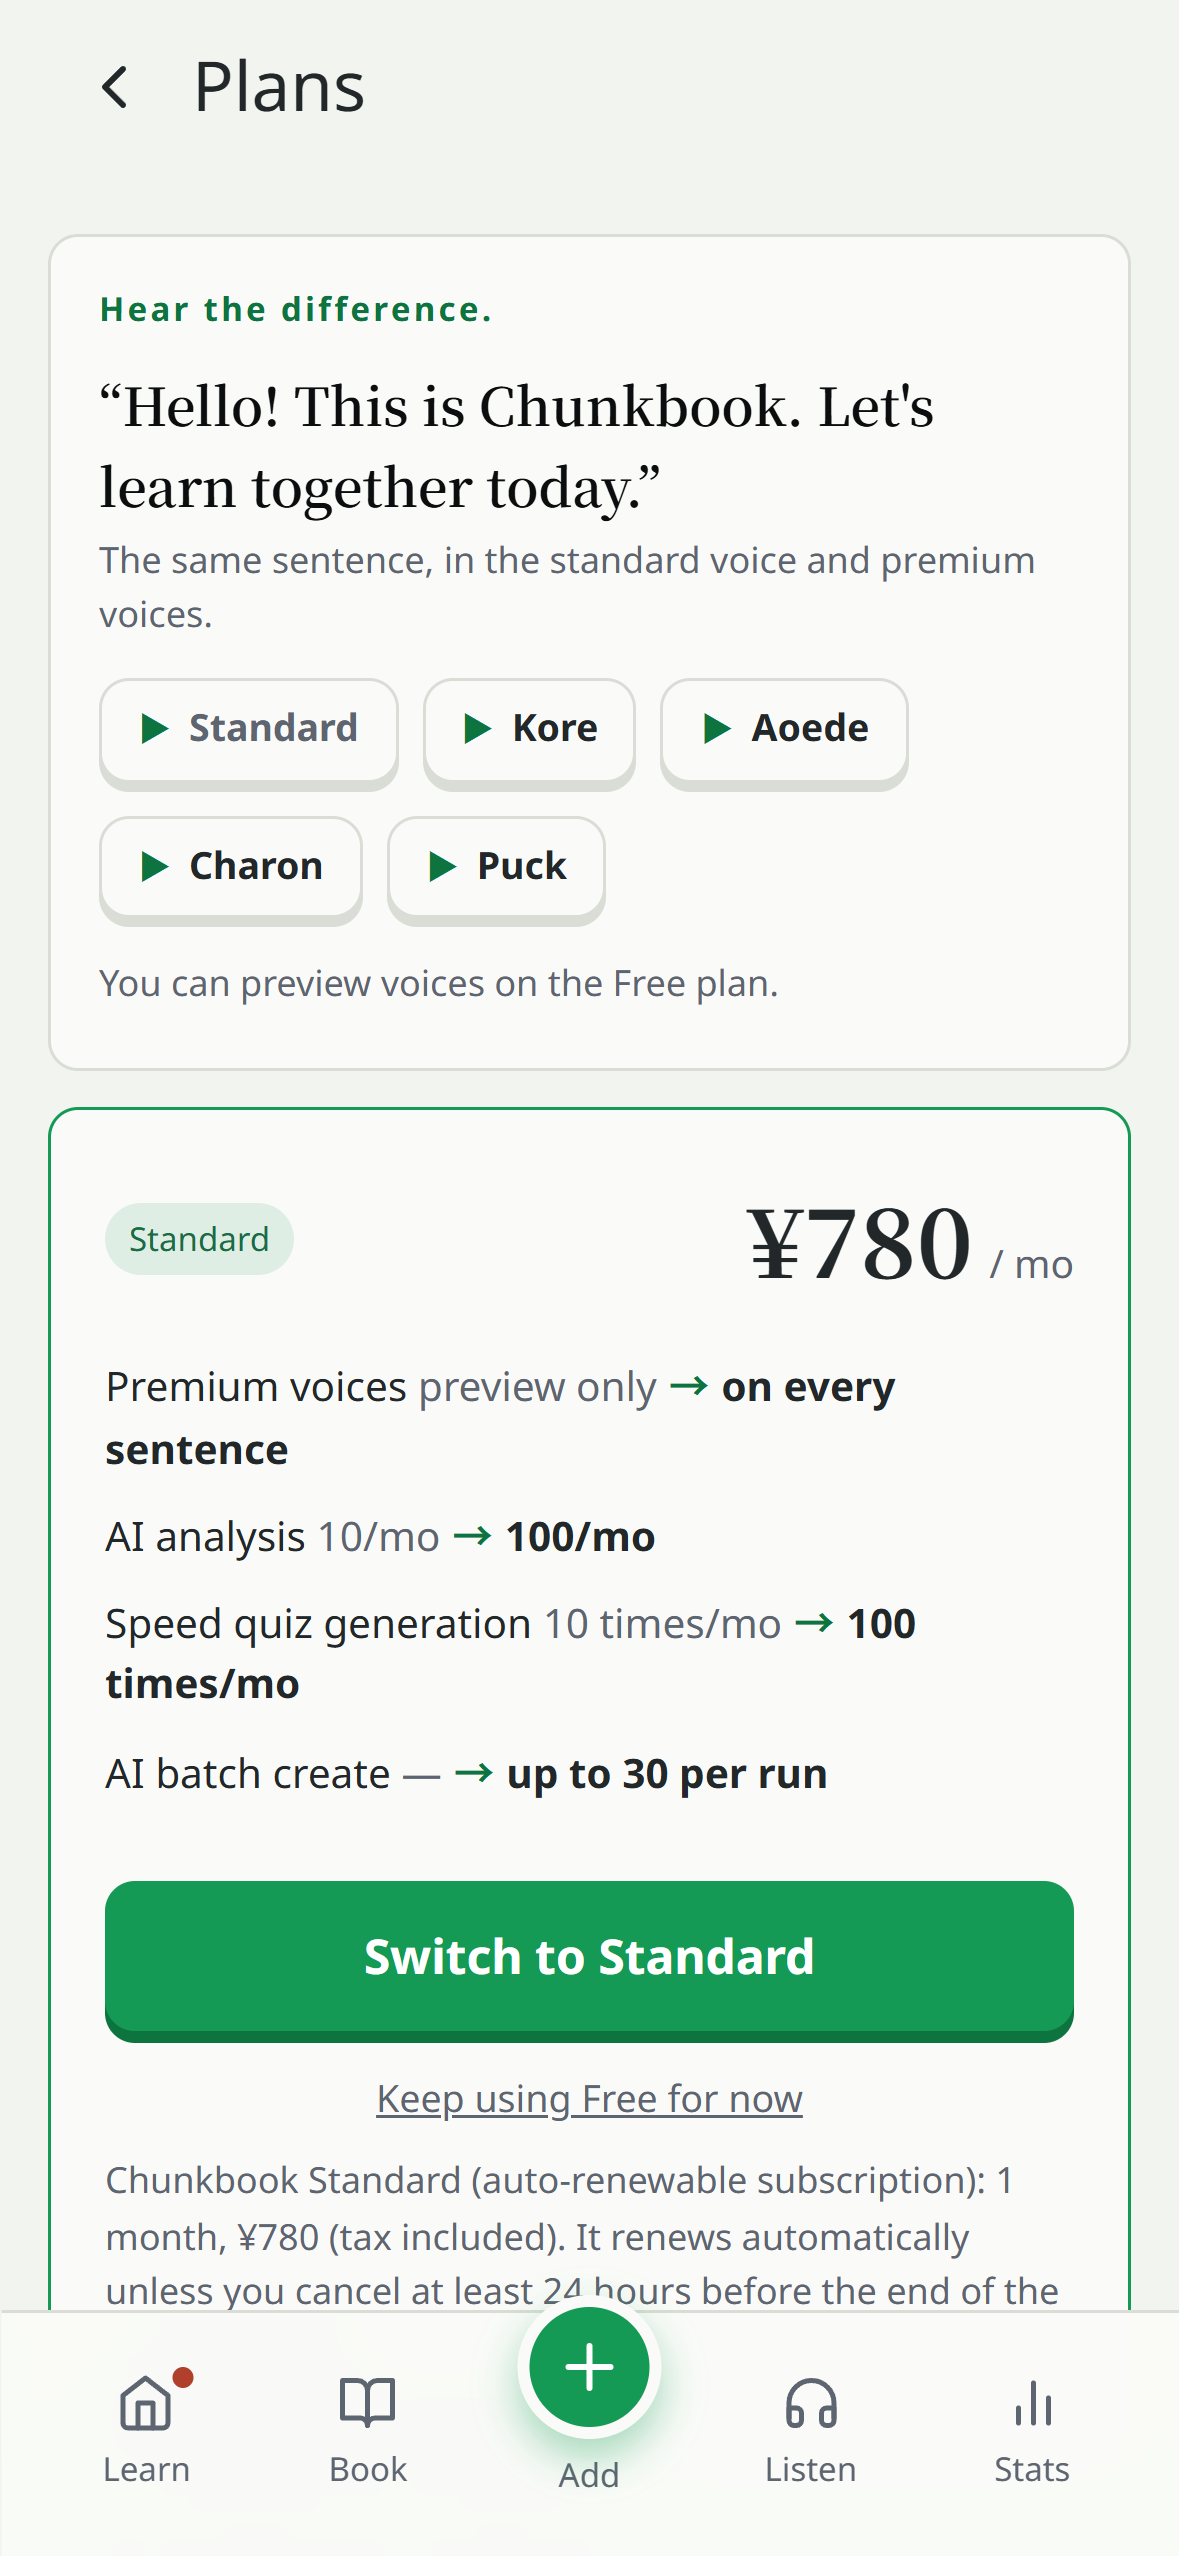
Standard unlocks premium voices and 10x AI for 780 yen a month
Inspiration
I keep hitting the same wall in English. In a meeting I know exactly what I want to say, fail to say it, and then lose that sentence forever. The sentence I actually needed was never in a textbook - it was the one I had just failed to produce. Chunkbook exists to catch that moment.
What it does
Chunkbook is an AI language notebook for the sentences you couldn't say.
- Capture - paste any text (an email, a subtitle line, a phrase you just fumbled) or speak it.
- Analyze - AI splits it into reusable chunks with translation, usage notes and audio.
- Practice - SM-2 spaced review, Instant Speaking (you have to say it before the answer appears) and listen-and-shadow playback.
- Score - a CEFR-style speaking score with written feedback.
It is for intermediate learners who read fine but freeze when they have to speak. 12 learning language pairs, UI in 4 languages, Anki .apkg / CSV import and export, three iOS widgets (phrase list, player, stats) and a Chrome extension.
How I built it
- Client: Capacitor 8 + Vite + React, shipped as a native iOS app.
- Backend: Hono + Drizzle + pg-boss on Render, Supabase for auth and Postgres, Cloudflare Pages for the web app, Sentry and PostHog for monitoring.
- Scoring: judgment runs on a non-generative model (TypeSafe AI's Jev), the arithmetic runs in code, and an LLM only writes the human-facing feedback.
- Monetization: the RevenueCat Capacitor SDK drives the whole native purchase path - configure, logIn with the Supabase user id, getOfferings, purchasePackage. Entitlements come back through a RevenueCat webhook that flips the account to STANDARD, and every event is persisted so replays stay idempotent. The web build bills through Stripe, but every Stripe subscription is registered back into RevenueCat, so plan state has a single source of truth across both surfaces.
Solo developer, pnpm monorepo.
How it makes money
- Free: 10 AI analyses / 10 speed-quiz generations / 30 AI checks per month. Manual entries and review quizzes are unlimited.
- Standard: 780 JPY (about $5) per month - 100 / 100 / 300.
- Every new account gets a one-time bonus of 20 / 20 / 60 for 60 days, so the paywall appears at the moment the learner has proven the habit and run out of quota, not on first launch.
Challenges I ran into
- LLM-as-a-judge was unusable. The same answer scored differently between runs, so a learner could not tell progress from noise. I replaced the judge mid-Shipaton, in production.
- Two App Review rejections, diagnosed and resolved without breaking the release train.
- Keeping AI cost low enough that the free tier could stay generous.
Accomplishments that I'm proud of
- Score standard deviation 0.01 out of 5.0 across 300 scorings (30 answers x 10 runs), median latency 249 ms, and cost per 1,000 scorings down from $0.16 to $0.045.
- Four App Store submissions in 12 days, solo: 1.0, 1.0.1, 1.0.2 including the full scoring-engine swap, and 1.0.3 submitted on day 12.
- Privacy by design: the scoring table stores cefr_scores.answer_chars, a character count. There is no column for the answer text.
What I learned
Writing the engineering decisions up in public forced me to measure instead of guess. The 300-scoring stability test exists because I needed real evidence for a blog post, and that number ended up being the product's strongest selling point.
What's next for Chunkbook
- Keep publishing the engineering decisions on dev.to and Qiita. It is the only acquisition channel I have actually run, and it is what forced the 300-scoring stability test into existence.
- Android build is in closed testing, plus more language pairs and shared decks.
Categories I'm targeting
- RevenueCat Design Award - a paper-metaphor UI where motion only ever explains state.
- RevenueCat Peace Prize - turning the shame of "I couldn't say it" into study material, with an East-Asian-first set of language pairs and a free tier that stands on its own.
- HAMM Award - a quota-based monetization model where the paywall is a consequence of real usage.
- RevenueCat Influencer Award (Productivity) - a tool for the sentence you failed to say, not another vocabulary drill.
- Grand Prize - honest post-launch numbers plus the velocity behind them.
Built With
- capacitor
- cloudflare-pages
- drizzle
- google-gemini
- hono
- ios
- openai
- pg-boss
- postgresql
- posthog
- react
- render
- revenuecat
- sentry
- stripe
- supabase
- typesafe-ai
- typescript
- vite

Log in or sign up for Devpost to join the conversation.