-
-
-
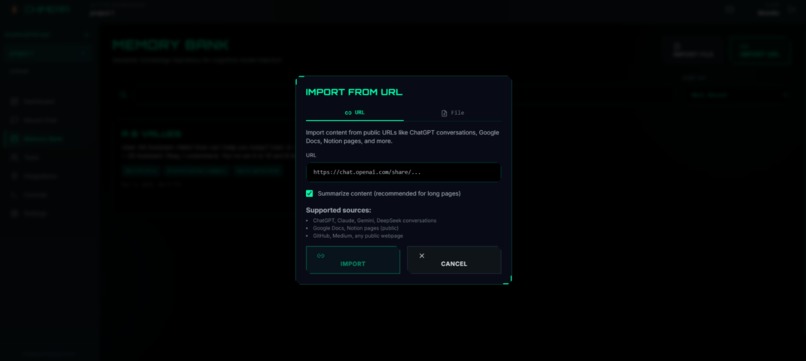
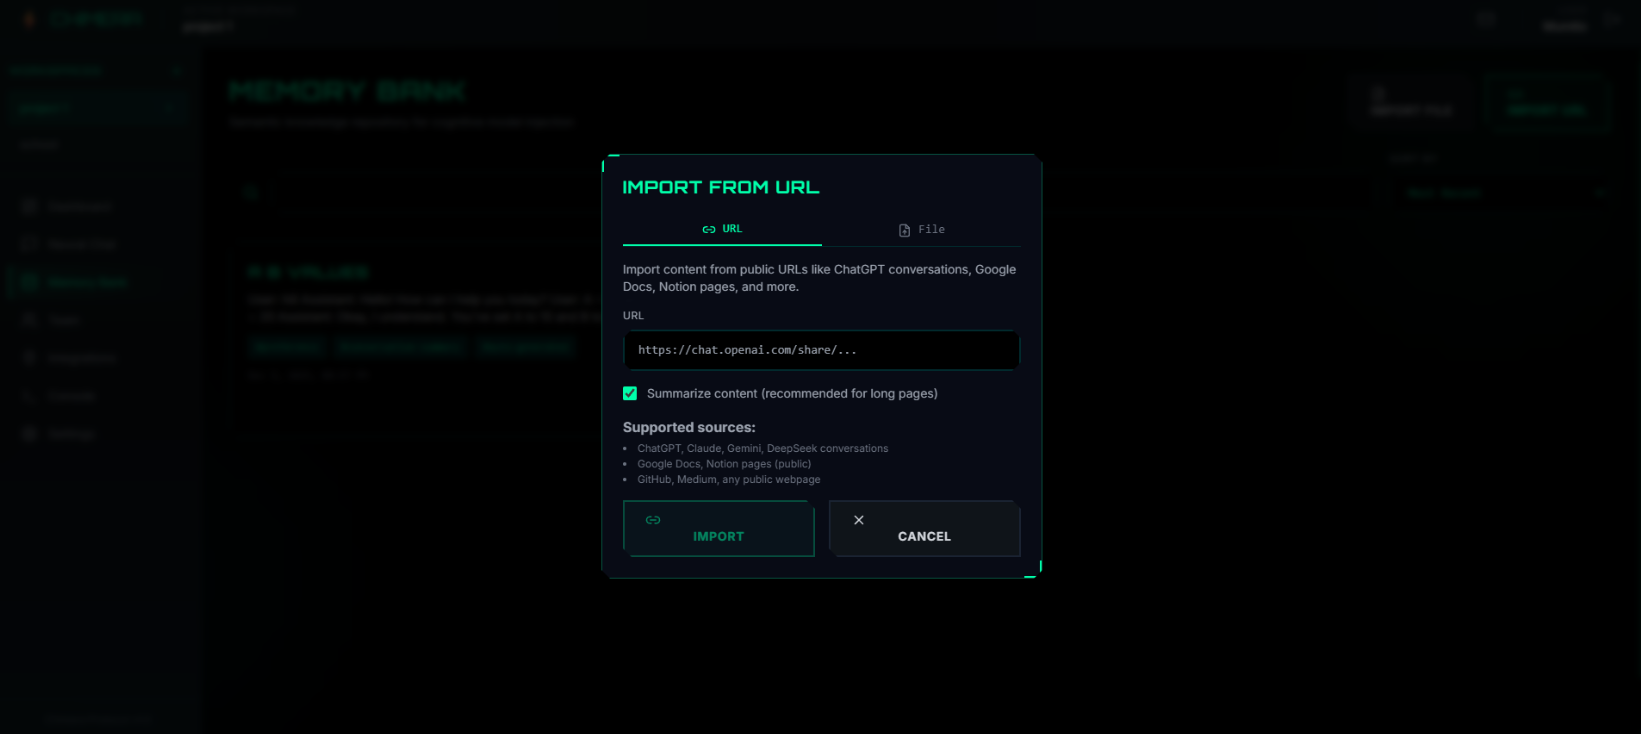
generate memory from any files/links
-
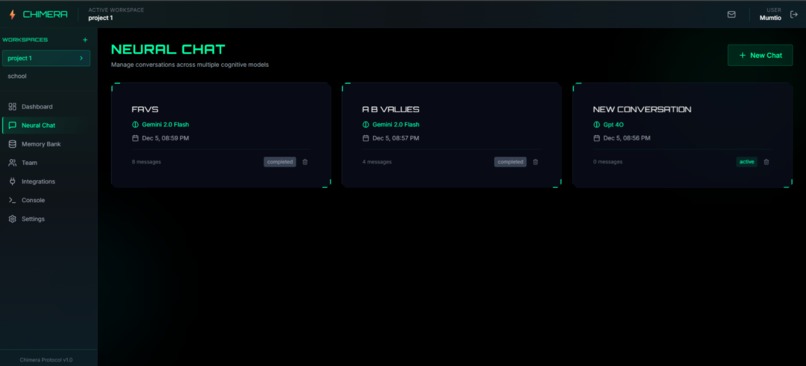
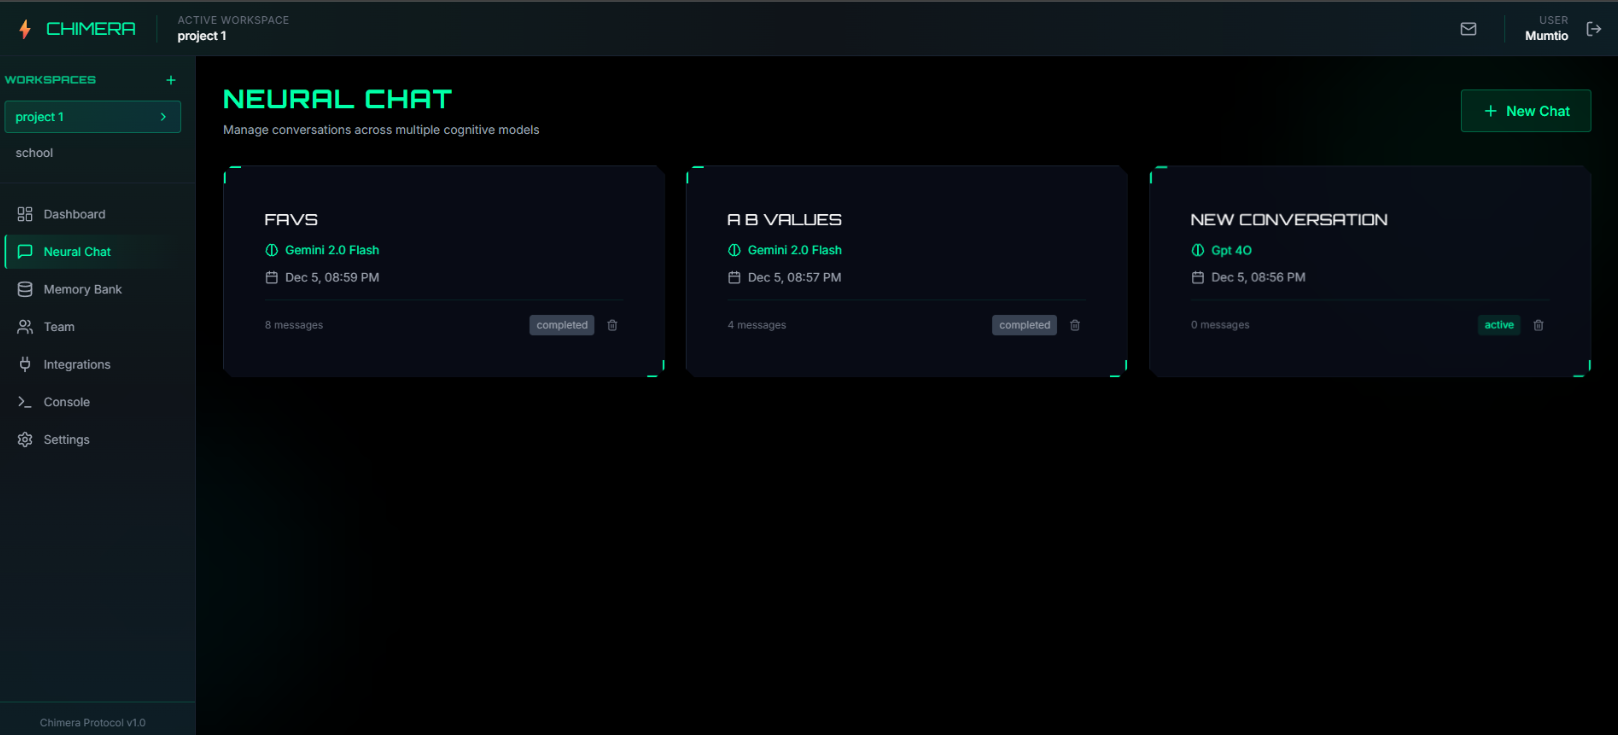
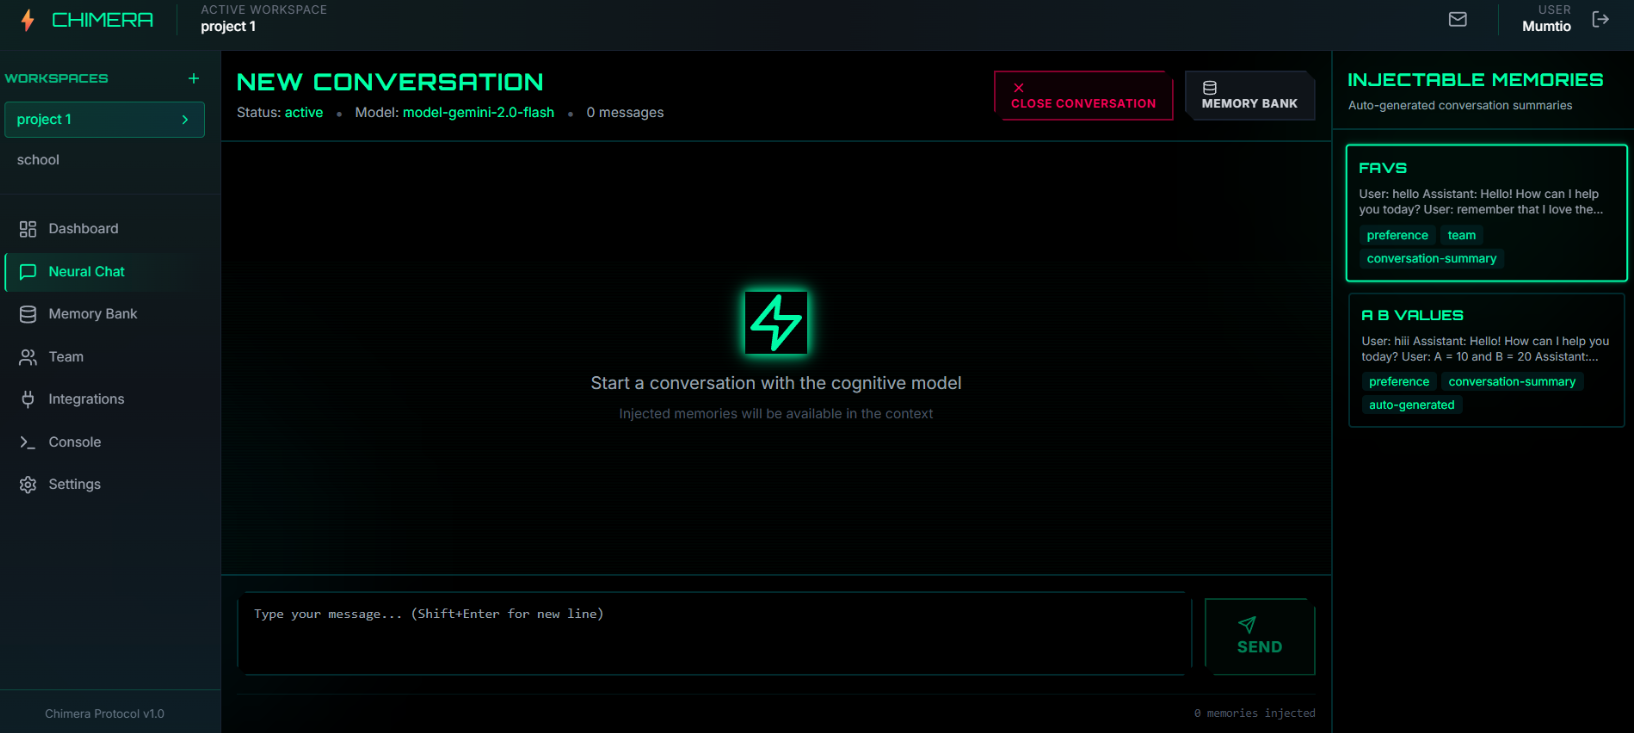
chatrooms
-
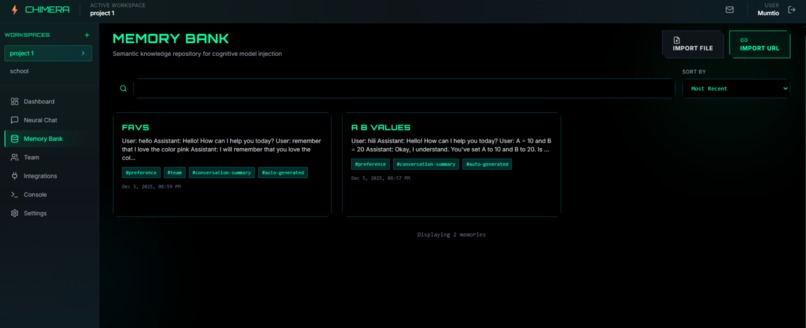
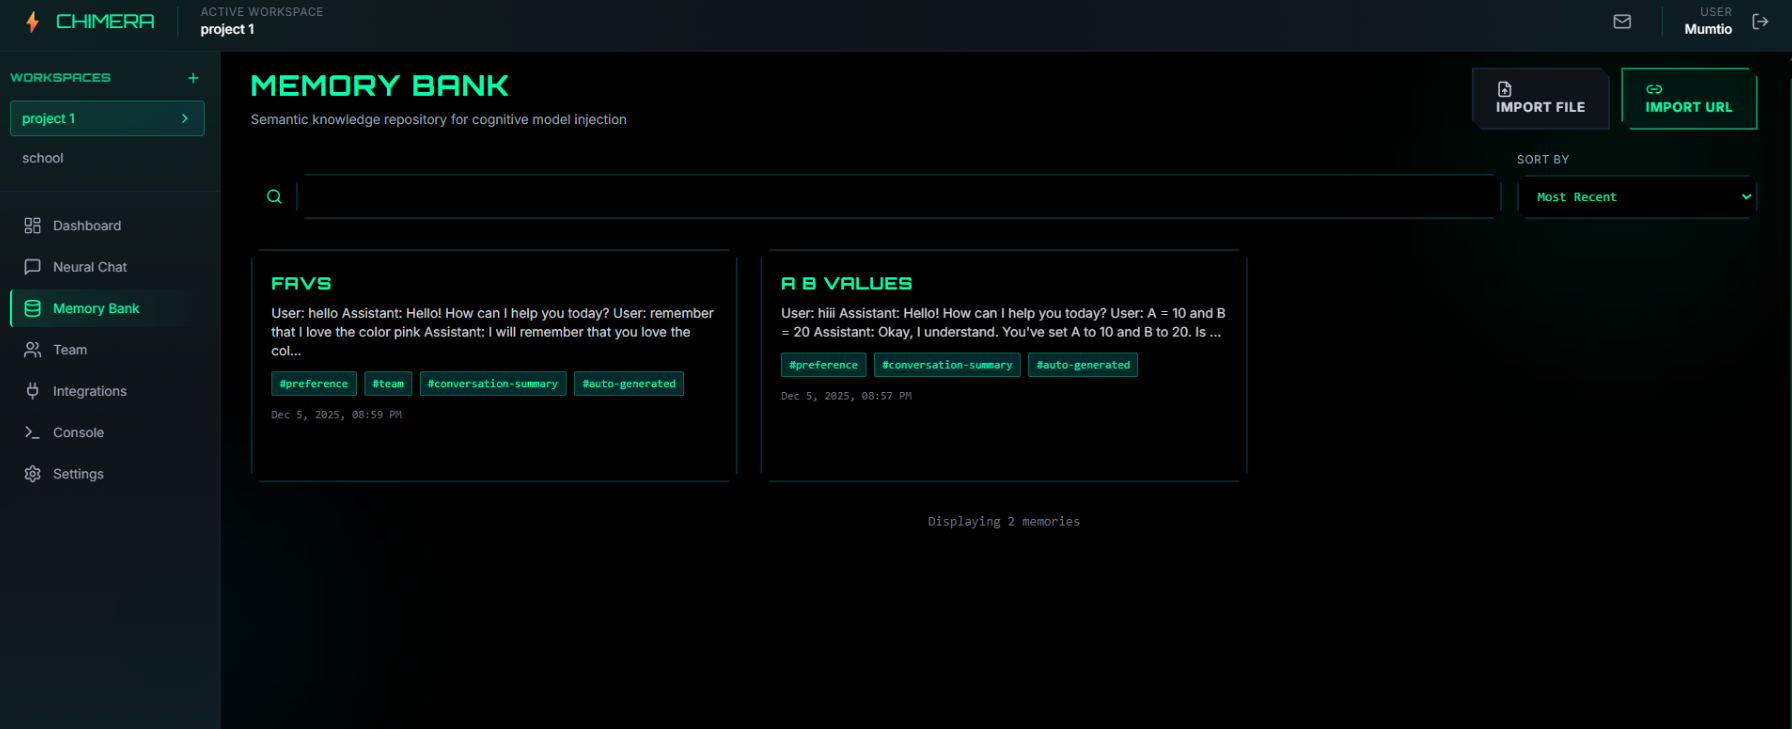
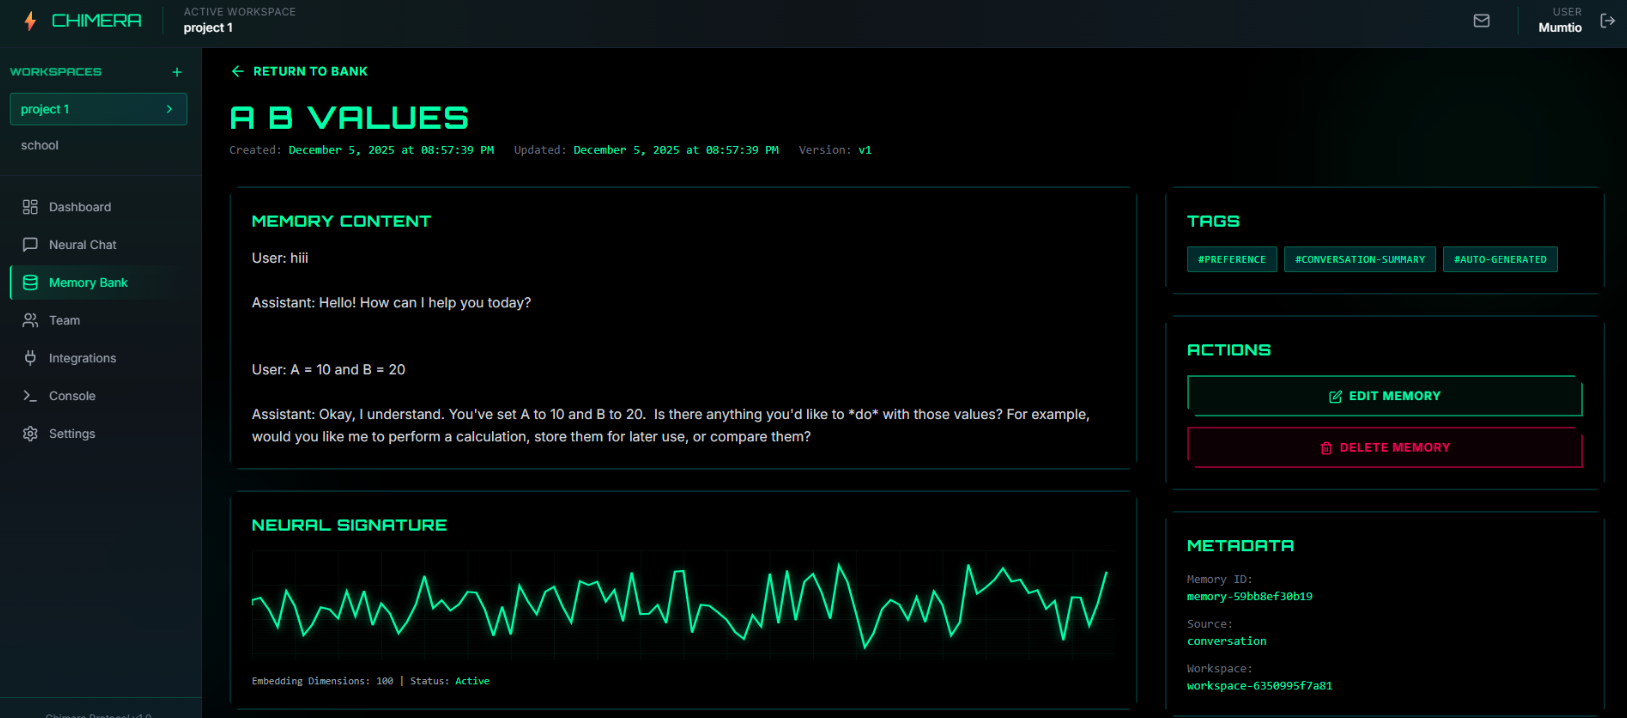
Memory bank
-
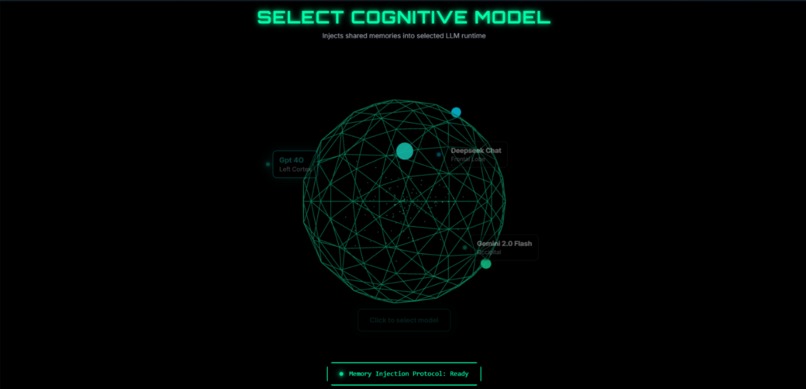
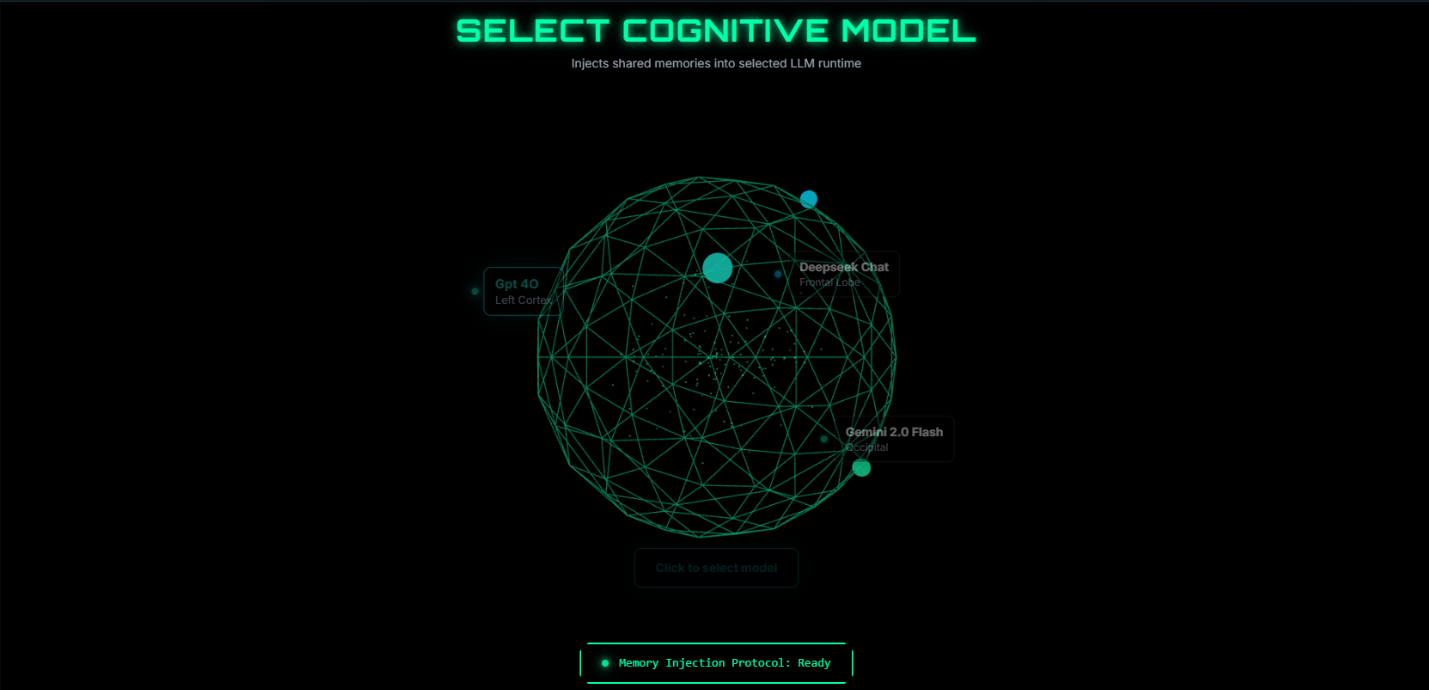
Selecting any AI model
-
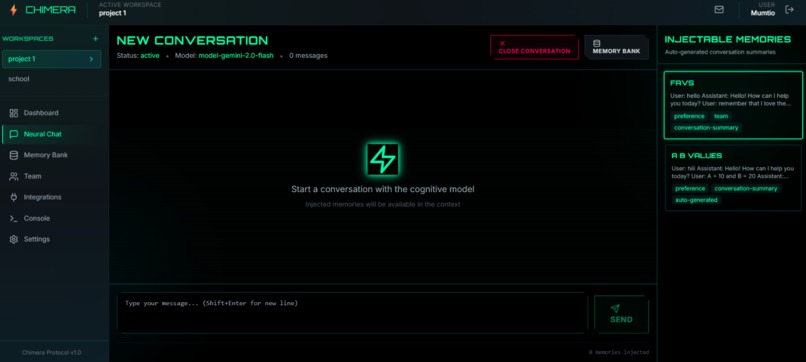
Chatting interface
-
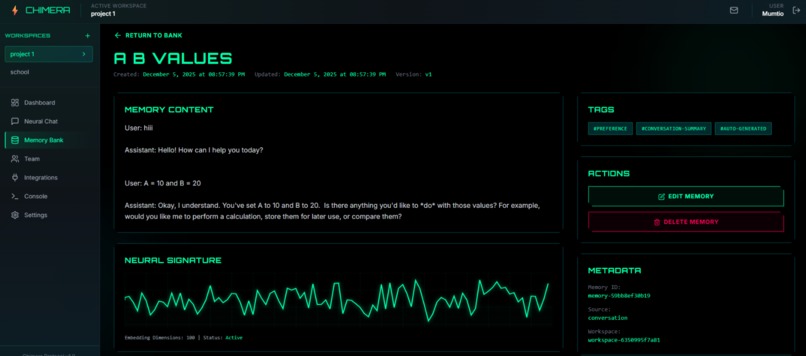
Memories stored in vectorized memory and can be edited
Chimera Protocol
🔐 Demo Access
Test Credentials:
- Email:
[email protected] - Password:
mumtiomumtio
Note: First login may take a moment while the server wakes up.
💡 Inspiration
In the current AI-powered development world, we frequently alternate between various LLMs: GPT for logical reasoning, Claude for programming tasks, Gemini for data analysis. However, each transition means beginning anew.
Fresh model. Fresh context. Broken continuity.
For teams developing AI-driven solutions, the challenge intensifies. Each team member's AI assistant functions independently, generating fragmented insights and redundant work. Context gets dispersed across isolated interactions.
We required a solution that could consolidate AI memory across models and teams.
That's the reason we created Chimera Protocol for Arctic League of Code: a universal memory infrastructure that connects fragmented AI interactions into one continuous, shared intelligence accessible by any LLM.
One memory. Multiple minds.
🧠 What It Does
Chimera Protocol is a universal memory infrastructure for AI-driven workflows.
Core Capabilities:
Multi-LLM Router: Effortlessly integrate OpenAI, Anthropic, Google, DeepSeek, and more through a unified interface


Persistent Memory System: Every interaction is vectorized and preserved. Context remains consistent across sessions and models.


Context Injection: Dynamically insert stored knowledge into any model, any interaction, at any moment

Universal Import: Generate persistent memories from PDFs, documents, webpages, or plain text

Team Workspaces: Collaborative spaces with role-based access management
Real-Time Collaboration: Multiple users operating simultaneously with live synchronization
Developer Console: MCP server for examining memory retrievals, prompt assembly, and routing logic
Full Data Export: Download comprehensive datasets as JSON: memories, conversations, embeddings, configurations
The outcome? Claude recalls what you discussed with GPT-4 yesterday. Your team's AI assistants share consolidated context instead of functioning in isolation.
🛠️ How We Built It
Chimera Protocol was designed and developed during Arctic League of Code using contemporary full-stack technologies.
Frontend: React/TypeScript single-page application with a neural-inspired interface showcasing neon aesthetics and a 3D brain visualization constructed with Three.js, where AI models manifest as interconnected glowing nodes.
Backend: Django REST Framework managing JWT authentication, workspace administration, encrypted API key storage (Fernet), and intelligent multi-LLM routing.
The Core Innovation: Our memory injection mechanism stores knowledge fragments as vector embeddings and dynamically prepends them as context to any AI interaction. This straightforward yet powerful approach enables genuine cross-model memory sharing.
Technology Stack:
- Frontend: React, TypeScript, Three.js, TailwindCSS
- Backend: Django, Django REST Framework, PostgreSQL
- AI Integration: OpenAI, Anthropic, Google AI, DeepSeek APIs
- Vector Storage: Custom embedding pipeline
- Security: Fernet encryption, JWT authentication
- Real-time: WebSocket connections for live collaboration
System Architecture:
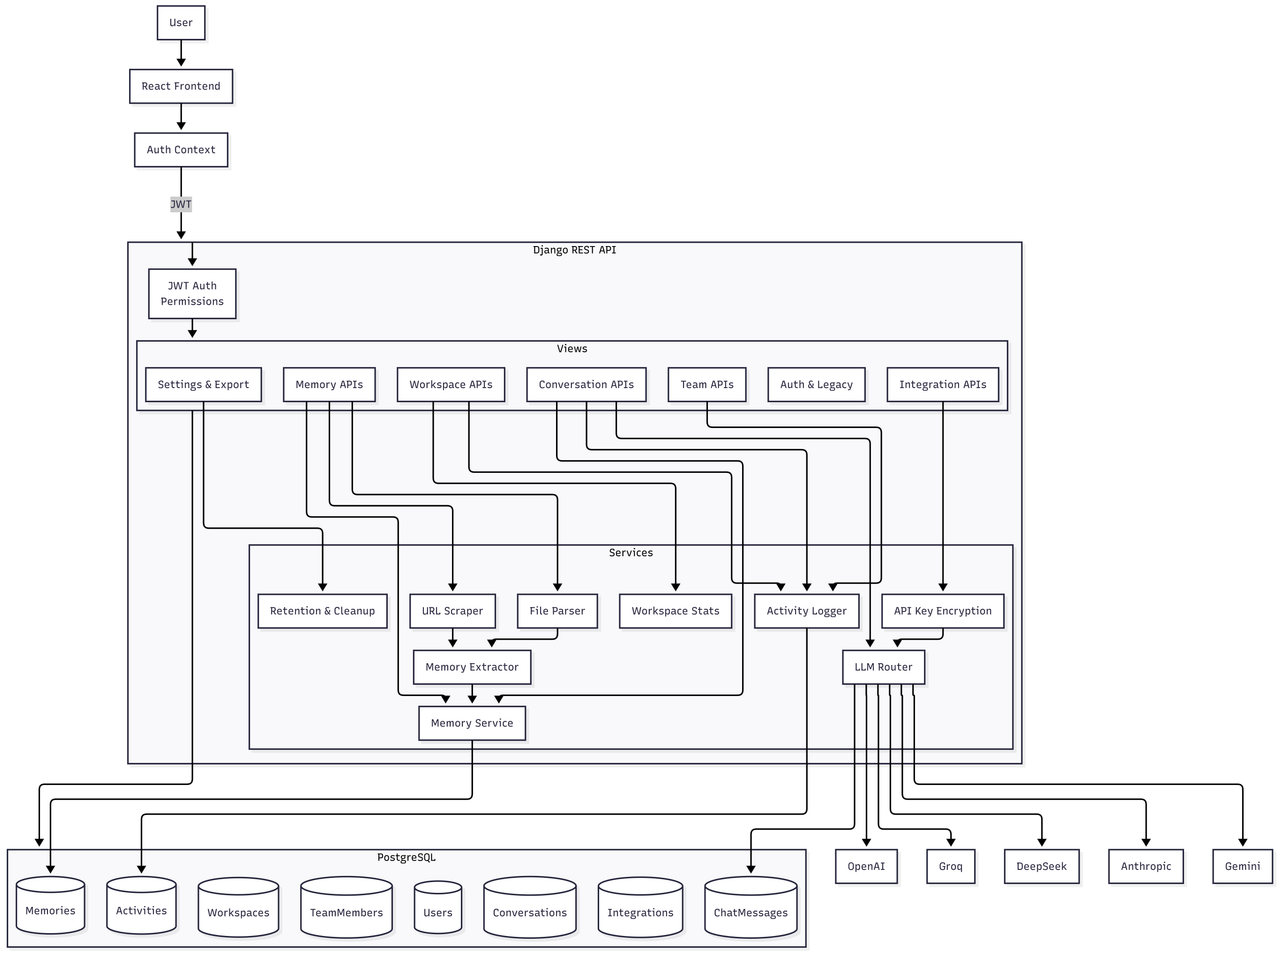
🚧 Challenges We Ran Into
Multi-LLM API Integration: Each AI provider (OpenAI, Anthropic, Google, DeepSeek) utilizes different authentication methods, request structures, and error management. Constructing a unified router that elegantly manages all variations demanded extensive iteration and resilient error handling.
3D Rendering Performance: Combining Three.js with React's state management introduced performance obstacles. Attaining smooth 60fps renders while preserving reactive state necessitated meticulous optimization using useMemo, useCallback, and appropriate WebGL resource disposal.
Chat Interface UX: Developing a production-grade chat interface exposed unexpected complexity: messages shifting during render, scroll positions resetting, auto-scroll malfunctioning at edge cases. Multiple iterations were essential to refine the flex layout and scroll behavior.
Security Architecture: Deploying secure API key storage (Fernet encryption) while retaining the capability to decrypt them for live API calls demanded balancing security best practices with usability needs.
🏆 Accomplishments We're Proud Of
True Cross-Model Memory: Successfully deployed memory injection that operates identically across GPT-4, Claude, Gemini, and DeepSeek. One shared context, multiple AI minds.
Immersive 3D Interface: Developed a model selection experience that resembles interfacing with an actual neural network: not merely a dropdown menu, but a visual representation of AI architecture.
Real-Time Team Collaboration: Constructed live synchronization enabling multiple users to collaborate in shared workspaces with instant updates. No manual refresh necessary.
Full-Stack Integration: Accomplished seamless frontend-backend communication with zero integration complications. Authentication, API routing, and state management operate flawlessly together.
Production-Ready Implementation: Every feature is completely functional with real API calls, persistent storage, and secure authentication. This is a deployable system, not a prototype.
Cohesive Design Language: The UI genuinely reflects the concept: a laboratory for connecting AI minds. Form perfectly matches function.
📚 What We Learned
Architecture Matters: Dedicating time to system design initially prevented significant refactoring later. Clear separation of concerns between routing, memory, and authentication layers yielded dividends.
API Abstraction is Critical: Constructing a unified interface over disparate AI APIs demanded thorough understanding of each provider's peculiarities. The abstraction layer became the most valuable component.
Performance Optimization is Iterative: 3D rendering performance necessitated multiple optimization passes. Profiling, measuring, and progressively improving was more effective than premature optimization.
Security Cannot Be Afterthought: Deploying encryption and authentication from the beginning was simpler than retrofitting it later. Security-first architecture streamlined development.
User Experience Details Matter: The distinction between a functional chat interface and a polished one came down to numerous small UX refinements: scroll behavior, loading states, error handling.
🔮 What's Next
RAG Integration: Deploy semantic search to automatically recommend relevant memories based on conversation context using advanced retrieval techniques.
Memory Graphs: Visualize connections between memories as an interactive knowledge graph, exposing patterns and relationships in stored knowledge.
Voice Interface: Integrate ElevenLabs for voice-based conversations with automatic memory injection and retrieval.
Mobile Application: Build React Native version for iOS and Android, enabling on-the-go memory management and AI conversations.
Fine-Tuning Pipeline: Utilize accumulated conversation history to fine-tune personalized models that comprehend user-specific context and preferences.
Enterprise Features: Incorporate audit logs, compliance controls, and advanced permission systems for organizational deployment.
Plugin Ecosystem: Establish an extensible architecture allowing third-party integrations and custom memory processors.
Chimera Protocol: Because your AI shouldn't forget every time you switch models.
Built for Arctic League of Code 2026
Built With
- django
- framer
- postgresql
- python
- react
- recharts
- tailwind
- typescript