-
-
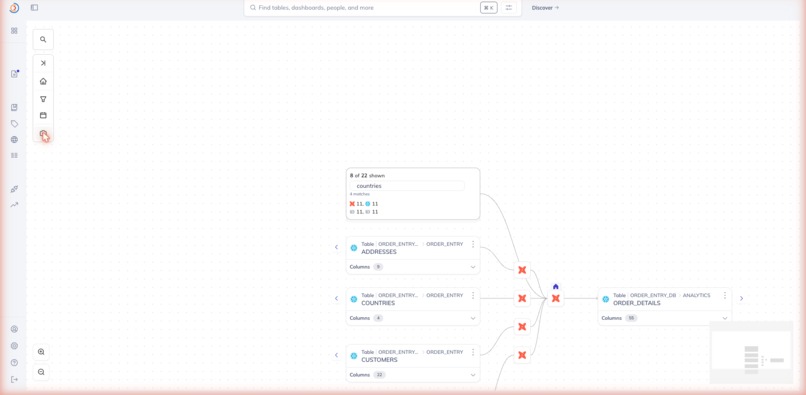
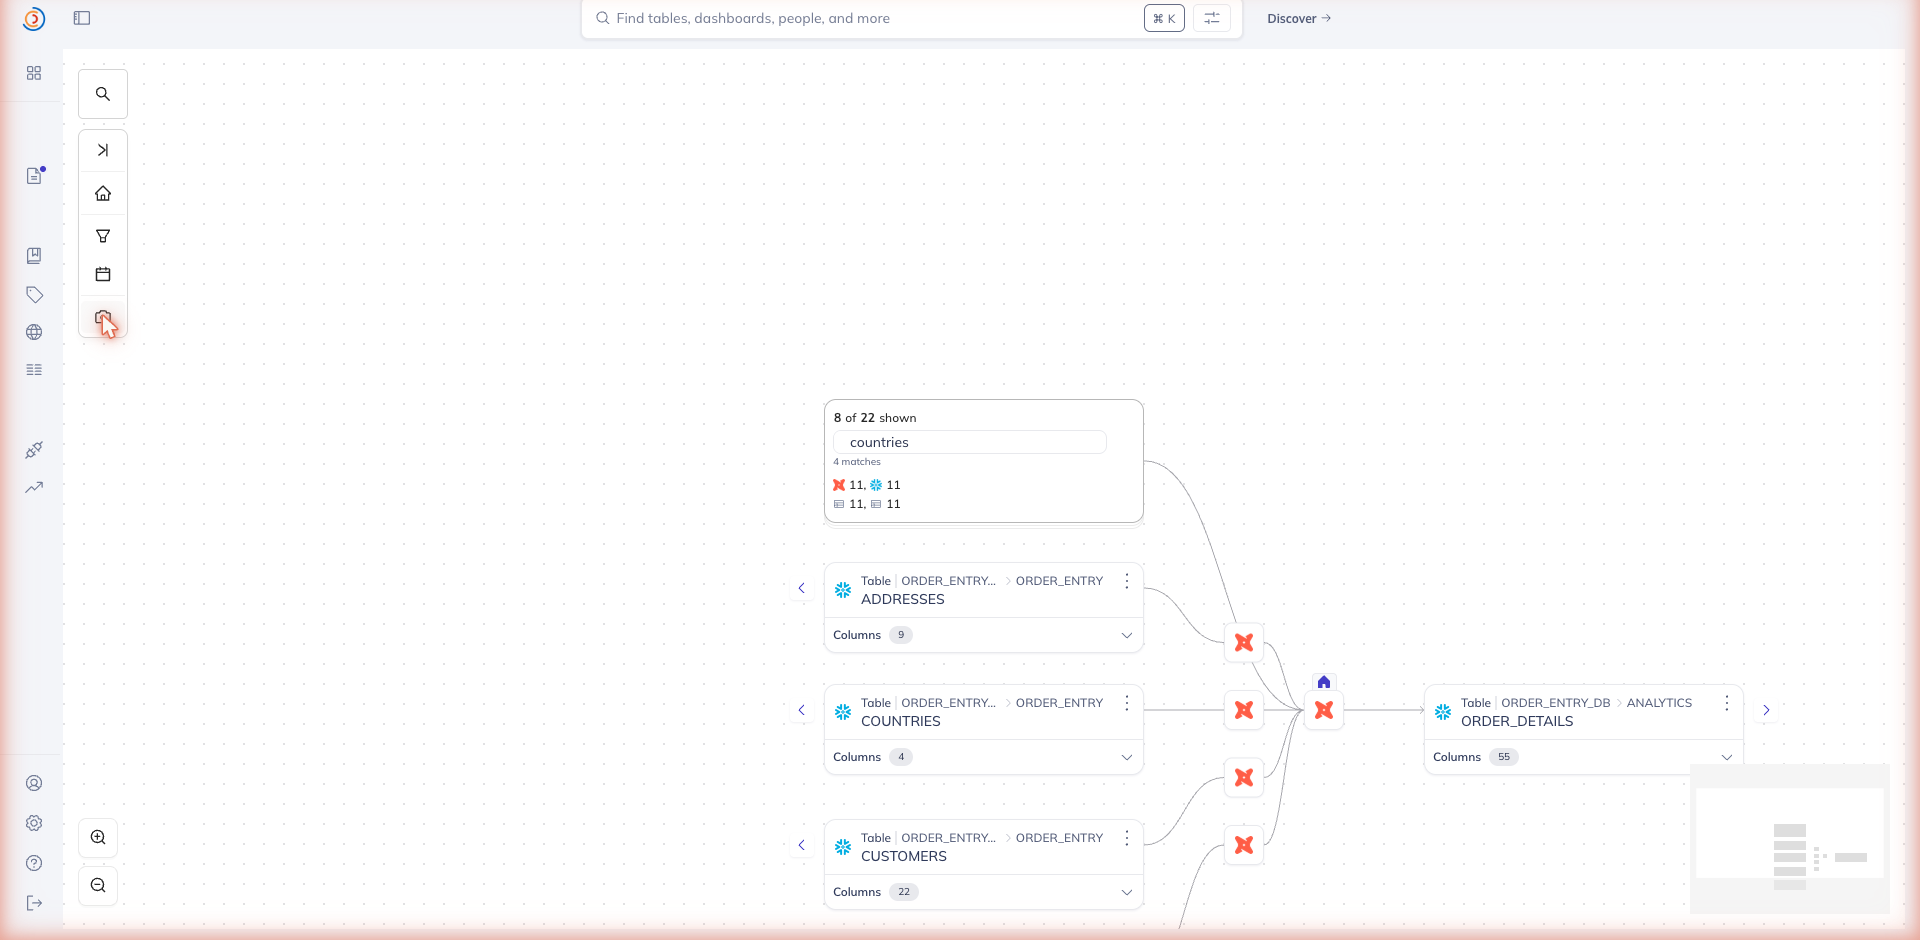
Real DataHub column-level lineage: countries → order_details — the hop CASCADE follows from the failing column to the root cause.
-
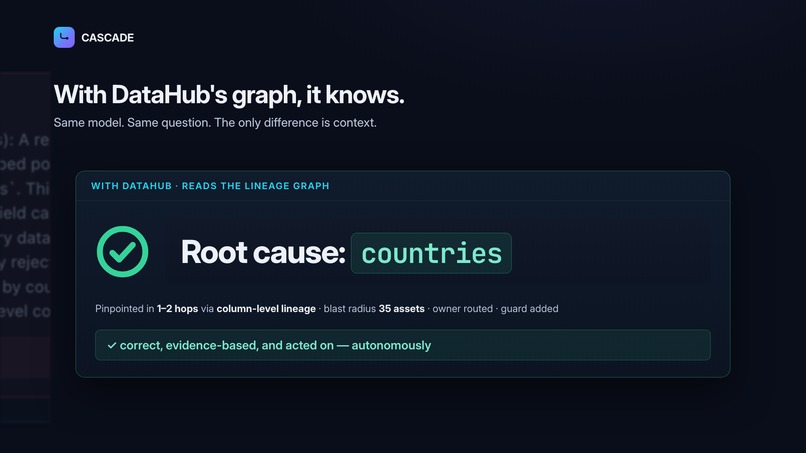
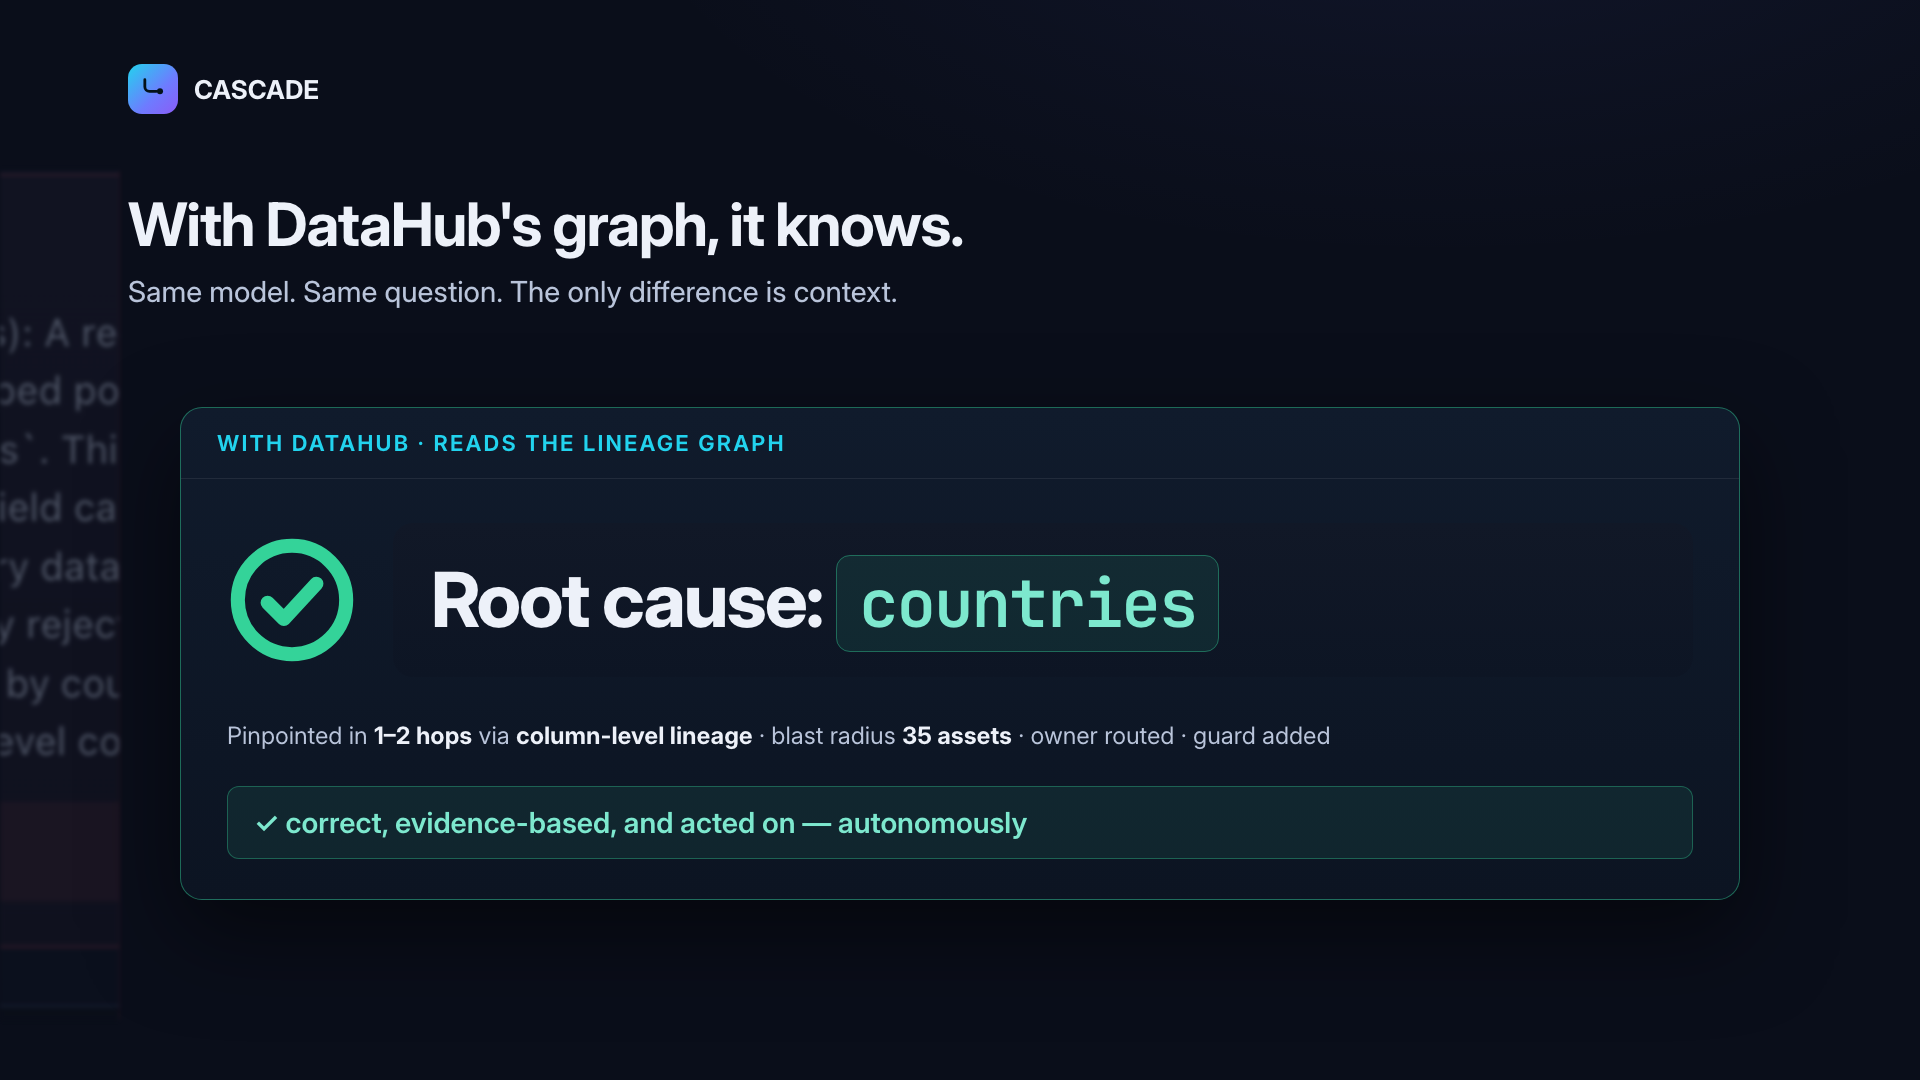
The A/B: same model, same question, with vs without DataHub's graph. With it, CASCADE names the root cause; without it, it guesses.
-
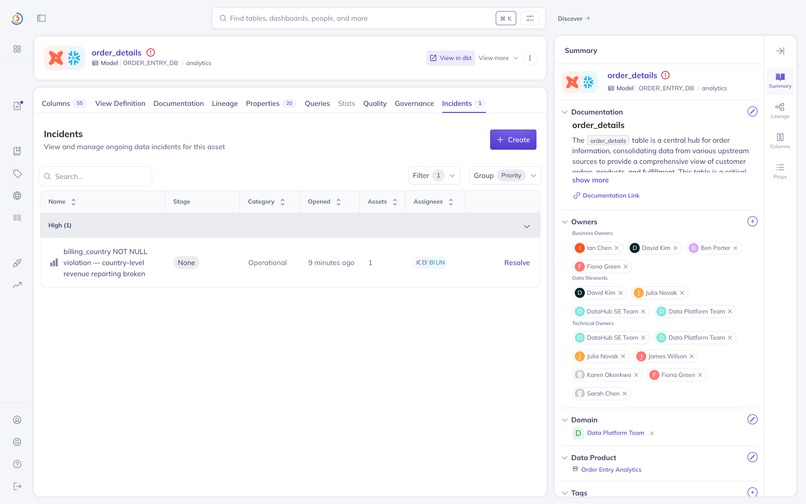
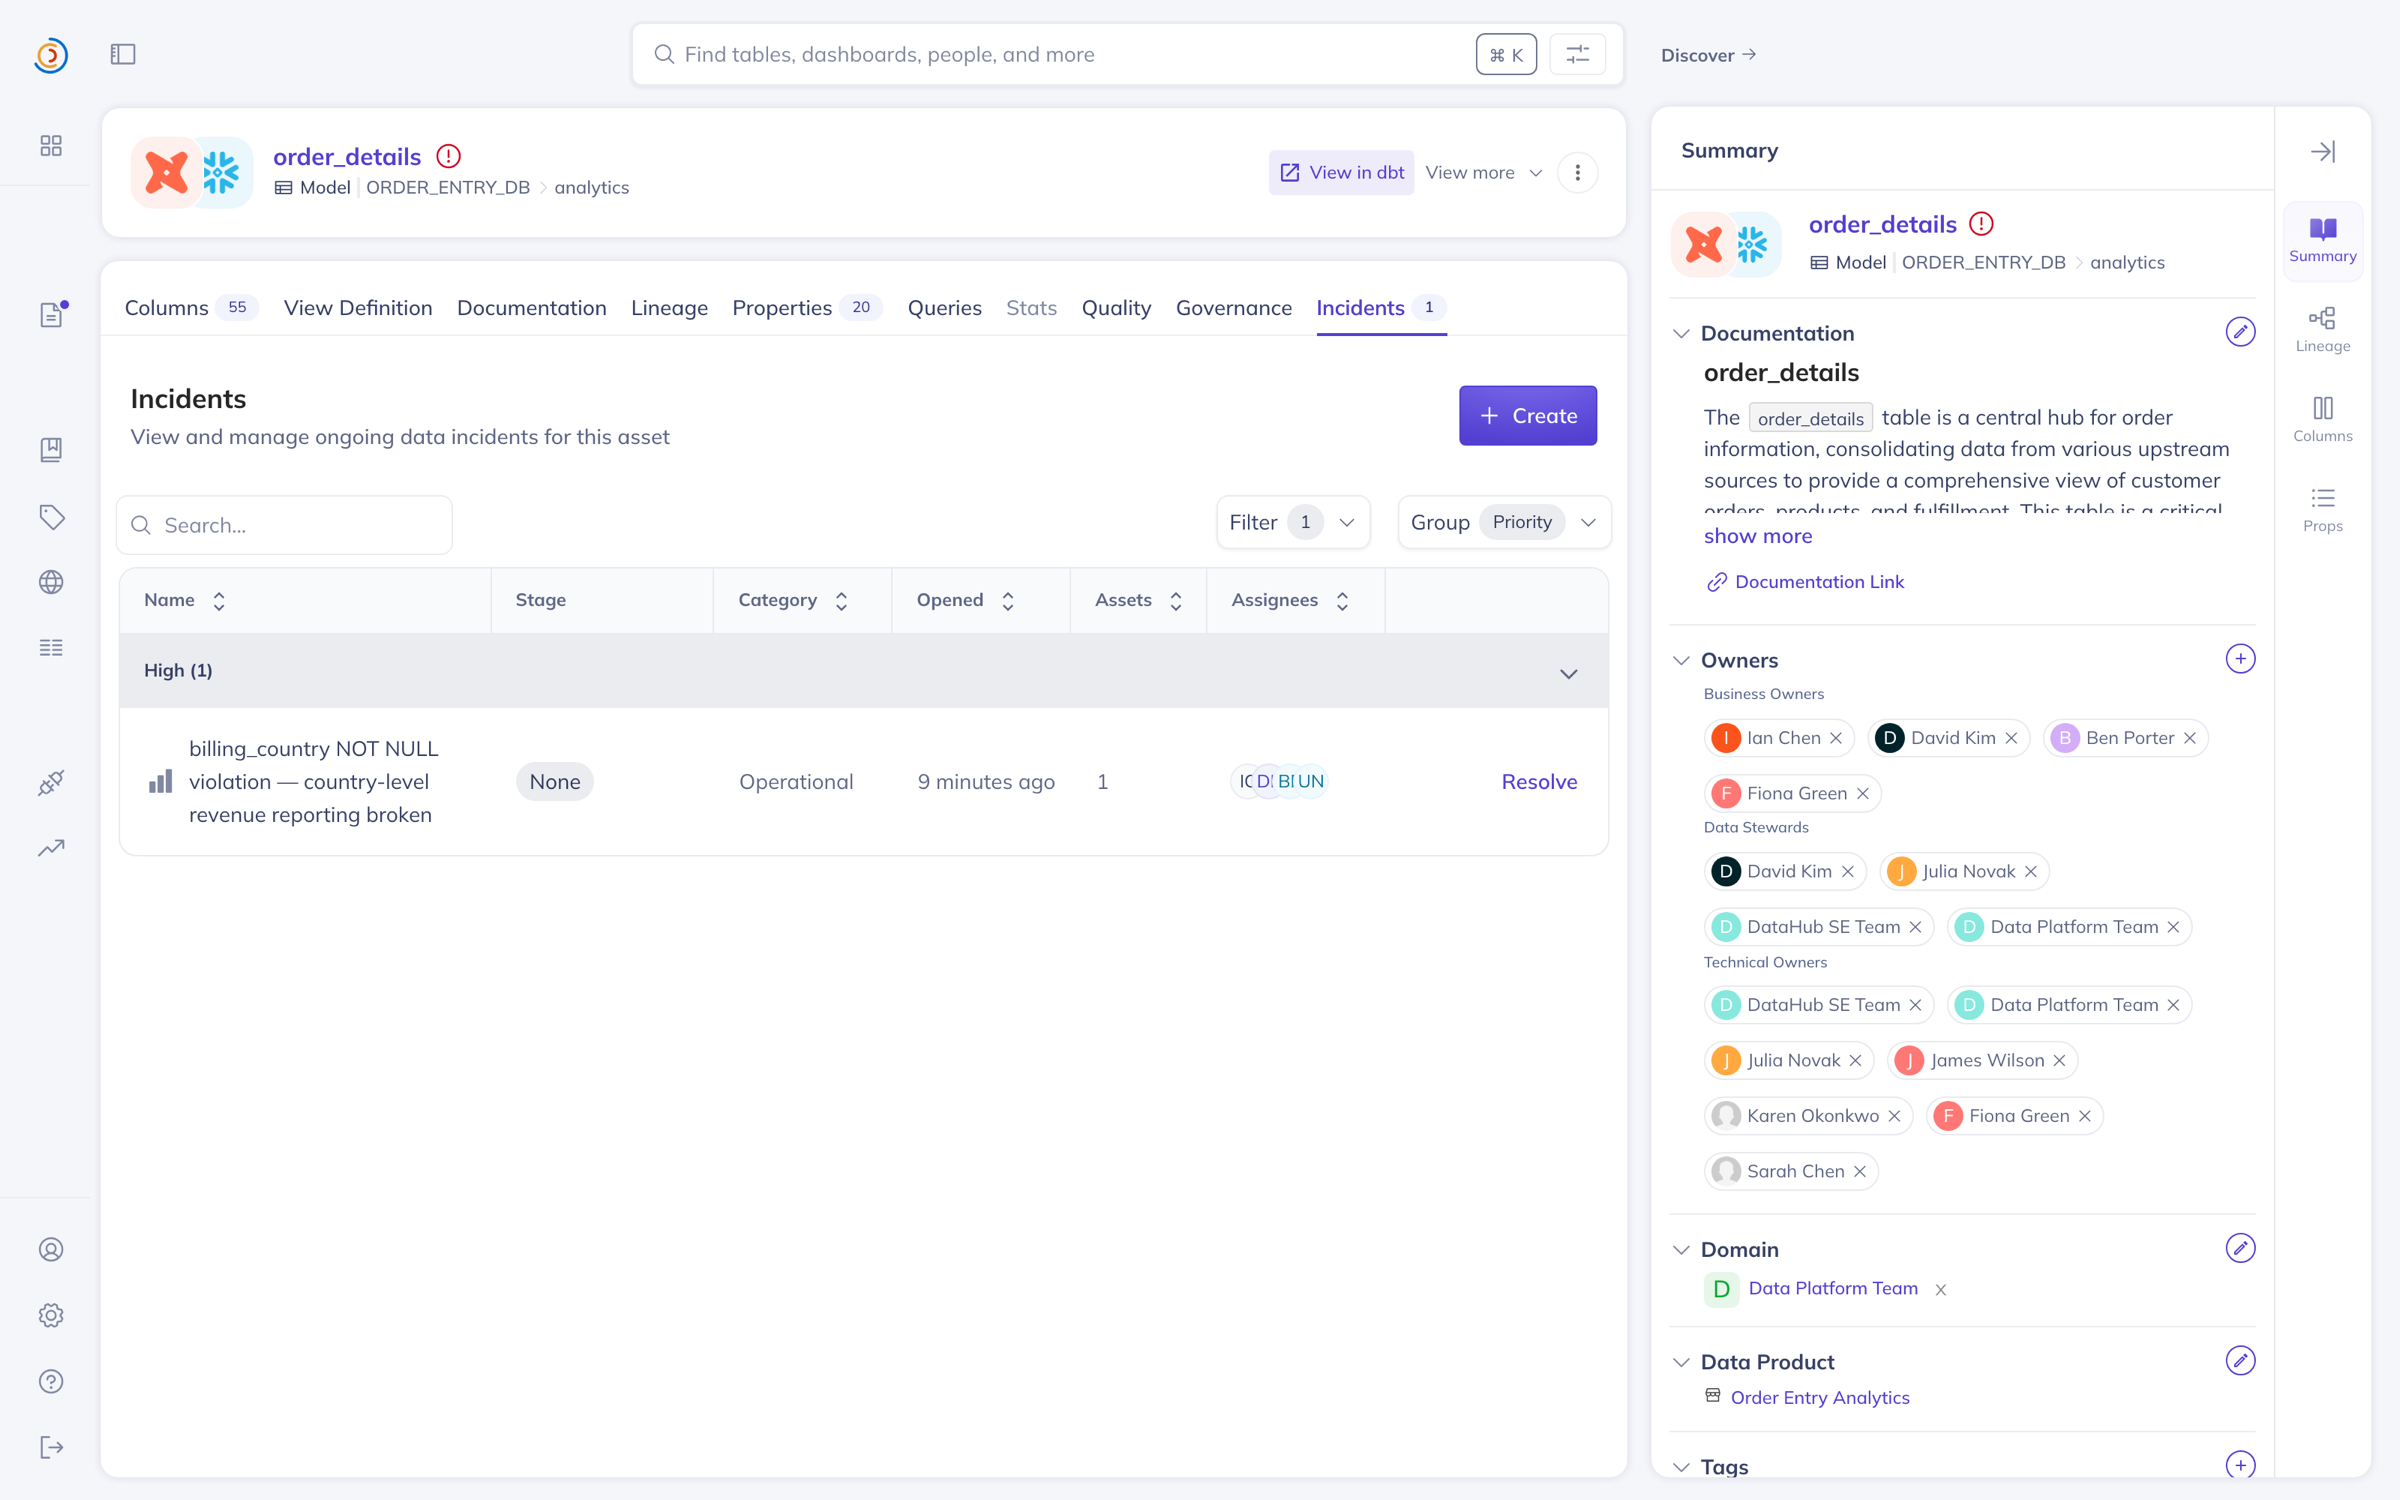
The native DataHub incident CASCADE raised, auto-assigned to the asset's owners straight from DataHub's ownership graph.
-
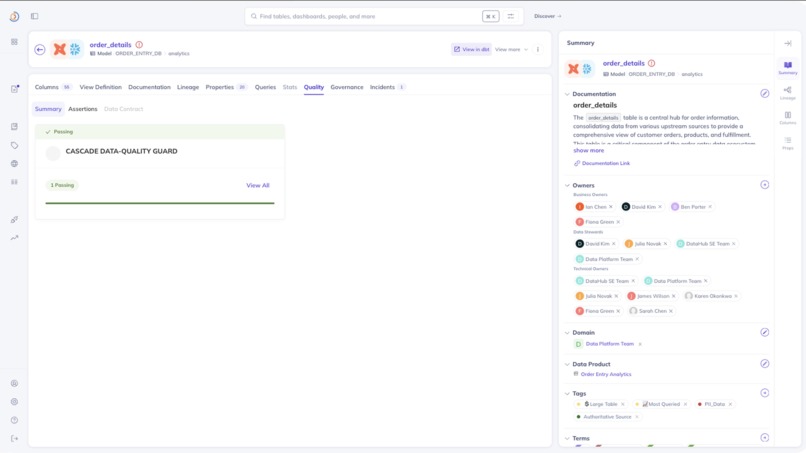
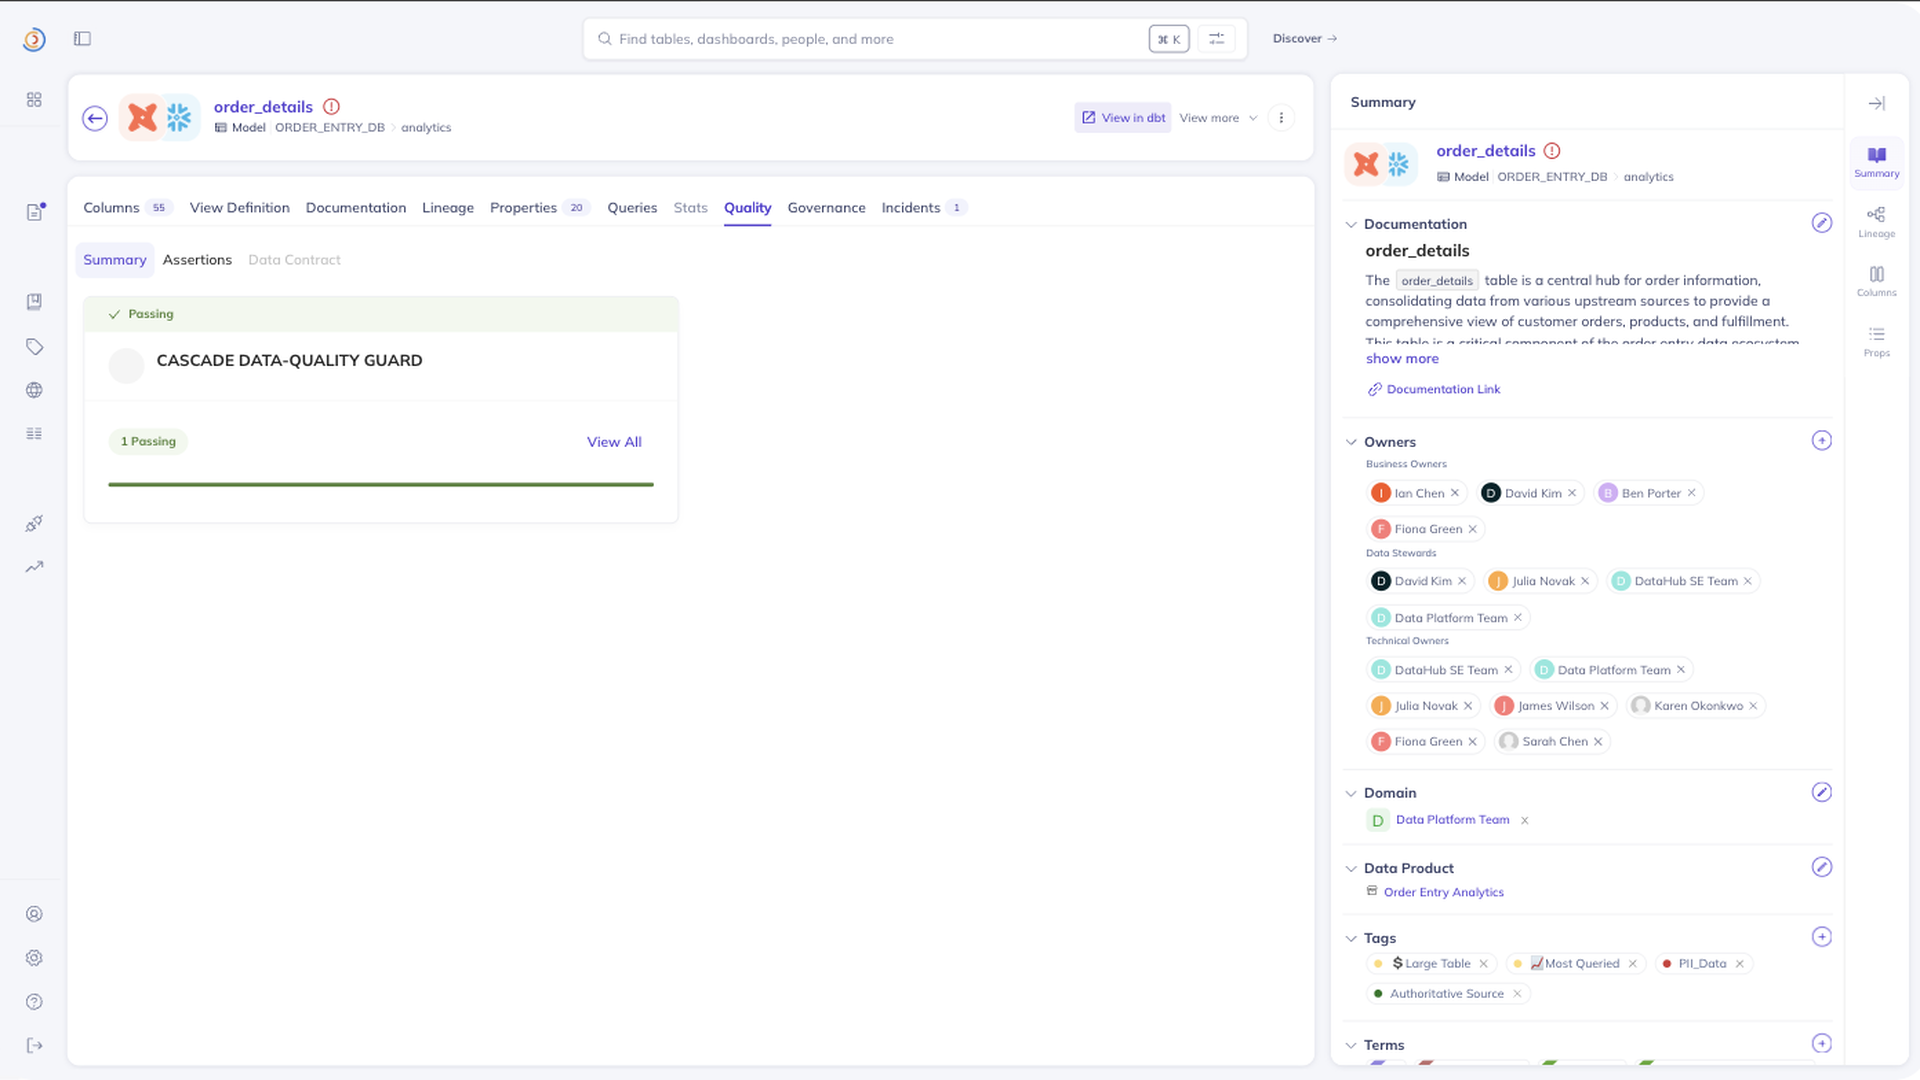
The guard assertion CASCADE registered. It registers the guard; the Passing status is reported by your own check runner (dbt/Airflow/CI).
-
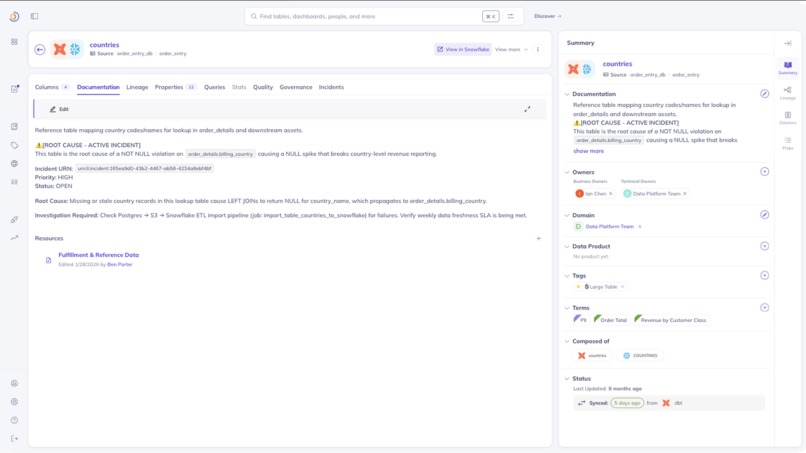
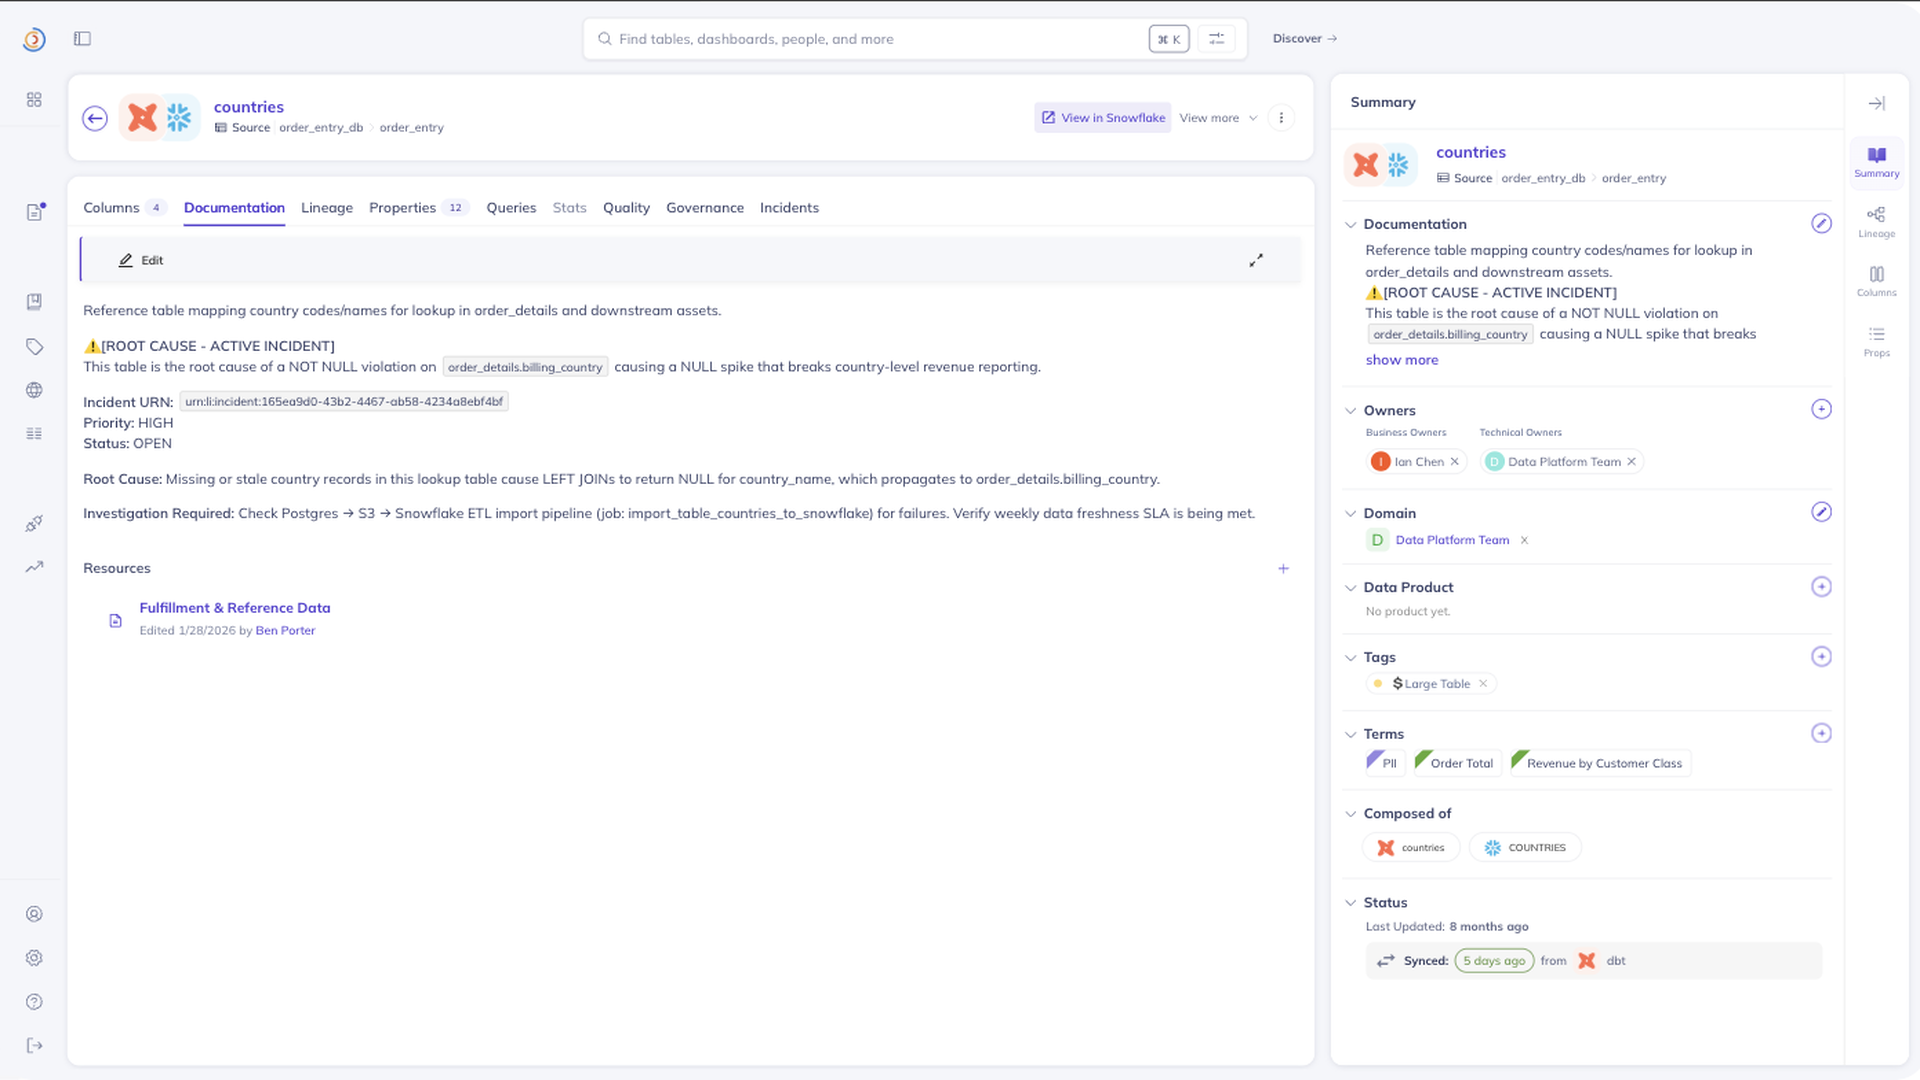
The root-cause table (countries) annotated by the agent, with the incident URN written into the asset's documentation in DataHub.
Data breaks at 2 a.m. CASCADE is the on-call engineer that never sleeps.
Every data team knows the page: a column silently breaks, and suddenly nobody knows which dashboards are wrong, what upstream change caused it, or who owns the fix. An engineer answers that by hand — reading lineage, clicking through catalogs, guessing — for hours, while wrong numbers reach executives.
CASCADE answers it in ~5 minutes, for $0.11, autonomously.
▶ Watch the 2:52 demo: https://youtu.be/3Zb7RKR61JQ ▶ Try it now (no setup, nothing to install): https://biniyoyo.github.io/Cascade/ — the war room replays three complete recorded investigations.
The thesis, measured — not asserted
DataHub's premise: it's a context problem, not a model problem. We turned that into a number, at two model tiers, with the same model in both arms of each:
| without DataHub | with DataHub (lineage via MCP) | |
|---|---|---|
| claude-haiku-4.5 · 5 runs × 3 scenarios | 0 / 15 | 15 / 15 |
| claude-sonnet-5 · 1 run × 3 scenarios | 0 / 3 | 3 / 3 |
Combined: 0/10 → 10/10 on the runs we can prove were hint-free.
All 18 runs passed — but we audited our own eval and found a bug, so we are not claiming 18. scripts/reset_graph.py read a scenario key that no longer existed, so it silently never cleaned the root-cause asset between reps. In 8 of 18 runs that asset still carried a previous run's CASCADE annotation ("[ACTIVE INCIDENT] — this source is implicated in a NULL spike on order_details.billing_country") when the agent read it. Those runs were told the answer, so they are excluded from the headline rather than quietly re-run. The bug is fixed, the contaminated traces stay published, and the auditor ships: python scripts/audit_contamination.py.
Native incidents and guard assertions: 18/18.
Graded structurally, not by vibes: a run counts only if the agent's update_description write lands on the ground-truth root-cause table (accepted at any layer of that table's ingestion chain — postgres origin, warehouse load, or dbt source — never the affected dataset itself). A URN merely mentioned in prose never counts. The graph is reset before every rep — and, because that reset had the bug above, we now verify hint-freeness per run from the traces instead of assuming it. Every raw trace ships in demo/cached/runs/, and python scripts/regrade.py re-scores them offline so judges never have to take our word for it.
Measured cost: $0.11 mean per investigation ($0.08–$0.13 on the Haiku tier; $0.37–$0.56 on Sonnet).
What it does
Hand CASCADE a failing check and it runs the entire incident response, end to end:
- Triage — reads the schema, confirms the affected column (type, NOT NULL contract, PII tag).
- Root cause — traces column-level lineage upstream to the responsible asset, with evidence, in 1–2 hops.
- Blast radius — maps every downstream dashboard, chart, and dataset now showing wrong numbers (35 in our demo incident).
- Acts — writes back into DataHub: raises a native DataHub incident, registers a guard assertion for the failing column so your check runner catches a recurrence, and annotates the root-cause asset. (Registering the guard is what the agent does; reporting run results into it is
scripts/evaluate_guard.py, the hook your dbt/Airflow/CI runner calls — native agent-driven evaluation is roadmap, not shipped.) - Routes — reads ownership from the graph, assigns the incident to the real owner URNs, and drafts a ready-to-send alert: cause, impact, fix.
- Proposes the repair — generates a reviewable dbt schema test + patch proposal (
scripts/propose_fix.py), explicitly human-approval gated. Nothing is auto-applied.
Run it on your catalog, not ours
Nothing in CASCADE is specific to the demo graph. It takes any dataset URN your DataHub knows about, on any platform, plus the symptom in plain English:
python run_incident.py \\
  --urn 'urn:li:dataset:(urn:li:dataPlatform:snowflake,PROD_DB.sales.orders,PROD)' \\
  --symptom 'freshness check failed — no rows loaded since 03:00 UTC' \\
  --priority critical --propose
--propose is how you meet a new catalog safely: CASCADE reads your real lineage, schema and ownership, then prints the exact writes it would make — executing none of them. Point it at production and read the diff before you ever issue a write token. Config is the same DATAHUB_GMS_URL / DATAHUB_GMS_TOKEN the DataHub MCP Server already uses.
How it uses DataHub (read AND write)
- Reads via the DataHub MCP Server:
get_lineage(column-level — the core reasoning substrate),list_schema_fields,get_entities,search,get_dataset_queries. - Writes back via native APIs:
raiseIncident(withassigneeUrns),upsertCustomAssertion, description updates — plusreportAssertionResultexposed as an operator hook (scripts/evaluate_guard.py) rather than an agent tool.
It doesn't just query the graph — it extends it: read → reason → write. The final verify hop (native assertion evaluation) is wired for your check runner, not claimed as agent-autonomous. Every DataHub screenshot in this submission is the real UI showing what the agent actually wrote — no mockups. They also ship in the repo under docs/media/, next to the traces that produced them.
Contributed back upstream
The MCP server had no incident-write tools. We built them and shipped them upstream:
- PR: acryldata/mcp-server-datahub #147 —
raise_incidenttool - PR: datahub-project/datahub-skills #56 —
datahub-incident-response, the methodology packaged for any agent - Issues filed from things we hit building this: mcp-server-datahub #153 (no incident-write tools), #154 (unbounded
get_lineagepayloads vs agent context limits); datahub-project/datahub #18709 (incidentpriorityenum/integer coercion error), #18710 (undocumented header requirements for GraphQL writes on quickstart), #18711 (API-created custom assertions in the UI health summary)
One of those issues is already fixed upstream. A DataHub maintainer closed #18709 as completed via their own PR #18738 — "docs: clarify incident priority enum vs integer storage" — merged. #18709 and #18711 were triaged onto DataHub's internal Linear board (CAT-2748, CAT-2749). The friction CASCADE hit while building was real enough that DataHub changed because of it.
We also closed one of our own issues: a maintainer pushed back on #18711 asking for evidence, we couldn't reproduce it on a clean quickstart, so we posted the write-up and closed it ourselves. The assertion had only looked de-emphasised because a custom assertion carries no status until a runner reports one — our misread, not a UI bug. Filing issues is easy; withdrawing one is the part that keeps the other four worth reading.
Security: the catalog is untrusted input
Agents that read shared metadata can be prompt-injected through the catalog itself. CASCADE treats every description as untrusted: when we planted a fake "incident note" pointing at a bogus root cause, it flagged the note and verified via get_entities before acting. Reproducible from a clean clone: python scripts/plant_injection.py.
Built to be trusted, not just demoed
- 10/10 vs 0/10 fair A/B on verified hint-free runs, two model tiers, URN-graded, re-scoreable offline — and we shipped the auditor that caught our own contaminated runs.
- $0.11 per investigation — cheaper than a minute of engineer time.
- Observe → propose → act rollout:
--proposemode prints intended writes without executing; writes are allowlisted, budget-capped, and audit-logged (audit/audit.jsonl). - Webhook-ready:
POST /api/triggeraccepts an assertion-failure payload — the hook DataHub's Actions/webhook events would point at. - Tested + CI: unit tests plus a live DataHub integration round-trip that exercises the real GraphQL write path against a local quickstart (auto-skips when no DataHub is reachable, so CI runs the unit suite green on 3.11/3.12); pinned lockfile for reproducibility.
- A real product — the hosted war room replays three complete investigations from cached traces ($0 to judge), plus a gated live mode for local runs.
Evidence & limits (what we are not claiming)
- CASCADE identifies the evidence-backed likely root cause: lineage proves the fault domain; confirming the exact defect needs run logs and row counts that live outside the catalog. The agent keeps verified facts and inference explicitly separate in its report, and declines rather than guessing when the graph doesn't support a conclusion.
- It proposes repairs; it does not merge or deploy them. No auto-fix, by design.
- The benchmark is 3 scenarios × 2 model tiers on a seeded DataHub quickstart (showcase-ecommerce, 1,049 entities) — a real graph, but not a production catalog. We publish every trace so the scope is auditable rather than implied.
- Live runs are disabled in the public deployment (they cost API budget and need a DataHub instance); the hosted site is the recorded replay, and the repo reproduces live runs locally.
- 8 of our 18 published runs are inadmissible for the headline A/B because of the reset bug described above, and the no-DataHub control's prompt originally discouraged it from naming specific assets — a fair criticism of our method. We publish the counter-evidence rather than the excuse: across all 18 control outputs the true root cause is named 0 times for
countriesand 0 times fororder_items. Both issues are fixed in code; the affected runs are labelled, not deleted.
How we built it
Python + the Claude Agent SDK driving the official DataHub MCP Server's tools against a local DataHub quickstart. We register those official tools in-process, so the agent's DataHub toolset is deterministic at conversation start rather than racing a subprocess handshake — same tool names, same GraphQL calls, pinned upstream version. FastAPI + a hand-built frontend for the war room. Model-agnostic by construction — any function-calling model works via MCP.
Challenges
Reliable URN capture from agent tool calls, GraphQL enum quirks, oversized lineage payloads vs agent context limits, DataHub's eventual-consistency indexing on freshly written assertions, and making an autonomous agent trustworthy — which shaped the propose mode, guardrails, audit log, and the injection defense. Each of those became an upstream issue rather than a private workaround.
What's next
DataHub Actions-framework consumer so assertion failures trigger CASCADE natively; FIELD-typed incidents; agent-driven incident closure once the guard has passed for N consecutive runs.
Code: github.com/Biniyoyo/Cascade (Apache-2.0) — agent, war room, fair-A/B eval + regrader, tests/CI, remediation proposals, and both OSS contributions.
