-
-
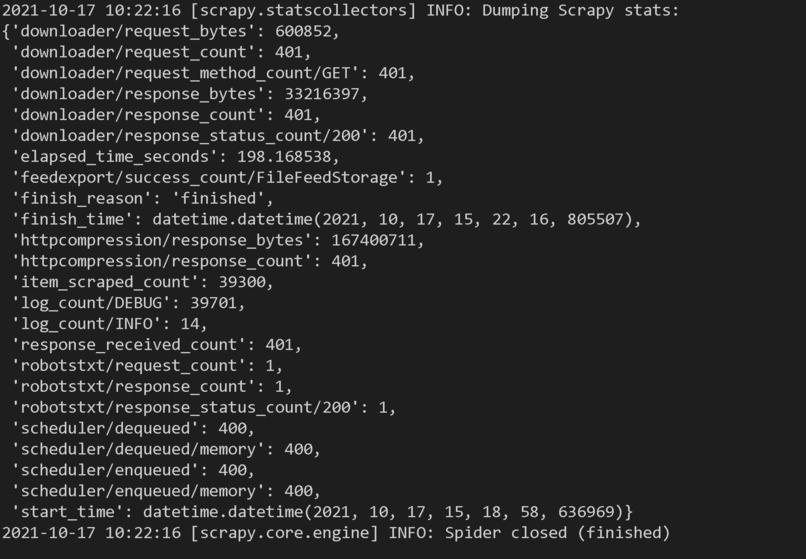
Info about scrapy's stats

The Dataset
We were trying to find large datasets to test our web scraping and visualization skills on and came upon Carmax, which held ~40k entries about various cars. Car price prediction had been done many times already, however we wanted to try and find any more unique features that could correlate with price.
Initially, the scraping was done on carmax using selenium and beautiful soup in order to automate scrolling down to view more results. However, we soon realized it was inefficient (only scraping 24 entries at a time), so we dug deeper and discovered their hidden XHR request. Luckily, we didn't need any session id or authentication. With this combined with scrapy, we could collect ~197 entries per second, totaling ~39000 entries of car info!
Using seaborn and sklearn, we were able to visualize the trends between various features through the use of heatmaps, polynomial regression plots, and histograms. Initially, we had many features that had no correlation with others. Some of these included the car's exterior color, interior color, state, car body, etc. After inputting and replacing many features, we were able to find the features that correlated well with others using the heatmap, showing us where the notable trends were.
Link to github repository: https://github.com/DNCHOW1/Carmax-Price-Correlations
Built With
- google-colab
- jupyter
- python
- scrapy
- seaborn
- sklearn

Log in or sign up for Devpost to join the conversation.