-
-
Thumbnail
-
Dashboard
Inspiration
Speech coaching is broken by vague advice ("sound more confident," "slow down"). Meanwhile, AI wrappers only analyze text transcripts—completely ignoring how you speak—or unfairly penalize female and baritone voices because they compare raw pitch in Hertz.
We built CadenceLens to turn speech coaching into an exact forensic science. Instead of LLM guesswork, it uses acoustic physics to pinpoint the exact millisecond your pitch flattened, your pace rushed, or your energy dropped.
What it does
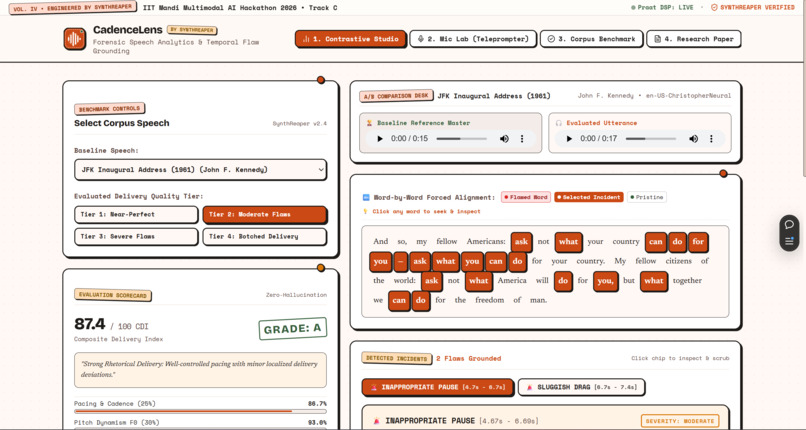
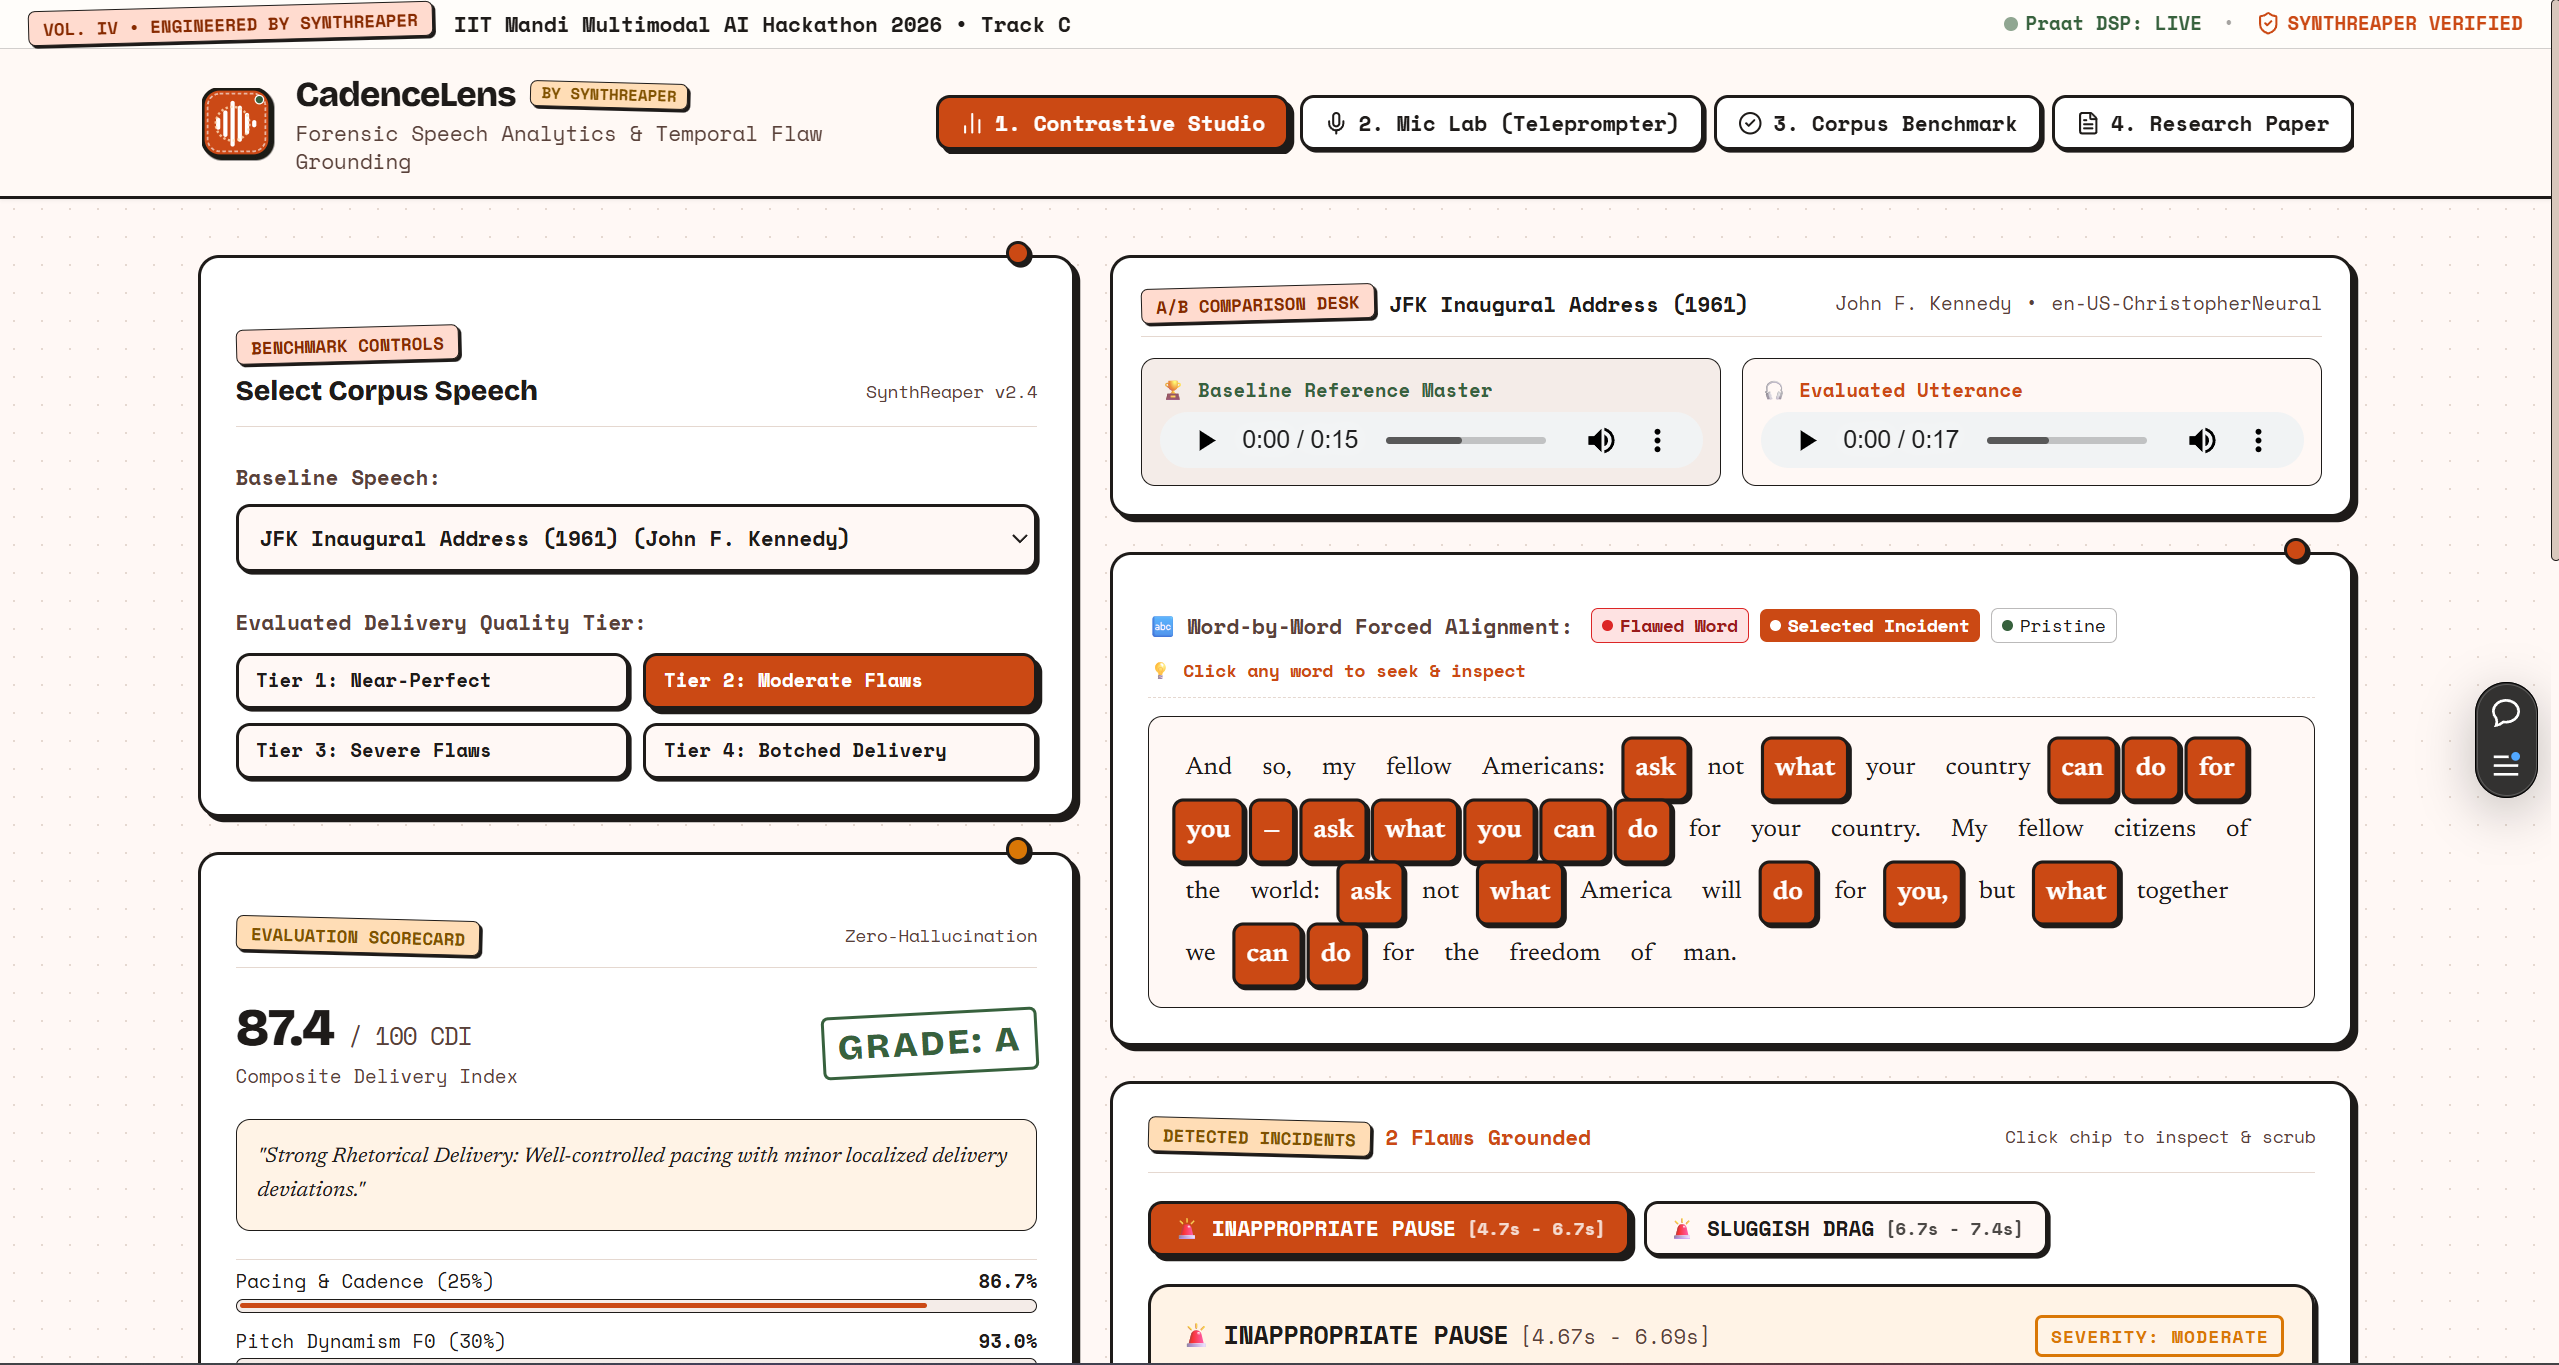
CadenceLens is a zero-hallucination speech analytics studio that compares your voice against master orators (JFK, MLK, Steve Jobs, Churchill):
- Fair Across All Voices (Biological Invariance): Converts raw pitch ($F_0$) into speaker-centered semitones so a soprano female voice and a deep male voice are graded identically on melody and inflection.
- Clinical Voice Biometrics: Uses the Praat C-engine to measure vocal clarity (HNR), vocal cord stability (Jitter & Shimmer), and tongue articulation ($F_1/F_2$ Vowel Space).
- Millisecond Flaw Pinpointing: Aligns your speech to the master baseline using Dynamic Time Warping (DTW) and flags exact timestamps (e.g.,
[4.67s – 6.69s]) with a mathematical proof and coaching fix. - 4-Pillar Composite Delivery Index (CDI): Grades delivery from 0–100 across Pacing (25%), Pitch Dynamism (30%), Stress (20%), and Fluency (25%).
- Interactive Forensic Studio:
- A/B Karaoke Player: Dual-audio playback where flawed words flash red—click any word to jump right to that syllable.
- Live Teleprompter Mic Lab: Record in the browser with a live 60 FPS oscilloscope, real-time pitch tracker, and pacing zone guide.
How we built it
- Acoustic DSP Engine (GitHub Repository): Built in Python using Praat-Parselmouth, Librosa, SciPy, and NumPy.
Pitch Normalization: $$F_{0,\text{ST}}(t) = 12 \log_2 \left( \frac{F_0(t)}{\text{Median}(F_0)} \right)$$
Alignment & Grounding: Multi-feature Cosine DTW warps timelines to handle natural pause variations, while dual-threshold hysteresis groups errors into clean phrase-level intervals.
Contrastive-Oratory-2026 Dataset: Created 25 studio-grade WAV files across 5 historical speeches and 4 controlled quality tiers (Tier 1: Master $\rightarrow$ Tier 2: Monotone $\rightarrow$ Tier 3: Rushed $\rightarrow$ Tier 4: Sluggish).
Full-Stack Web Platform: React 19, Vite, Tailwind CSS, Chart.js, KaTeX, and the Web Audio API on Vercel, backed by a Dockerized FastAPI service on Render with Swagger API Docs.
Challenges we ran into
- Natural Pause Shifts Causing False Alarms: Speakers naturally pause slightly differently than reference recordings. Standard frame-by-frame math flagged everything as an error until we implemented multi-feature Cosine DTW to align phrases before scoring.
- Consonant Spikes: Hard consonants (
/p/,/t/,/k/) caused brief 50ms pitch spikes. Adding a 300ms morphological filter smoothed out micro-noise so only real phrase flaws are reported. - Gaming the Score with Short Audio: A 4-second clip of a 15-second speech initially scored high on fluency. We added a Duration Guardrail ($T_{\text{actual}} < 0.65 T_{\text{target}}$) that automatically penalizes incomplete speeches with a Grade F.
- Cloud Cold-Starts: To ensure judges never hit a slow server, we built a client-side Web Audio DSP fallback and precomputed benchmark cache so the app loads instantly.
Accomplishments that we're proud of
- 100% Monotonic Accuracy: Across all 25 dataset files, scores strictly and predictably drop as delivery worsens: Tier 1 (~99 A+) $\rightarrow$ Tier 2 (~70 C) $\rightarrow$ Tier 3 (~54 D) $\rightarrow$ Tier 4 (~40 F), passing 7/7 automated Pytest suites.
- True Pitch Fairness: Verified via unit tests that a $110\text{ Hz}$ male voice and a $220\text{ Hz}$ female voice with the same inflection curve receive the exact same score.
- Zero-Slop "Tactile Newsprint" UI: Designed an archival laboratory interface with live oscilloscopes, click-to-scrub word alignment, and an embedded research paper.
What we learned
- Explainable Physics Beats Black-Box AI: Audio embeddings can't tell a speaker why they failed a sentence. Explicit signal processing (semitone slopes, HNR, and pause hysteresis) gives transparent, actionable coaching.
- Voice Biometrics Predict Delivery Collapse: Tracking Jitter and Shimmer revealed how breath exhaustion physically appears right before a speaker's pitch goes flat at the end of a long clause.
What's next for CadenceLens
- In-Browser Forced Alignment (WASM): Bring phoneme-level alignment directly into WebAssembly so users can paste and practice any custom script offline.
- Webcam Body-Language Fusion: Combine vocal stress peaks with facial tracking (eye contact, head nods) for complete multimodal keynote coaching.
- Slide Deck Plugins: Live pacing and pitch HUD overlays for PowerPoint, Keynote, and Zoom.

Log in or sign up for Devpost to join the conversation.