Inspiration
We wanted to turn raw web-scraped data into something people could actually use to make decisions. While working with book data, we noticed that a large dataset of titles, prices, ratings, and availability is useful, but difficult to understand when it is just sitting in a CSV.
That inspired us to build BOOKSCOPE, an interactive book intelligence dashboard that transforms scraped data into searchable analytics, comparisons, insights, and recommendations.
How we built it
We used Bright Data Scraper Studio to collect structured book data from Books to Scrape. The collector navigates through the site, handles pagination, collects book information, and produces structured output containing fields such as title, price, rating, availability, and product URLs.
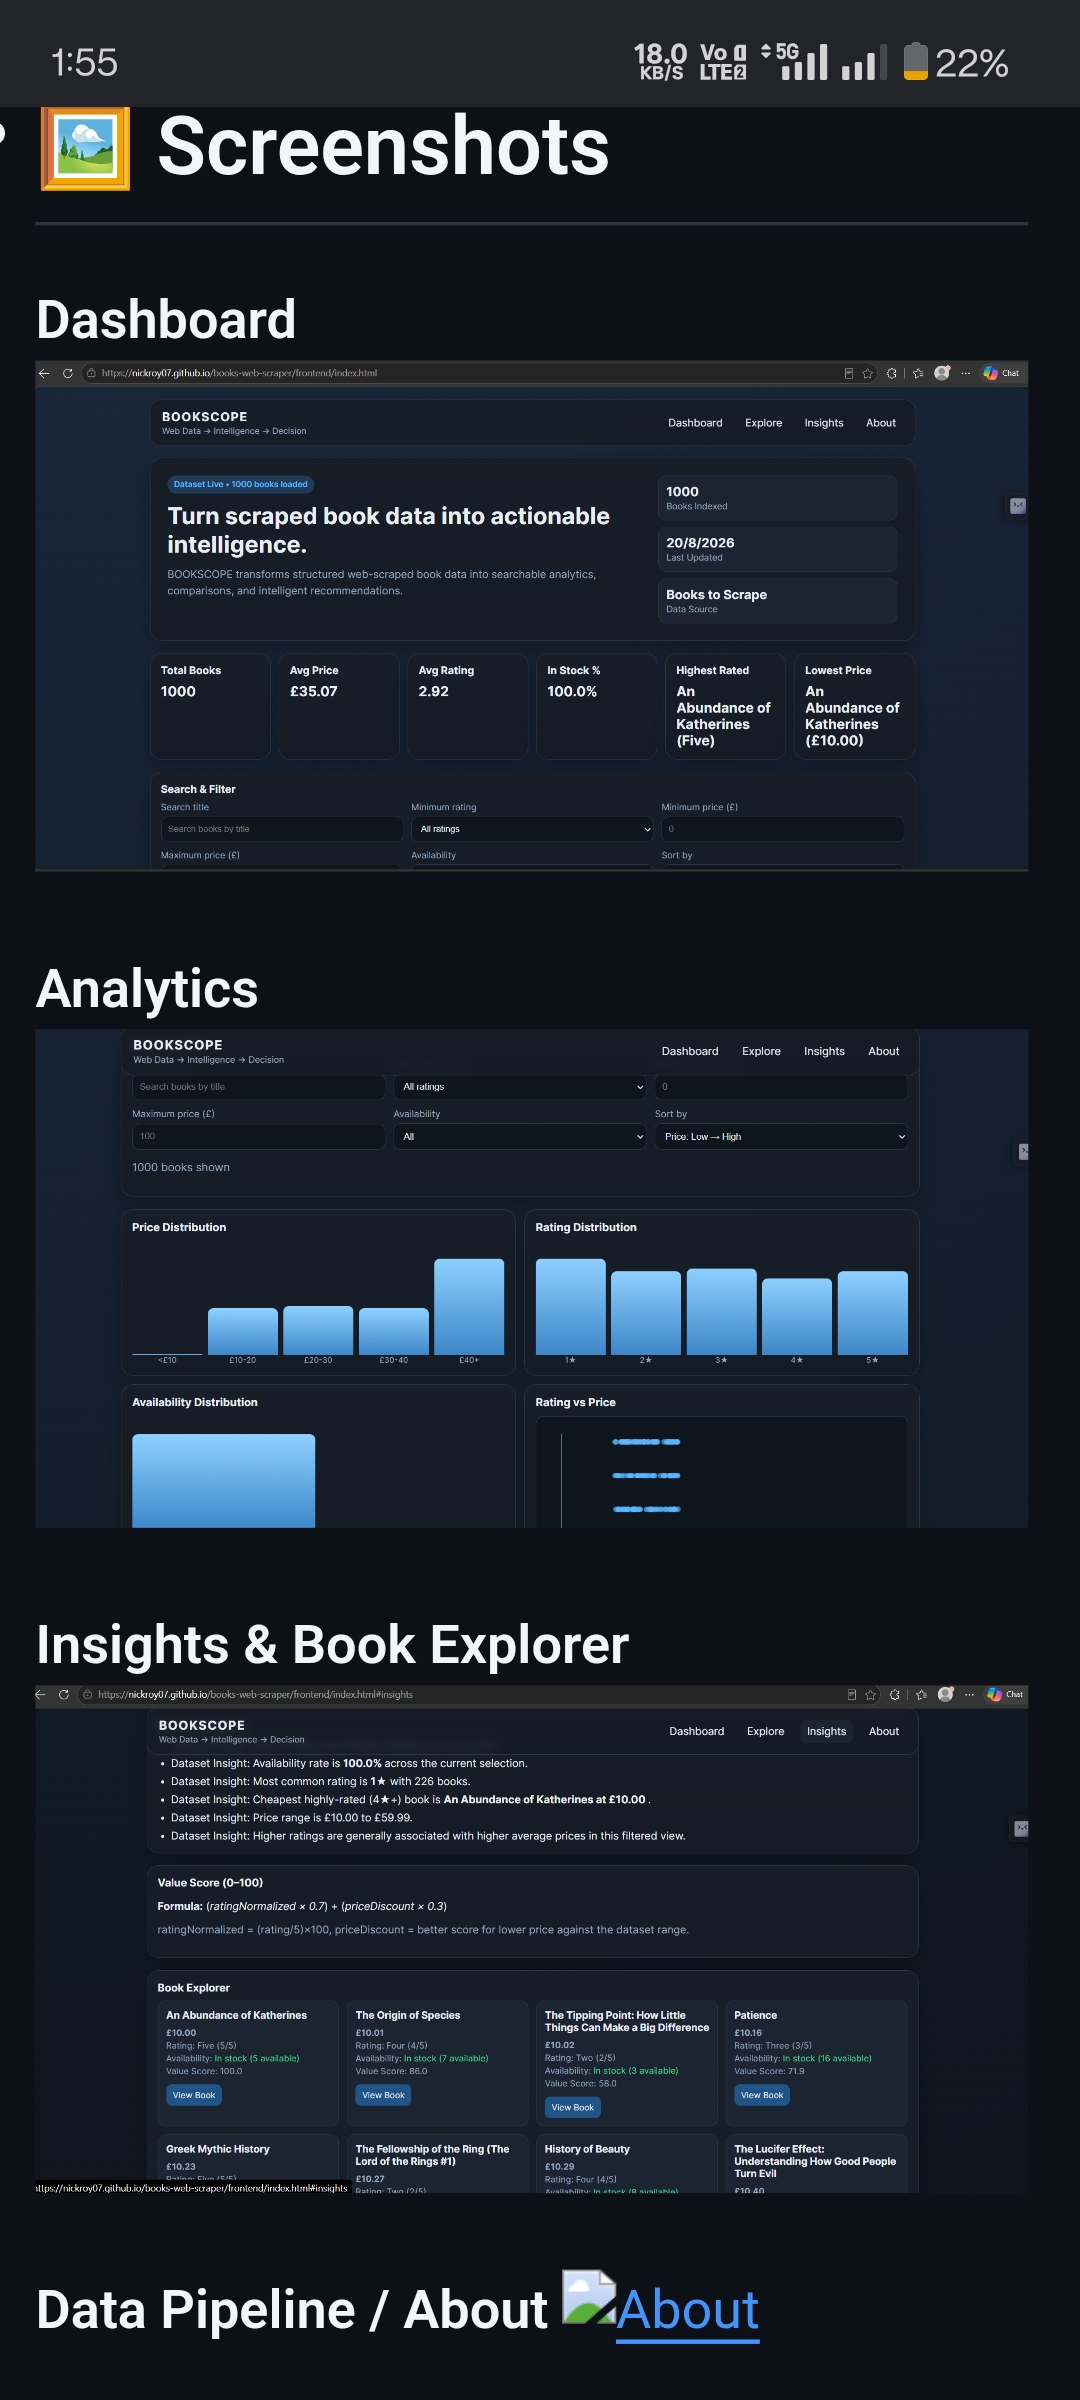
We then built a frontend dashboard that consumes the collected dataset and turns it into an interactive experience. Users can search and filter books by title, rating, price, and availability, while the dashboard dynamically updates KPIs, charts, smart picks, and dataset insights.
We also implemented a value-scoring system that combines rating and price to help users identify books that offer better value.
Challenges
One of our biggest challenges was making the scraping pipeline and frontend data flow work reliably together. We faced issues around pagination, structured data handling, and validating the collector output.
We solved these problems by debugging the collector step by step, validating the output in Bright Data Scraper Studio, improving the pagination flow, and testing the frontend against the actual collected dataset.
What we learned
This project taught us that scraping is only the beginning. The real value comes from transforming collected data into something understandable and actionable.
We also learned more about building reliable data pipelines, working with structured web data, designing interactive dashboards, debugging scraping workflows, and using Bright Data's tooling to improve the development process.
What's next
We would like to make the pipeline more automated and resilient to website changes, add more advanced recommendations and analytics, and expand BOOKSCOPE into a broader decision-support platform for web data..
Built With
- bright
- css
- csv
- data
- github
- html
- javascript
- pages
- scraping
- visualization
- web


Log in or sign up for Devpost to join the conversation.