-
-
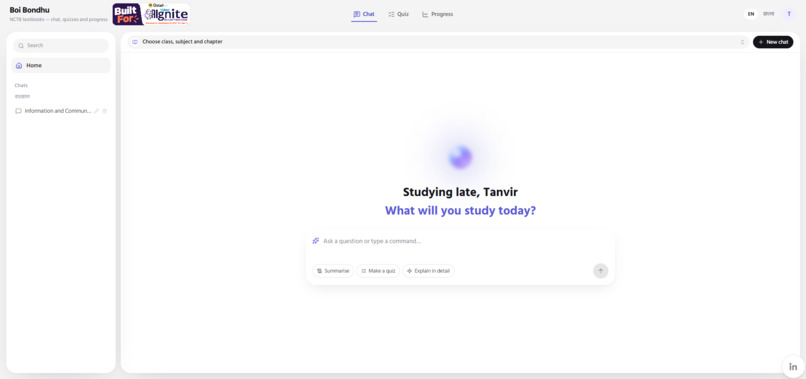
Home Page
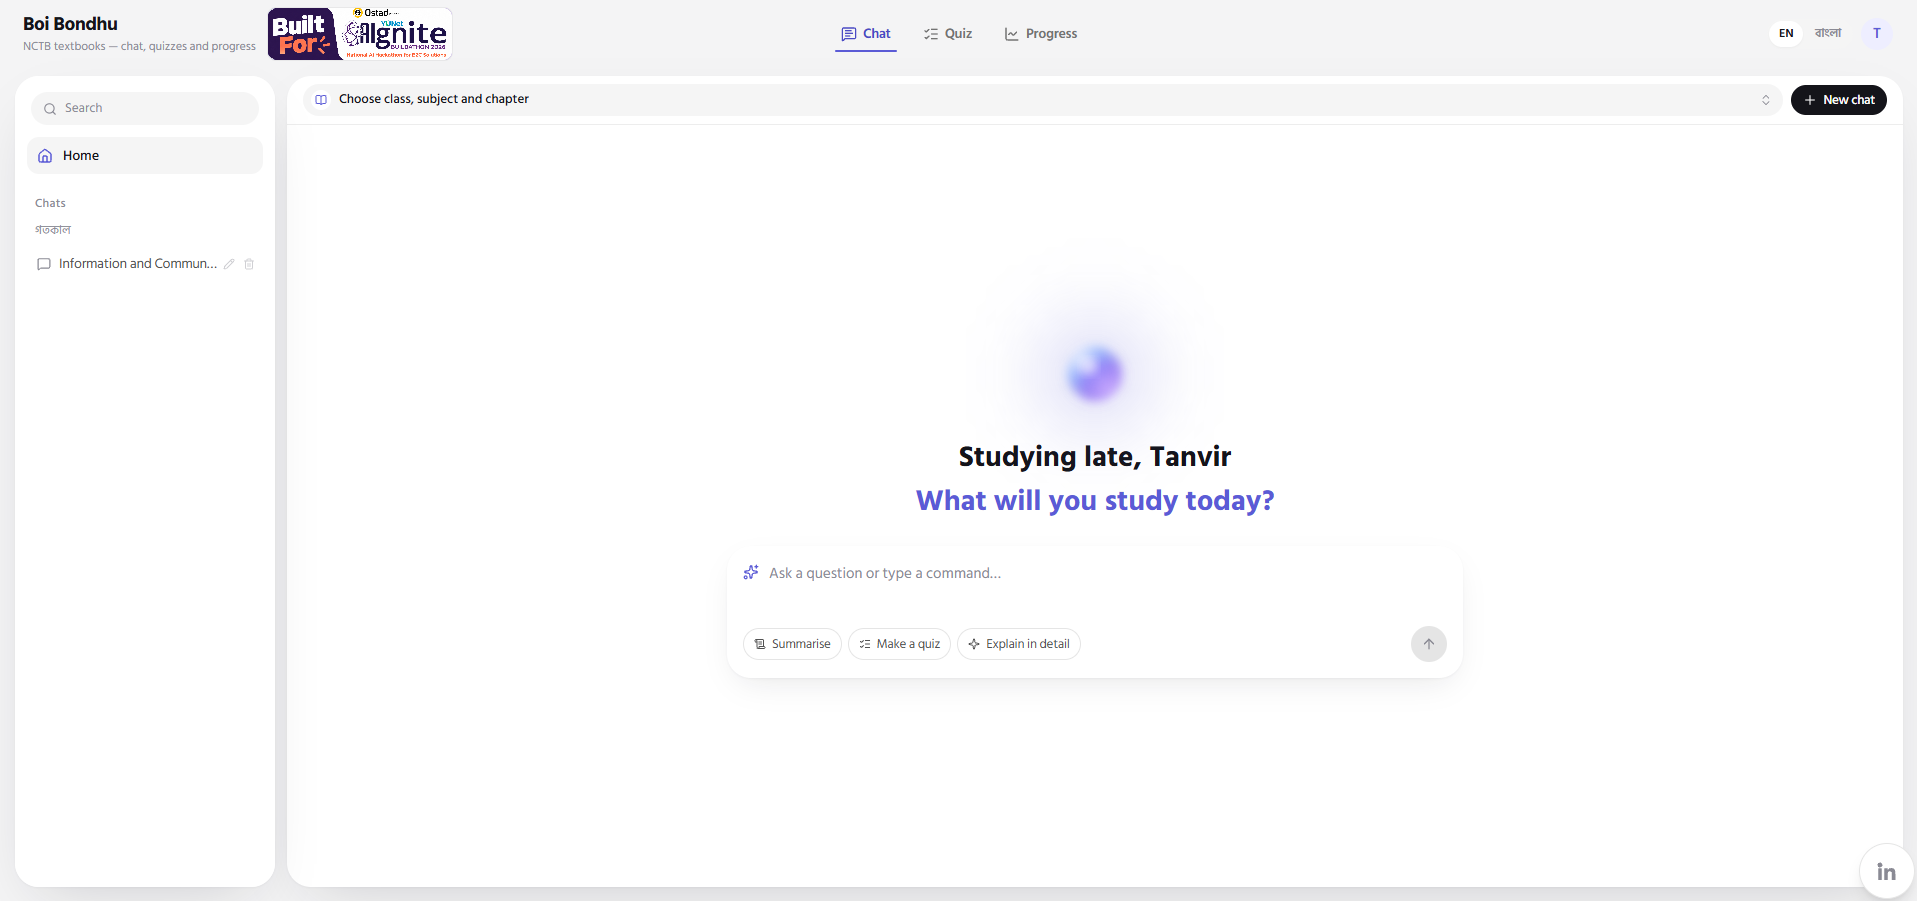
Inspiration
NCTB textbooks are in Bangla and organised chapter by chapter, but general AI chatbots answer from the whole internet. They can invent facts, mix chapters and drift out of the syllabus, which makes them risky for exam prep. Students also can't check their understanding of one chapter, teachers can't generate a fresh chapter quiz on demand, and parents can't see where a child is weak. Boi Bondhu (বই বন্ধু) is a study friend that stays inside the student's own chapter.
What it does
Pick Class 9–10, a subject and a chapter. Everything then stays inside that chapter:
- Chat: ask in English or Bangla. Answers use only that chapter's passages, cite the page and stream token by token.
- Quiz: 5 multiple-choice questions written from the chapter, with explanations and a topic label. Correct answers stay on the server, so scores can't be tampered with.
- Progress: per-chapter accuracy, weakest topics, recent attempts and an LLM-written summary for parents, with a deterministic fallback.
One toggle switches the interface, subject names, chapter titles and the AI's answer language to বাংলা. There are no accounts, and chats are deleted after 3 days.
How we built it
- Offline pipeline: NCTB PDFs → OCR → chapter chunks (1500 characters, 350 overlap) →
multilingual-e5-baseembeddings (768-d) → one FAISS index per chapter. - Retrieval: keyword search (BM25) and semantic search (FAISS) are combined, with slightly more weight on semantic matches ($0.4$ BM25, $0.6$ dense). The top $k = 5$ passages from the selected chapter only go to the LLM.
- Generation: Groq
gpt-oss-120bwith DeepSeek as automatic fallback, streamed as NDJSON events. - Backend: FastAPI (Python 3.12) and SQLite (WAL), one row per answered question.
- Frontend: Next.js 16 and Tailwind on Vercel, which proxies
/api/*to a Docker container on AWS EC2.
Scale: 27 books, 26 subjects, 385 searchable chapters, and all 437 chapter titles translated into English.
Challenges we ran into
- Keeping answers grounded: searching one chapter instead of a whole book keeps the context small and the citations meaningful.
- Image size: the model cache shrank from $10.1\,\text{GB}$ to $1.1\,\text{GB}$ (about $89\%$ smaller) by using one flattened model directory instead of five duplicate copies.
- HTTPS vs HTTP: the HTTPS site couldn't call the plain-HTTP backend, so Vercel proxies
/api/*to EC2. That avoids mixed content and CORS. - Bilingual by design: translating all 437 chapter titles and switching the AI's answer language with the UI.
- Reliability: a catalog served with ETag, gzip and a browser cache, plus an end-to-end test suite that passes in both English and Bangla.
What we learned
- Scoping retrieval to one chapter does more for trust than a bigger model.
- Small engineering details, like image size and a proxy, decide whether a demo actually ships.
- Server-side quiz answers and anonymous, auto-deleting chats are cheap to build and make the product safer.
What's next
More classes, a teacher dashboard and an offline PWA.
Try it: https://boibondhu.vercel.app
