Inspiration
Some conversations are hard not because we don't know what to say — but because we don't know how the other person will react. That uncertainty keeps us silent.
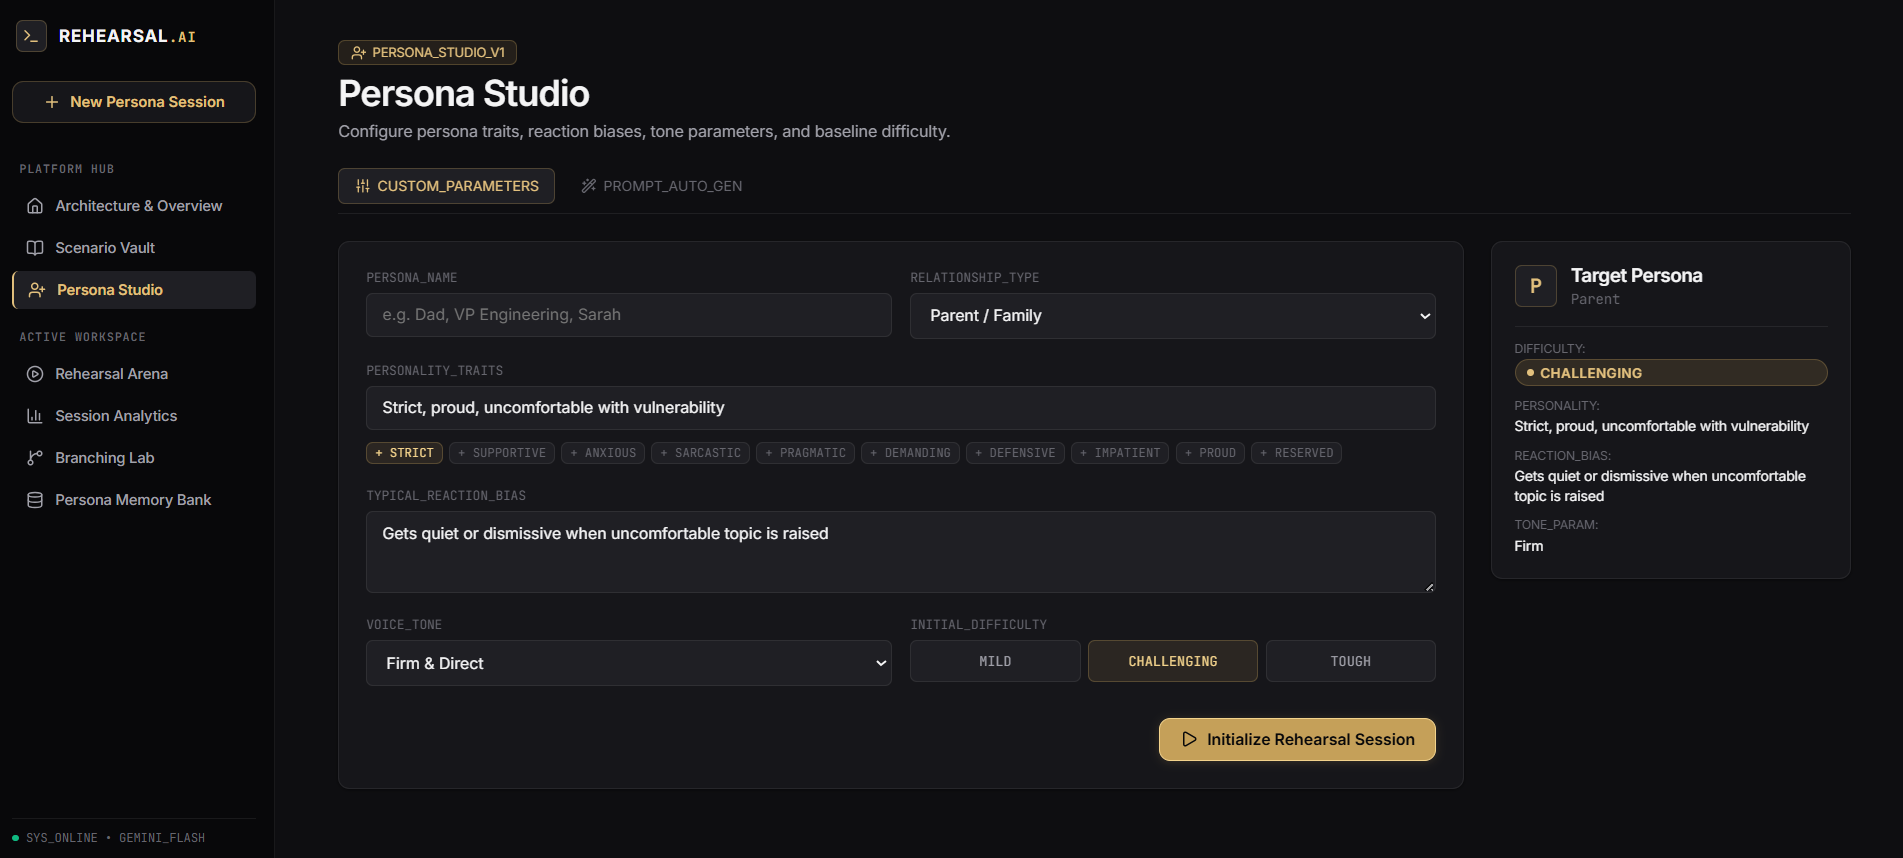
Rehearsal.ai is a voice-first AI simulation platform where users describe real people in their life — their personality, tone, typical reactions, even speech habits — and then have a live, spoken voice conversation with AI-voiced versions of them.
Instead of typing into a static chatbot, you speak the hard thing out loud, hear a realistic voiced reaction back, and practice until you feel ready for the real conversation. This is a private, voice-driven rehearsal space personalized to the actual people you need to talk to.
What It Does
- Live Voice Rehearsal Loop: Low-latency, spoken conversation powered by Web Speech STT/TTS and Google Gemini 2.5.
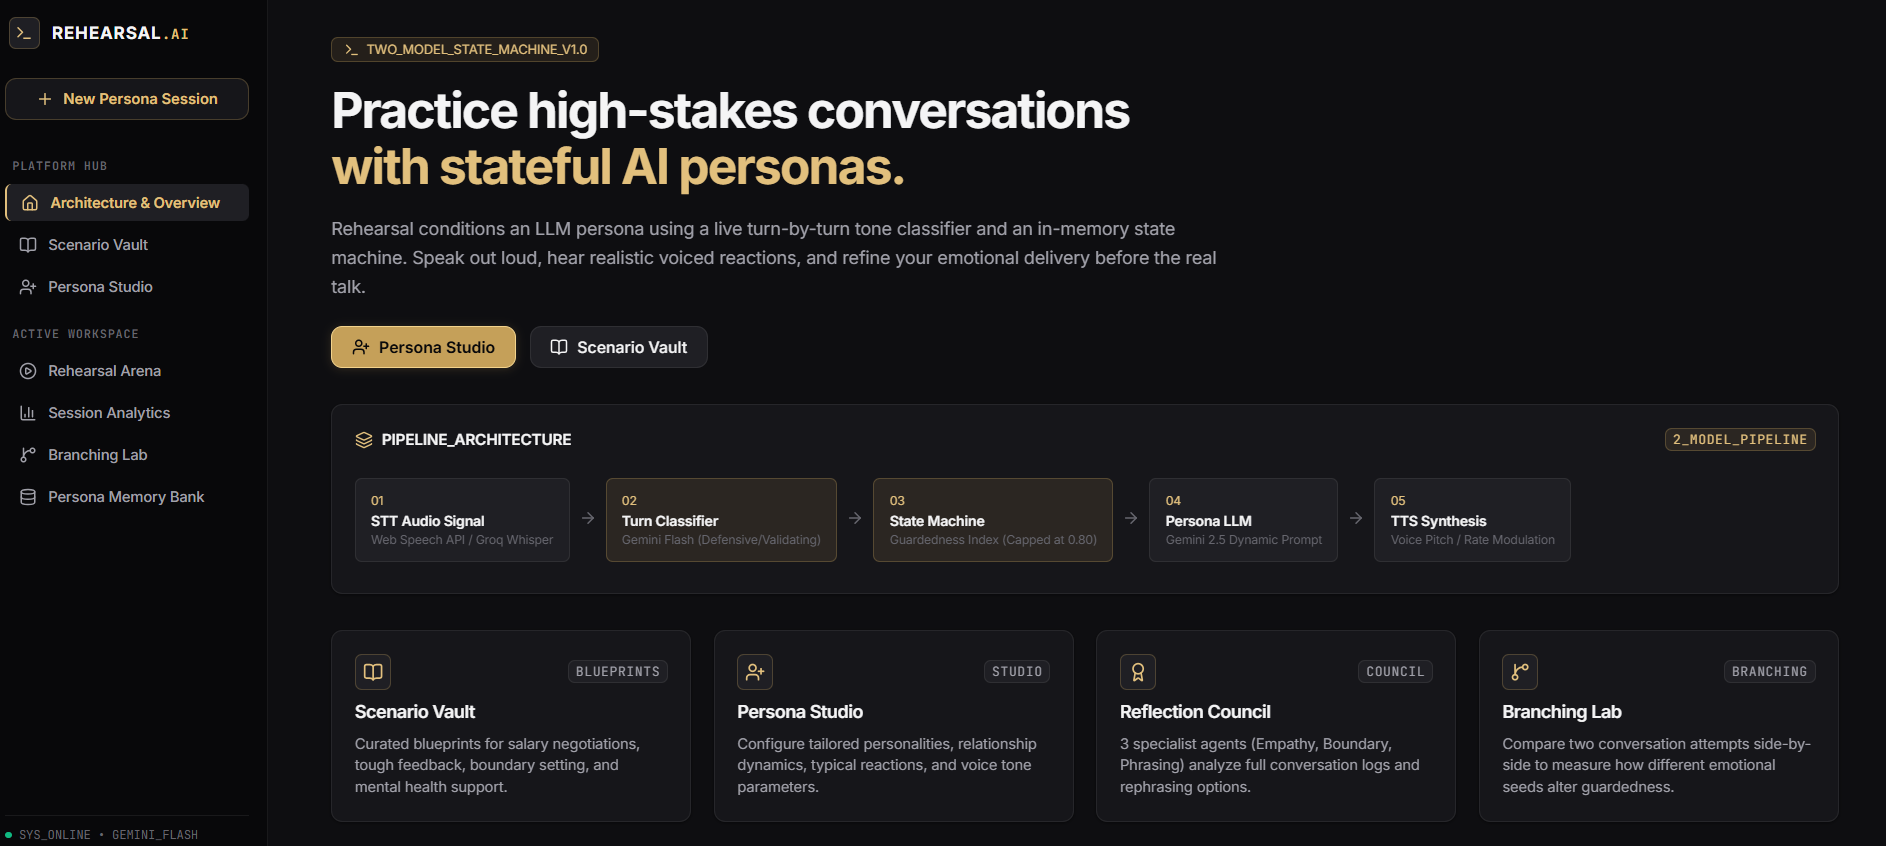
- Two-Model State Machine: A fast turn classifier detects user emotional tone (defensive, validating, evasive, hedging) every turn, feeding an in-memory state machine that dynamically mutates the persona's
guardednessindex (capped at 0.80 for safety). - Visual Audio Signal Waveform: Real-time HTML5 Canvas sine wave visualizer tracking microphone input and AI voice speech output.
- Live Telemetry & State Debugger: Real-time inspector tracking persona mood, guardedness index, unvalidated turn count, and user signal classifications.
- Stealth AI Coach: A background AI agent observing alongside you, providing non-blocking private tips every 2 turns without interrupting the voice flow.
- 3-Stage Reflection Council: A parallel multi-agent council (Empathy, Boundary, Phrasing agents + Chairman) generating executive feedback, rephrasing alternatives, and emotional arc timelines.
- Conversation Branching Lab: "What if they got angry / calm / dismissive?" — restart from mid-conversation checkpoints with different reaction seeds and compare guardedness trajectories side-by-side.
- Cross-Session Memory Bank: Persistent lightweight context memory injected into subsequent persona system prompts across sessions.
How We Built It
- Frontend: Built with React 18, Vite 5, React Router v6, Lucide Icons, and standard Web APIs (
SpeechRecognition,SpeechSynthesis, HTML5 Canvas). Designed with a Vercel/Linear-inspired dark minimalist aesthetic (#08080Acharcoal +#C5A059champagne gold) with zero emojis and full monospace telemetry typography. - Backend API: Python 3.11+ + FastAPI + Uvicorn with native async execution.
- AI / LLM Engine:
- Model 1 (Classifier): Google Gemini Flash (
gemini-2.5-flash) for low-latency per-turn user tone classification. - Model 2 (Persona Reasoning): Gemini 2.5 Flash for dynamic system prompt generation conditioned by the state machine.
- Model 1 (Classifier): Google Gemini Flash (
- Multi-Agent Reflection: Parallel async council execution (
asyncio.gather) aggregating specialist feedback into structured JSON schemas via Pydantic.
Mathematical composite scoring formula for confidence index: $$ \text{Confidence} = 100 - (0.25 \times \text{FillerRate} + 0.45 \times \Delta\text{Guardedness} + 0.30 \times \text{DefensiveTurnRatio}) \times 100 $$
Challenges We Ran Into
- Stateful Emotional Dynamics: Standard LLM system prompts don't maintain realistic emotional momentum. We solved this by designing a Two-Model Architecture where a lightweight classifier explicitly mutates an in-memory
PersonaStatevariable that conditions the primary reasoning LLM. - Low-Latency Voice Integration: Orchestrating Web Speech API STT, fast classifier inference, persona generation, and Web Speech Synthesis without blocking the main event loop.
- Safety & Responsible Boundaries: Ensuring persona responses are challenging without escalating into cruelty or abusive content by hard-capping guardedness at 0.80 and enforcing strict safety guidelines in system prompts.
Accomplishments That We're Proud Of
- Built a legitimate Two-Model State Machine architecture rather than relying on a single prompt.
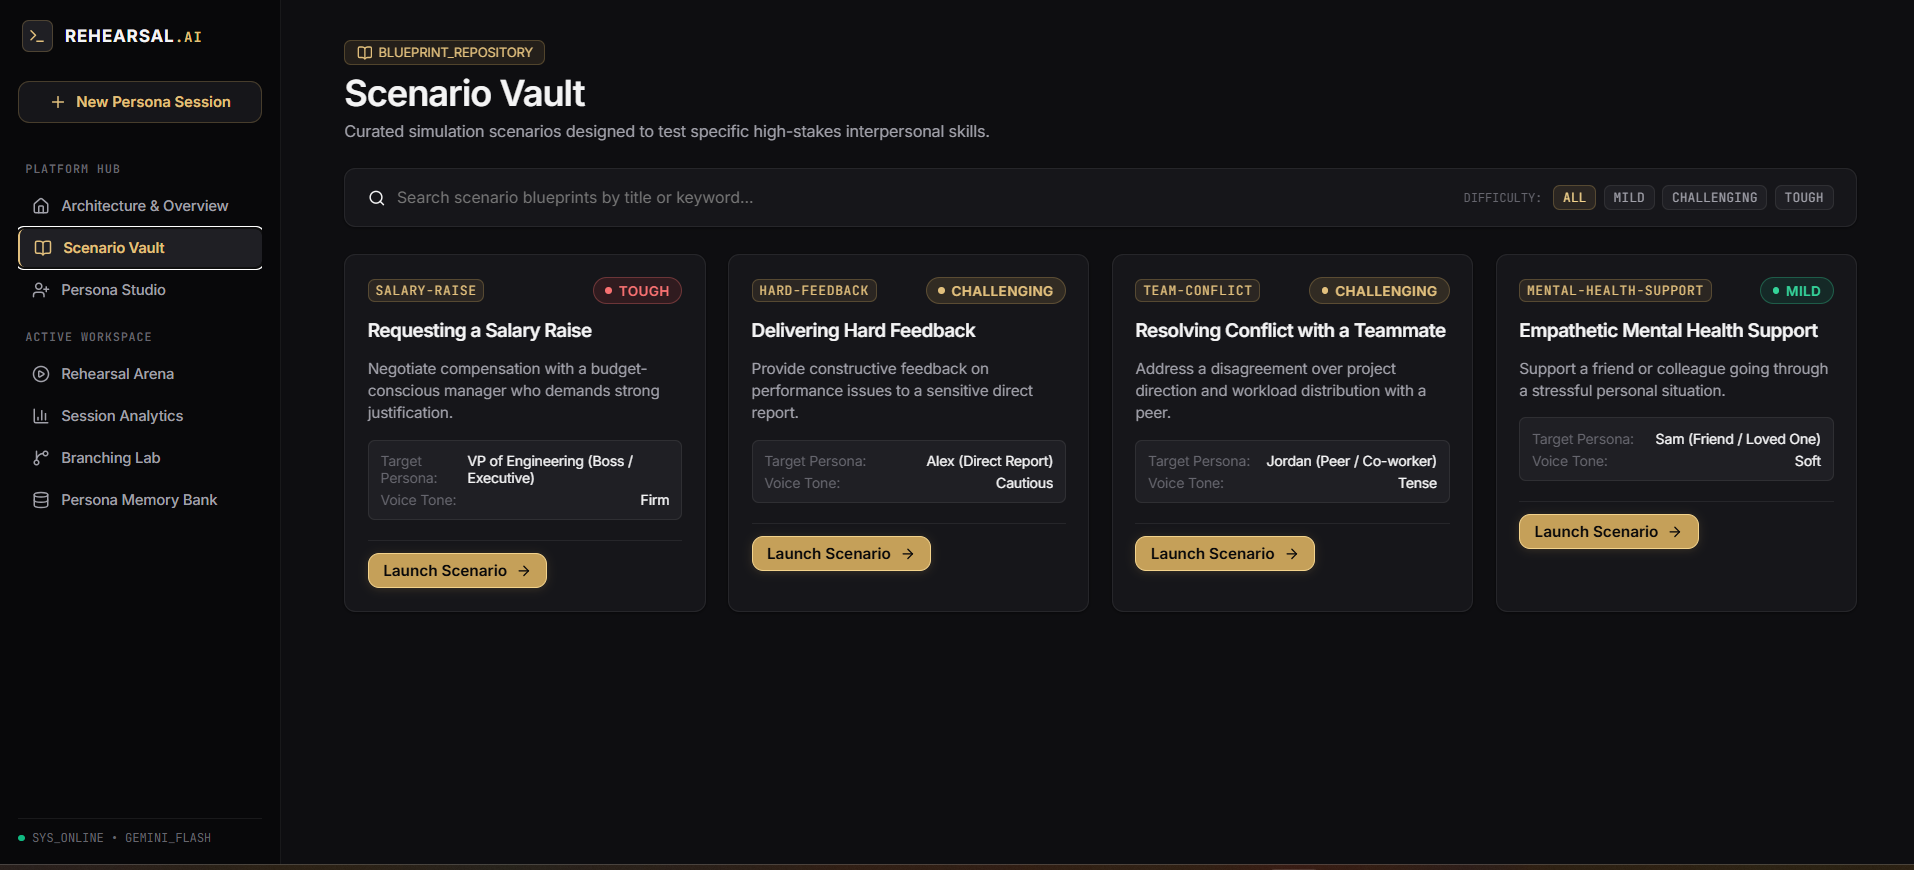
- Crafted a hyper-polished, professional dark minimalist UI with 7 comprehensive views (Landing, Scenario Vault, Persona Studio, Rehearsal Arena, Session Analytics, Branching Lab, Memory Bank).
- Developed a non-blocking Stealth AI Coach and parallel 3-agent Reflection Council.
- Achieved 100% test passing rate across our FastAPI PyTest suite and clean production Vite builds with 0 errors.
What We Learned
- How stateful dynamic variables dramatically improve LLM consistency in realistic roleplay scenarios.
- The power of parallel multi-agent reflection for deep post-session analytical feedback.
- Best practices in browser Web Speech API stream handling and canvas frequency visualization.
What's Next for Rehearsal.ai
- Mobile PWA app with native haptic feedback during speech playback.
- Multilingual support for Hindi, Spanish, and French conversation rehearsals.
- ElevenLabs voice clone integration for personalized vocal resonance.
Built With
- css3
- fastapi
- google-gemini-api
- html5
- javascript
- lucide-icons
- pydantic
- pytest
- python
- react
- rest
- uvicorn
- vite
- web-speech-api

