-
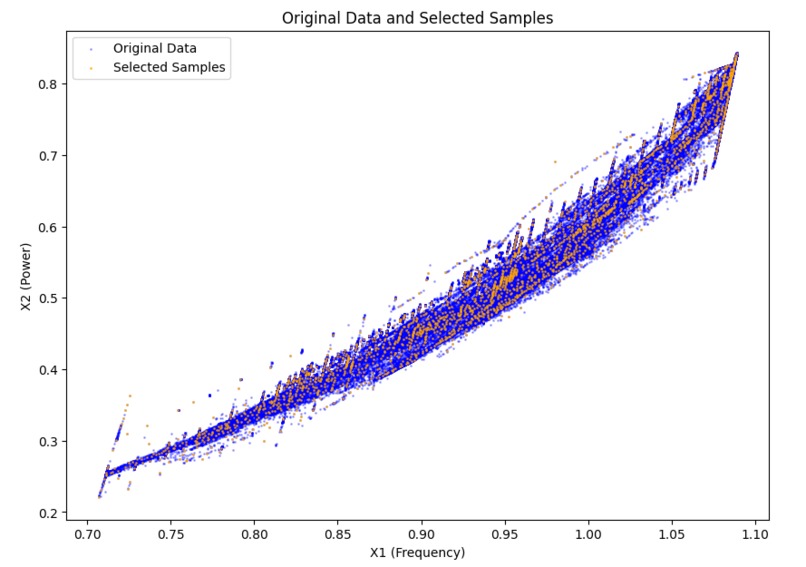
dataset 1 comparison
-
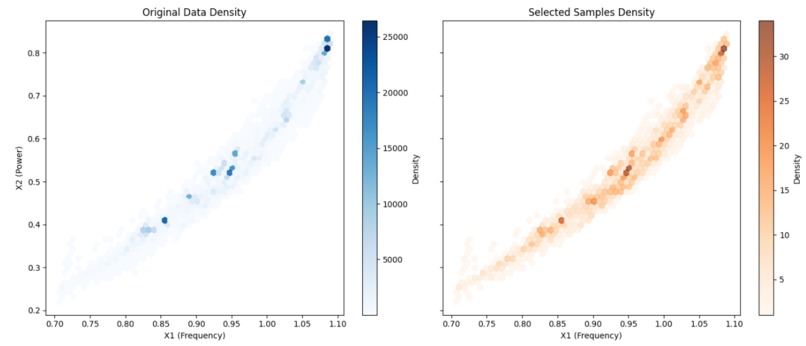
dataset 1 density peak
-
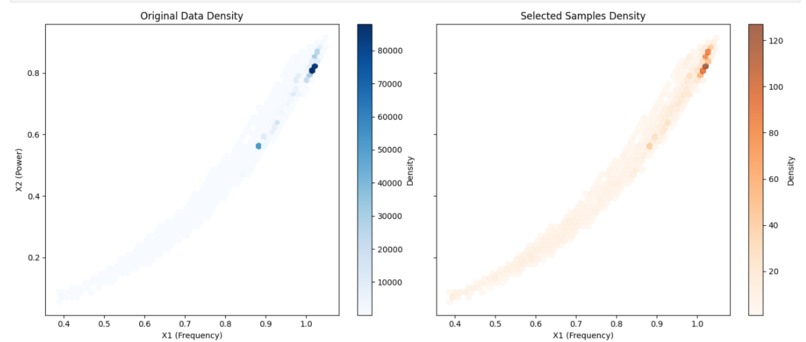
dataset 2 density peak
-
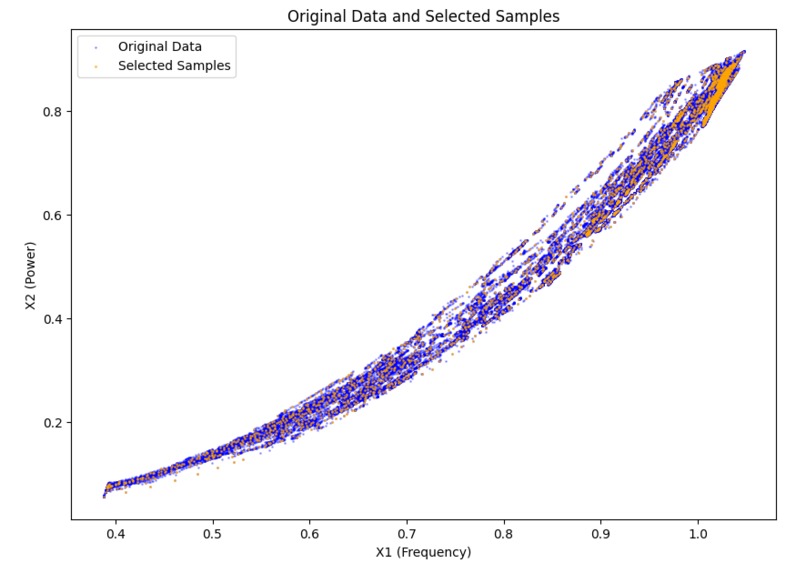
dataset 2 comparison


Inspiration
Clustering is a good tool to sample data in an unsupervised manner. So, we used K-means clustering to sample data.
What it does
K- means clustering into 2500 clusters and selecting one sample per cluster.
How we built it
Using Pandas dataframe and sklearn's k-means clustering
Challenges we ran into
Computation time and memory requirements (needs more RAM. specially the experiment with DBSCAN. So, we divided it into chunks)
Accomplishments that we're proud of
Excellent coverage and matched density peaks on the both datasets
What we learned
Usefulness of clustering algorithms for data sampling.
What's next for Baker Hughes Data Sampling
For very high dimensional data, we can also use trained embeddings for clustering. Since, we only have 2 dimensions, k-means is a good approach.
