-
-
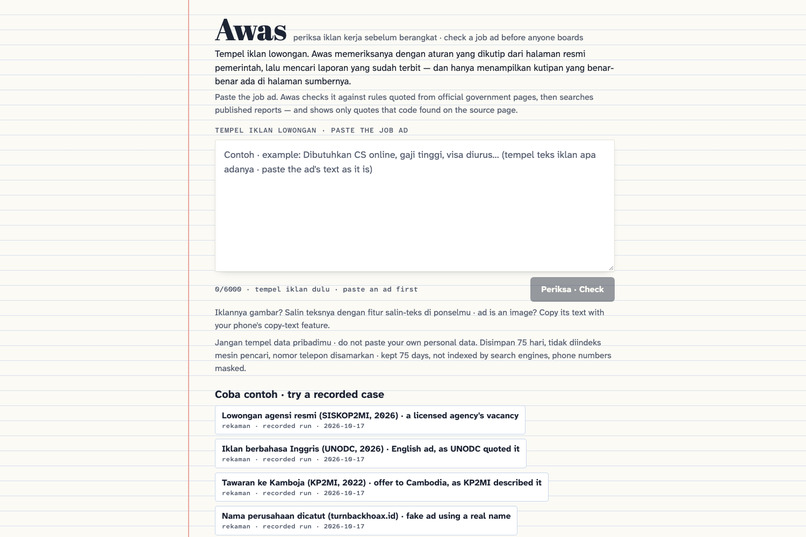
Awas home: paste an overseas job ad as plain text. No login, no daily cap; 60 live checks an hour per connection.
-
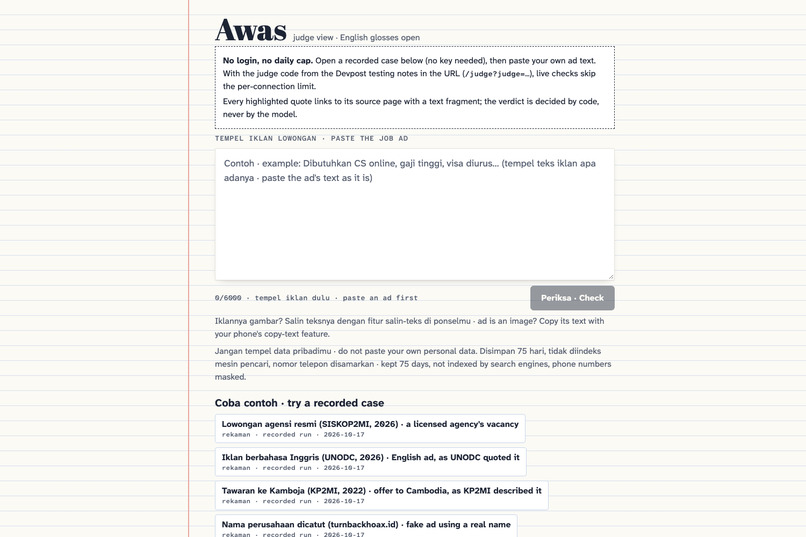
/judge: five recorded real runs to open with no key, each dated, or paste your own ad. Highlighted quotes link to their source page.
-
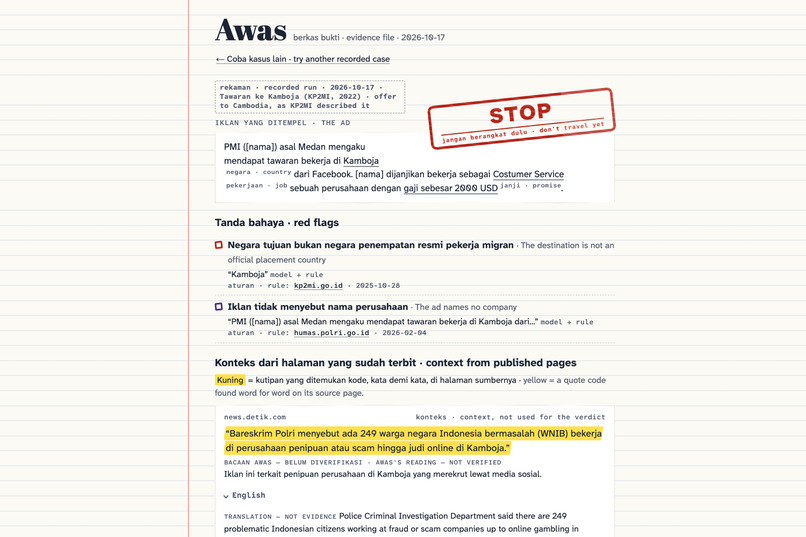
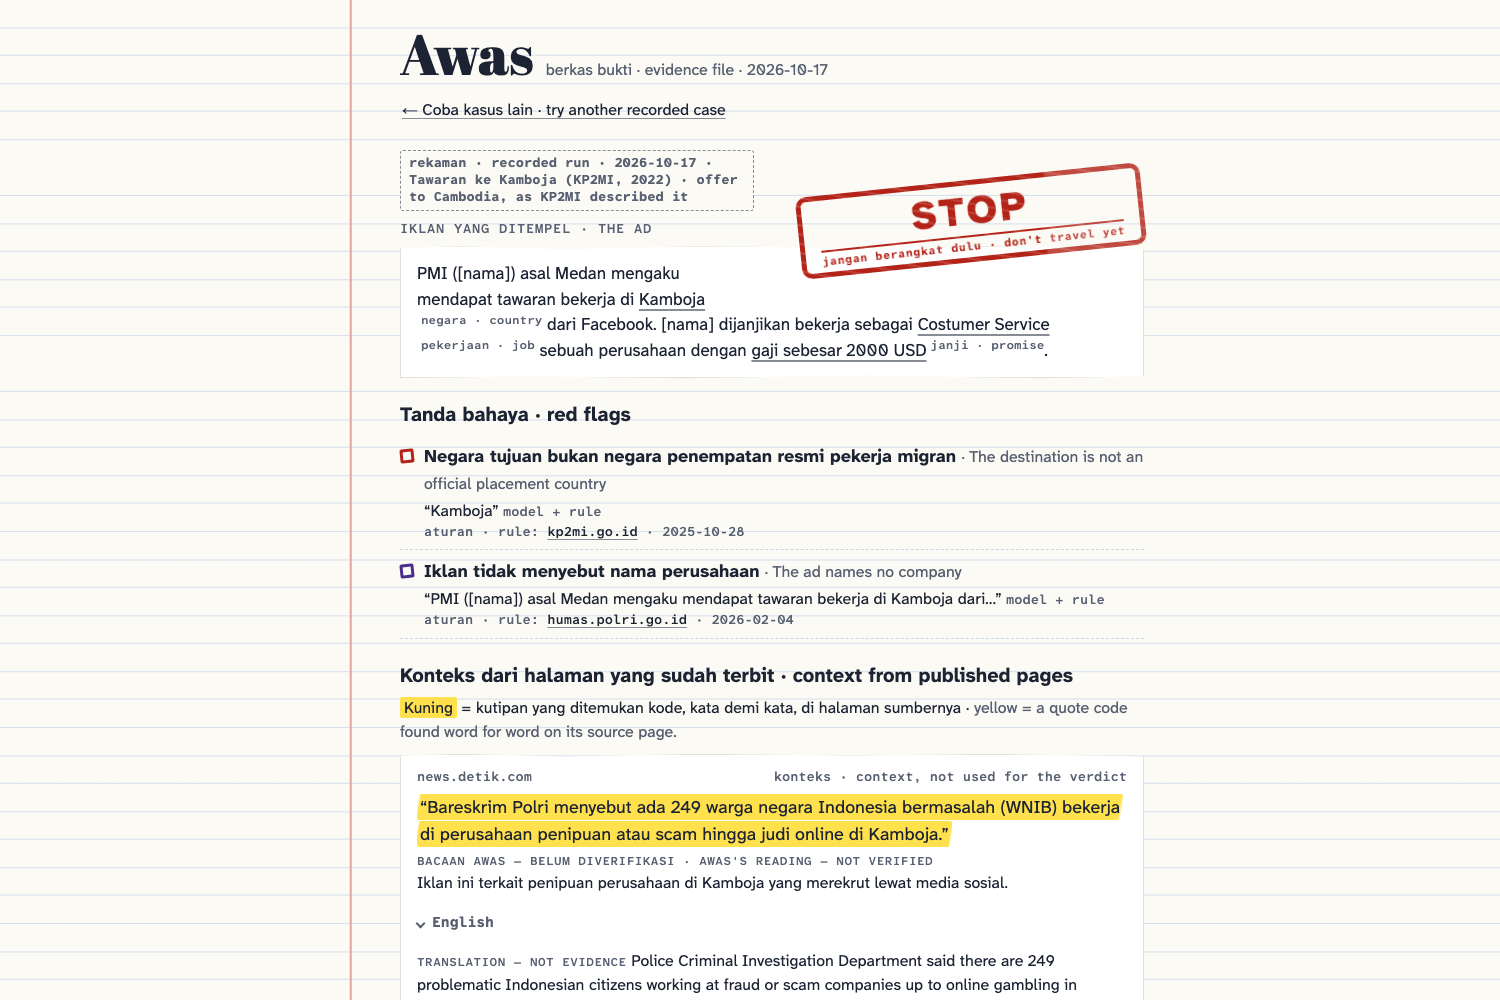
A recorded case: the pasted offer, red flags quoting official pages, a source line highlighted where code found it. Verdict: STOP
-
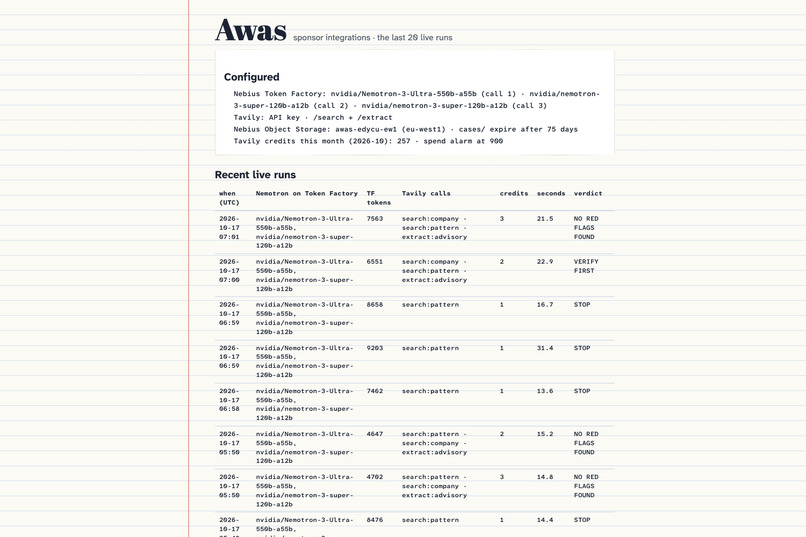
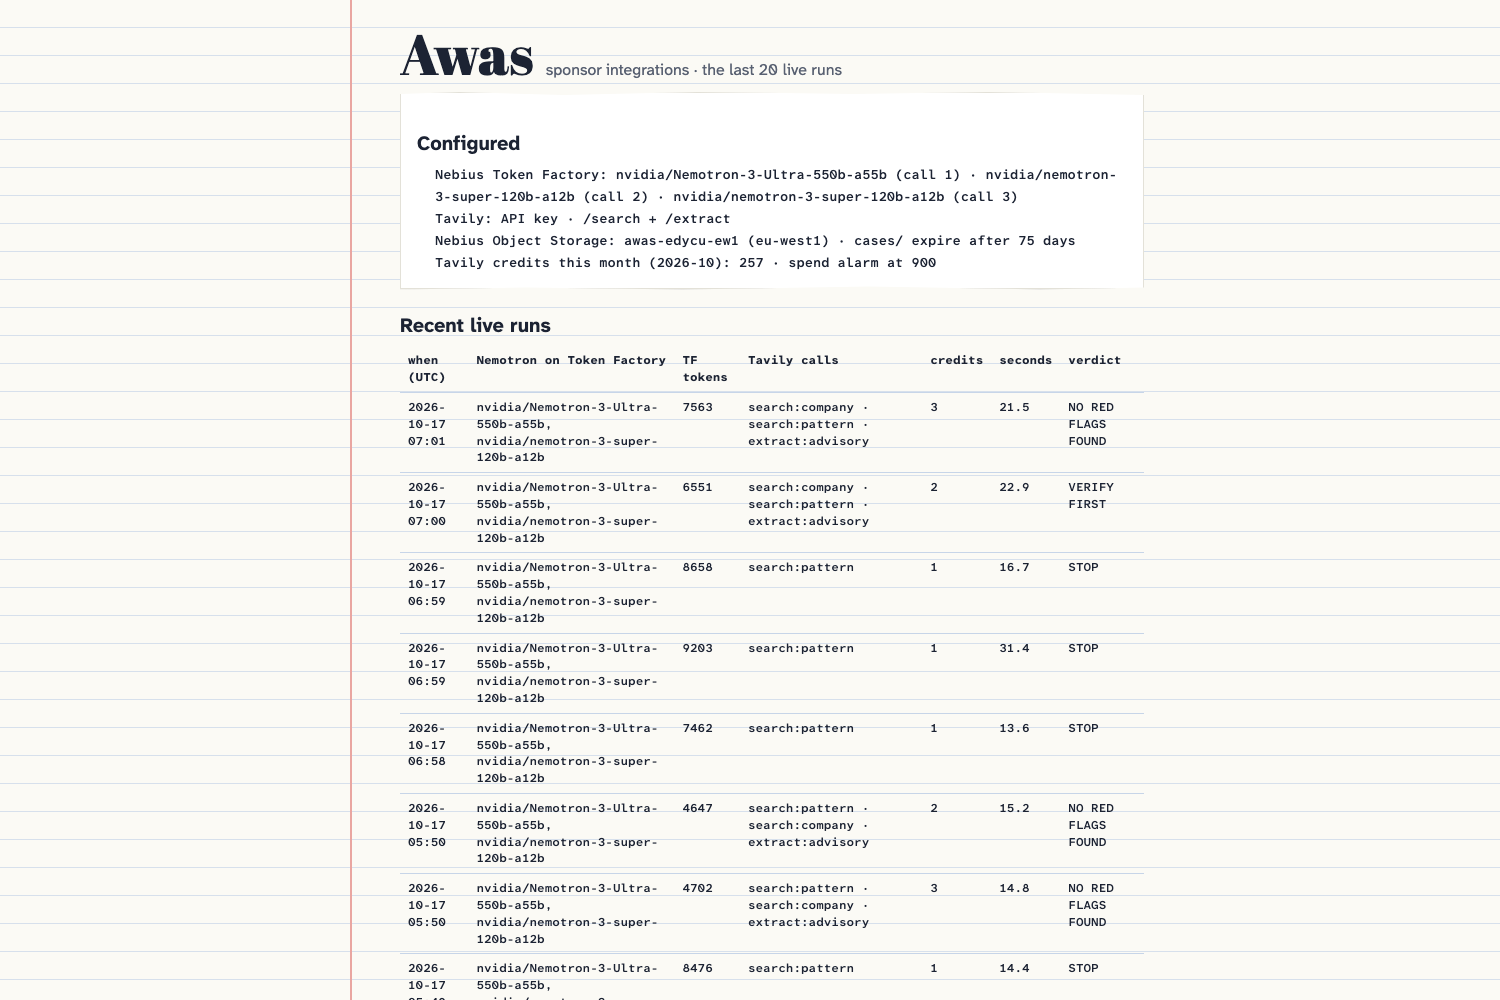
/integrations: the last live runs, with the Nemotron models on Token Factory, the Tavily calls, credits spent, seconds and the verdict
-
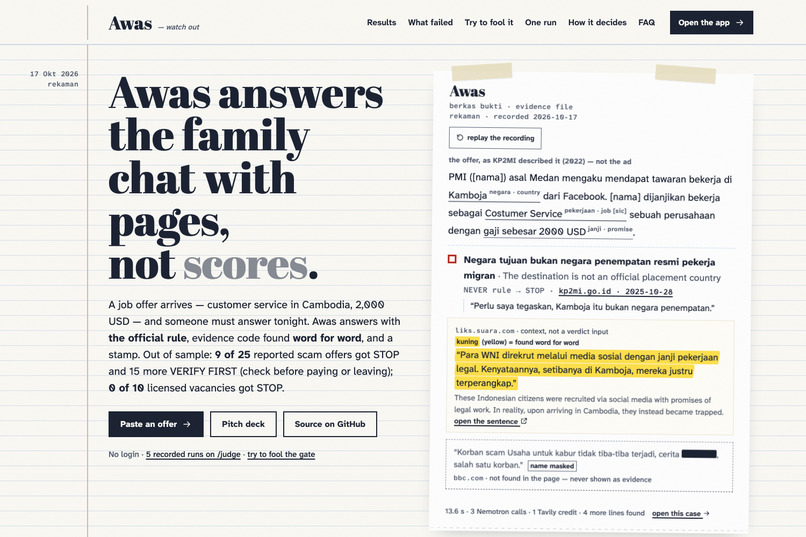
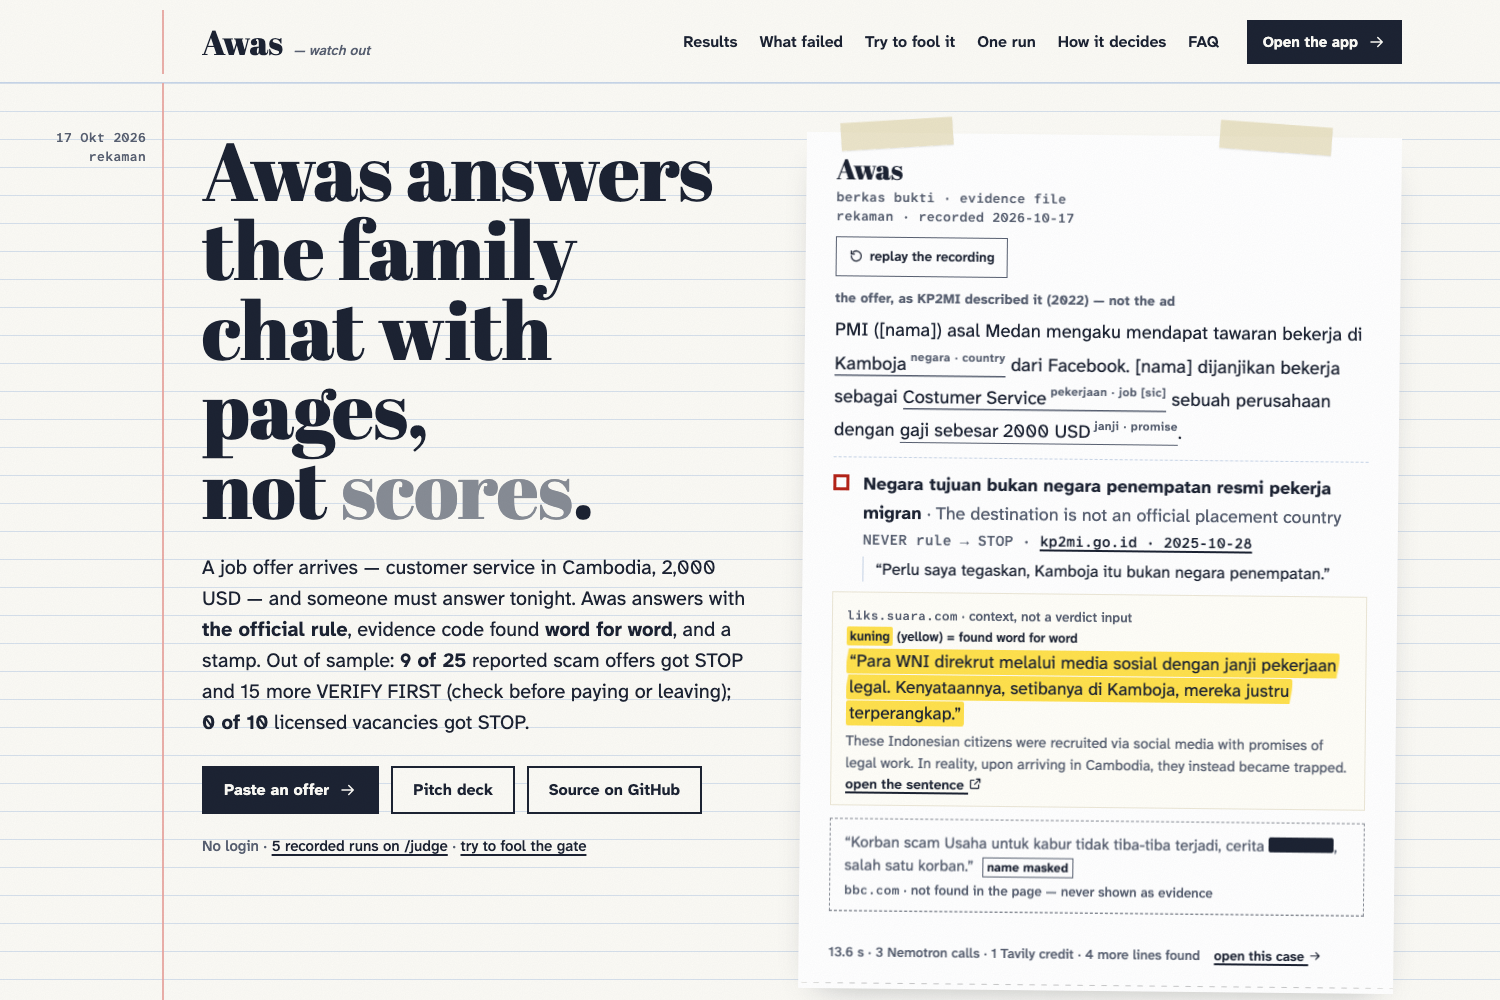
/about: the story page. Awas answers with the official rule, a quote found word for word and a stamp, not a score
-
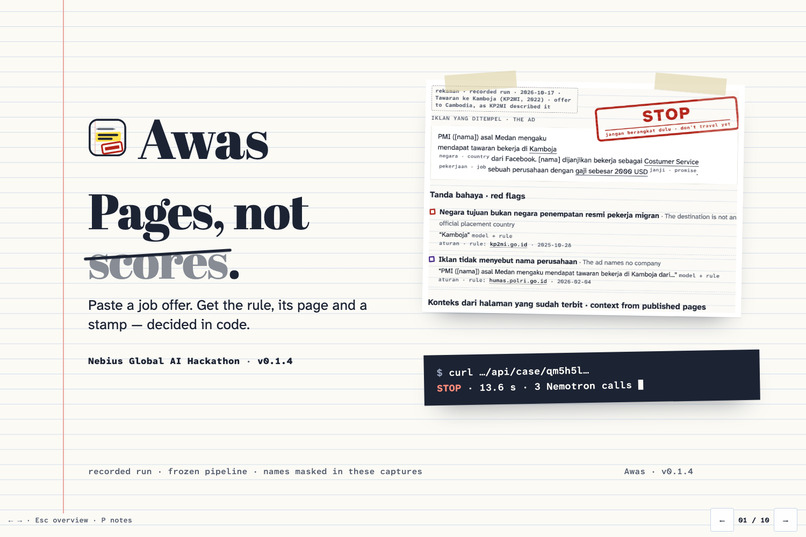
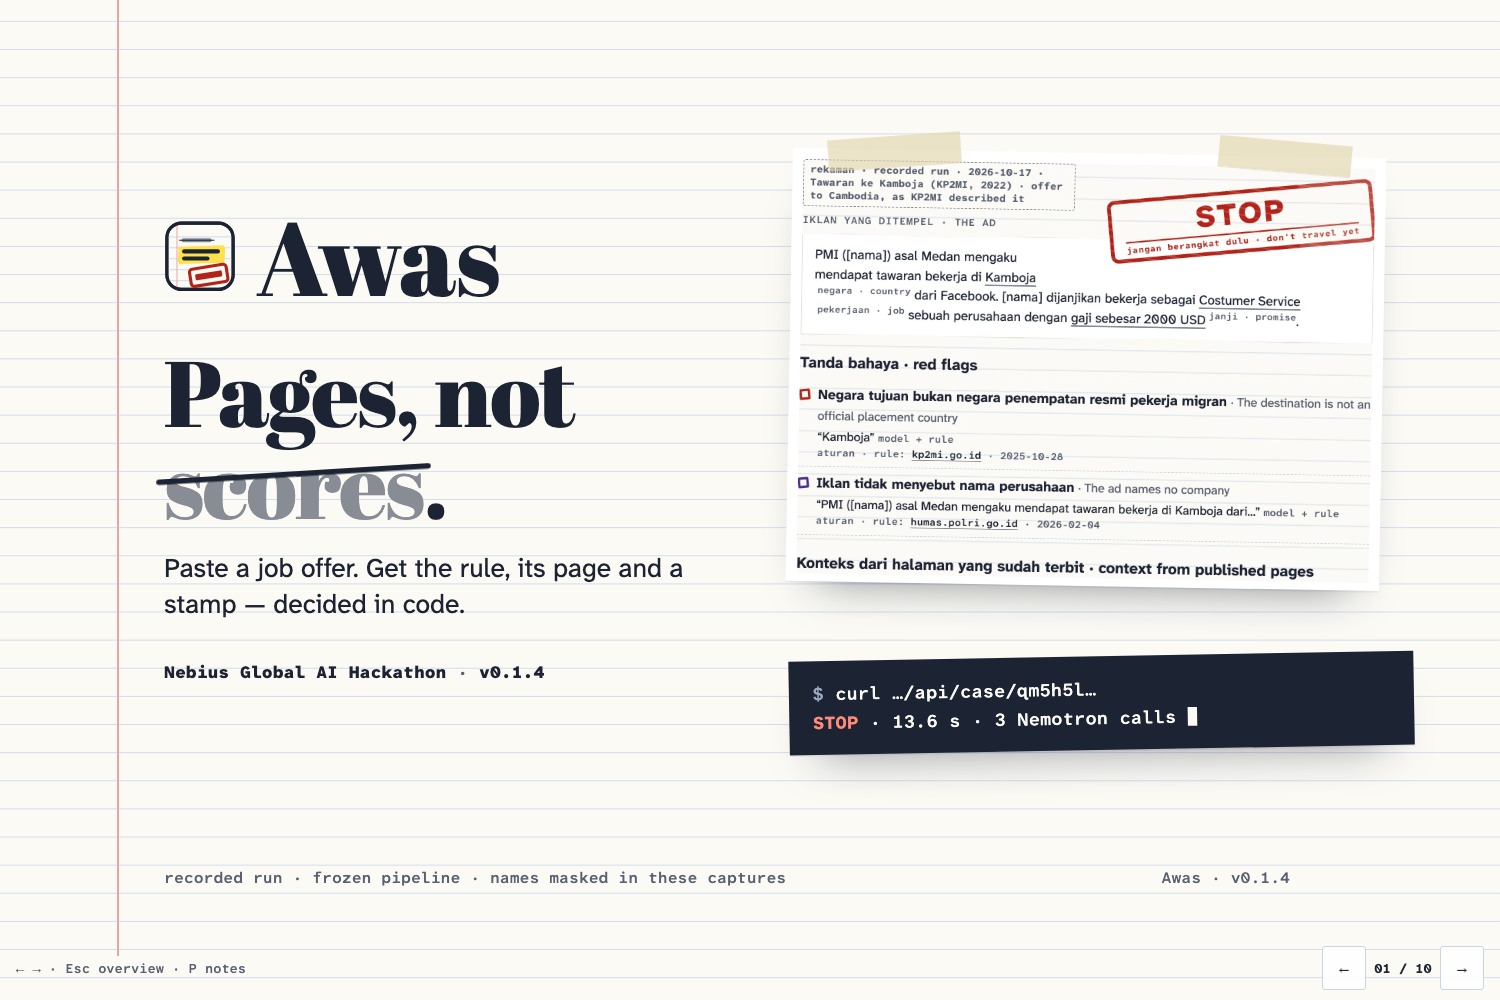
/pitch: the pitch deck, slide 1: "Pages, not scores", a recorded STOP run and its curl receipt (names masked)
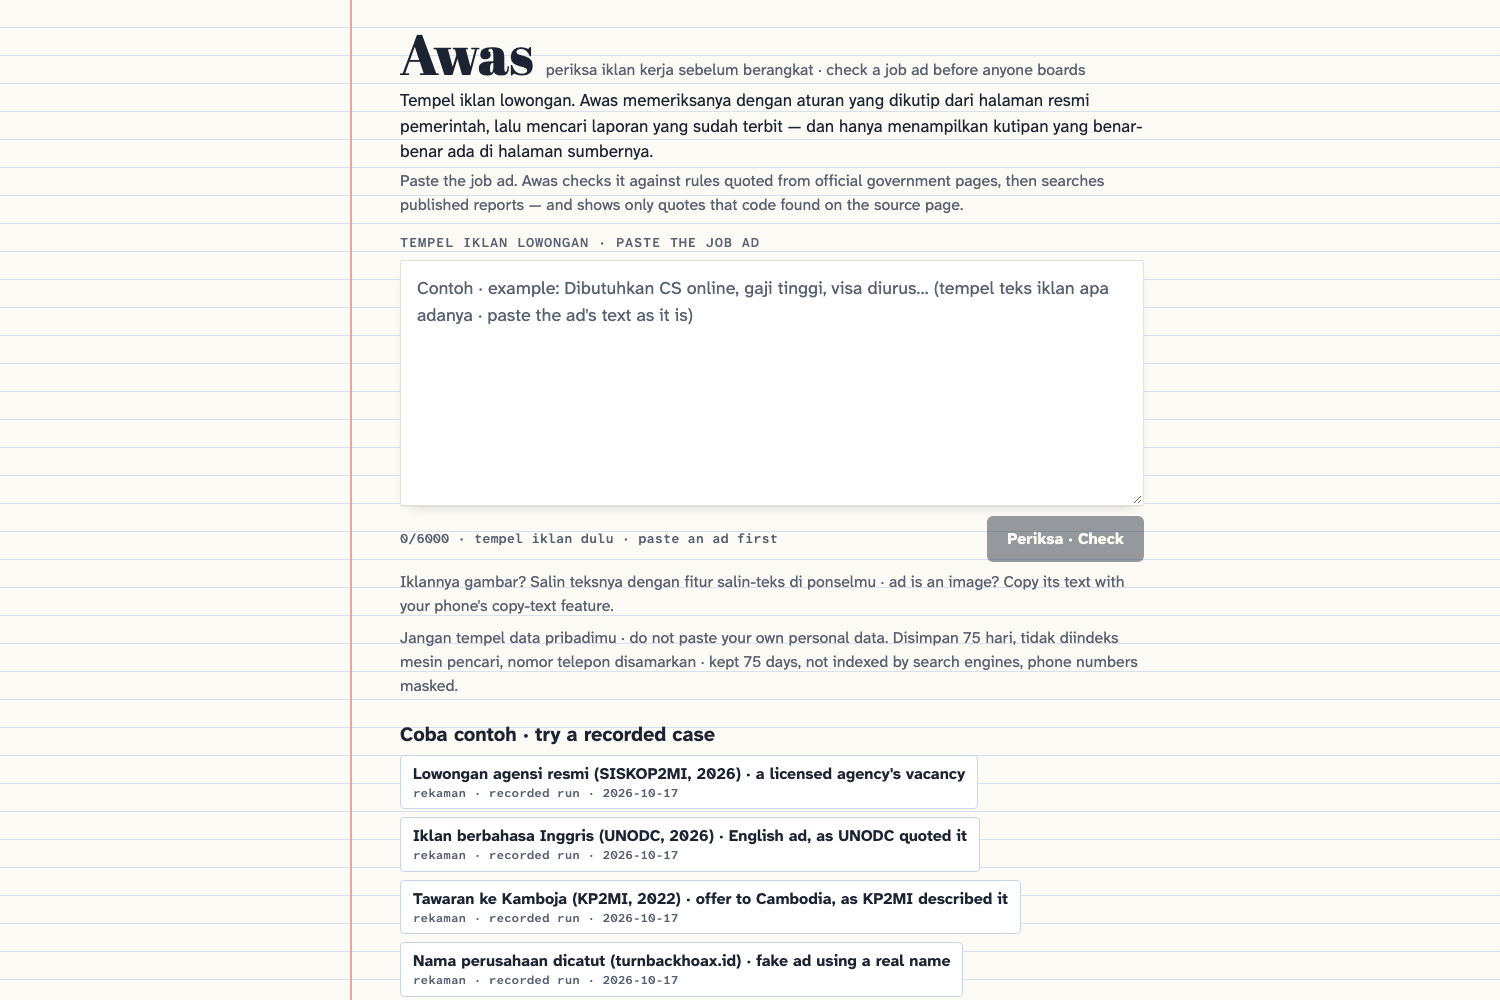
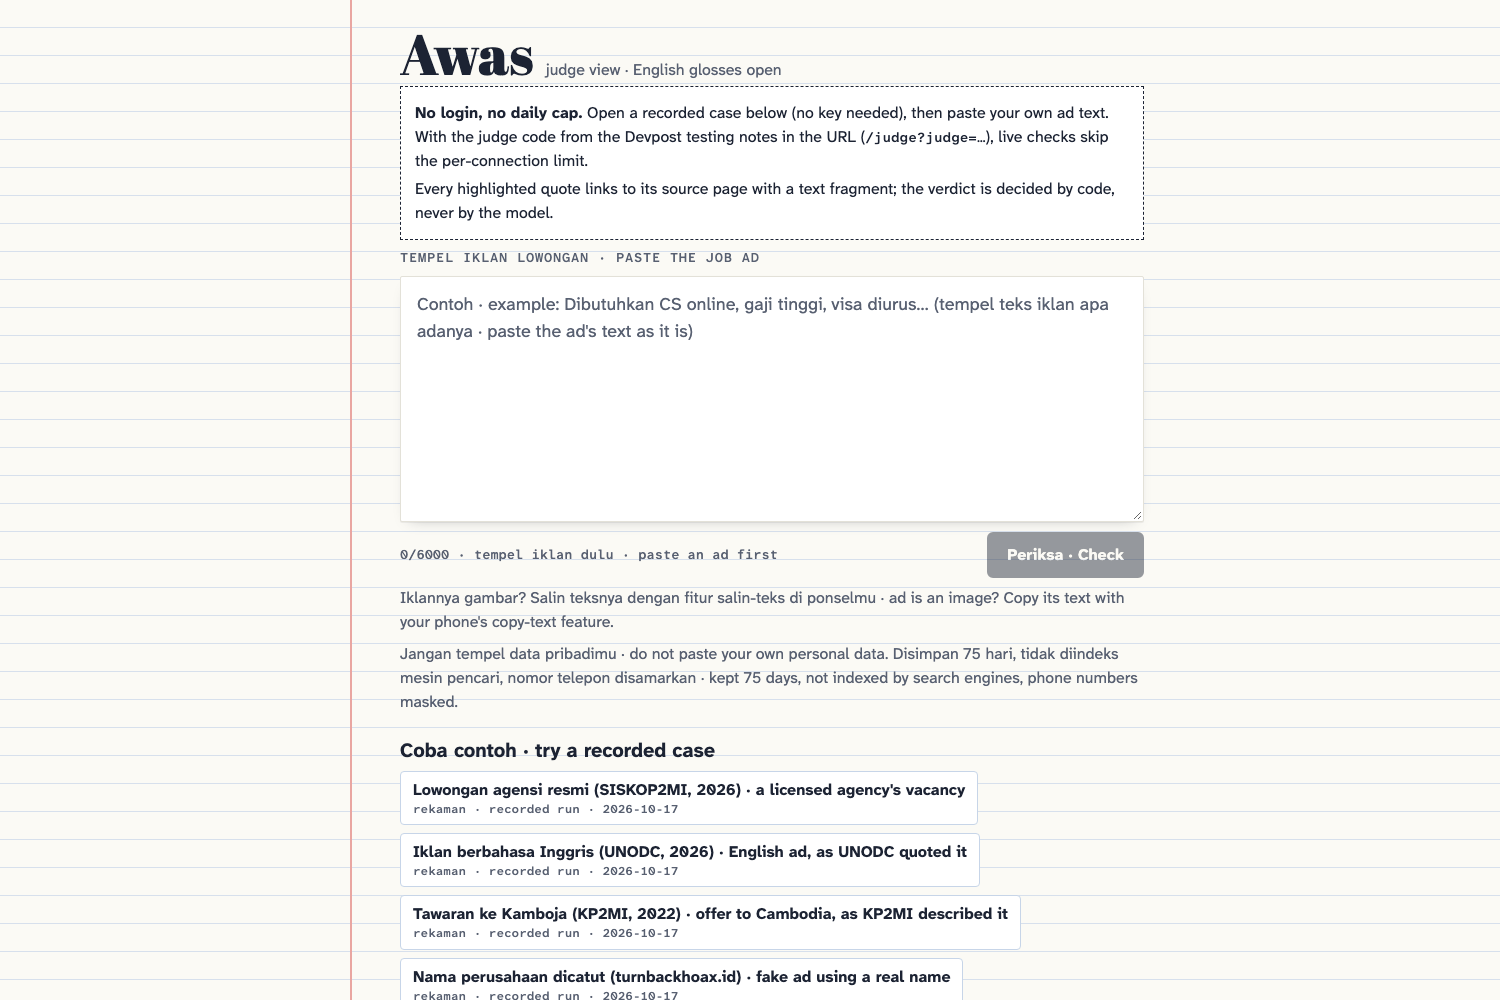
Try it in under a minute, no account: open the judge page with five recorded real runs · the live app · code, MIT · measured results · feedback on Nebius and NVIDIA · Tavily receipts · story page · pitch deck
Inspiration
A job offer arrives in a family WhatsApp group: "CS Kamboja, Rp 15 jt/bulan, visa turis OK, tiket ditanggung." Someone must tell the person who is about to board, tonight, whether to take it. The rules that would stop them exist. Cambodia is not a placement country, a tourist visa is not a work permit, a fee before a contract is a warning sign. But they are scattered across police, ministry and embassy pages, and nobody in the group can check them all in an evening. (This scene is a composite built from the pattern in published reports, not one person.)
The scale is official. Indonesia's foreign ministry reports 1,301 cases handled by its embassy in Cambodia in the first quarter of 2025, 85 % of them online scams, and more than 12,000 Indonesians affected between 2021 and 2025. The 1,301 "cases" include Indonesians who ran scams, not only victims, so Awas claims only that the offers follow a pattern that official pages describe. Each figure is quoted with its page in docs/SOURCES.md in the repository. Most scam checkers we looked at (named in docs/COMPARISON.md) give a score or a safe/unsafe label. We wanted a file of evidence instead, where every line can be re-checked.
What it does
You paste the text of an overseas job ad. Awas returns an evidence file and one of three outcomes: STOP, VERIFY FIRST, or NO RED FLAGS FOUND (explicitly "not a guarantee", never "safe"). There is no score.
- Extract. Nemotron 3 Ultra on Nebius Token Factory copies typed fields (company, destination, job, visa, fees, promises, phones) out of the ad. Code checks that each field is literally in the ad.
- Rubric. Fixed rules, each quoting an official page: a job in Cambodia or Myanmar (not placement countries, per the migrant-worker ministry), a tourist visa for work, a fee before a contract and a held passport are STOP rules. The police checklist's fast departure, high pay for light work, costs advanced then deducted, no company named, and any fee are VERIFY FIRST rules. A named Indonesian company is looked up in a dated snapshot of the official licensed-agency (P3MI) list.
- Search. Tavily searches for published pages naming this exact company or number, and for reporting on job scams to the same destination, and extracts passages from official advisory pages. This is context for the family and never an input to a rule flag; a verified line can raise a verdict, which happened once in the 25 held-out cases.
- Propose. Nemotron 3 Super proposes evidence lines as a URL, a quote and a claim, over the pages Tavily returned in this run.
- Quote gate. Code accepts a quote only if it is a verbatim substring (after normalisation) of the page text fetched in this run. A line that fails is dropped, visibly, on screen. Anyone can re-check with scripts/verify_quotes.py in the repository: on the held-out run 33 of 48 shown quotes were re-found by that script; the other 15 need a browser (14 pages refuse scripts or are PDF/JavaScript pages) or had changed since fetch (1), see DEMO.md section 4.
- Verdict by code, not by model. The verdict comes from the rubric flags, the verified lines and any failed step.
- Family message. A short Bahasa Indonesia message built only from verified lines, with a link to the source of each.
How we built it
- App: Next.js 15, TypeScript and Tailwind 4, deployed on Vercel at awas.edycu.dev.
- Models, routed per call on Nebius Token Factory: Nemotron 3 Ultra (nvidia/Nemotron-3-Ultra-550b-a55b) extracts the fields; Nemotron 3 Super (nvidia/nemotron-3-super-120b-a12b) proposes the evidence lines and writes the family message. A strict json_schema is used for extraction and proposals; the family message uses json_object.
- Retrieval: Tavily /search (exact-phrase and pattern searches) runs on every check that reaches the search step (35 of 35 held-out checks), and /extract runs when a search returns an official advisory page (10 of 35 held-out checks). Every Tavily call and its credit cost is shown on the evidence card and on the /integrations page.
- State: Nebius Object Storage over the S3 API with SigV4: evidence packs, per-connection rate slots (a conditional create that returns 412 on a repeat), recorded samples, and the benchmark job's results. There is no database.
- Benchmark on Nebius compute: the held-out tranche ran as a Nebius Serverless Job (job aijob-e03nhcfcwc4vnee33m, uk-south1, cpu-d3, created with POST /ai/v1/jobs) against the production app. The job held no Nebius or model-provider credential, only the app's bench secret and two presigned upload URLs.
- Reuse: the Nebius client libraries (src/lib/nebius/) are copied from the author's earlier hackathon project, faultline.
- Quality: 341 vitest tests (100 % statement, branch, function and line coverage of src/lib), 96 pytest tests for the scripts and 56 Playwright tests that need no credentials; lint, typecheck, npm audit and a gitleaks scan pass in CI on later commits (since the code freeze, the verdict code in src/lib changed only by the verdict-neutral phone-masking fix, docs/proof/p0-3-verdict-neutral-2026-10-18.json, plus tests).
How we used NVIDIA and Nebius
| Surface | What Awas does with it |
|---|---|
| NVIDIA Nemotron 3 Ultra on Nebius Token Factory (POST /v1/chat/completions) | Call 1: reads the pasted ad into typed fields. Chosen for 84.8 % field accuracy on 25 Indonesian texts, against Super 70.7 % and Lightning 59.6 %, measured against labels our build agent drafted and a human reviewed (25 of 25 rows, none changed) |
| NVIDIA Nemotron 3 Super on Nebius Token Factory | Call 2: proposes evidence lines. Call 3: writes the family message from verified lines only |
| Tavily /search and /extract | Runtime context searches on every check that reaches search, and advisory-page passages when an official page is found |
| Nebius Object Storage (S3 API, SigV4, conditional PutObject, presigned URLs) | Evidence packs, per-connection rate limit with no database, recorded samples, benchmark results |
| Nebius Serverless Jobs (POST /ai/v1/jobs) | Ran the frozen out-of-sample benchmark |
That is five distinct API methods: three Nebius methods (Token Factory chat completions with Nemotron models, Object Storage, Serverless Jobs) plus Tavily /search and /extract.
What Nemotron adds, if code decides the verdict. On the held-out cases, rules alone already gave 8 STOPs and full Awas gave 9, so the models' value is mostly not in the STOP count. It is in what the family reads and what the rules can see:
- The evidence file. Super proposed 54 evidence lines; the gate kept 48, each a URL plus a quote found word for word on the page, and 44 of them carry an English gloss. Without Super there is a verdict but no file to show a relative.
- The rules' inputs. Ultra's typed fields feed 14 of the 16 rules. In tranche 1 the copied visa span "bukan izin kerja hanya wisata" raised the tourist-visa flag on a tourism-only offer; the same fields can also switch a rule off, which we list under Honest limits.
- The one evidence-decided STOP. In the only report that names its company, rules plus extraction said VERIFY FIRST. Super's proposed line from another outlet's report (rri.co.id) named the company next to "bisnis TPPO"; the gate found it verbatim, and the verdict became STOP (1 of 1: the mechanism working once, not a rate).
- The family message. Call 3 writes a short Bahasa Indonesia message from verified lines only.
Measured results
Tranche 2 of a benchmark frozen before it ran, run once on code tagged code-freeze (commit d853dbe), as Nebius Serverless Job aijob-e03nhcfcwc4vnee33m. Every number is in the repository's DEMO.md and bench/ folder.
- Licensed agencies' vacancies wrongly stopped: 0 of 10. (NO RED FLAGS FOUND 9, VERIFY FIRST 1.)
- 25 publicly reported scam-recruitment cases: 9 STOP, 15 VERIFY FIRST, 1 NO RED FLAGS FOUND. Eight of the nine STOPs come from cited rules alone; the ninth is the one case whose report names the company, found through another outlet's report of the same case. One case is a single case, not a rate.
- 48 of 48 evidence lines shown are gate-verified: each a URL plus a quote the code found verbatim in the page text. Six of 54 proposed lines were dropped (11 %).
- Seconds to verdict: p50 13.7 s, p95 31.7 s. Median cost of a full check is $0.0078 in Token Factory tokens, plus 1 to 3 Tavily credits.
- Run to run: the same verdict on 20 of 20 reruns of 10 reported cases (that rerun was added after the headline run), and 19 of 20 reruns of 10 licensed vacancies.
Challenges we ran into
- Our own gate failed. Before the first benchmark run we set a gate in our own plan (it first appears in the repository history afterwards): Tavily must surface a relevant advisory or news item for at least 12 of 20 known cases. It surfaced one for 8 of 20 (read by an agent, not yet by a human). So we dropped the promise of "published reports about this company". The verdict now rests on rules quoted from official pages; the web evidence is context, and raised one verdict in the 25 held-out cases. We rescoped instead of hiding the number.
- Reports almost never name the recruiter. Of the benchmark's reported cases, 1 in the development set, 0 in tranche 1 and 1 in tranche 2 name a company. A "company-matched STOP" rate cannot be measured on that.
- Token Factory quirks. The structured-output guide's own json_schema example is refused with HTTP 422 on Super and Lightning; the API reference's name/schema/strict form works. The same low_effort reasoning setting behaves differently per model, and on Lightning it returned no answer on 2 of 2 test rows. Details are in FEEDBACK.md.
- Indonesian is on none of the model cards we could read. We measured it ourselves instead of assuming it works.
Accomplishments that we're proud of
- The model proposes, code decides. Between Nemotron and anything a reader sees there is a quote gate and a code verdict. A line that cannot be found word for word in the fetched page is dropped on screen, not hidden.
- A pre-registered benchmark we then reported honestly, including the failed coverage gate, two outlets withdrawn because their terms prohibit AI use, and the one case that fell the wrong way.
- The benchmark itself ran on Nebius, as a Serverless Job, and the rest of the stack sits on Nebius Object Storage with no database.
- Reproducible. Shown quotes can be re-checked against their source pages without Awas code (33 of the held-out run's 48 by script, the rest by opening the page); the repository has the frozen benchmark files, their hashes and the scripts.
What we learned
- A strong extraction model reading a language that no model card lists is workable, but only if the code checks every field against the source text.
- Search coverage for Indonesian official and news pages was weaker than we assumed. The reliable part of the product is the cited rules, not the web search, and the honest design follows from that.
- Nemotron 3 Super is a reasoning model: we give it generous token room because an earlier project of ours saw it spend everything thinking (the empty answers recorded in this repository are Lightning's).
What's next
- Add the Middle-East domestic-worker moratorium rule (Kepmenaker 260/2015) after judging. We left it out because its current scope was not verified, and adding it now would invalidate the held-out result.
- Benchmark the phone-number path, which is live-only and unmeasured today.
- Have a human review the labels behind the 25-text extraction test, and collect real ads from people outside the team. We have no outside users to report yet.
- Read image ads directly if Token Factory exposes image input for a Nemotron vision model.
Honest limits
- Our pre-run search-coverage gate failed (8 of 20 against a threshold of 12 set in our own plan; see Challenges); web evidence is context and raised one verdict in 25.
- The benchmark's reported cases are reporters' descriptions of offers, not the ads, so real ads may carry more red-flag wording, and the "no company named" rule fires partly because reports rarely name the company.
- Field accuracy on the 25-text extraction test (Ultra 84.8 %) is measured against labels drafted by an agent and reviewed by one human, blind to the model outputs (25 of 25 rows, none changed: bench/stage-t-review.json).
- The phone-number path is unbenchmarked. The licensed-ad set is plainer than social-media ads.
- NO RED FLAGS FOUND is never a guarantee. Awas has not been used by any outside user yet.
- Awas is a research prototype, not legal advice and not an official service.
Open source (MIT): https://github.com/edycutjong/awas · Live: https://awas.edycu.dev
Built With
- nebius-object-storage
- nebius-serverless-jobs
- nebius-token-factory
- nemotron-3-super
- nemotron-3-ultra
- next.js
- nvidia-nemotron
- playwright
- python
- tailwindcss
- tavily
- typescript
- vercel
- vitest

Log in or sign up for Devpost to join the conversation.