Inspiration
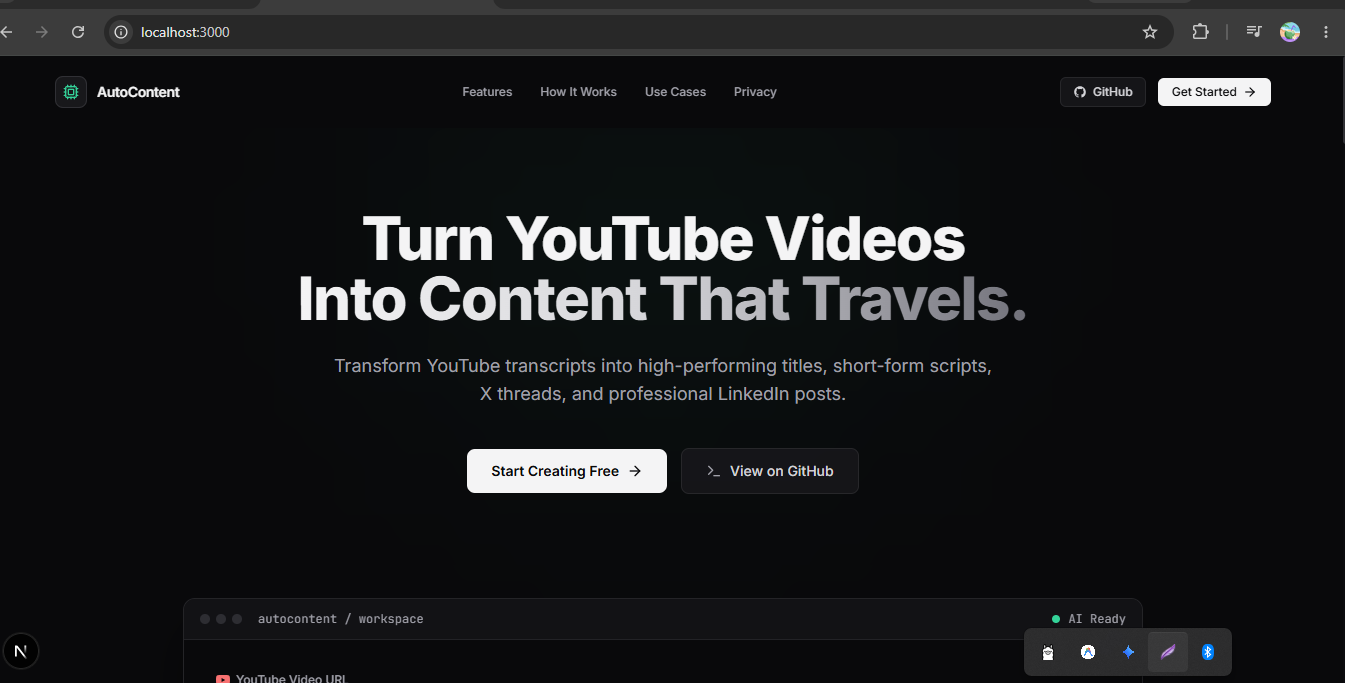
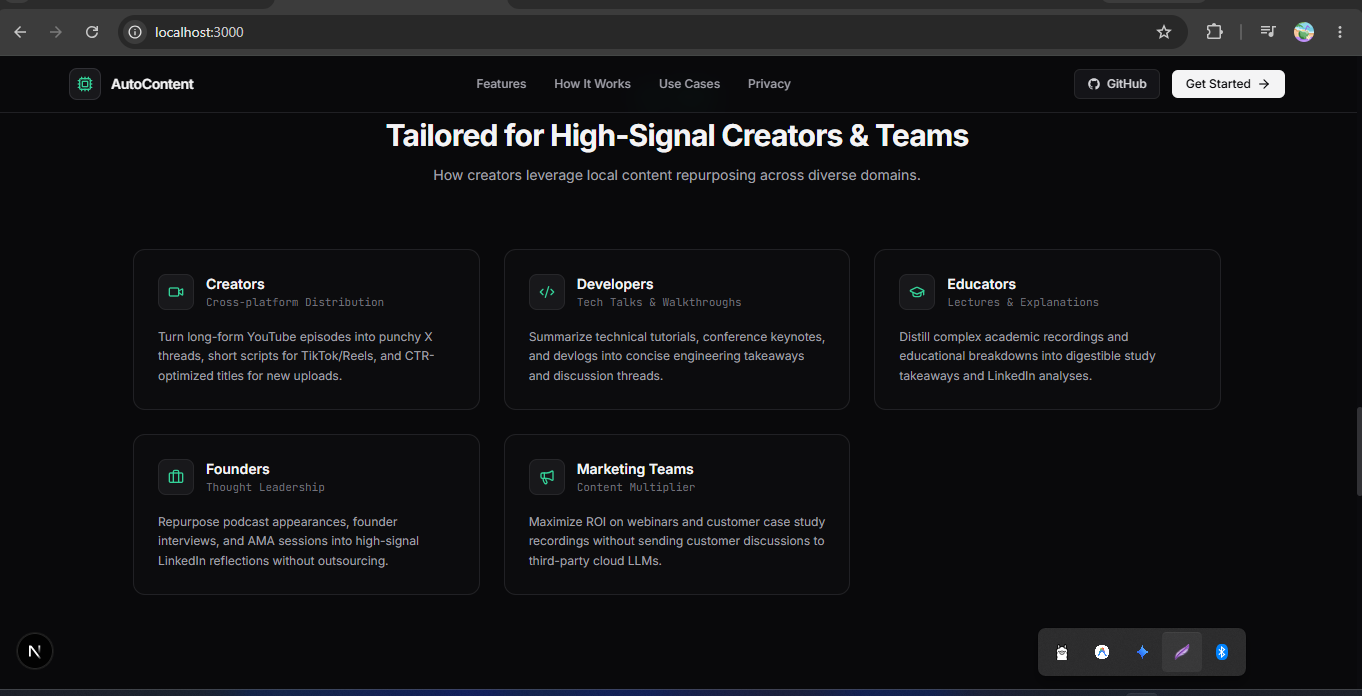
Content creators spend hours manually repurposing long-form videos into platform-specific social posts, or rely on expensive cloud SaaS tools that leak video data and run up hefty API token bills. We wanted to build a zero-cost, privacy-first alternative that lets creators generate high-impact deliverables locally on standard consumer laptops without needing high-end GPUs or paid API keys.
What it does
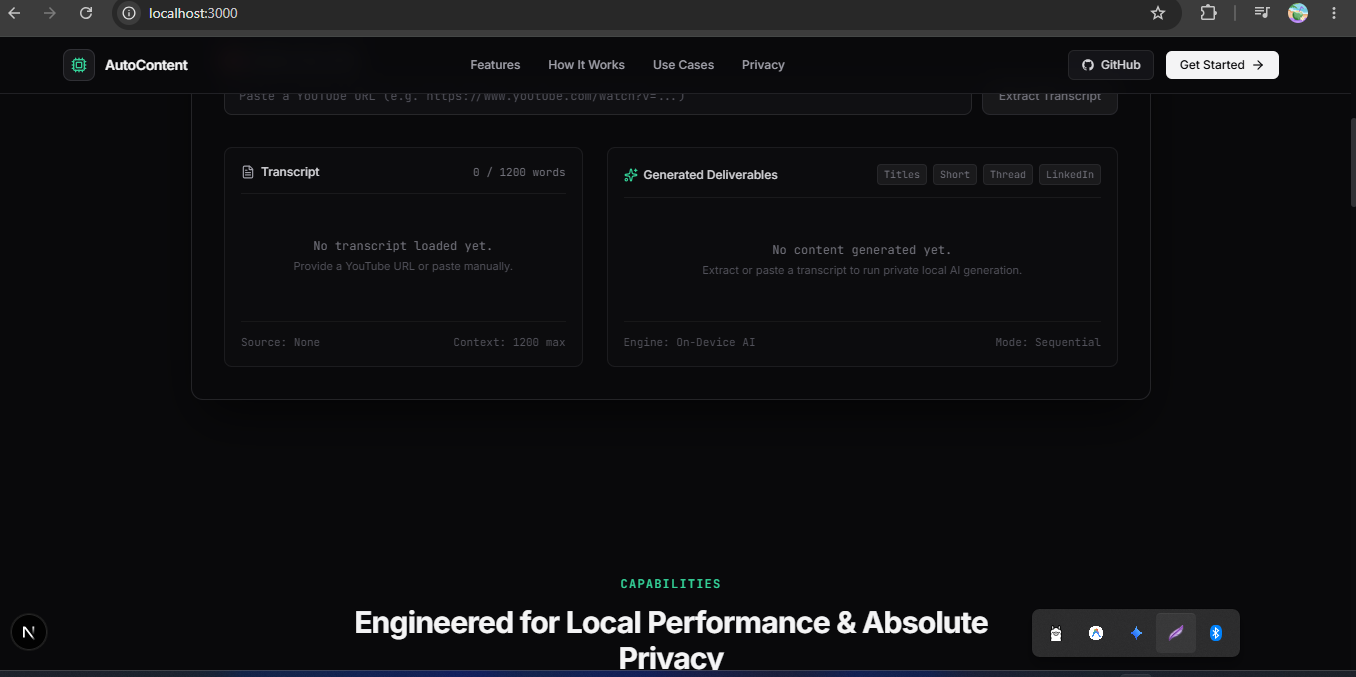
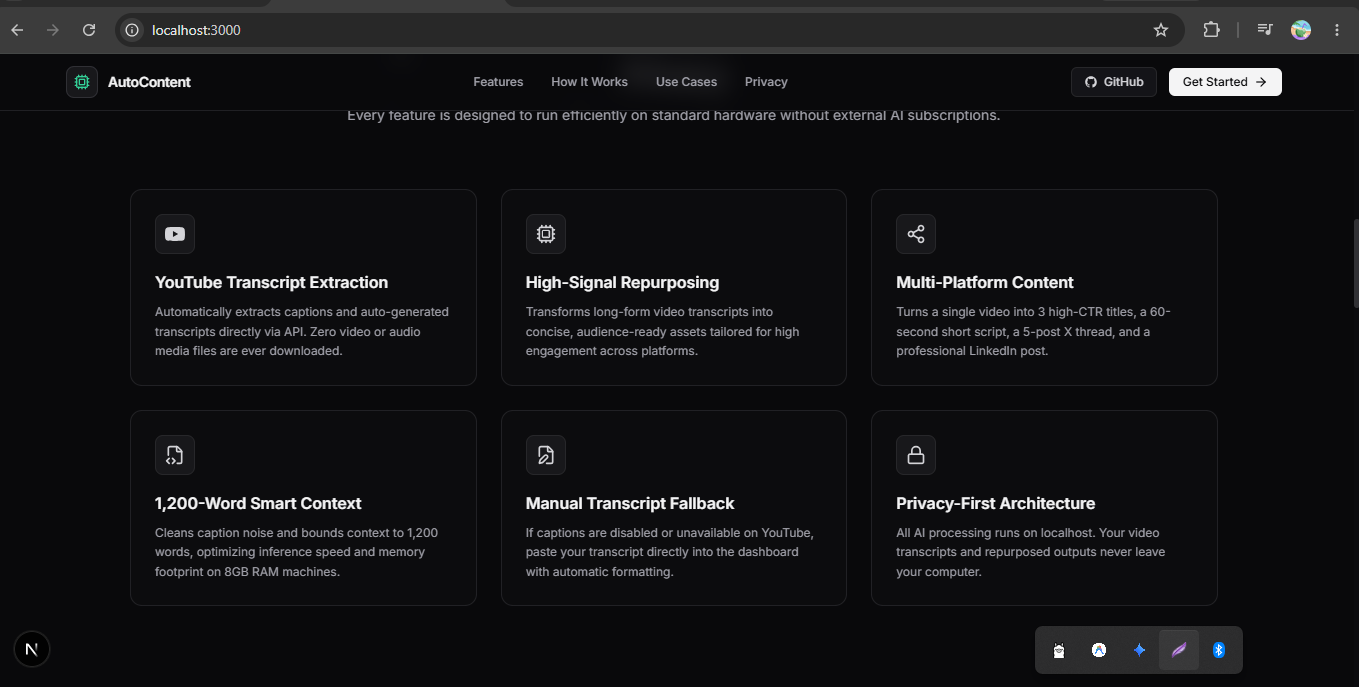
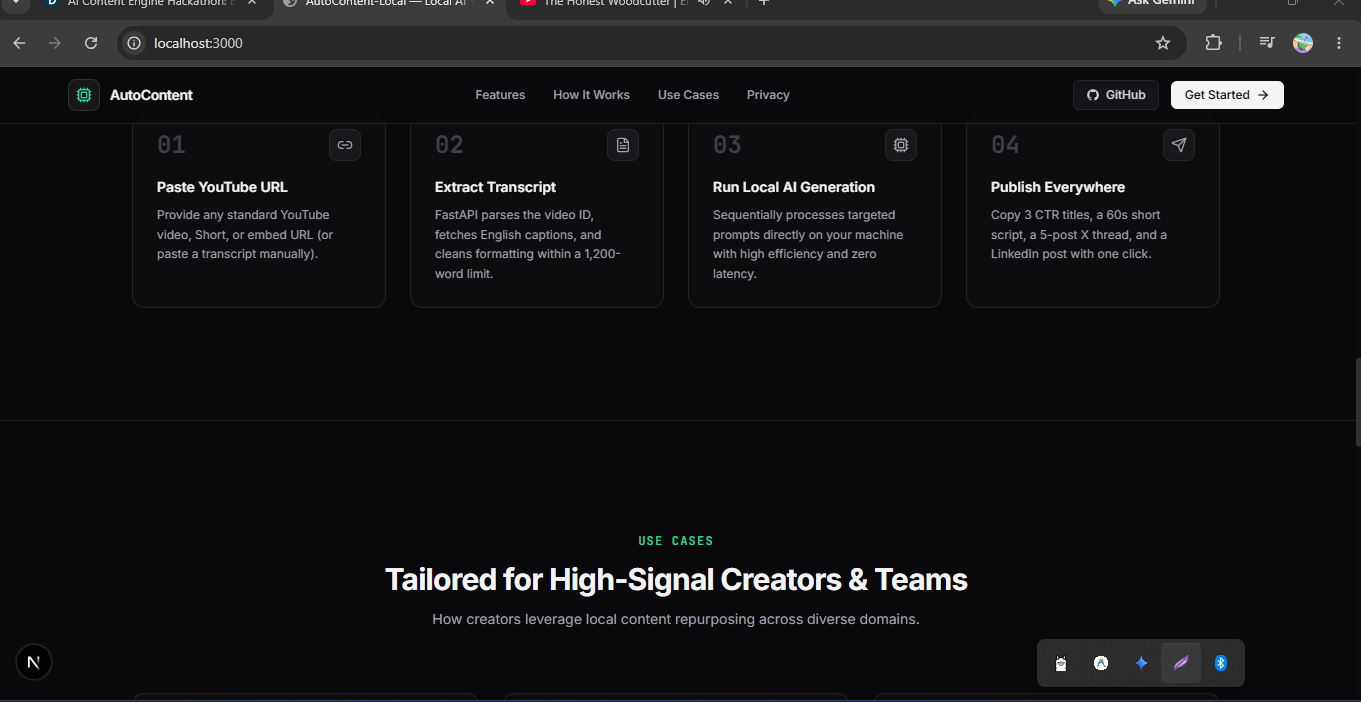
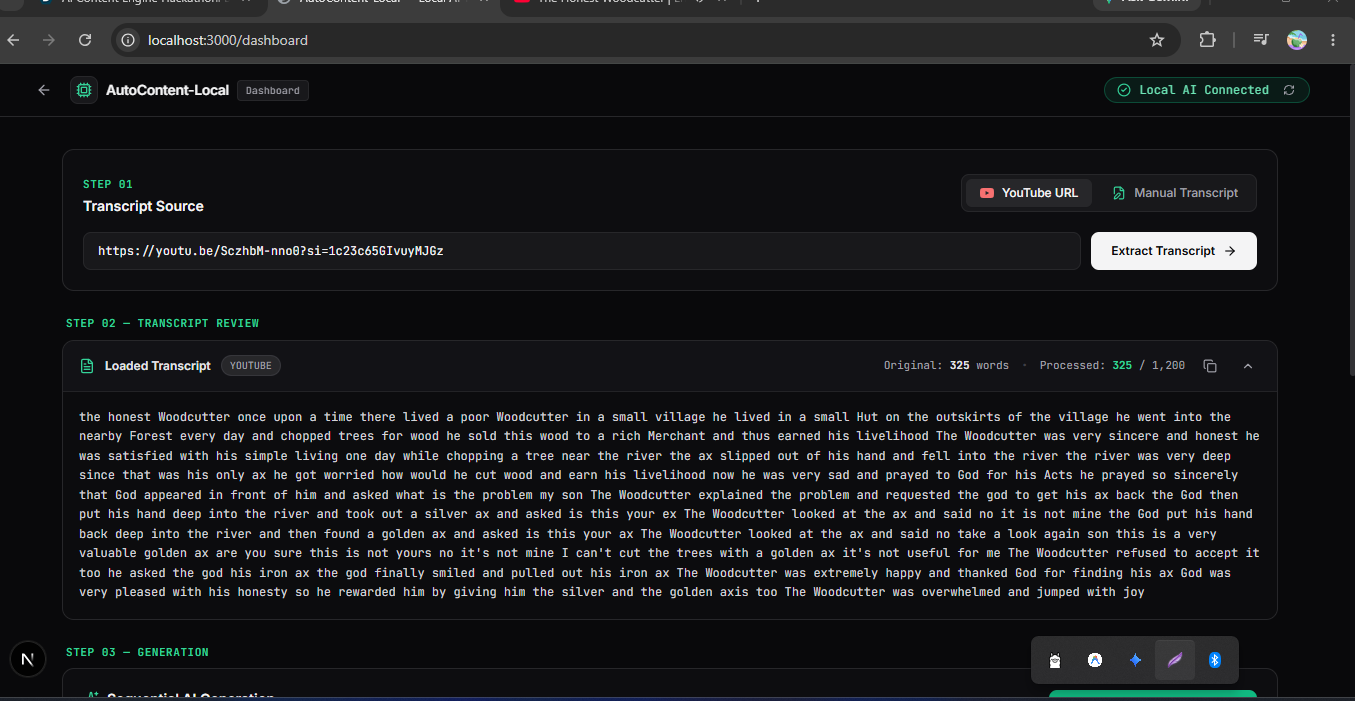
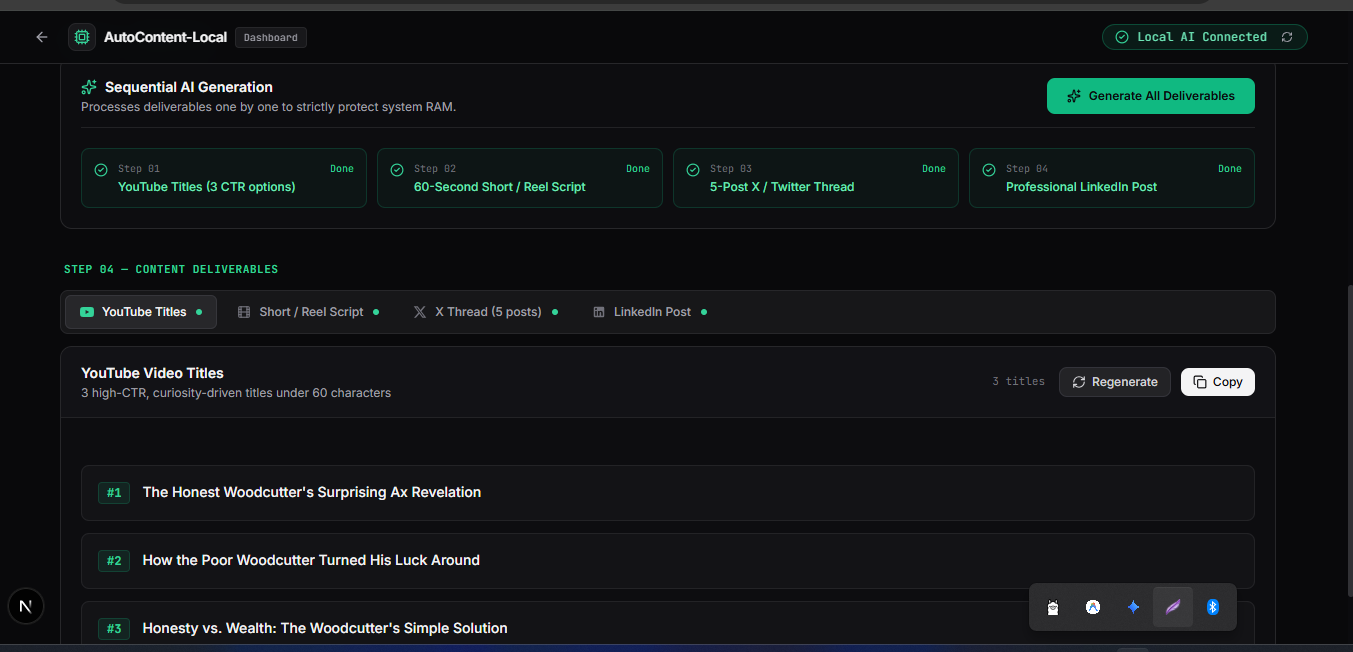
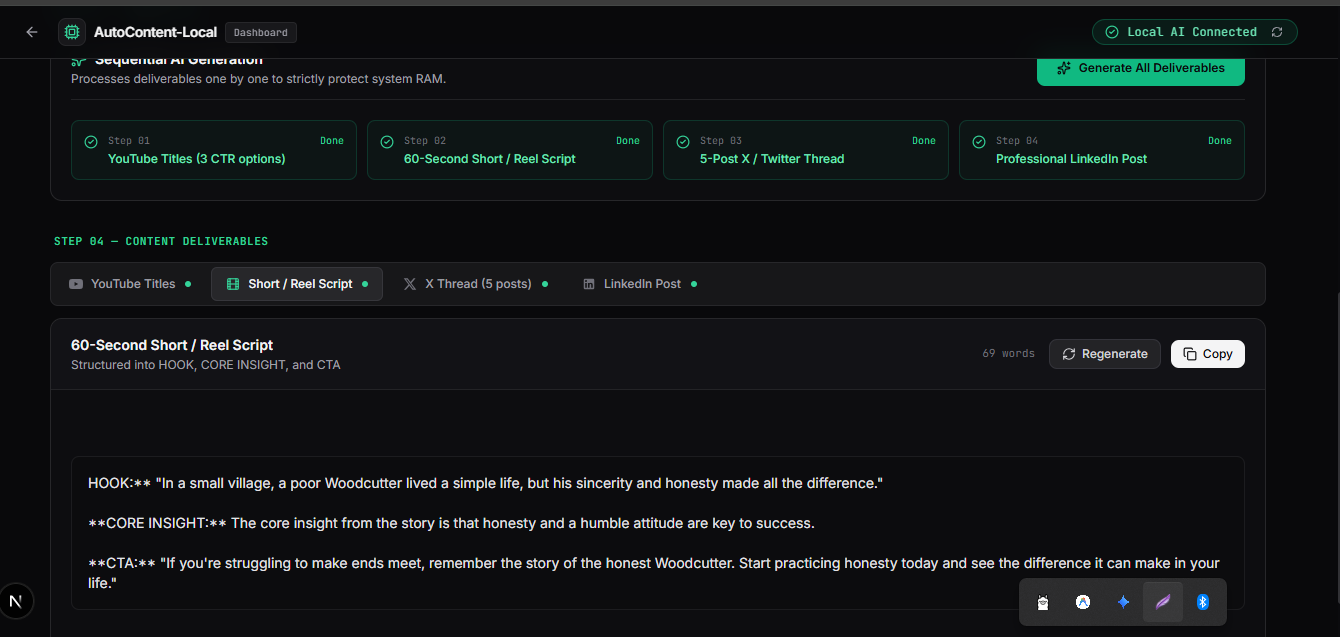
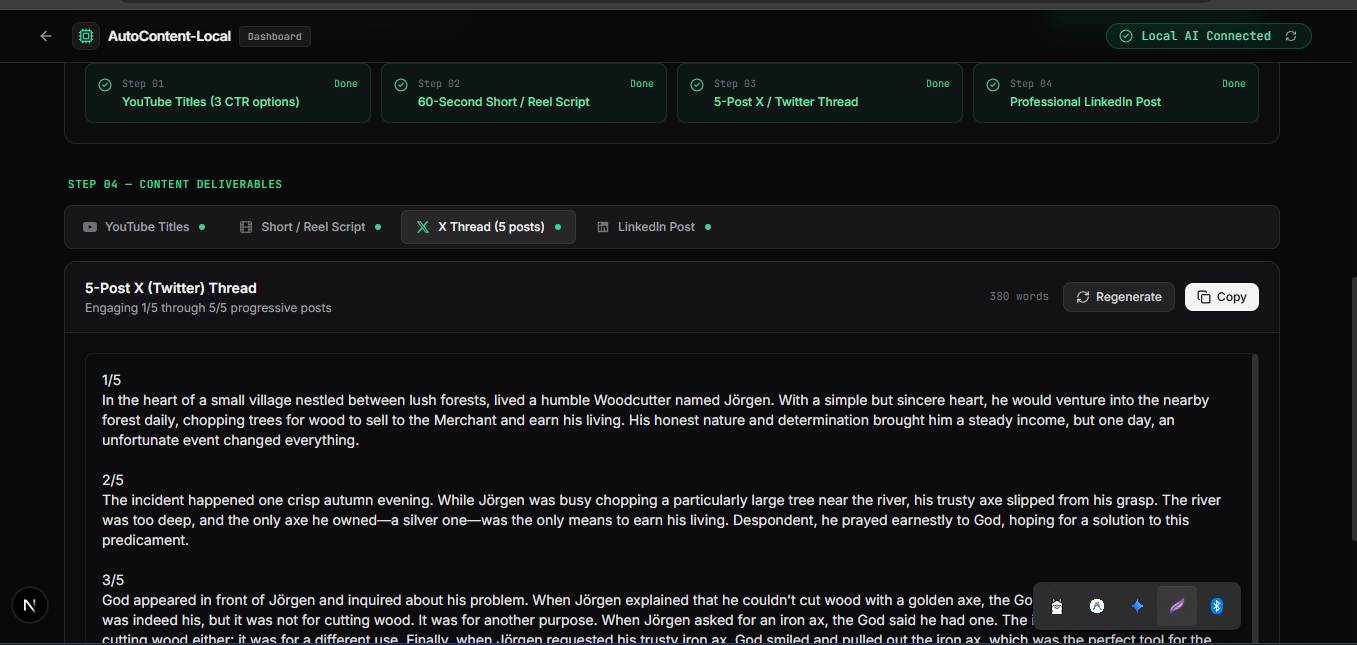
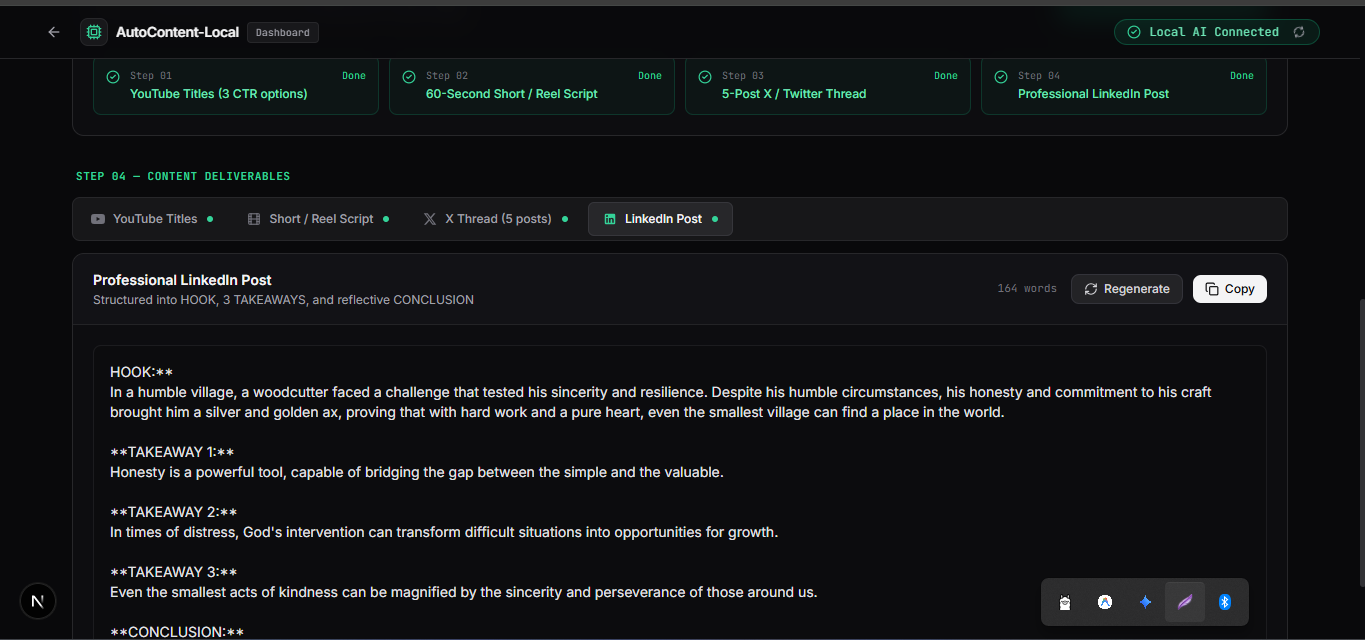
AutoContent-Local extracts YouTube caption text (with a fallback for pasted transcripts), cleans the text, enforces a strict 1,200-word limit, and leverages a local Ollama instance running qwen2.5:1.5b via FastAPI. It sequentially generates four ready-to-publish assets:
3 High-CTR YouTube Titles: Curiosity-driven, verified under 60 characters, with zero clickbait deception.
60-Second Short/Reel Script: Structured into a clear Hook, Core Insight, and Call-to-Action.
5-Post X (Twitter) Thread: A logical 1/5 through 5/5 progression crafted for readability.
Professional LinkedIn Post: Formatted with an engaging opening hook, three actionable takeaways, and a reflective conclusion.
How we built it
Frontend: Next.js (Node.js 18+) providing an intuitive creator workspace with clean empty states.
Backend: FastAPI handling input validation, caption extraction via youtube-transcript-api, noise filtering, word truncation, and output sanitization.
Local Inference: Ollama serving Qwen 2.5 1.5B over port 11434, keeping memory loads isolated from the Python process.
Testing: Pytest suite covering regex URL parsing, word-capping boundaries, and model output validation.
Challenges we ran into
Running multiple LLM generations on 8GB RAM machines without crashing or freezing was our toughest hurdle. We resolved this by never loading model weights inside Python, executing generation tasks sequentially rather than in parallel, and capping the transcript context window to 1,200 words. Fine-tuning prompts to keep a compact 1.5B model strictly adhering to formatting constraints (like exact character and thread count limits) also required rigorous sanitization layers.
Accomplishments that we're proud of
Zero Cloud Dependence: Zero paid API keys, zero cloud LLM dependencies, and 100% local data privacy.
Lightweight Footprint: Instant caption-only parsing that never downloads heavy video or audio files.
Fast Inference: Reliable multi-format social copy generated on standard consumer hardware in seconds.
What we learned
Small language models (1.5B parameters) punch well above their weight when fed tightly scoped, pre-cleaned context instead of raw, noisy transcripts. Decoupling the model runner into a separate daemon (Ollama) also dramatically improves backend memory stability.
What's next for AutoContent
Local Whisper integration for offline transcription when captions are disabled.
Direct one-click scheduling export to social media platforms.
Custom user prompt templates and tone toggles.
Built With
- fastapi
- next.js
- ollama
- pytest
- python
- qwen-2.5
- tailwind-css
- typescript

Log in or sign up for Devpost to join the conversation.