💡 Inspiration
In competitive forensics, debate, and declamation, judging delivery has traditionally been subjective and prone to adjudicator fatigue. Speakers routinely receive vague feedback like "improve vocal variety" or "fix pacing" without knowing the exact moment or mathematical reason their delivery fell short. Standard speech models only transcribe what is said, ignoring how it was delivered. We built AuraVoice to turn rhetorical speech evaluation into an objective, signal-grounded science.
⚙️ What It Does
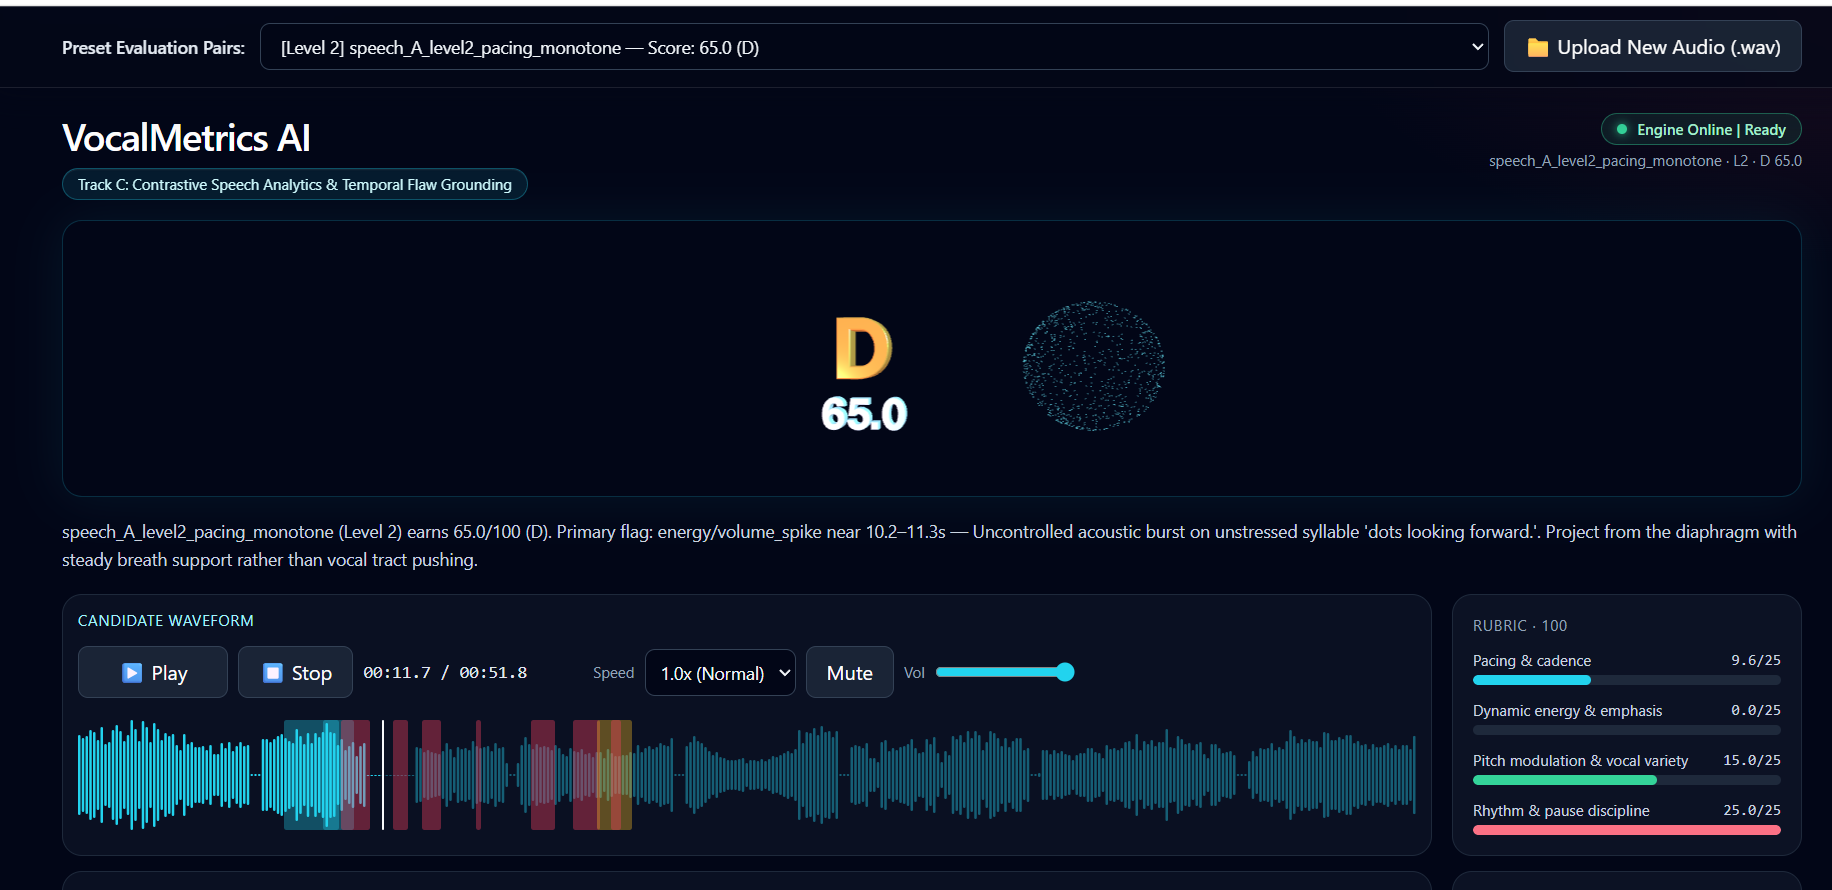
AuraVoice is an end-to-end contrastive acoustic evaluation engine:
- Contrastive Dataset Gradient: Compares candidate speech against aligned master baseline speeches across a 4-tier flaw degradation spectrum (Level 0 pristine to Level 3 botched).
- Forced Alignment: Uses PyTorch forced alignment to anchor transcript words and pauses to microsecond intervals.
- Speaker-Agnostic DSP: Extracts Pitch (F0), RMS Energy, and Cadence (WPM) with Z-score normalization to eliminate biological vocal range bias and microphone gain variance.
- Temporal Flaw Grounding: Employs word-anchored residual tracking and dynamic time warping to isolate precise anomaly boundaries [T_start, T_end].
- Causal Explainability: Translates acoustic deltas into actionable coaching feedback across an objective 4-axis rubric (Pacing, Dynamic Energy, Tonal Variety, Pause Discipline).
- Interactive Dashboard: A zero-npm FastAPI dashboard featuring WaveSurfer dual-waveform scrubbing, Chart.js time-series metrics, and an interactive Three.js 3D telemetry HUD.
🛠️ How We Built It
- Backend & Signal Processing: Python, PyTorch (MMS Alignment), Librosa, NumPy, SciPy, FastAPI, Uvicorn.
- Frontend & 3D HUD: WaveSurfer.js (with Regions plugin), Chart.js, Three.js, Tailwind CSS.
- System Governance: Token-bucket rate limiting, exponential backoff with jitter, API key rotation across Grok and Gemini, and 100% offline deterministic fallback.
🏆 Accomplishments We're Proud Of
- Maintained strict monotonic score degradation across all gradient levels (
Score(L0) > Score(L1) > Score(L2) > Score(L3)). - Achieved sub-second temporal flaw boundary precision on continuous speech streams.
- Full end-to-end test coverage passing 12/12 automated QA criteria.
🤖 AI Assistance & Transparency Disclosure
AI tools (Cursor Composer and Gemini) were utilized for architectural brainstorming, generating boilerplate API route scaffolding, synthetic text-to-speech scripting, and structuring documentation outlines. All core acoustic DSP algorithms, Z-score normalization math, DTW alignment tuning, custom rubric penalty equations, and end-to-end pipeline debugging were designed, tested, and implemented by the project author..

Log in or sign up for Devpost to join the conversation.