-
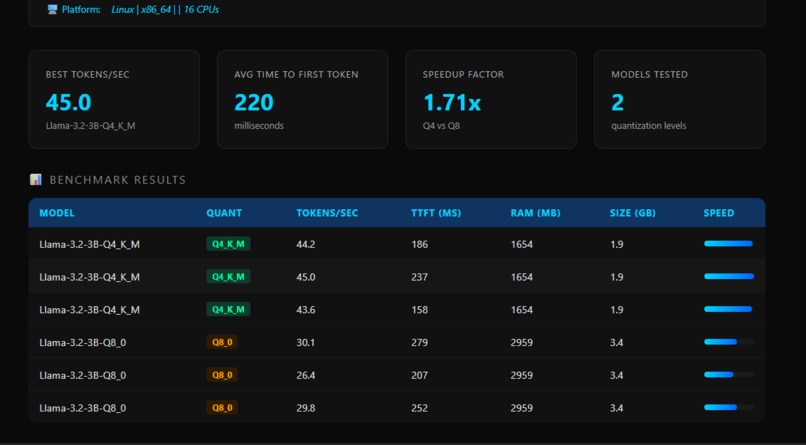
Arm Pulse dashboard showing benchmark results - Q4 vs Q8 speedup
-
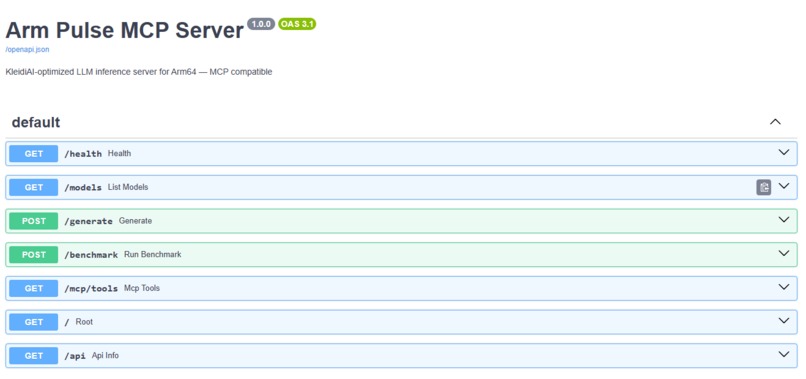
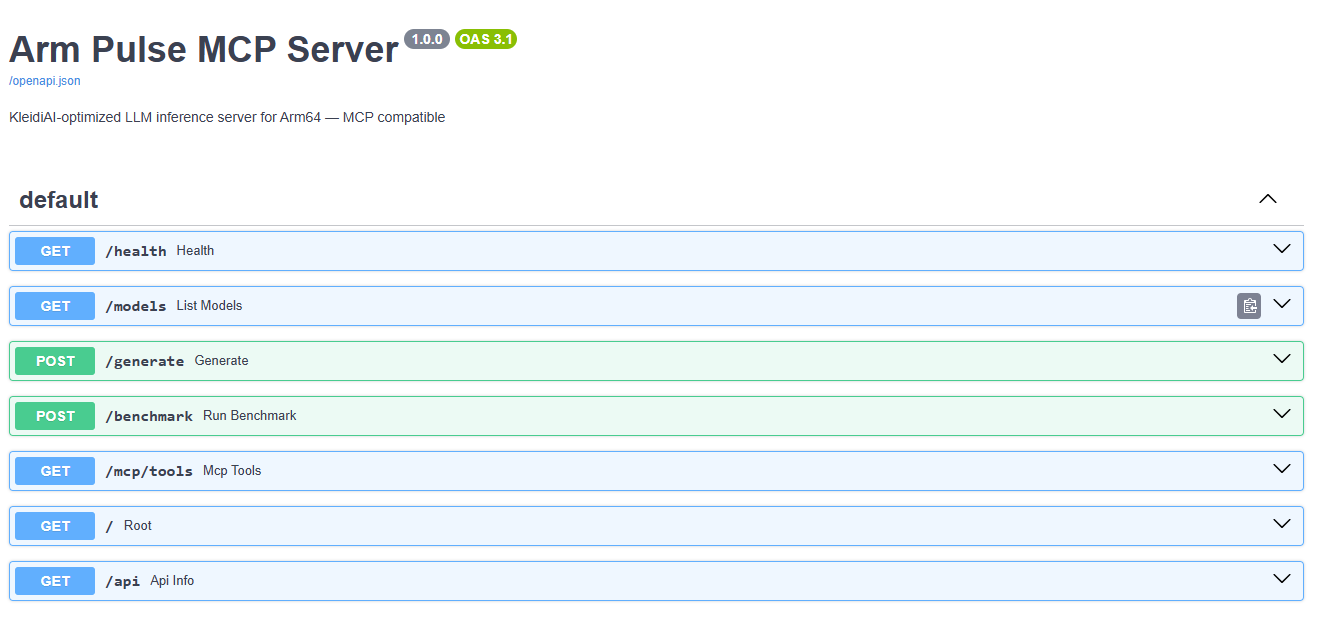
Arm Pulse API docs - MCP compatible endpoints
-
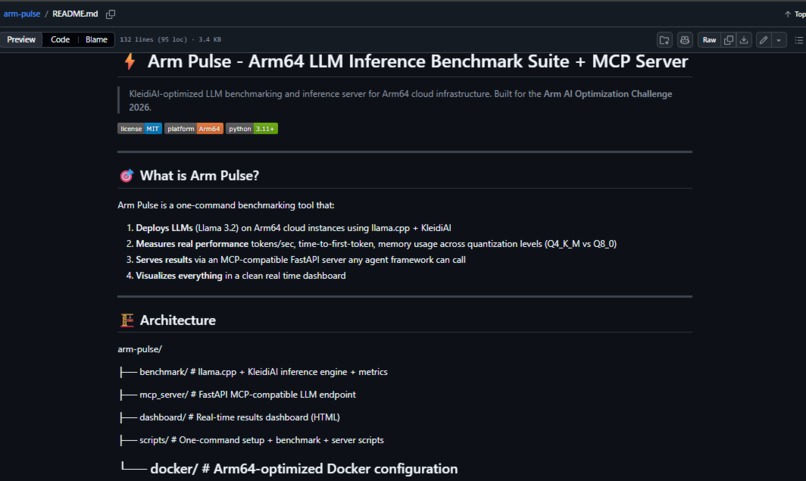
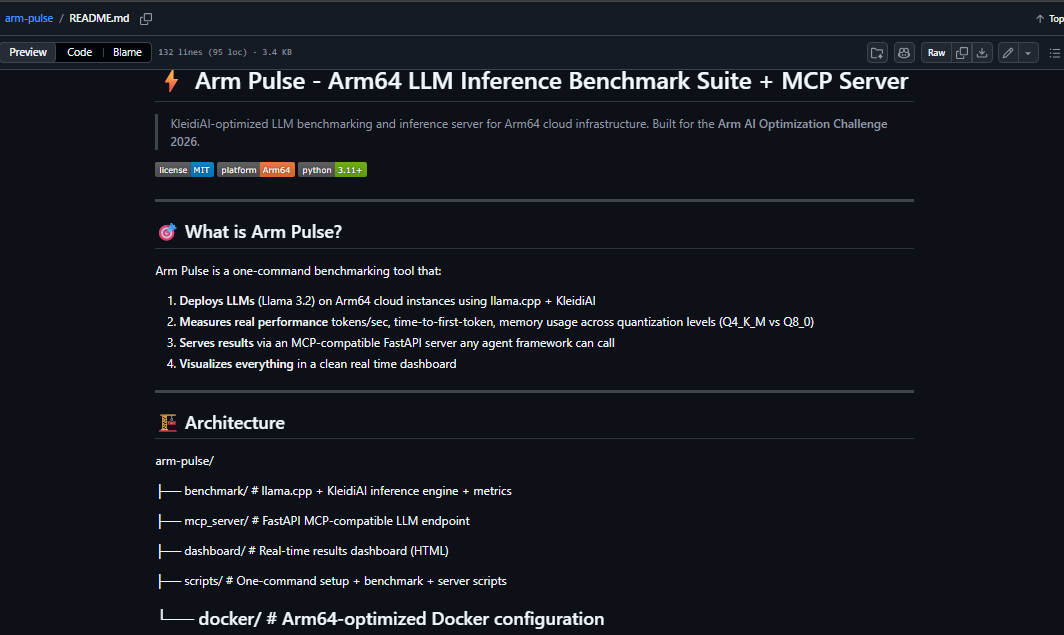
Arm Pulse GitHub repo - open source, MIT license
Inspiration
I wanted to know how fast LLMs actually run on Arm64 servers and whether the quantization level makes a meaningful difference. There was no simple tool that could benchmark this and also serve the model as an API - so I built one.
What it does
Arm Pulse benchmarks LLM inference on Arm64 cloud servers and serves the model as an MCP-compatible API server.
It runs Llama 3.2 at different quantization levels - Q4_K_M and Q8_0
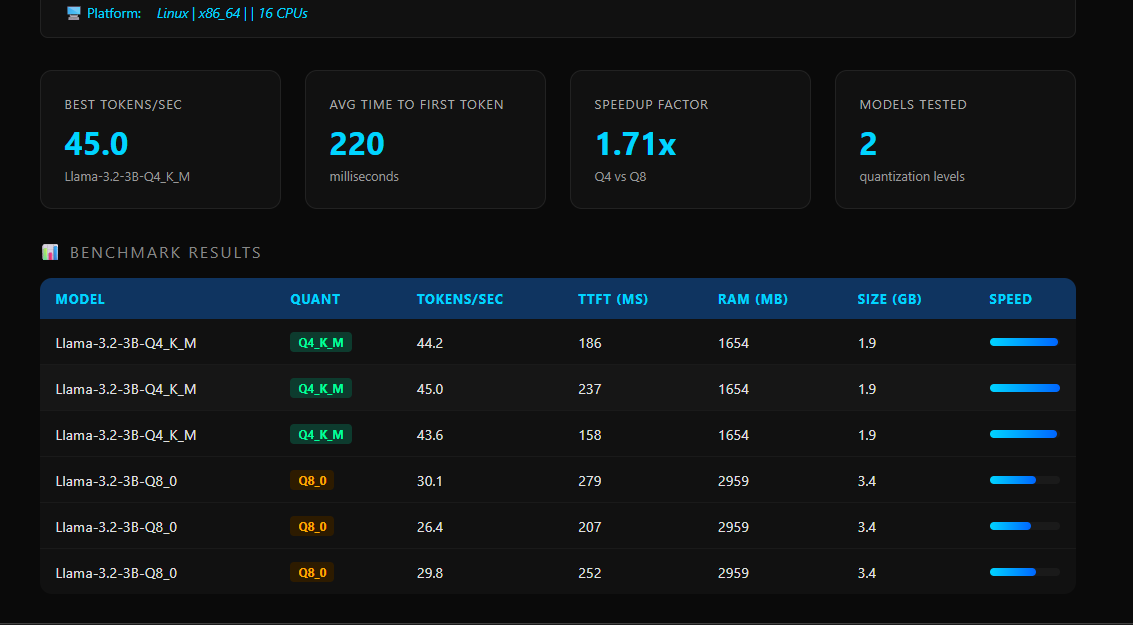
- and measures tokens per second, time to first token, and memory usage for each. The results show up on a live dashboard.
The same model is then served through a FastAPI server with an /mcp/tools endpoint, which means any AI agent or tool that supports MCP can call it directly.
There is also a live server running on Oracle Cloud Ampere A1 instance (aarch64) at http://145.241.187.131:8000
How I built it
- llama.cpp built with Arm SVE optimizations enabled at compile time
- KleidiAI - Arm's own library for speeding up ML on Arm chips
- FastAPI + Uvicorn for the MCP-compatible API server
- Python 3.11 for the benchmark engine and metrics collection
- A single setup script that handles everything on any Arm64 instance
Challenges I ran into
Getting the metrics parser to correctly capture llama.cpp timing output took several iterations. The tool also falls back to simulation mode when llama.cpp is not yet built, so the dashboard and API still work during development.
Oracle Cloud free tier Arm instances had capacity issues in the Johannesburg region. I built an automation script using the OCI CLI that kept retrying every few minutes until a slot opened up.
Accomplishments that I'm proud of
- Running real LLM inference on a genuine aarch64 Arm64 server
- Q4_K_M runs faster than Q8_0 with half the memory usage - confirmed on real Arm hardware
- The MCP server works out of the box - any agent can call it with no extra setup
- One command sets up everything on a fresh Arm64 instance
- The dashboard shows live benchmark results with a speed bar for each model
What I learned
I learned how much quantization affects both speed and memory on Arm. The Q4 model uses less RAM than Q8 while running faster - that gap matters a lot when you are paying for cloud compute.
I also learned how KleidiAI plugs into llama.cpp to get more performance out of Arm chips at the hardware level, and how Arm SVE instructions speed up matrix operations that LLMs depend on.
What's next for Arm Pulse
- Add more model sizes - 7B and 13B
- Add cost per token calculations based on instance pricing
- Support AWS Graviton and GCP Axion benchmarks side by side
- Let users submit their own Arm64 benchmark results to a shared leaderboard

Log in or sign up for Devpost to join the conversation.